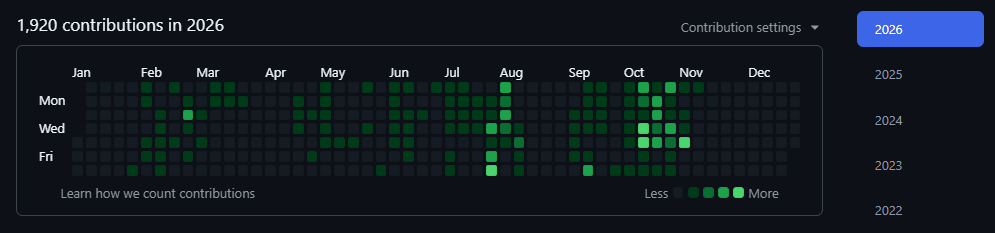
Not even close to the end of '26, my personal productivity has already boosted to the next level. Models advancing fast, harness in wrap speed. As a #vibecoding -er, I am so thrilled to live in such a once-in-a-civilization moment. Let's go new age!
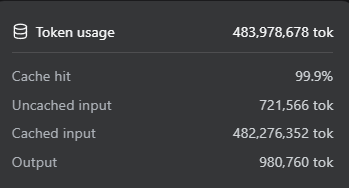
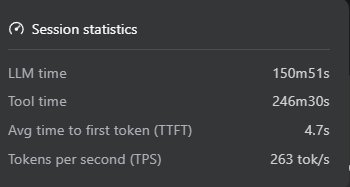
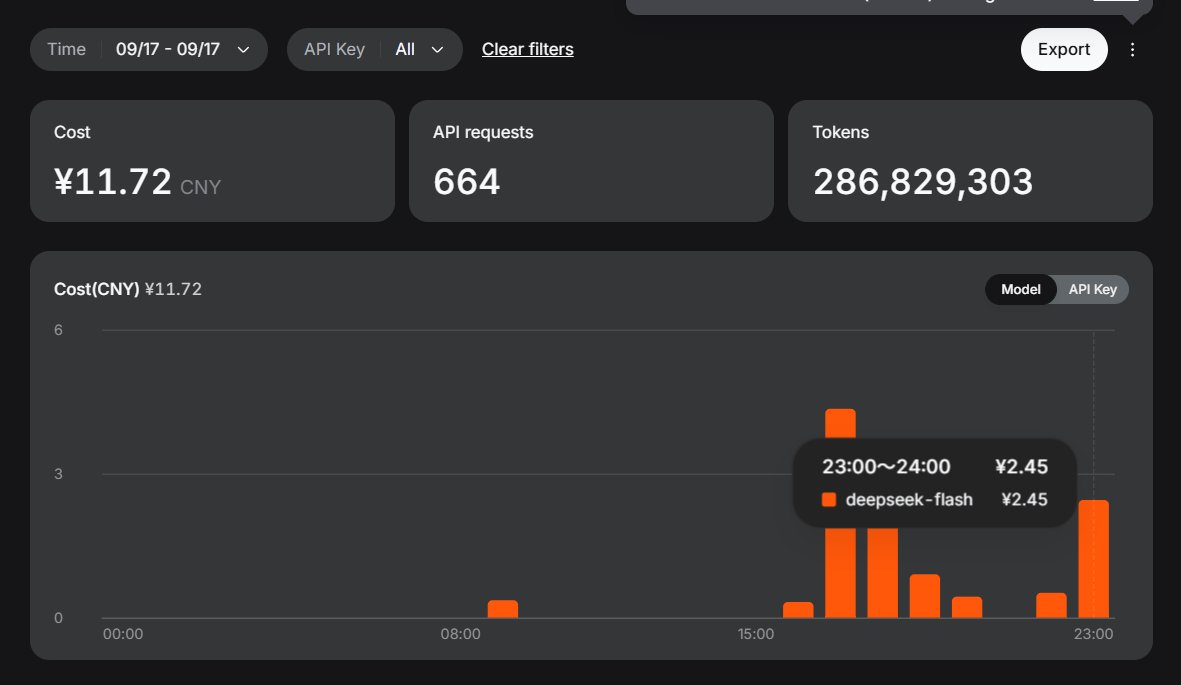
Of coz, it's not a comparable chart, but this chart has told the whole story. Anthropic got 12x, and I've got 100x YoY, sounds crazy, the peak of productivity has yet to come.
Not even close to the end of '26, my personal productivity has already boosted to the next level. Models advancing fast, harness in wrap speed. As a #vibecoding -er, I am so thrilled to live in such a once-in-a-civilization moment. Let's go new age!
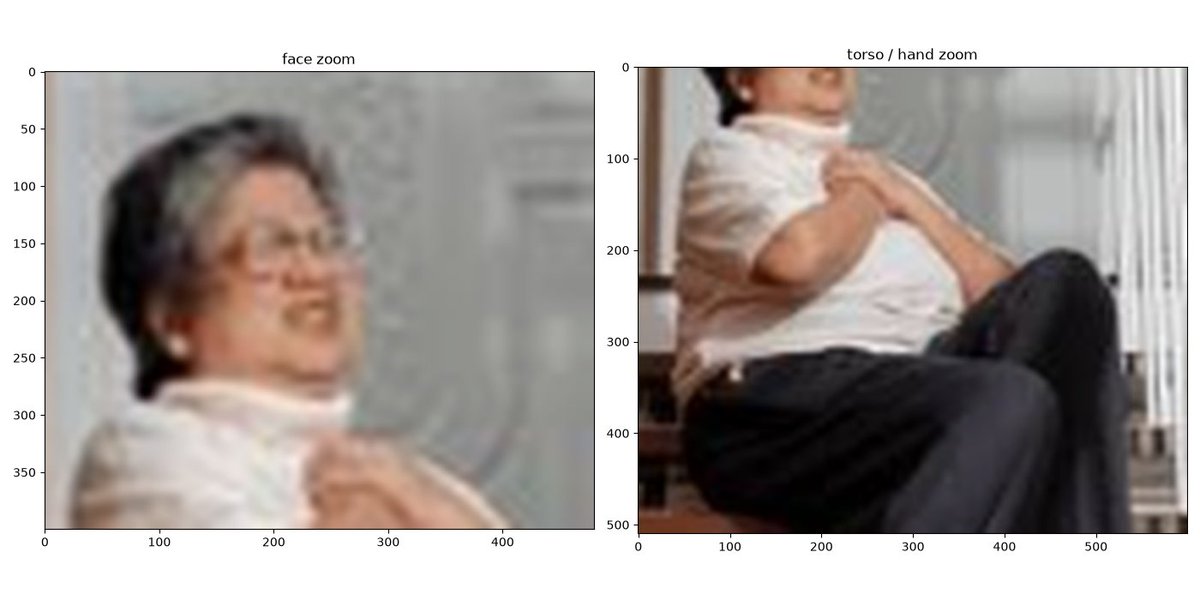
@ElorianAI is really cooking something. I've tried a random image to ask if she thinks that woman in the picture has fallen or not, does she feel well. Elorian model could reason correct situation that she is having now. It could seriouly open up tons of ideas how we integrate vision into many solutions. Well done @AndrewDai Your team is awesome!🥳
Spent years watching models ace a single image and completely whiff on anything that moves or changes angle. Today we’re fixing that.
Try Glimpse now, our first visual thinking model with competitive frontier performance compared to Astra on key public visual reasoning benchmarks.
🚨NEW EXPERIMENT 🚨
Playground is an experimental gaming platform that lets you create your own games with zero coding experience. If you can think it, you can play it.
Go to https://t.co/fRUukpuoqM to learn more! Available to users 18+ in the US.
Introducing Griffin, the first model to pass the video Turing test.
48% of people who talked to it live thought it was a real human. Previous systems have had a pass rate <3%. It is #1 on NVIDIA's benchmark for full-duplex AI video.
It’s the first Human Interaction Model (HIM).
The point isn't to replace climate QC. It's to put a cheap, auditable, replayable triage layer in front of human attention:
rules for gross failures → model for the gray zone → humans only where the model escalates.
Disclaimer: AI generated content maybe wrong. Always fact check.
Jev model test : I've asked my AI agent to try the latest Jev model on NOAA dataset . Result: Hand-written QC rules caught 3 of the 76 climate records NOAA's own quality layer flagged. Jev, the typed-decision model caught 35 — 7.6× the F1 — for $0.02 per 1,000 records, deterministically and with a full audit trail.
Limits, stated plainly:
• It catches 46%, not 100% — it's triage, not a solver.
• No physics. It pattern-matches on numbers; it is not a meteorological model.
• The ground truth is itself rule-generated, so the 10 "false alarms" may be real problems the official layer missed. That needs manual review to settle.
This wave of jev is heating up so fast. Before we actually get the waitlist approved, we can access the model via openrouter. Cost is…Jev Latest costs $0.042/M input tokens and $0.00/M output tokens. Why not just make it free ☺️
https://t.co/nD4oM7UKKU
DeepSeek Harness Plugin released. Agents-Playbook loop cycle tools officially integrated with DSH and tested. From my few tests, that dsh works really well with the long-running tasks, our unique closed-loop design brings positive impact to the code quality.
https://t.co/7zA5155Mxy
https://t.co/sndIMOueOJ
@GithubProjects@deepseek_ai@HarnessWatcher