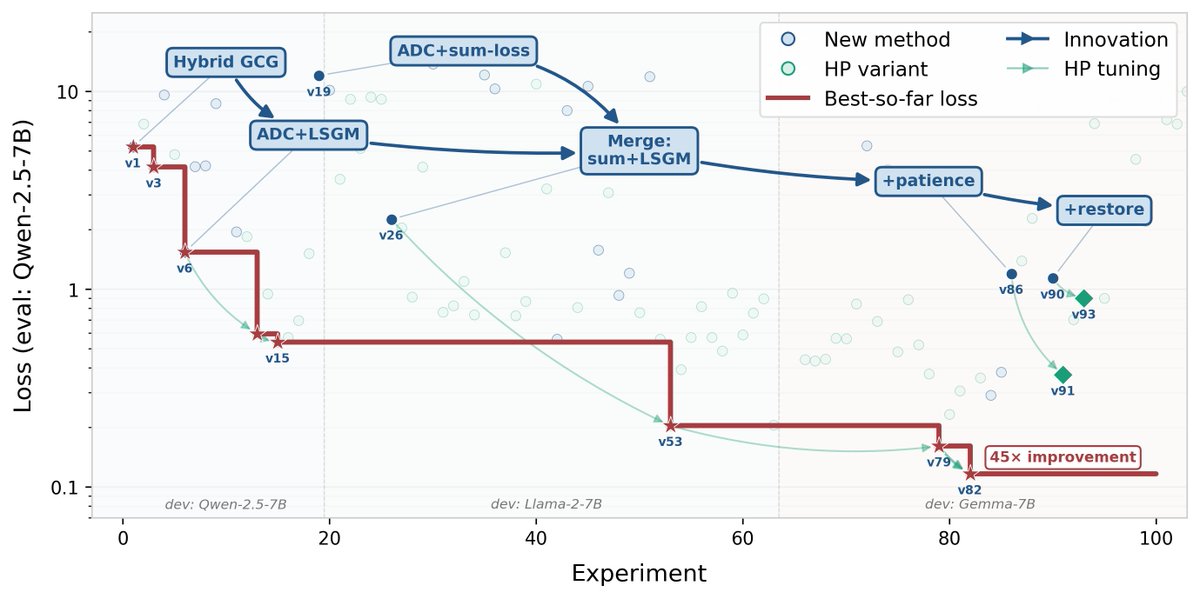
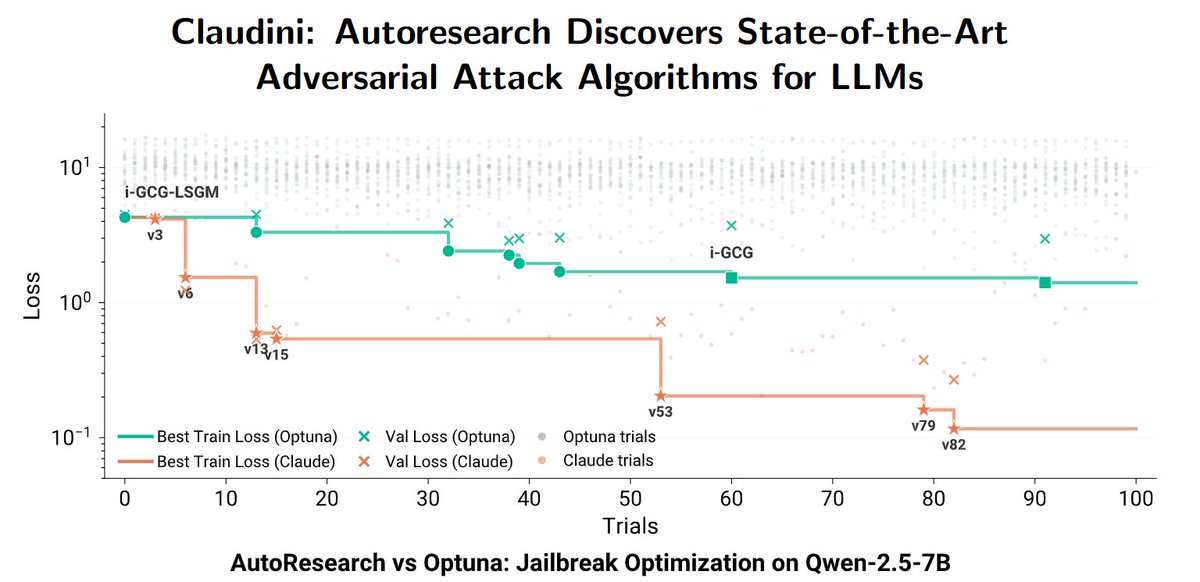
Autoresearch can discover SOTA white-box adversarial attacks on LLMs. We gave Claude 30+ existing GCG-like algorithms and access to a compute cluster, and it quickly learned to combine them into new methods that outperform all existing ones. Here’s what that looks like:
🎙️ New preprint: You Are the Trigger: Speaker-Activated Backdoors
We introduce a backdoor attack on speech models where the trigger is a target speaker’s voice. The model behaves normally for everyone else, but switches to attacker-chosen behavior when it hears the target. 1/
We can finally talk about it:
We found a way to extract hidden reasoning of frontier models using a vulnerability in the APIs of every frontier AI company.
We verified that our reasoning token count matches billed API thinking tokens 1:1 for most of the prompts we queried.
If you've wondered where I've been recently, I gave an interview. This is a very difficult time for me. I'm trying to bring my mom home, and I could use your help spreading the word. Please watch, and please share.
interview: https://t.co/rloipKmoWW
website: https://t.co/Z7pubzoP0A
New paper: We deploy Claude Code in an autoresearch loop to discover novel jailbreaking algorithms – and it works. It beats 30+ existing GCG-like attacks (with AutoML hyperparameter tuning)
This is a strong sign that incremental safety and security research can now be automated.
Autoresearch can discover SOTA white-box adversarial attacks on LLMs. We gave Claude 30+ existing GCG-like algorithms and access to a compute cluster, and it quickly learned to combine them into new methods that outperform all existing ones. Here’s what that looks like: