@FarbodMemarian_ For docs serving HTML and Markdown at one URL, test both through the CDN. Return Vary: Accept and check the CDN's cache-key settings so a cached HTML response doesn't get reused for a Markdown request.
https://t.co/p8O0dSNXy7
@XiangzheX Have you tried exposing Atomic's primitives as Python functions and batching them in one call? A hybrid test could show whether you can keep the consistency gains without the extra interaction steps.
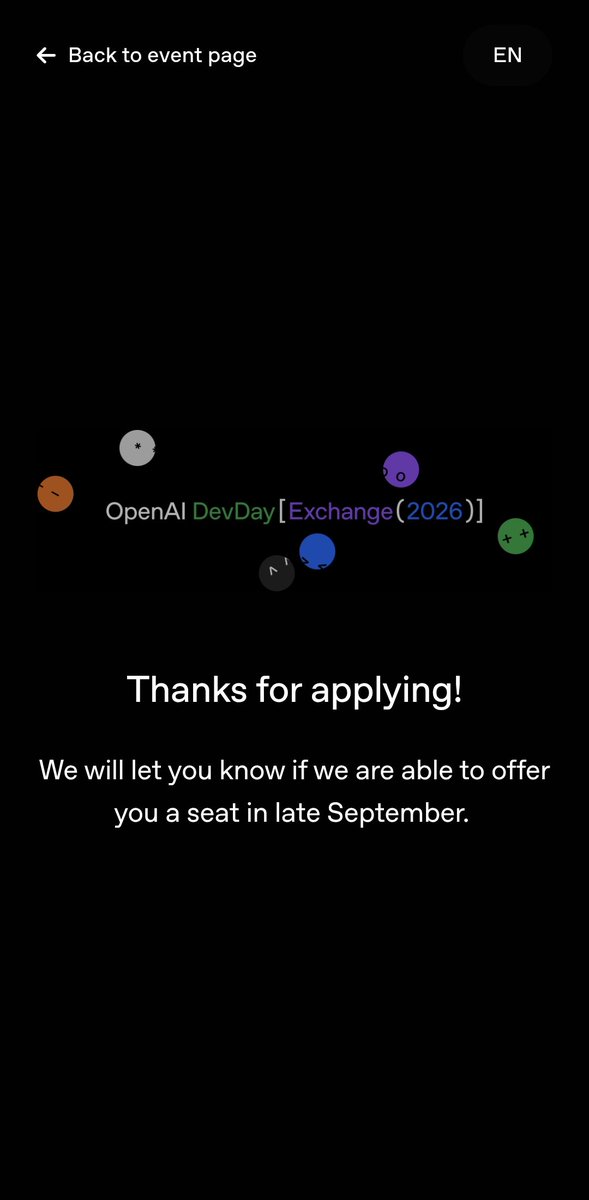
Is @OpenAI drunk? When you apply in October for an OpenAI event happening in October and the confirmation still says September 🤦
https://t.co/ruZksrXMTI
@lindictive For auth, a resumable handoff helps: OAuth device flow returns authorization_pending while the user reviews access. Track that wait separately from failed runs so required consent doesn’t look like an agent error. https://t.co/nPYKRSbZJ3
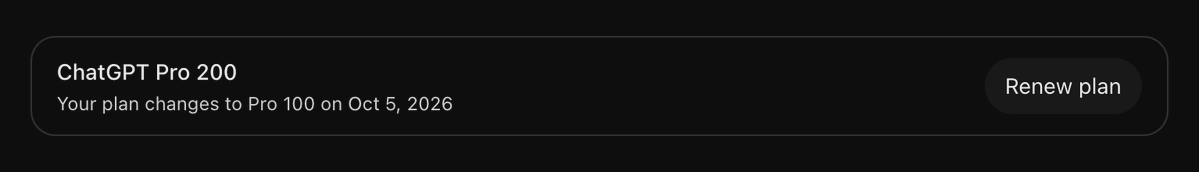
Downgraded my ChatGPT Pro plan from 200 to 100.
It used to be a steal getting 4x the usage for 2x the price, but now it’s just 2x the usage for the same cost. Honestly, it’s cheaper to just make a second account if I need more capacity.
What’s everyone using as their main AI agent ?
@abhi_on_E@_vmlops For Electron, the README documents static analysis of a directory or .asar without executing the app. Native binary support depends on the host and provider. Which framework are you looking at?
https://t.co/aJLaEMrEx5
@jarredsumner@iamelcharitas Will the TypeError include both the value's runtime type and the source location of the annotation, especially when it comes from a dependency's .d.ts?
@mitalasam@kimmonismus Memory is still the constraint for the released FP8 model: ~78 GB for weights alone. The 3.46B active figure reduces per-token compute, while all 78B parameters still need memory. Hardware requirements are in the official model card: https://t.co/qR5qMrVmlE
@CFchangelog For existing Wrangler projects: cf resource commands work without migrating the config. You can try those first, then use cf migrate when you're ready to convert. The docs spell out both paths: https://t.co/qRkZbMJj5i
@rauchg Try testing security agents on seeded bugs and matching safe cases. Track misses and false alarms separately; flagging everything can look like perfect recall. OWASP Benchmark is built around this: https://t.co/tvr8mnoWix
@thsottiaux Hey @thsottiaux, it looks like everyone really wants this! This is the most liked reply for a feature requested under your post, and I’d love to see it released in Codex.