I resigned from Anthropic today. I spent the last three years doing pretraining research at both OpenAI and Anthropic. Neither company is acting responsibly. They are racing straight to self-improving superintelligence and gambling with our lives. More thoughts below.
Andrej Karpathy:
"Remove yourself as the bottleneck. Maximize your leverage. Put in very few tokens, and a huge amount of stuff happens on your behalf."
loop engineering is the exact thing that gets you there.
in a hand-run session you do two things. you decide what the agent runs next, and you check its output before the next step. both are manual, and both are the ceiling on how far the agent gets without you.
loop engineering moves both steps into the system. the diagram below shows the operating structure that surrounds the loop:
→ a trigger decides what to run, whether that's a message, an event, or a schedule, so the agent starts without you there to kick it off.
→ the loop is the maker that produces the work, thinking, acting, and observing until it's done or the brakes stop it.
→ a separate checker grades the output, because a model grading its own work justifies what it already did instead of catching where it failed. the checker's findings return to the maker as the next instruction, and the cycle repeats until nothing is left to fix.
→ state lives on disk, not in context, since the model forgets everything between runs. an MD file or a knowledge graph holds what's done and what's still open, so a loop can pick up again days later.
for that state layer, Zep's Graphiti is a clean open-source option, a temporal knowledge graph that invalidates stale facts and returns context through vector, full-text, and graph search in one call.
repo: https://t.co/8CboBlWffX
two things decide whether an unattended loop holds up.
the exit has to be set before the loop runs, not while it's running. a loop with no stop condition burns tokens, and the cost climbs fast once sub-agents and long runs stack up. a clean exit reads like "all tests pass and lint is clean, stop after two passes."
and the checker only catches failures inside a run. the harness around the loop, the prompts, tools, and checks wrapped around the model, still drifts and breaks in production as models change. catching that needs observability on every run, not a green checkmark.
Comet's Opik is built for that layer, an open-source tool that traces every call and turns a failing production trace into a regression test so the same break can't recur.
repo: https://t.co/Qxk9BHZBlx
your job stops being the hands inside the loop. it becomes designing the machine that runs without you, then watching the traces closely enough to trust it.
the model is becoming a commodity. the loop around it is where the real engineering lives now.
I wrote the full breakdown. the article is quoted below.
stay tuned for more on this!
This is a glimpse of where local AI is heading and we are glad to be part of it.
Really impressive work by all the teams involved @Gradient_HQ, @tryParallax, and @GA_agent_ai
Everyone on planet Earth is talking about local AI right now
And for good reason
Governments are banning models. Hardware prices are 10xing
You NEED to be getting into local AI. The number 1 questions everyone has though is which computer to buy?
Here's your answer:
You basically have 3 options:
1. MAC STUDIO (high memory, low bandwidth)-
Mac Studios are excellent devices for local AI. They can run MASSIVE models. I'm running GLM 5.2 right now on a single Mac Studio. The model is Opus 4.8 level
The issue is, Mac Studios have very low memory bandwidth. Meaning, the models run very slow
Mac Studios are a good choice for you if you want frontier level intelligence, but are fine running the intelligence passively
Meaning you get top intelligence, but it runs more in the background rather than on demand
As an example, I have GLM 5.2 running security checks on my codebase every hour. It creates a report. I review this later in the day
2. POWERHOUSE NVIDIA CHIPS (RTX 5090, 6000 Pro)
Nvidia is the most valuable company in the world, and for good reason
They make the world's best GPUs.
They have decent VRAM (32gb on the 5090, 96gb on the 6000 Pro) and INSANE bandwidth. Meaning the local models run at unbelievable speeds
I'm running Qwen 3.6 locally on a 5090 and it's just as fast as cloud models
I'd go this route if you want to run an AI agent like Hermes off a local model, still get decent intelligence, but have it able to work lightning fast
3. AI WORKSTATIONS (DGX Spark type computers)
The DGX Spark is an excellent AI computer
It has high memory (128gb unified memory) and has decent speeds because of the Nvidia CUDA architecture
It is basically the sweet spot between a cutting edge Nvidia chip and a Mac Studio
You can run medium sized models, and get usable speeds out of them
You're not going to get the same performance as cloud models, but it will allow you to offload small secondary tasks to your local models for them to handle
They are also the absolute easiest to get up and running
You plug it in, then tell your agent on your main computer to go onto it and set it up. You don't even need it connected to a monitor
CONCLUSION
Here's what it comes down to: how high intelligence do you need, what speeds do you need, and how plug and play do you want?
Want the highest speeds, like you are used to with cloud compute? Build a computer around an RTX 5090
Want to run frontier level intelligence, and don't mind slow speeds, go with a Mac Studio
Either way, it's never been more important to get into local AI
🚨 I JUST FOUND THE AI WORKFLOW EVERYONE WILL BE COPYING IN SIX MONTHS
Andrej Karpathy, co-founder of OpenAI, posted something simple that hit 16 million views. Stop using AI to write code for a minute. Use it to build yourself a second brain instead.
You point Claude Code at a folder. You drop in anything, an article, a transcript, a PDF. Claude reads it, links it to everything else you've fed it, and files it into a living wiki of your own knowledge. The more you put in, the smarter it gets. It compounds like interest.
Here's the whole setup.
→ install claude desktop (https://t.co/uwyusXbQBv) and obsidian (obsidian.md), both free to start, claude needs a paid plan to use the code tab
→ in obsidian create a new vault, this folder is your brain, every file claude writes lands here
→ turn on the local rest api plugin in obsidian settings and copy the api key it gives you
→ in claude code, run one command to connect to your vault using that key, this is mcp, the standard way claude talks to other apps
→ test it by asking claude to list every file in your vault, if it answers, you are connected
→ have claude interview you about who you are, your goals, your projects, and save it all into a claude.md file at the root, this is your permanent context, you never retype it again
→ for each area of your life, content, work, finances, create a project folder with its own claude.md so claude focuses on one job at a time instead of everything at once
→ turn repeated tasks into skills, saved workflows claude runs on command instead of you explaining the steps every time
→ connect live tools like google calendar through mcp so claude can read what is actually happening today, not just static notes
→ schedule a daily task so claude organizes new notes and summarizes what changed while you sleep
Five minutes to set up. After that you stop opening a blank chat every time, because the system already knows what you've been reading and thinking about.
Bookmark this.
The companies charging $200/month for AI assumed local hardware would never catch up.
It caught up.
He's assembling the proof right now.
A PC that runs Qwen 3.6 27B a free model that beats Claude on vision by 7 points. DeepSeek R1 for math and reasoning. Llama 3.3 70B for everything else. All local. All free. All forever.
Electricity: $9/month. Subscriptions: $0.
He used to pay $459/month for Claude Code, ChatGPT Pro, and Cursor. That's $5,500 a year going to someone else's servers.
The hardware he's building costs less than one year of that bill.
And it never sends another invoice.
He's still assembling it.
The subscription renewal reminder hit his inbox while he was putting it together.
He ignored it.
Do you actually understand what's happening. He built a personal local AI voice agent that fits in your pocket.
Clients pay him $2,500/month to have one.
It runs locally. No cloud. No rate limits. No data going anywhere. You talk to it and it acts in real systems, automatically, without a human in the loop.
He looked at that device and didn't think about using it himself.
He thought about who would pay him to build one for them.
$28,000/month ops team. Five agents. $200/month in tools. Client saves $22,000. He earns $2,500/month to maintain it.
They never cancel. Canceling means hiring the team back.
8 clients. $20,000/month recurring.
Everyone is talking about AI voice agents like they're a personal productivity tool.
He turned one into a business.
Different outcome.
A software developer earns $8,000/month.
He earns $20,000/month and works 15 hours a week.
The difference isn't skill. It's the business model.
The developer trades time for money. He trades agents for retainers.
Five agents built once for a client. Lead qualification, support, invoicing, monitoring, reporting. All automated. All local. All running on a mini PC he assembled himself.
Setup: one week. Retainer: $2,500/month. Client saves $22,000/month from day one.
They never ask to cancel. The math won't let them.
8 clients. $20,000/month. 15 hours of maintenance per week.
He stopped trading time for money when he built the first agent.
Now the agents trade time for him.
He's still building the infrastructure on that mini PC.
Do you actually understand what's happening right now. He is assembling a box that costs $600 once.
The business running on it makes $20,000/month.
Not a server room. Not a data center. A small box on a desk. Six agents running on his own hardware, his own models, his own terms.
He walks into a business. Asks what their team repeats every day. Builds the agents to do it. Charges $2,500/month to keep them running.
Client was spending $28,000/month on people doing that work. Now they spend $2,500. They save $22,000 a month. He collects a retainer forever.
They never cancel. The math won't let them.
8 clients. $20,000/month. 85% margin.
Everyone is watching AI and waiting. He is already billing.
ANTHROPIC CEO, Dario Amodei:
"In the next 2 to 5 years, AI will hit the job market faster and broader than anything we've ever seen."
This isn't a forecast, it's already happening and you can't adapt while ignoring it.
38 minutes on how to win through these changes, from the CEO of a $965B company.
Watch it, then read the guide on everything Claude can do below and you'll already know more than 99% of people.
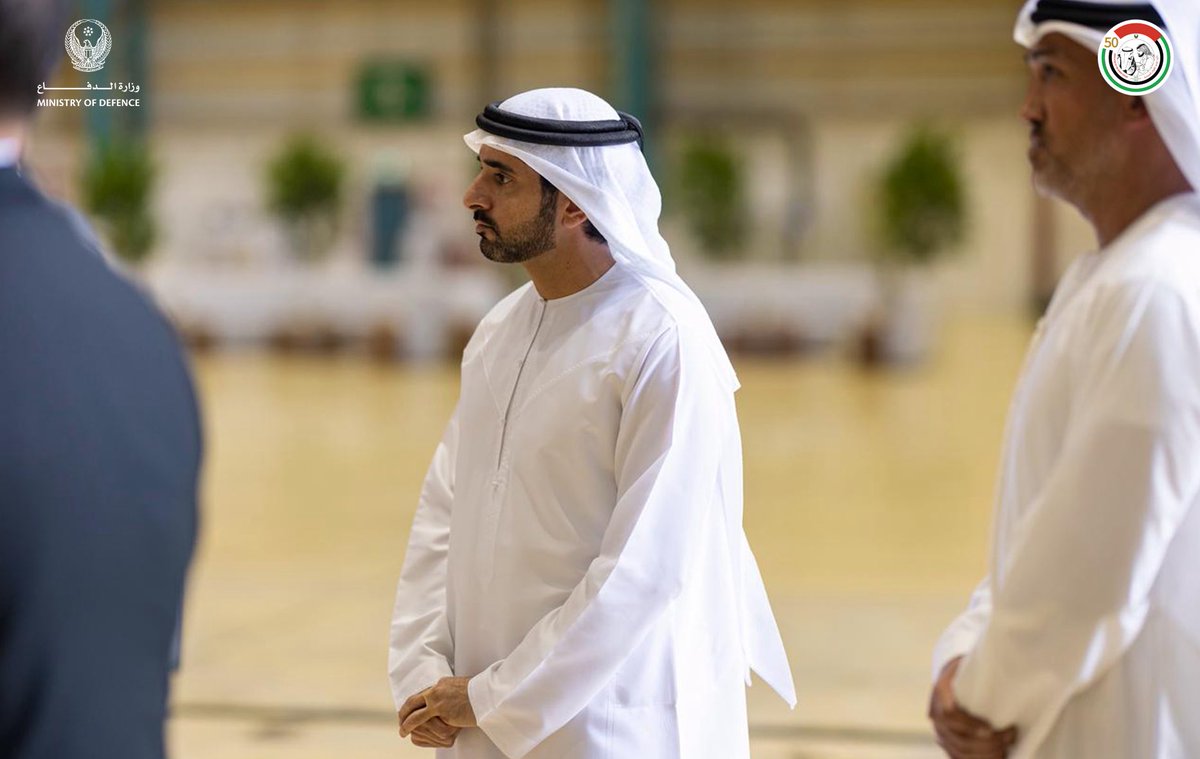
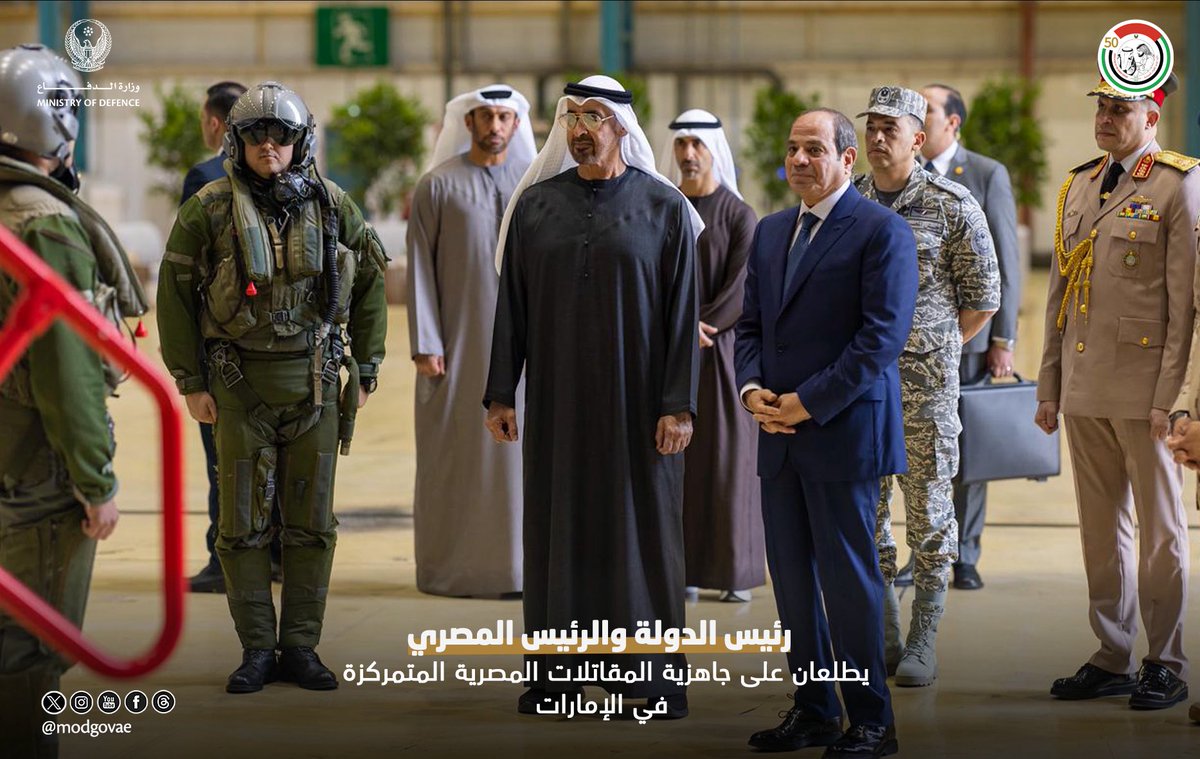
قام صاحب السمو الشيخ محمد بن زايد آل نهيان رئيس الدولة ”حفظه الله“ وفخامة عبدالفتاح السيسي رئيس جمهورية مصر العربية الشقيقة بزيارة تفقدية إلى مفرزة المقاتلات المصرية المتمركزة في الدولة، للاطلاع على الجاهزية والجهود المبذولة لتعزيز القدرات العملياتية والاستعداد لمختلف التحديات.
رافق سموه وفخامة الرئيس المصري خلال الزيارة، سمو الشيخ حمدان بن محمد بن راشد آل مكتوم، وسمو الشيخ حمدان بن محمد بن زايد آل نهيان، ومعالي محمد بن مبارك بن فاضل المزروعي، وزير دولة لشؤون الدفاع، وعدد من كبار ضباط وزارة الدفاع.
#وزارة_الدفاع
#وزارة_الدفاع_الإماراتية
#MOD
#UAEMinistryOfDefence