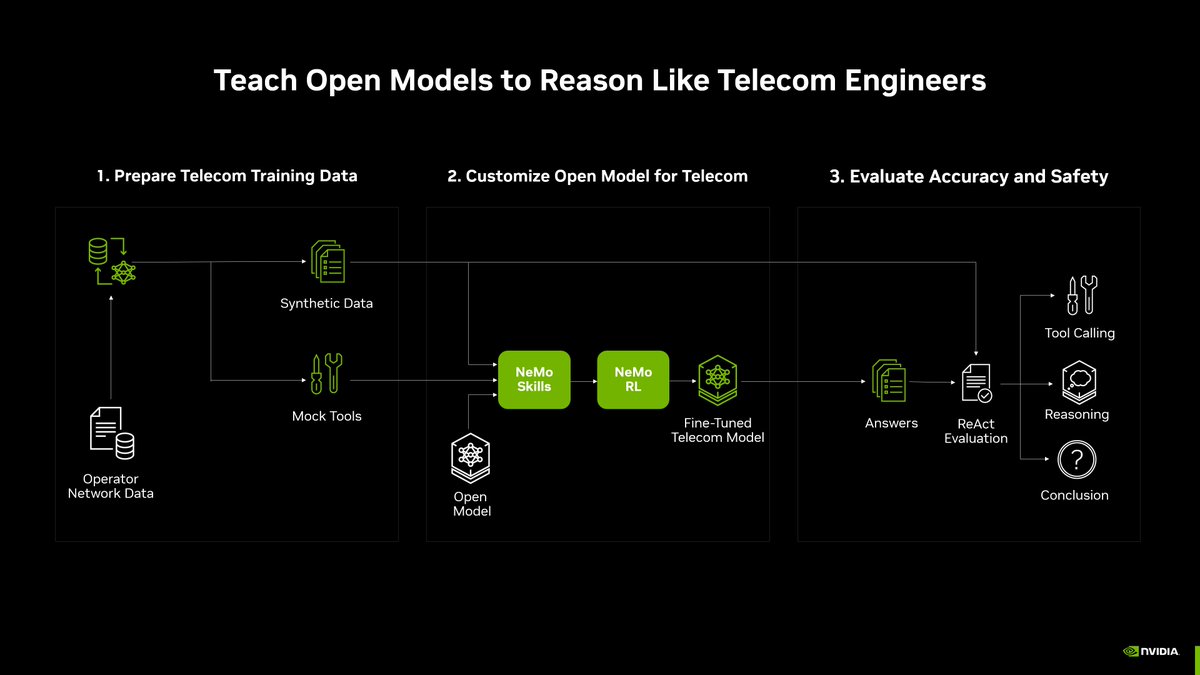
Telcos are just one of the many industries tapping into the benefits of open models, with 89% of operators building using them. @nvidia has been working with companies like @ATT on everything from fine tuning to locally deploying AI. Read more below!
https://t.co/QKQxRqirSv
The work the Nemo Speech team is doing is incredible! So glad to see so many of you hype for this technology and even happier to answer all your questions!
Huge thank you to everyone who downloaded Nemotron 3 Diarization and helped it trend on @huggingface! And we appreciate all the comments.
@sabbassi_11 answered a few of your questions:
Today, with over 100 industry partners, we introduced the NVIDIA Open Agent Safety Platform, bringing together OpenShell and Sentry.
Artificial intelligence is extraordinary technology that will advance discovery, productivity, security, health, and prosperity for generations to come.
But its full promise can only be realized when people have confidence that AI is being built to be safe and deployed with wisdom and responsibility.
This is bigger than a single product. It's the beginning of an open ecosystem to build the trust layer for safe agent systems.
Together, we are building the foundation of the AI economy.
Trust and innovation are not in conflict. Safety is how trust is earned. We must build not only the most capable AI, but the most trusted AI, so that this extraordinary technology can realize its enormous promise for the world. https://t.co/ugYWQ1MyRi
When several people talk at once, a transcript can get messy fast.
Our new Nemotron 3 Diarization model tracks who spoke when, even when voices overlap. It handles up to eight speakers, has 100M parameters, and is now available on @huggingface 🤗
How can a 30B-parameter model activate just 3B parameters per token and still draw on the full model’s capacity?
Learn how dense and MoE models use parameters differently, and what that means for throughput, memory and serving complexity.
Check out our new technical explainer: https://t.co/HdOPFs2WA3
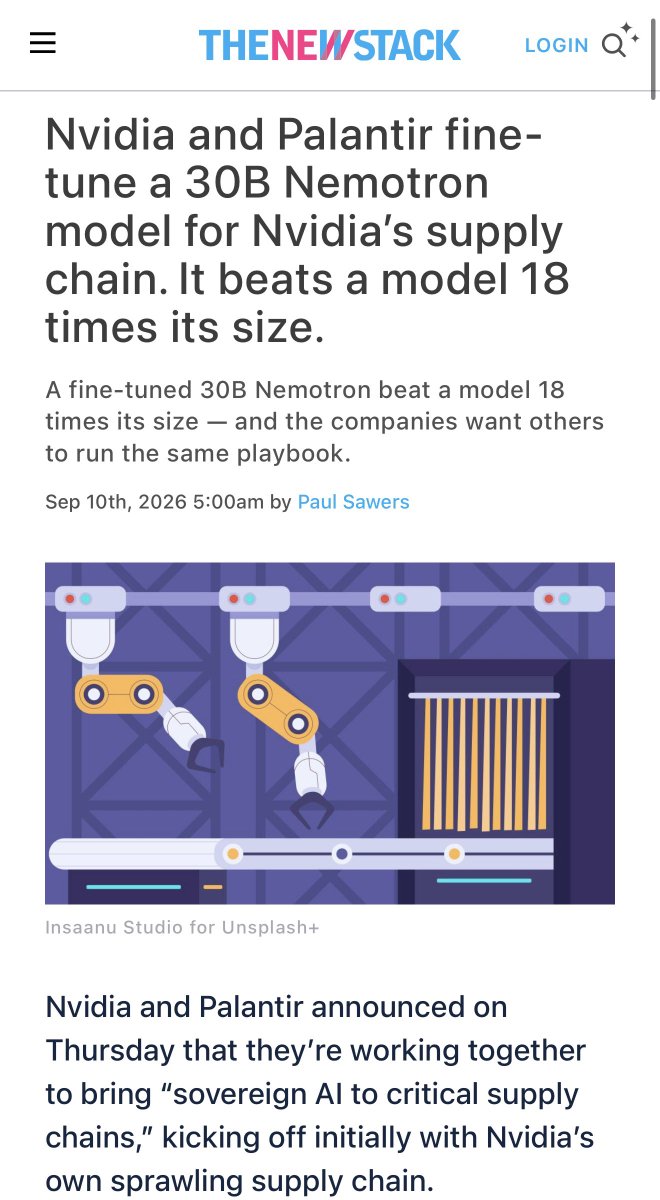
30B post-trained on the Ontology loop beat 550B
Specialization > scale
“Supply chains are the operating system of the physical economy, and AI factories are among the most complex systems ever built.”
“NVIDIA has arguably the most valuable, intricate, and complex supply chain in the world.”
“This doesn’t mean the smaller model is more capable overall. Its gains are concentrated in the domain it was post-trained on.”
I'll be attending #NVIDIAGTC Berlin and talking about open technologies for AI.
I’ll be sharing how we build NVIDIA Nemotron models - from architectures, training data, and weights to post-training recipes and evaluation - and how you can inspect, adapt, and deploy them for domain-specific work.
Don't forget to use my code to get 25% off your pass: GTC-NVP8A3H2
Hope to see you there: https://t.co/SB2lOrCCp1
Exciting day for NVIDIA and @huggingface.
Open models strengthen safety and cybersecurity, accelerate innovation and diffusion, and enable sovereignty. They allow every developer, startup, university, industry and country to build with, customize and benefit from AI.
Thank you @ClementDelangue for coming to me.
NVIDIA is going to be a great home for Hugging Face, its community and the future of open models. 🤗
https://t.co/q8Om2Xc5ye
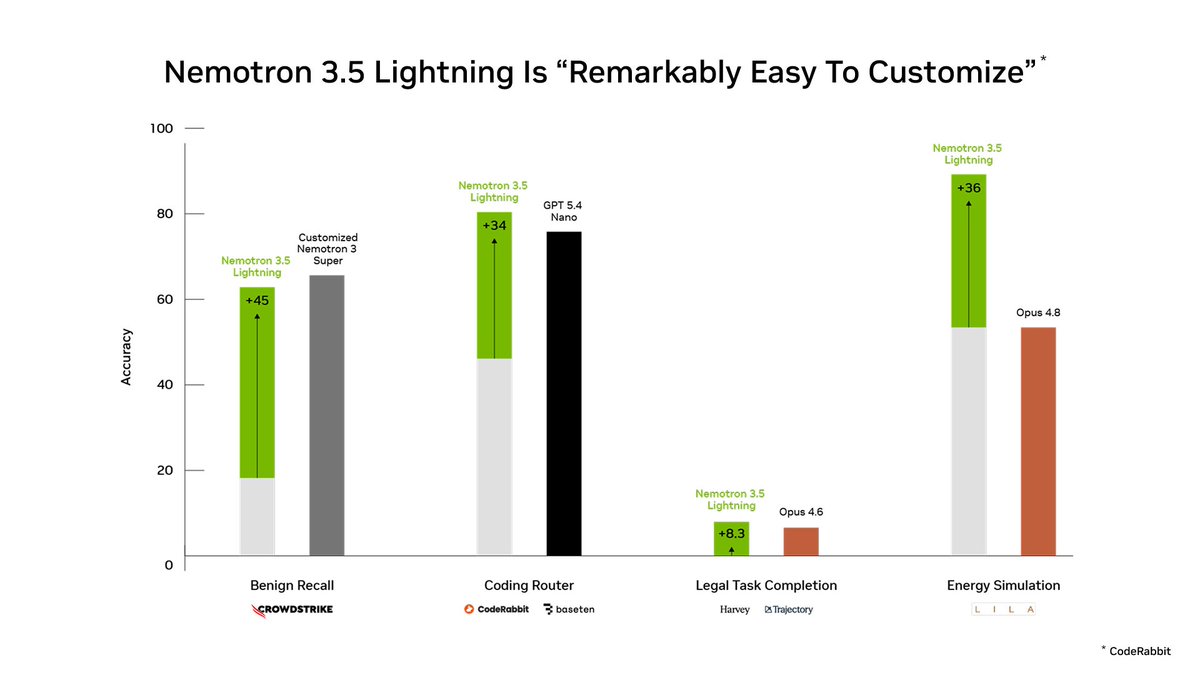
Lightning fast to customize. Lightning fast to run.
NVIDIA Nemotron 3.5 Lightning is a compact, customizable open model built to help always-on agents complete specialized tasks faster.
Kari Briski joins @MTSlive to explain how Lightning helps always-on agents work faster.
NVIDIA knows the importance of supporting your "local" community.
Perplexity's newest release Portable Computer runs Perplexity Computer's agent harness, orchestrator, and post-trained model locally on hardware your very own DGX Spark.
The future is now, and it is yours to keep
Today we’re launching Portable Computer on @NVIDIA DGX Spark.
Portable Computer is a fully local version of Perplexity Computer, where the entire runtime: orchestrator LLM, subagent LLM, agent harness all run on your local hardware. No cloud dependency.
Our general-purpose coding agent just scored 100% on the ARC-AGI-3 interactive reasoning benchmark.
NVIDIA AVO completed all 183 levels across all 25 public environments, figuring out what to do with no instructions, explicit rules, or stated goals.
The right model depends on the task.
NVIDIA NeMo Switchyard helps developers route each agent workflow step across a chosen model pool based on their own quality, latency and cost criteria.
Kari Briski joins @MTSlive to explain why agent workflows need model routing.
Holy moly. 🤯
Qwen 3.8 27B just scored higher than:
GPT 5.6 Terra
GLM 5.2
DeepSeek V4 Pro
Muse Spark 1.2
Claude Opus 4.8
on the Artificial Analysis Agentic Index.
And you can run this on a single RTX 3090/4090.
Go show your GPU some respect. 🫡
Qwen 3.8 27B weights and benchmarks are now out
This thing in full precision would fit on a single RTX PRO 6000 and beats Opus 4.6 Max in several benchmarks
SoTA at home
Ready to run Qwen3.8 locally? 👀
Qwen3.8-27B packs powerful AI into an open model developers can download, serve locally, and build with on their own terms.
Qwen shipped Qwen3.8 today: 2.4T parameters, configurable reasoning, open weights.
4,000+ tokens/sec/GPU and 350+ tokens/sec/user on GB300 NVL72 in FP8.
It ran on NVIDIA day 0.
Companies make great things. NVIDIA makes them better.
https://t.co/HAzimvG55u
NVIDIA VP @karibriski on why models are the new libraries: data is source code, weights are compiled code, and you import many models to create a single application
"This is a new way to develop software. Before, you had source code, compilers, and libraries within your software applications."
"With generative AI, you're infusing models into a new type of software application. Everyone uses the term harness now. This is the new software operating system."
"When we put out the data, that's our source code. We put out the weights, that's our compiled code. When you create a software application, do you just have one library? No, you import many libraries in order to create a software application."
"The libraries are models, and you have to call different models to get the right answer at the end. You have inputs and outputs."
@nvidia
Severe weather alert @NVIDIAAI ⚡️⚡️!
Nemotron 3.5 Lightning is NVIDIA's new 30B A3B model. It's smart, it's fast, and its yours to have.
Built for specialized high volume agentic tasks, 3.5 Lightning is completely customizable and open, frontier level intelligence is your own.