I built a stupidly simple skill that finds the cheapest flights by searching every site (even the obscure ones).
It always beats Google Flights.
LAX → Tokyo just came back at $428 RT vs $650+ on Google.
👇
In case you've been struggling with RAM for your agents.
Everyone's buying Mac mini. A 64GB M5 is ~$3,000. Sure, "unified memory," but most people aren't going to run local models.
Meanwhile, you can get a renewed DELL 7010 MICRO i5 13400T 64GB 960SSD for ~$1,000. Just a bit larger, super quiet.
Highly recommended as a budget option. You can get three instead of one M5.
Personal Intelligence in Gemini securely connects information from apps you already use to make your experience more personalized and helpful. Today, we’re adding Google Wallet to the list of connected apps so you can get more tailored responses in the @GeminiApp around personal finance questions, based on your spending habits, including:
📈 Generate dynamic charts tracking cash flow, asset allocation, and budgets directly in your chat to help you visualize your spending.
📅 Find forgotten subscriptions and recurring charges across your linked accounts, and Gemini will also flag any price increases.
🎁 Set a budget for the holidays by asking “How much did I spend on gifts and travel last year? Use that to help me set a holiday budget” and Gemini will look at your transactions from the last year to suggest a budget tailored for you.
You’ll also have the option to securely link your financial accounts from your credit cards and banks to Wallet via @Plaid to unlock deeper insights.
You can now build custom themes for Claude Code on desktop with mods! Change the colors, add an animated background, and make it your own.
Just tell Claude how you want it to look, or get started quickly with the theme-examples plugin. We'd love to see what you make!
Product Hunt insider tip (I'm the CEO):
Launches submitted via MCP are 3 times more likely to be featured than manual launches.
Our MCP actually helps you create a better launch.
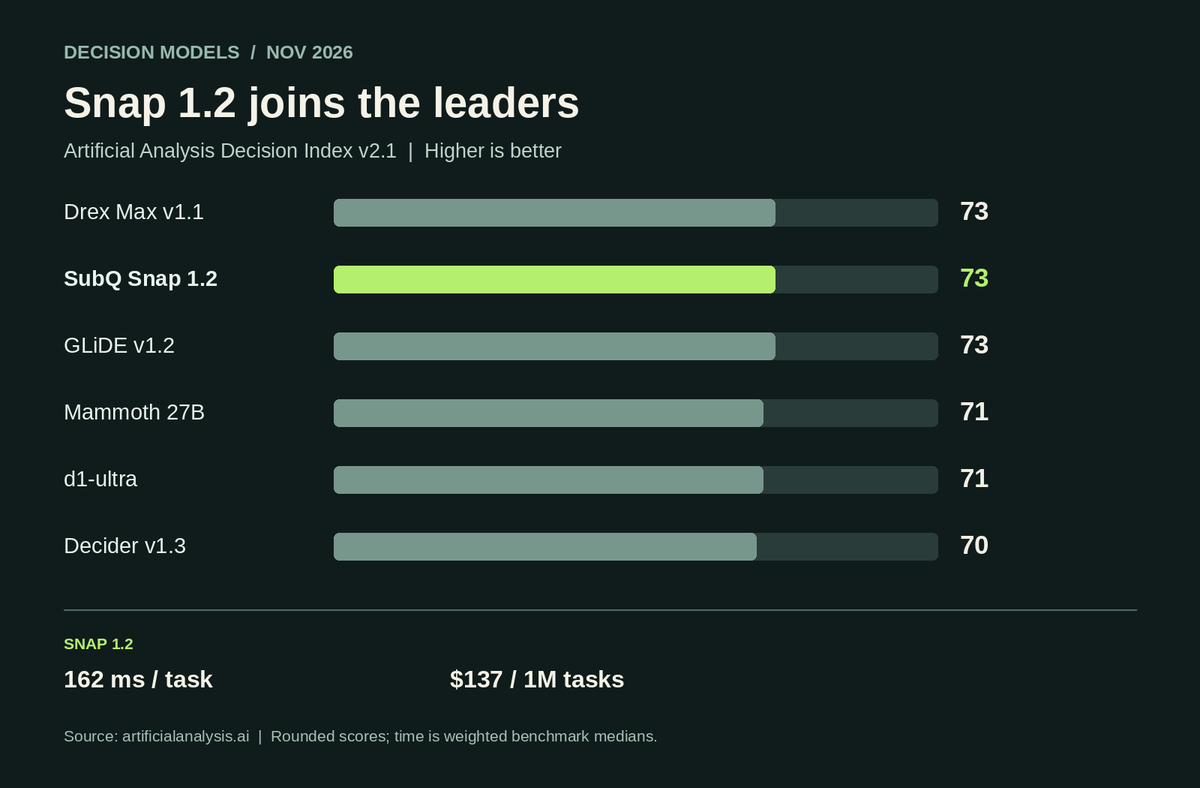
SubQ Snap 1.2 scores 73 on AA's Decision Index, up from 68. With 384K context and $0.04 per 1M input tokens, I'd test it for long-document routing.
Important: Knowledge gains come from abstaining more, not higher accuracy. Don't mistake it for a knowledge engine.
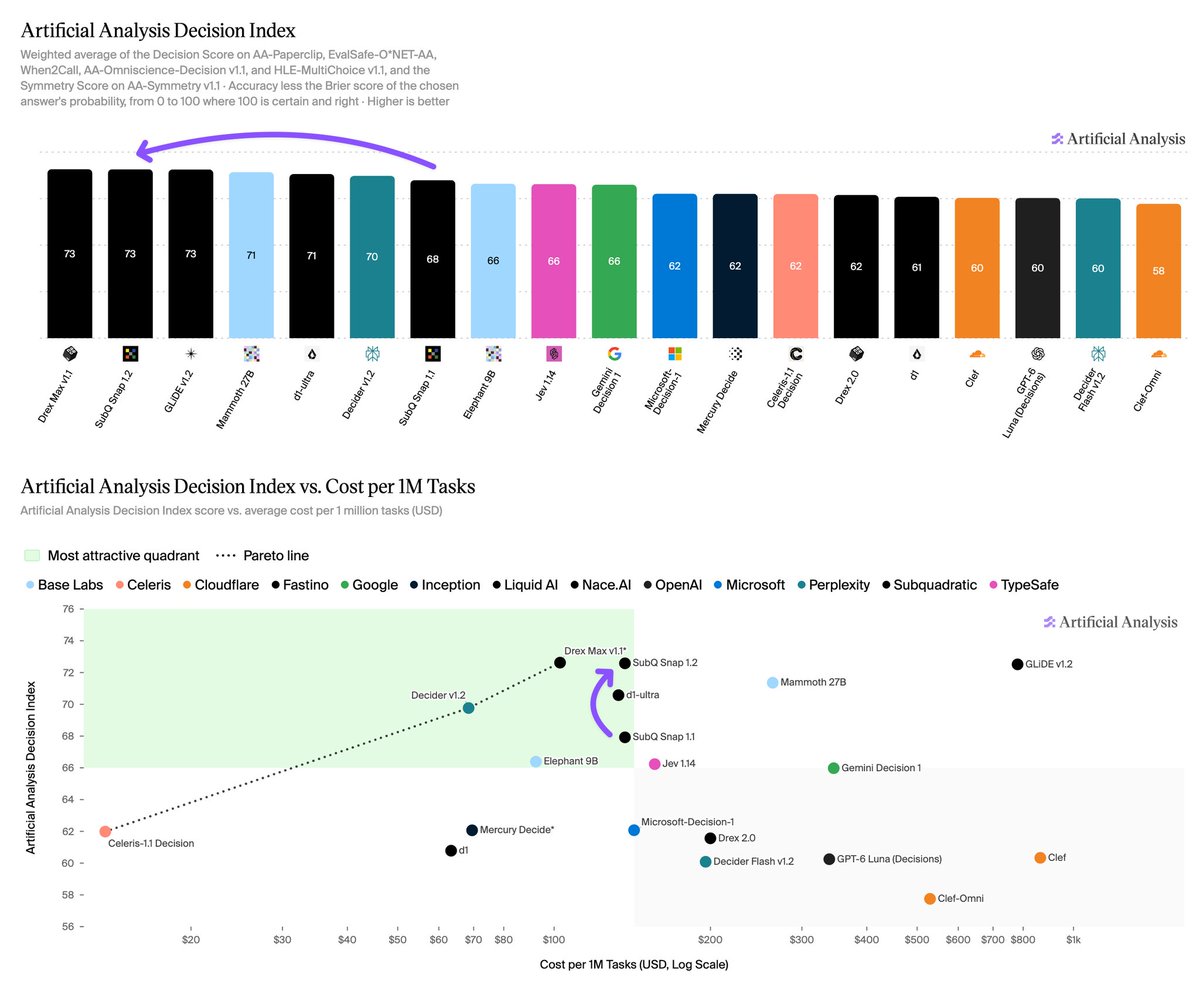
Subquadratic’s SubQ Snap 1.2 gains 5 points over SubQ Snap 1.1 on the Artificial Analysis Decision Index v2.1, and is tied with Drex Max v1.1 and GLiDE v1.2 as the leading decision model
SubQ Snap 1.2 is the latest decision model from @subquadratic. Pricing is unchanged at $0.04 per 1M input tokens, and it supports a 384K token context window.
Decision Index v2.1 updates AA-Symmetry to v1.1. AA-Symmetry measures whether a model keeps the same decision and confidence when a question changes in ways that should not matter. v1.1 moves the answer options into the state and rewords them with the same meaning.
Key takeaways:
➤ SubQ Snap 1.2 scores 73 on the Artificial Analysis Decision Index v2.1, up from 68 for SubQ Snap 1.1: Drex Max v1.1 (73) and GLiDE v1.2 (73) are within 0.1 points. The largest gains are on AA-Paperclip (+8 points) and AA-Symmetry (+8 points).
➤ The AA-Paperclip gain comes from more documents answered fully correctly: the all-pass rate rises from 46% to 62%, level with Drex Max v1.1 (63%) and GLiDE v1.2 (62%).
➤ The gains on AA-Omniscience-Decision and HLE-MultiChoice come from abstention, not accuracy: non-hallucination rates rise from 85% to 89% and from 46% to 55%. Accuracy is flat at 21% and 9%. On AA-Omniscience-Decision, SubQ Snap 1.2 attempts 29% of questions, down from 33%.
we shut down a software business making $250k a year to build a hardware company
put $20k of our own money into it, moved to the US with less than 3 months of runway, and eventually got into @ycombinator
today, we're introducing @antimattr_one
we're building a voice-first hardware interface for human-agent interaction
I'd start with Decider v1.3 for quality: 70 vs Flash's 64 on the @ArtificialAnlys Decision Index. Flash costs $34 vs $68 per 1M benchmark tasks and takes 178 ms vs 289 ms. Use Flash when speed and volume matter more. Both add Locate for span extraction.
We're rolling out pplx-decider-v1.3 and pplx-decider-flash-v1.3, the latest version of our open-weight decision models.
v1.3 adds locate, a new feature that extracts spans based on type or instructions.
Now available in our Decisions API, @huggingface, and @OpenRouter.
https://t.co/bsTSl2tHSo
We are deeply sorry for the disruption this incident has caused our customers and partners. We know the trust they place in our services and take that responsibility extremely seriously. We are seeing broad recovery and stability across our services.
This was a technical issue not related to cyber or AI / agents. The incident was introduced by an issue during an earlier network capacity upgrade that surfaced following a recent network change. We have addressed the underlying issue and continue to restore service to remaining customers and regions.
Given the scale of demand, we restored services gradually, validating stability at each stage. While this took longer, it helped ensure a stable restoration.
We will provide a full post-incident report once our review is complete.
I’d keep Hydrogen on High. Xhigh buys 3 AA Index points (51 to 54), but cost/task jumps from $1.87 to $3.16. Terminal-Bench 4.0 stays at 54%. Pay for Xhigh when scientific terminal work matters: 41% to 50%. Data: @ArtificialAnlys.
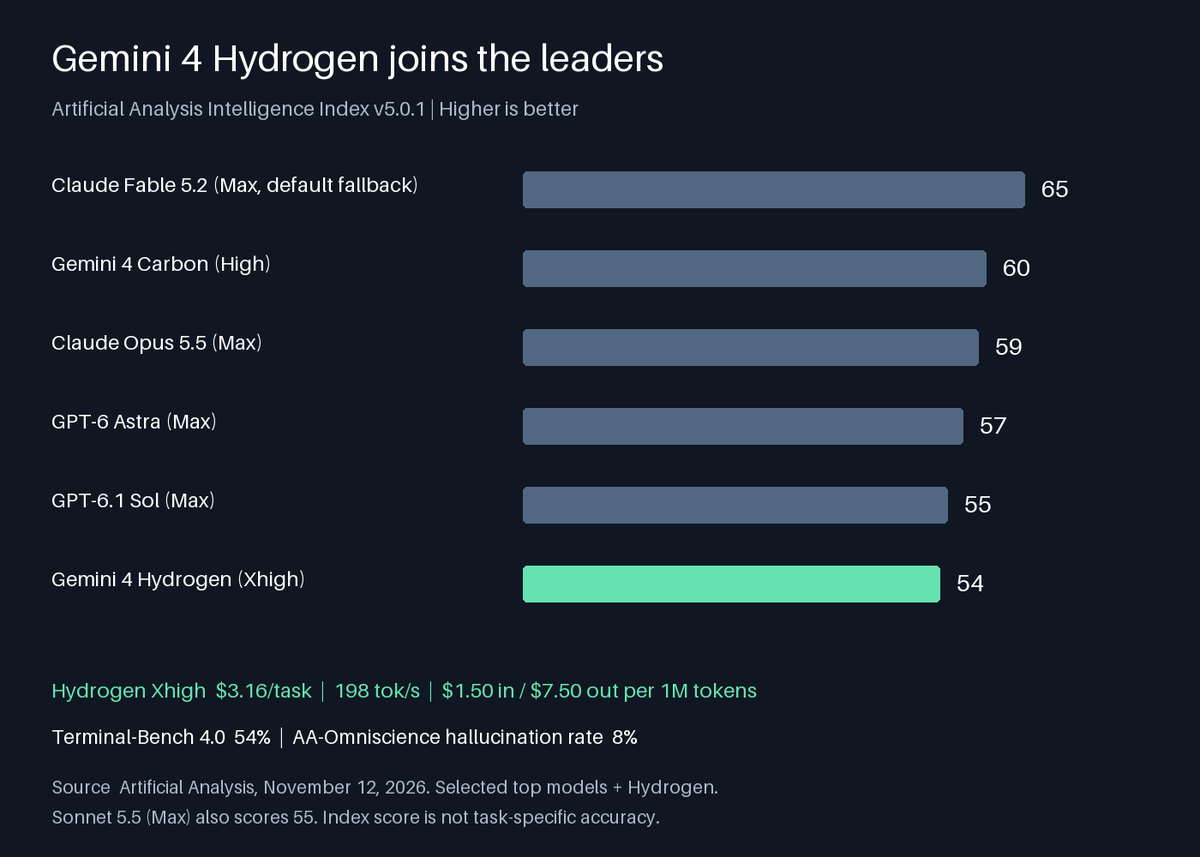
Google's new Gemini 4 Hydrogen has Intelligence just below Claude Sonnet 5.5 and GPT-6.1 Sol, at a third of Sonnet’s cost but ~2.5x that of GPT-6.1 Sol
@GoogleDeepMind has released their third new model in six weeks. Gemini 4 Hydrogen introduces an xhigh reasoning level and scores 54 on the Artificial Analysis Intelligence Index, with strengths in visual reasoning and non-hallucination. This places it 1 point behind Claude Sonnet 5.5 (max) and GPT-6.1 Sol (max), at ~32% of Sonnet’s cost but ~2.5x that of GPT-6.1 Sol. With high reasoning, Gemini 4 Hydrogen matches the Intelligence of Gemini 4 Argon for ~19% of the Cost per Task
Key takeaways:
➤ The new xhigh reasoning level scores 54 on the Intelligence Index: xhigh is the first reasoning level above high on a Gemini model, and puts Hydrogen 1 point below Claude Sonnet 5.5 (max) and GPT-6.1 Sol (max), and 4 points ahead of Gemini 4 Argon (high). With default (high) reasoning, Gemini 4 Hydrogen scores 51, just behind GPT-6.1 Sol (xhigh, 52) and Claude Opus 5.5 (high, 52)
➤ Strong visual reasoning, presentation and non-hallucination: On GDP.pdf, a visual reasoning benchmark over long documents, it scores 33% all-pass on medium reasoning, the tied #1 score on the benchmark. On AA-Omniscience, Hydrogen has one of the lowest hallucination rates recorded at 8%, compared with 43% for Claude Sonnet 5.5 (max) and 52% for GPT-6.1 Sol (max). On AA-Briefcase, our agentic knowledge work evaluation, graders rate Hydrogen's presentation above other Gemini models, including Carbon
➤ Weaker on agentic terminal work: Hydrogen scores 54% on Terminal-Bench 4.0 and 50% on Terminal-Bench-Science 0.1, covering agentic coding and scientific research workflows in the terminal. Claude Sonnet 5.5 (max) scores 64% and 53%, and GPT-6.1 Sol (max) scores 56% and 58%. xhigh reasoning helps on the science tasks, lifting Terminal-Bench-Science from 41% at high to 50%, but makes no difference on Terminal-Bench 4.0 (54% at both). Science scores are even across domains, from 46% in earth sciences to 53% in physical sciences
➤ Low cost for its intelligence, with high token use at xhigh: Hydrogen is priced at $1.50/$7.50 per million input/output tokens. At xhigh it costs ~32% as much per task as Claude Sonnet 5.5 (max) for near-equal intelligence, but ~2.5x as much as GPT-6.1 Sol (max). xhigh nearly doubles output tokens compared with high for a 3 point gain in Intelligence, and Cost per Task falls from $3.16 at xhigh to $1.87 at high. Medium ($0.80) and low ($0.29) cost less again, but score 41 and 27 on the Intelligence Index
➤ On the Time per Task vs. Intelligence Pareto frontier: Gemini 4 Hydrogen has an output speed of ~200 output tokens per second. With high, medium, and low reasoning effort, Gemini 4 Hydrogen is on the Time per Task vs. Intelligence Pareto frontier, meaning no models are both more intelligent and have a lower Time per Task
Key model details:
➤ Context Window: 1M tokens
➤ Multimodality: Text, image, video, and speech input, with text output
➤ Reasoning efforts: Gemini 4 Hydrogen offers four reasoning levels (low, medium, high, and xhigh) with xhigh new in this release
➤ Pricing: $1.50/$7.50 per 1M input/output tokens. Cached input tokens receive a 95% discount ($0.075)
Congratulations to the @GoogleDeepMind team on the launch!
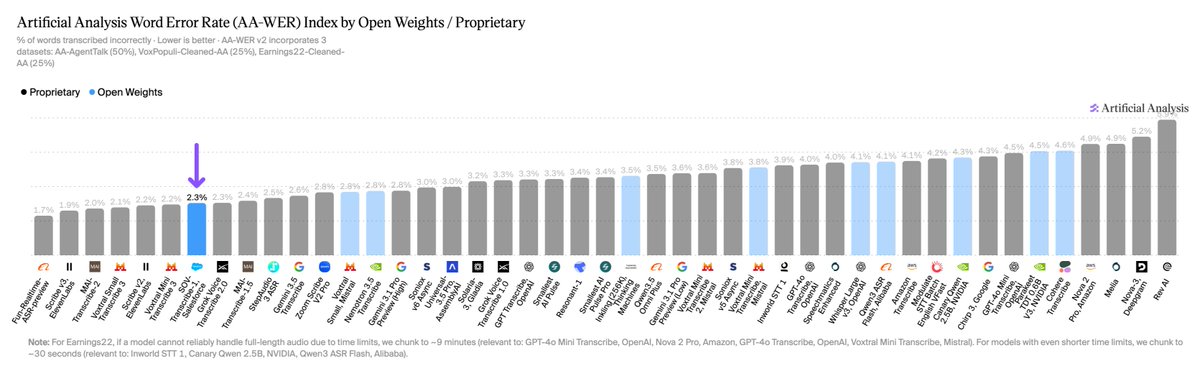
SOV-Transcribe-1 is my first pick to test for self-hosted transcription. AA puts it #1 in open weights at 2.3% word error, versus 1.7% for the overall leader. Apache 2.0, but non-streaming. The win is control over your audio, not the accuracy crown.
SOV-Transcribe-1 is the new #1 open weights Speech to Text model, scoring 2.3% on the AA-WER Index with 4.6B active parameters. It ranks #7 of 44 models overall, including proprietary models.
Congratulations to @salesforce and the Missionforce Sovereign AI team on the release! 🧵