Apparently spatial intelligence is worth 𝟖.𝟐𝐁 now. We settled for a 𝐍𝐞𝐮𝐫𝐈𝐏𝐒 acceptance 😄
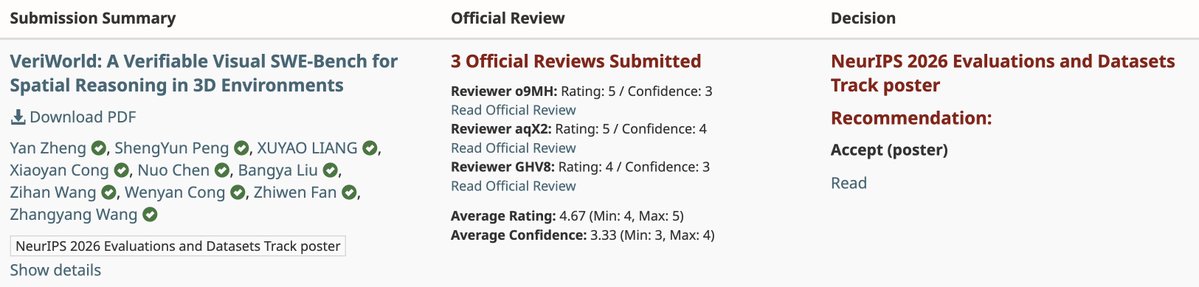
Excited that 𝐕𝐄𝐑𝐈𝐖𝐎𝐑𝐋𝐃 was accepted to the 𝐍𝐞𝐮𝐫𝐈𝐏𝐒 𝟐𝟎𝟐𝟔 E&D Track 🎉
We study how VLMs perceive, reason, and act in interactive 3D worlds 🌐. We find that they often reason well once spatial structure is given explicitly, but still struggle to extract that structure from visual input 👀. We also find that the interaction setup itself can significantly change the outcome ⚙️.
Big thanks to @YanZhengtexas & Atlas Wang 🙌
More soon!
#NeurIPS2026 #SpatialIntelligence #VLMs
🎉Our paper "Interpretation Meets Safety: A Survey on Interpretation Methods and Tools for Improving LLM Safety" has been accepted to EMNLP 2025 Main Track! @emnlpmeeting
👉First survey connecting LLM interpretation & safety
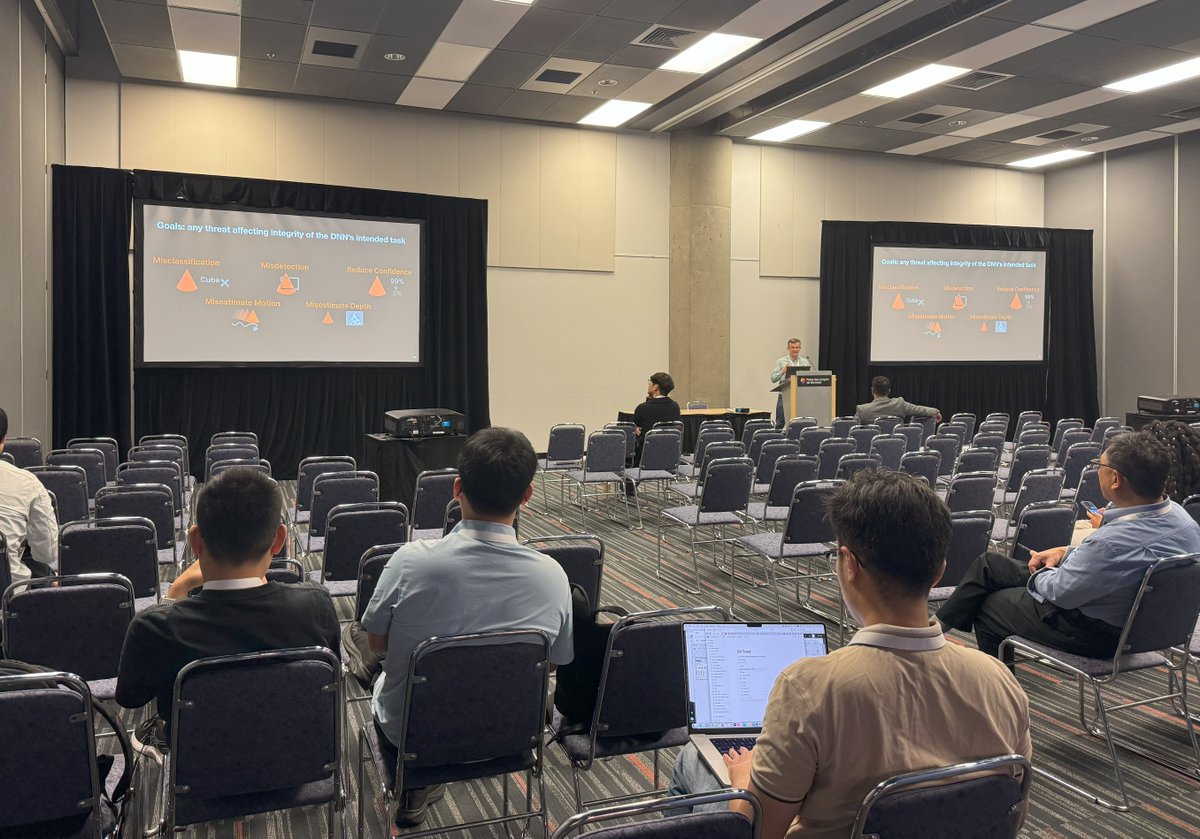
#IJCAI2025 Matthew Hull, Georgia Tech, delivering their talk #8557: RenderBender: A Survey on Adversarial Attacks Using Differentiable Rendering at the CV: attacks session.
🚨 New work: We rethink how we finetune safer LLMs — not by filtering after the generation, but by tracking safety risk token by token during training.
We repurpose guardrail models like 🛡️ Llama Guard and Granite Guardian to score evolving risk across each response 📉 — giving rise to the STAR ⭐ score, a fine-grained safety signal that enables more targeted safety supervision.
On top of this, we introduce ⭐DSS (STAR-Guided Dynamic Safety Shaping) — a training method that 🚫 suppresses unsafe patterns, 💪 preserves capability, and generalizes across LLMs, guardrails, harm levels, and datasets.
Our method outperforms "Deep Token," the method from this year’s #iclr2025 Best Paper 🏆 — remaining robust against key finetuning-as-a-service threats like 🔄 response adaptation, 🧪 prompt poisoning, and 🛑 harmful prefilling.
#MachineLearning #DeepLearning #LLM #AISafety #Alignment #Finetuning
@ChatGPTapp has a new sub-window that seems intended to display reasoning chain-of-thought but the display truncates and is blanked after a few output words on MacOS
Highly niche problems - @ChatGPTapp app always wants to emphasize parts of an LaTeX equation using \underbrace but it can't render with display math so it just displays as raw chars. When I ask it to re-generate w/out \underbrace, it works great!
Diffusion models leverage a variety of samplers.
Deterministic methods like DDIM produce orderly paths. In contrast, stochastic samplers like DDPM produce chaotic trajectories.
Despite their differences, both methods draw valid samples from the underlying distribution.
Create heatmaps that localize text concepts in generated videos.
We discovered that our approach, ConceptAttention, can be directly extended from image generation to video generation models!
It's amazing how simple techniques often generalize way better than more complex ones.
Diffusion Transformers aren't just generative models, but also powerful multi-modal encoders.
ConceptAttention creates rich heatmaps of text concepts in images from DiT representations.
This even works on real images, and can be applied to tasks like segmentation!
Demo 👇
Transformer Explainer
Interactive Learning of Text-Generative Models
discuss: https://t.co/p1GMsyhsEI
Transformers have revolutionized machine learning, yet their inner workings remain opaque to many. We present Transformer Explainer, an interactive visualization tool designed for non-experts to learn about Transformers through the GPT-2 model. Our tool helps users understand complex Transformer concepts by integrating a model overview and enabling smooth transitions across abstraction levels of mathematical operations and model structures. It runs a live GPT-2 instance locally in the user's browser, empowering users to experiment with their own input and observe in real-time how the internal components and parameters of the Transformer work together to predict the next tokens. Our tool requires no installation or special hardware, broadening the public's education access to modern generative AI techniques.
Introducing ClickDiffusion!
We developed a system for precise image manipulation and generation that combines natural language instructions with visual feedback provided by the user through a direct manipulation interface.
@DJSnM@neiltyson I can't believe how many people taught _only_ the equal transit theory (still widely accepted!). I was also taught this way when I started flying and have only recently realized that there is more to it.
Looking to convert your tables from images and PDFs to HTML? Check out our UniTable! It outperforms both GPT-4V and LLaVA-1.6 in table recognition. #TableRecognition
Paper and code in thread 🧵