DevOps Interview Questions asked for my friend with 4 Years of Experience.
1. If you implement HPA for StatefulSets and a new pod is created, will the PVC be empty? How would the pod serve requests?
2. When would you prefer an on-premises Kubernetes cluster over EKS, and vice versa?
3. Questions on ECR.
4. In-depth Kubernetes architecture: functioning of every component. How do you join a new node to the cluster? How do you add a new control plane node?
5. Apart from kubelet, is there any similar agent to manage the control plane components?
6. When would you implement HPA and VPA? Provide examples.
7. Node selectors, taints, and tolerations.
8. A pod is in Pending state. What are the possible reasons?
9. How would you secure a Kubernetes cluster (both container-level and infrastructure-level) using native Kubernetes features?
10. Which controller manages self-managed worker nodes?
11. What is Karpenter? On which metrics does it scale nodes up and down?
12. The complete process for upgrading an EKS cluster.
13. Helm commands: How do you deploy an application using Helm? How do you integrate Helm deployments into CI/CD?
14. Project-specific: How would you set up a new environment on AWS using Terraform for infrastructure provisioning?
15. How many clusters are you currently managing? How many add-ons have you deployed?
16. Why would you deploy an application as a StatefulSet?
17. How do you provision infrastructure using Terraform in a CI/CD pipeline?
Are these questions reasonable for a 4 YOE role, or are they over-expectations? What do you think 👇
Most DevOps engineers deploy to Kubernetes without understanding how their pods actually talk to each other.
Let me break down Kubernetes networking in the simplest way possible:
🔹 Level 1: Inside a Pod (Localhost)
All containers in the same pod share the same network namespace. They talk to each other via localhost — just like processes on your laptop.
Example: Your app container talks to a sidecar on 127.0.0.1:8080
🔹 Level 2: Same Node (Virtual Cables)
Pods on the same node connect through veth pairs (virtual ethernet cables) and a Linux bridge. Think of it like plugging devices into the same network switch.
Your pod gets an IP. Another pod gets an IP. The bridge routes traffic between them.
🔹 Level 3: Different Nodes (Overlay Networks)
This is where it gets interesting. Pods on different nodes need to talk across physical machines.
CNI plugins (like Calico, Flannel, Cilium) create overlay networks using:
- IP-in-IP tunneling wraps your packet inside another packet
- VXLAN creates a virtual Layer 2 network over Layer 3
Your pod thinks it’s on the same network. It’s not. CNI handles the magic.
🔹 Level 4: Services (NAT Translation)
Pods are ephemeral. Their IPs change. Services solve this.
When you hit a Service IP, Kubernetes uses iptables (or IPVS) to NAT the request to healthy pod IPs behind that service.
Service IP → Load balances to → Pod IP 1, Pod IP 2, Pod IP 3
You don’t need to be a networking expert. But you do need to understand how your pods communicate.
DevOps Architect Interview at Atlassian
Round 1 – Infra, Kubernetes, and Cloud Patterns (45 mins)
• Design a multi-tenant EKS cluster with isolation across dev, QA, and prod, with no noisy neighbors.
• What’s your approach to managing 10+ Kustomize overlays without drift or duplication?
• Explain how you’d secure cross-region S3 replication and validate data integrity at scale.
• What happens when systemd hits a failing unit in a containerized node? How would you auto-recover?
• Walk through your strategy to detect & mitigate pod-to-pod lateral movement inside a cluster.
• How do you perform zero-downtime upgrades for a stateful workload using Helm 3?
• Describe a hybrid cloud routing architecture between GCP and AWS. Where do you enforce boundaries?
• Your Terraform state got corrupted during a backend migration. Rebuild strategy?
• Bash One-liner: Find all running containers using more than 500MB RSS memory on a node.
Round 2 – Real Fire, RCA, and Chaos Control (75 mins)
• A new AWS ALB config caused TLS handshakes to fail intermittently. Walk through your full RCA path.
• Kubernetes nodes are healthy. But kubectl logs is blank for critical pods. What’s happening?
• You deployed a sidecar logging agent. Suddenly, CPU throttling spikes. Diagnose and rollback.
• Autoscaling isn’t kicking in despite the CPU crossing the threshold. What’s broken — metrics, HPA, or API server?
• Prod users reporting 504s, but ELB health checks are green. Explain your isolation + triage process.
• Systemd journal logs vanish on reboot across some AMIs. What do you check in the image build and boot sequence?
• A production pod was OOMKilled, but you can’t find logs. Walk through a forensic-level debug.
• Kernel panic on a GKE node mid-deploy. How do you identify if it’s infra, base image, or app-level?
Round 3 – Leadership, Engineering Influence & Production Principles (30 mins)
• How do you design infrastructure that empowers devs without giving them footguns?
• What’s your Linux-level checklist before approving any custom AMI to production?
• You’ve been asked to move from centralized logging to a service-mesh-based observability model. Your tradeoffs?
• Describe how you simulate production-level chaos in staging for Kubernetes.
• How do you handle pushback from leadership when your SLOs threaten velocity?
💡 TL;DR
If you haven’t:
Debugged a kernel panic in a prod cluster
Recovered from Terraform state corruption mid-deploy
Rolled back a broken Helm upgrade with zero visibility
Built cross-cloud boundaries that enforce security
Then, Atlassian won’t just test your YAML fluency.
They’ll test your judgment under system stress.
@airtelindia don't buy airtel fiber internet service. Worst customer service ever. It's been 2 days my internet is not working. The excuse they are saying we have assign this ticket to NOC team. Don't buy.
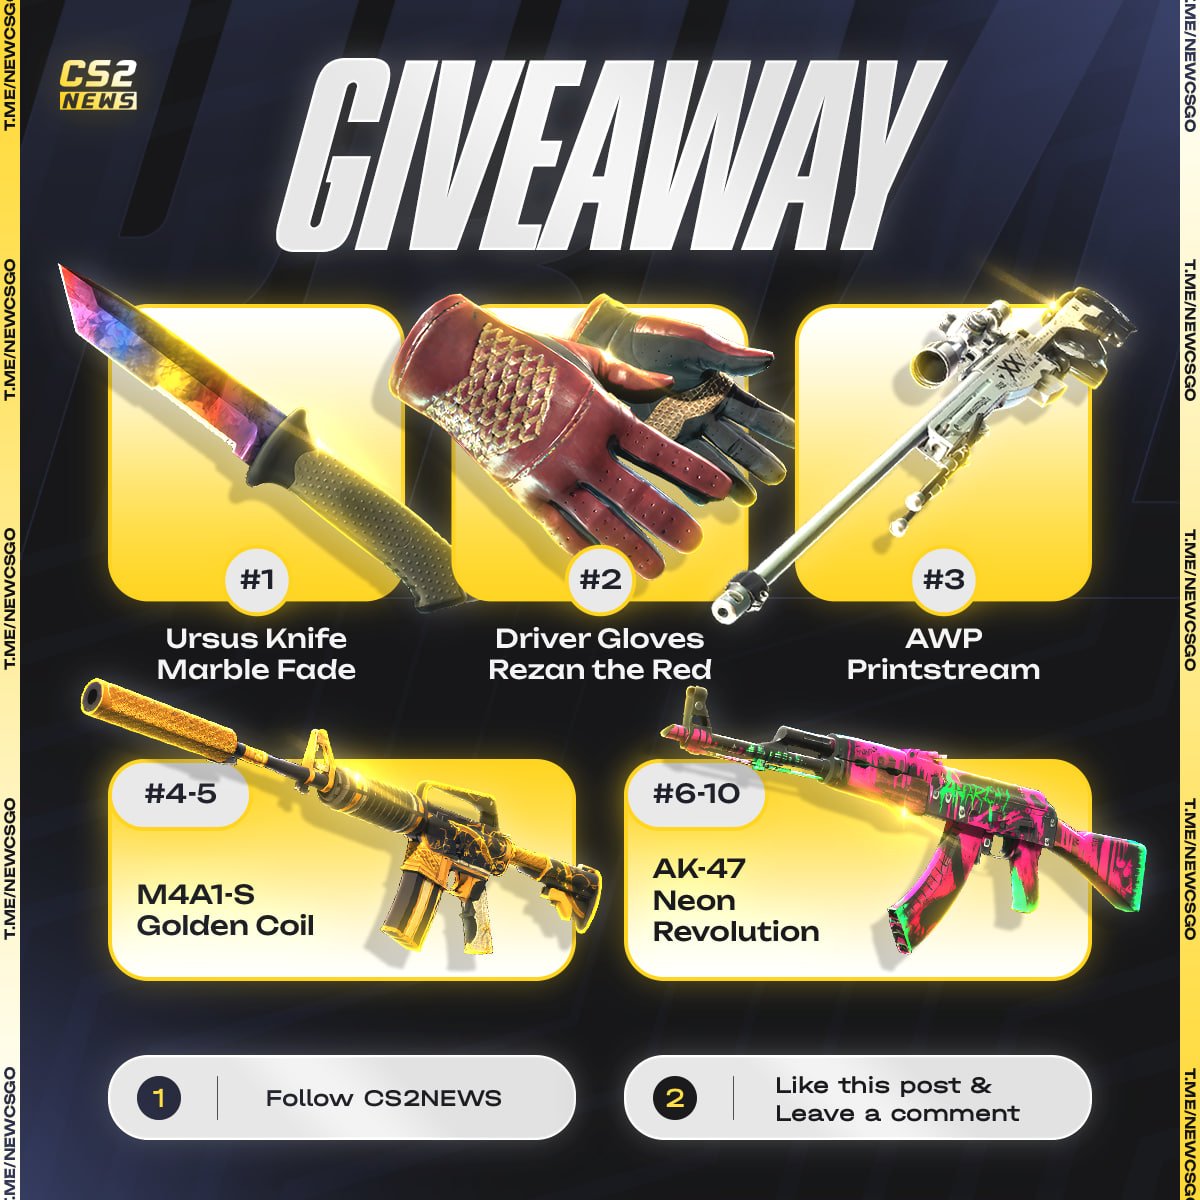
🎫 GIVEAWAY: $1,000+ IN SKINS FOR 10 WINNERS
▪️ Follow CS2 NEWS
▪️ Like this post + Leave a comment
We’ll announce the results on July 10. Good luck! 🙌🏻