Use the uploaded storyboard image <<<image_1>>> as the direct visual reference and shot-by-shot guide for this video — its 6 panels show the exact pose, action, framing, and identity to hit at each corresponding timestamp. Use the uploaded Flowery Whiff product photo <<<image_2>>> as the exact product reference for color, label geometry, and packaging accuracy throughout.
CONTINUOUS MOTION — HIGHEST PRIORITY: This must render as ONE single, unbroken, continuously flowing take from 0:00 to 0:15. There must be NO hard cuts, NO jump cuts, NO scene changes, and NO abrupt snapping between poses anywhere in the video — not even at the storyboard's panel boundaries. Treat the 6 panels as waypoints along one fluid, uninterrupted camera-and-body movement, not as separate shots to stitch together. Every transition between panels must be built as continuous physical motion: her head, hands, and the camera drift smoothly and organically from one pose into the next, at a natural human pace, the same way a real person's body moves through a sequence of actions without ever freezing or jump-snapping into position.
Preserve the woman's identity exactly as shown across all 6 storyboard panels: dark curly brown hair, green eyes, warm olive/tan skin tone, casual sage-green t-shirt. Preserve the white cylindrical tube shape, purple/lavender label with tree illustration graphic, and exact label text ("FLOWERY WHIFF" / "DEODORANT STICK" / "BERGAMOT & CEDARWOOD" / "40g/1.40oz") exactly as shown in <<<image_2>>> — treat the label as a fixed, rigid graphic that does not warp or distort as the tube moves or rotates.
Handheld smartphone selfie shot, held at arm's length, single continuous take — she is outdoors in warm golden-hour natural sunlight, soft-focus grass and wildflowers in the background, wearing a casual sage-green t-shirt, speaking straight to the lens with candid, off-center energy — natural head tilts and small shifts in angle throughout, not a static symmetric mirror pose.
[0:00-0:03 — flowing continuously from Panel 1's pose] Warm, relaxed, candid smile, head gently tilted, golden light catching her hair, hands not yet on the product: "Okay, so this has become part of my everyday routine."
[0:03-0:05.5 — smoothly transitioning into Panel 2] Her hand rises into frame carrying the Flowery Whiff stick, and she turns it in one continuous motion so the label faces the lens: "It's from this tiny UK brand, Flowery Whiff—"
[0:05.5-0:07 — flowing into Panel 3] A small, natural shrug and knowing half-smile, the product easing to a slightly different angle in her hand as she speaks: "—nobody's really heard of them yet—"
[0:07-0:10 — flowing into Panel 4] Her thumb twists the cap free in one smooth, unhurried motion, revealing the product underneath, cap held loosely in her other hand: "hand-made, vegan, no aluminum."
[0:10-0:12.5 — flowing into Panel 5] She raises the open stick toward her collarbone/shoulder in one continuous arc, eyes gently closing, head tilting back slightly as if catching the scent on the breeze: "Bergamot and cedarwood..."
[0:12.5-0:15 — flowing into Panel 6] Her eyes reopen, head tilts back toward the lens, and a warm, satisfied smile forms as the motion settles: "so warm, kind of addictive."
Camera holds a medium close-up, chest-up framing throughout — natural handheld micro-shake and breathing sway only, drifting smoothly to follow her head and hand movements, no zooms, no pans, no re-cuts, no re-framing.
Lighting stays warm and natural throughout, matching the storyboard reference: golden-hour sunlight, soft directional warmth, gentle lens flare acceptable, no artificial studio light, no cool/blue tones.
Environment holds constant: outdoor natural setting, soft-focus grass and wildflowers, consistent golden-hour color temperature from first frame to last — no environment or location changes.
Audio: her voice delivered live and in sync with natural lip movement, unhurried conversational pacing; ambient outdoor tone only (faint breeze, distant birdsong); no background music, no added SFX beyond the natural cap-twist sound.
Negative rules: absolutely no cuts, no jump cuts, no scene breaks, no freeze-frames, no panel/grid artifacts carried over from the storyboard reference image, no text overlays, no captions, no watermark, no additional people, no camera zooms or pans, no drift in facial identity, no distortion or invented text on the product label, no lighting or environment changes mid-take, no snapping or teleporting between poses — every pose change must read as continuous physical movement.
The useful part wasn’t one “magic prompt.”
It was describing the image in priority order:
1. Composition
2. Face + expression
3. Hair silhouette
4. Product interaction
5. Wardrobe
6. Lighting
7. Environment
8. Camera texture
Next: same locked prompt, different model.
What transferred
What transferred well:
• Kitchen layout
• Lighting and colour palette
• Wardrobe
• Product placement and grip
• Hair category
• Overall UGC framing
The prompt rebuilt the scene’s visual system surprisingly well.
What did not transfer
What didn’t transfer:
• Exact facial identity
• Individual curl paths
• Precise crop and subject scale
• Cabinet and prop placement
That matters: detailed text can reconstruct a creative direction, but it cannot guarantee an identity clone.
Test conditions
Test conditions:
• Source: fictional AI adult
• Reconstruction input: text only
• Reference supplied: no
• Attempts: 1
• Cherry-picking: none
• Retouching: none
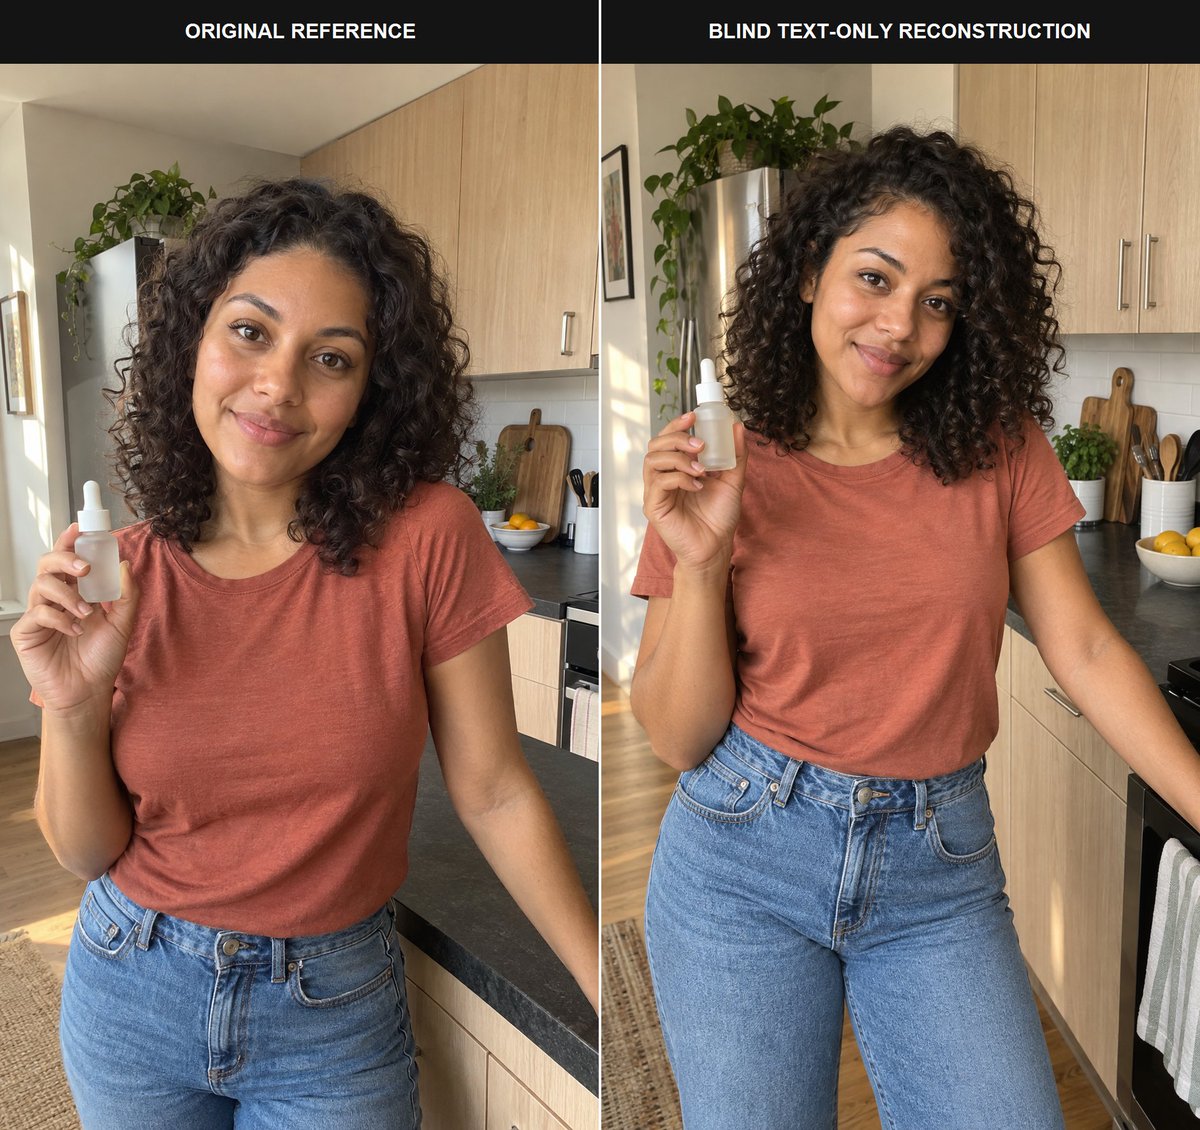
I scored composition, identity, hair, pose, product, wardrobe, lighting and environment separately.
Can a text prompt rebuild a UGC image without seeing it?
I made a fictional AI reference, analysed it, then regenerated it from text alone.
First attempt:
Scene + style: 8.7/10
Identity: 6.5/10
The visual recipe transferred. The person didn’t.
Both images are AI-generated.
Use the uploaded storyboard image <<<image_1>>> as the direct visual reference and shot-by-shot guide for this video — its 6 panels show the exact pose, action, framing, and identity to hit at each corresponding timestamp. Use the uploaded Flowery Whiff product photo <<<image_2>>> as the exact product reference for color, label geometry, and packaging accuracy throughout.
CONTINUOUS MOTION — HIGHEST PRIORITY: This must render as ONE single, unbroken, continuously flowing take from 0:00 to 0:15. There must be NO hard cuts, NO jump cuts, NO scene changes, and NO abrupt snapping between poses anywhere in the video — not even at the storyboard's panel boundaries. Treat the 6 panels as waypoints along one fluid, uninterrupted camera-and-body movement, not as separate shots to stitch together. Every transition between panels must be built as continuous physical motion: her head, hands, and the camera drift smoothly and organically from one pose into the next, at a natural human pace, the same way a real person's body moves through a sequence of actions without ever freezing or jump-snapping into position.
Preserve the woman's identity exactly as shown across all 6 storyboard panels: dark curly brown hair, green eyes, warm olive/tan skin tone, casual sage-green t-shirt. Preserve the white cylindrical tube shape, purple/lavender label with tree illustration graphic, and exact label text ("FLOWERY WHIFF" / "DEODORANT STICK" / "BERGAMOT & CEDARWOOD" / "40g/1.40oz") exactly as shown in <<<image_2>>> — treat the label as a fixed, rigid graphic that does not warp or distort as the tube moves or rotates.
Handheld smartphone selfie shot, held at arm's length, single continuous take — she is outdoors in warm golden-hour natural sunlight, soft-focus grass and wildflowers in the background, wearing a casual sage-green t-shirt, speaking straight to the lens with candid, off-center energy — natural head tilts and small shifts in angle throughout, not a static symmetric mirror pose.
[0:00-0:03 — flowing continuously from Panel 1's pose] Warm, relaxed, candid smile, head gently tilted, golden light catching her hair, hands not yet on the product: "Okay, so this has become part of my everyday routine."
[0:03-0:05.5 — smoothly transitioning into Panel 2] Her hand rises into frame carrying the Flowery Whiff stick, and she turns it in one continuous motion so the label faces the lens: "It's from this tiny UK brand, Flowery Whiff—"
[0:05.5-0:07 — flowing into Panel 3] A small, natural shrug and knowing half-smile, the product easing to a slightly different angle in her hand as she speaks: "—nobody's really heard of them yet—"
[0:07-0:10 — flowing into Panel 4] Her thumb twists the cap free in one smooth, unhurried motion, revealing the product underneath, cap held loosely in her other hand: "hand-made, vegan, no aluminum."
[0:10-0:12.5 — flowing into Panel 5] She raises the open stick toward her collarbone/shoulder in one continuous arc, eyes gently closing, head tilting back slightly as if catching the scent on the breeze: "Bergamot and cedarwood..."
[0:12.5-0:15 — flowing into Panel 6] Her eyes reopen, head tilts back toward the lens, and a warm, satisfied smile forms as the motion settles: "so warm, kind of addictive."
Camera holds a medium close-up, chest-up framing throughout — natural handheld micro-shake and breathing sway only, drifting smoothly to follow her head and hand movements, no zooms, no pans, no re-cuts, no re-framing.
Lighting stays warm and natural throughout, matching the storyboard reference: golden-hour sunlight, soft directional warmth, gentle lens flare acceptable, no artificial studio light, no cool/blue tones.
Environment holds constant: outdoor natural setting, soft-focus grass and wildflowers, consistent golden-hour color temperature from first frame to last — no environment or location changes.
Audio: her voice delivered live and in sync with natural lip movement, unhurried conversational pacing; ambient outdoor tone only (faint breeze, distant birdsong); no background music, no added SFX beyond the natural cap-twist sound.
Negative rules: absolutely no cuts, no jump cuts, no scene breaks, no freeze-frames, no panel/grid artifacts carried over from the storyboard reference image, no text overlays, no captions, no watermark, no additional people, no camera zooms or pans, no drift in facial identity, no distortion or invented text on the product label, no lighting or environment changes mid-take, no snapping or teleporting between poses — every pose change must read as continuous physical movement.
THE BLACK BOX OF AI VIDEO PRODUCTION IS FINALLY WIDE OPEN
Higgsfield just open-sourced their 'Originals' productions, making every single cinematic shot an open book 🤯
Instead of hiding their best workflows, they are giving creators the exact production blueprints.
Here's what's unlocked:
→ raw prompts and exact generation settings
→ all image and audio reference files
→ workflows for 4K and native lip-sync
You don't have to guess how to build cinematic, character-consistent AI video anymore.
You can literally download the clips, copy the exact setups, and remix them instantly for your own projects 👊
Prompt and links in 🧵↓
this is just getting better and better.
15-Second Ultra-Realistic Tiger Zoo Selfie Vlog created using Seedance 2.0
Prompt:
Style A single continuous front-facing smartphone selfie video recorded entirely by a young Korean woman visiting a zoo. She holds the phone herself at arm's length for the entire video. No cuts, no third-person shots, no cinematic camera work, no drone footage, no tripod. Authentic modern smartphone footage: Natural handheld shake Real walking bounce Occasional autofocus adjustments Minor exposure fluctuations Slight framing imperfections Natural front-camera lens distortion Realistic skin texture Natural daylight No beauty filters No skin smoothing No color grading No artificial HDR Character A cheerful Korean woman in her early twenties with shoulder-length dark hair tied in a loose ponytail. Outfit remains identical throughout: Oversized cream hoodie Relaxed blue jeans White sneakers She always has exactly two hands. One hand holds the phone at all times. Environment A modern zoo on a pleasant sunny afternoon. Natural ambient sounds only: Visitors chatting Footsteps Distant birds Light wind through trees Occasional animal sounds No music, subtitles, captions, logos, or watermarks. Animal Only one Bengal tiger appears in the entire video. The tiger is realistic, anatomically correct, sharp, and consistent throughout. No duplicate animals, morphing, glitches, extra limbs, or unrealistic behavior. The woman remains safely behind the visitor barrier at all times. Scene (15 Seconds) 0–5 seconds Walking along a zoo path while filming herself. The tiger enclosure comes into view behind her. She smiles excitedly at the camera. Dialogue: "Guys... there’s actually a tiger right behind me." 5–10 seconds She reaches the viewing area. The tiger slowly walks across the habitat behind her. It briefly glances toward the camera. She laughs in surprise. Dialogue: "Okay, that was way cooler than I expected." 10–15 seconds She sits on a nearby bench still holding the phone. The tiger relaxes in the shade behind her. A gentle breeze moves her hair naturally. She smiles and shakes her head. Dialogue: "I could honestly watch this all day." She slowly lowers the phone, creating a natural imperfect ending as the recording stops. Target Result: indistinguishable from a genuine smartphone selfie vlog uploaded by a real zoo visitor, with natural human behavior, authentic phone-camera imperfections, realistic tiger movement, and zero AI-generated appearance.
this is just getting better and better.
15-Second Ultra-Realistic Tiger Zoo Selfie Vlog created using Seedance 2.0
Prompt:
Style A single continuous front-facing smartphone selfie video recorded entirely by a young Korean woman visiting a zoo. She holds the phone herself at arm's length for the entire video. No cuts, no third-person shots, no cinematic camera work, no drone footage, no tripod. Authentic modern smartphone footage: Natural handheld shake Real walking bounce Occasional autofocus adjustments Minor exposure fluctuations Slight framing imperfections Natural front-camera lens distortion Realistic skin texture Natural daylight No beauty filters No skin smoothing No color grading No artificial HDR Character A cheerful Korean woman in her early twenties with shoulder-length dark hair tied in a loose ponytail. Outfit remains identical throughout: Oversized cream hoodie Relaxed blue jeans White sneakers She always has exactly two hands. One hand holds the phone at all times. Environment A modern zoo on a pleasant sunny afternoon. Natural ambient sounds only: Visitors chatting Footsteps Distant birds Light wind through trees Occasional animal sounds No music, subtitles, captions, logos, or watermarks. Animal Only one Bengal tiger appears in the entire video. The tiger is realistic, anatomically correct, sharp, and consistent throughout. No duplicate animals, morphing, glitches, extra limbs, or unrealistic behavior. The woman remains safely behind the visitor barrier at all times. Scene (15 Seconds) 0–5 seconds Walking along a zoo path while filming herself. The tiger enclosure comes into view behind her. She smiles excitedly at the camera. Dialogue: "Guys... there’s actually a tiger right behind me." 5–10 seconds She reaches the viewing area. The tiger slowly walks across the habitat behind her. It briefly glances toward the camera. She laughs in surprise. Dialogue: "Okay, that was way cooler than I expected." 10–15 seconds She sits on a nearby bench still holding the phone. The tiger relaxes in the shade behind her. A gentle breeze moves her hair naturally. She smiles and shakes her head. Dialogue: "I could honestly watch this all day." She slowly lowers the phone, creating a natural imperfect ending as the recording stops. Target Result: indistinguishable from a genuine smartphone selfie vlog uploaded by a real zoo visitor, with natural human behavior, authentic phone-camera imperfections, realistic tiger movement, and zero AI-generated appearance.