I haven't posted anything in a while...
So here's an implementation of PointPillars, a 3D object detection network using point clouds all done in #VRChat! It's similar to the stuff you see on self driving cars.
Code: https://t.co/poZAxnnqSX
#unity3d#MachineLearning
Remember this meme from 2022 which contrasted DALL·E “mini” against DALL·E 2?
We’re going to see the same thing now for large language model: Community-developed LLMs, some without any forced ‘alignment’ or ‘moralizing’ censorship, vs closed mainstream LLMs run by big companies.
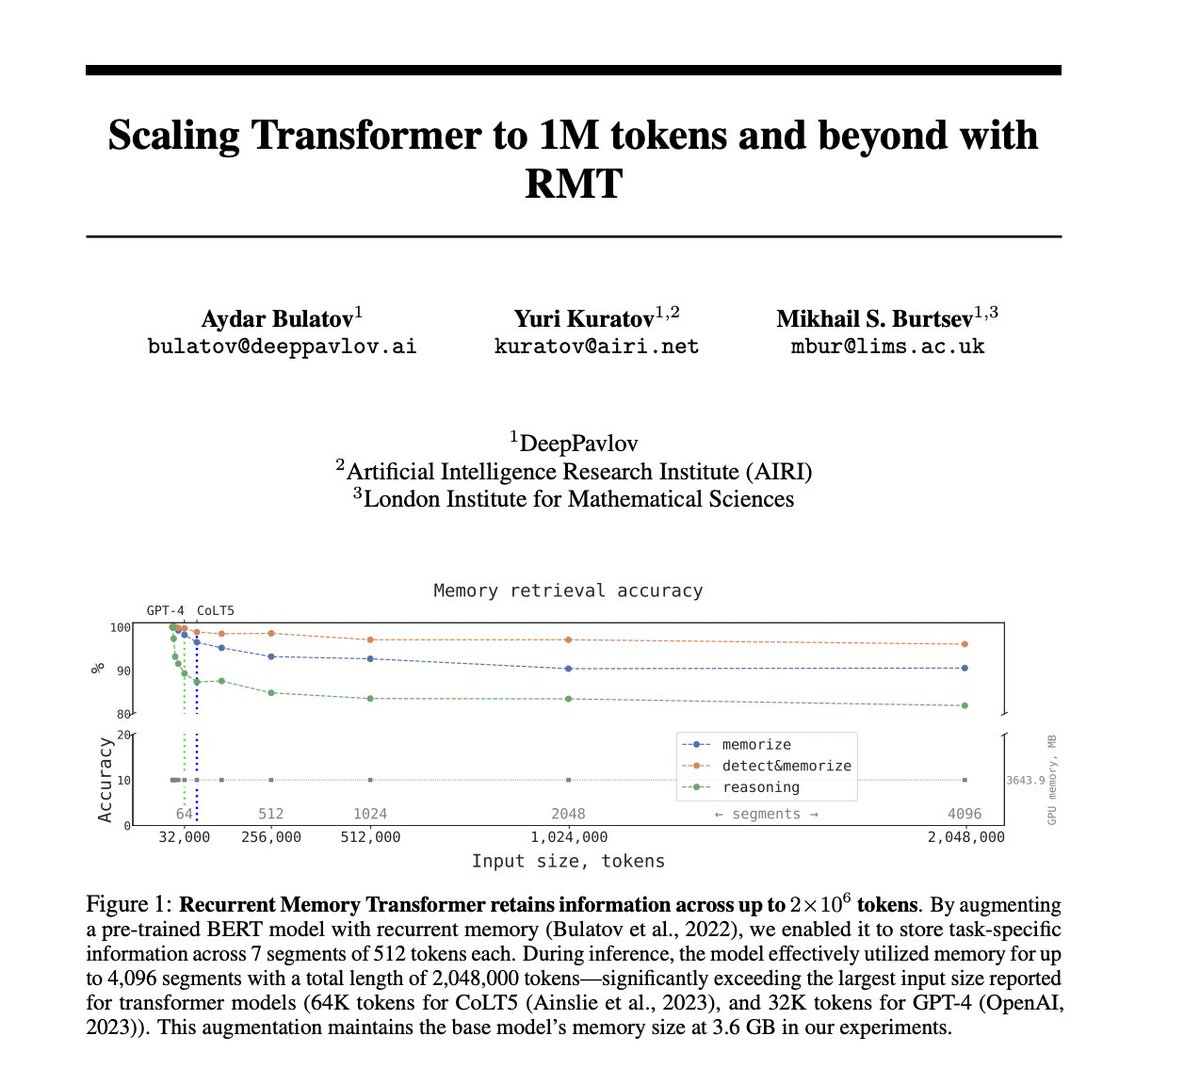
Scaling Transformer to 1M tokens and beyond with RMT
Recurrent Memory Transformer retains information across up to 2 million tokens.
During inference, the model effectively utilized memory for up to 4,096 segments with a total length of 2,048,000 tokens—significantly exceeding the largest input size reported for transformer models (64K tokens for CoLT5 (Ainslie et al., 2023), and 32K tokens for GPT-4 (OpenAI, 2023)). This augmentation maintains the base model’s memory size at 3.6 GB in our experiments
abs: https://t.co/P4KJKpvdx2
github: https://t.co/RQFpBEpTf9
I am releasing version 2.0.0 of my optimizer.
Now VPM & UPM compatible!
Additionally it merges simple toggles in the fx layer into one big direct blend tree.
There is also improved merging of blendshapes that get animated in a fixed ratio to each other.
My Lighthouse in the Snow world is finally out! Enjoy a serene experience with music and raymarchers. Available on PC and Quest! World link in replies #VRChat#unity3d#shaders
How neat. Researchers claim to have found, at long last, an "einstein" tile - a shape that tiles the plane in a pattern that never repeats. First two authors appear to have no academic affiliations. https://t.co/T4UB6Ei6Lo
Presenting Long Suffering by @ElIZAGRACEMUSIC This is one of my favorite songs. I loved making this performance with the help of @TheHoizen and cinematography by @Depereo_
This song is a strong emotional one. I hope I conveyed those feelings through this
https://t.co/GzZaZodEWR
Visual ChatGPT: Talking, Drawing and Editing with Visual Foundation Models
build a system called Visual ChatGPT, incorporating different Visual Foundation Models, to enable the user to interact with ChatGPT by 1) sending and receiving not only languages but also images 2) providing complex visual questions or visual editing instructions that require the collaboration of multiple AI models with multi-steps. 3) providing feedback and asking for corrected results
abs: https://t.co/0nYSa7CupY