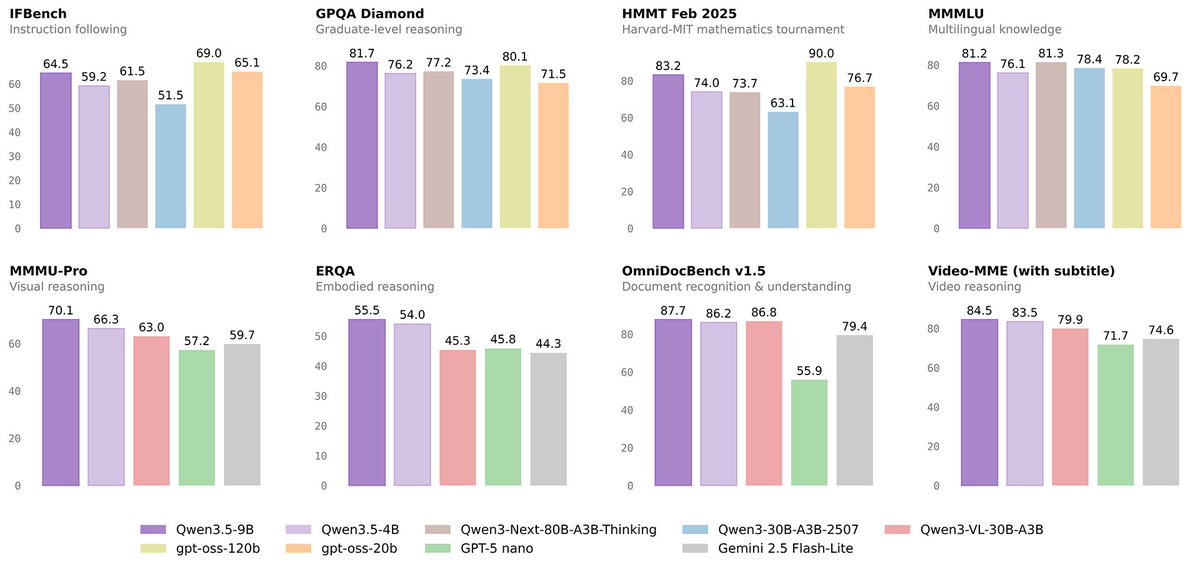
🚀 Introducing the Qwen 3.5 Small Model Series
Qwen3.5-0.8B · Qwen3.5-2B · Qwen3.5-4B · Qwen3.5-9B
✨ More intelligence, less compute.
These small models are built on the same Qwen3.5 foundation — native multimodal, improved architecture, scaled RL:
• 0.8B / 2B → tiny, fast, great for edge device
• 4B → a surprisingly strong multimodal base for lightweight agents
• 9B → compact, but already closing the gap with much larger models
And yes — we’re also releasing the Base models as well.
We hope this better supports research, experimentation, and real-world industrial innovation.
Hugging Face: https://t.co/wFMdX5pDjU
ModelScope: https://t.co/9NGXcIdCWI
When she sees a folder named "Models" on your PC and it all contains some files ending with -
qwen-7b-q2_k.gguf
qwen-14b-q3_k_m.gguf
qwen-32b-q4_k_s.gguf
qwen-72b-q5_k_m.gguf
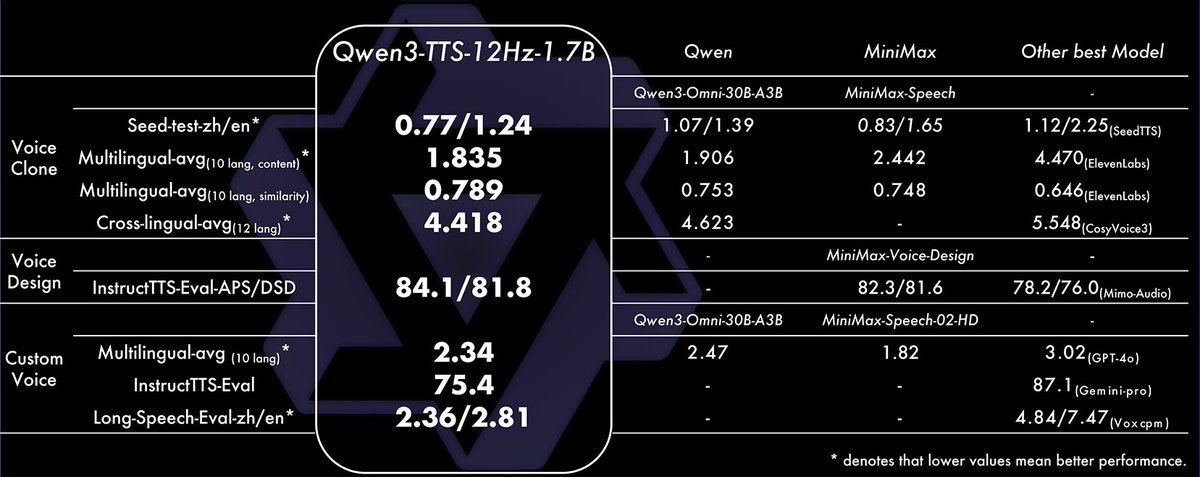
Qwen3-TTS is officially live. We’ve open-sourced the full family—VoiceDesign, CustomVoice, and Base—bringing high quality to the open community.
- 5 models (0.6B & 1.8B)
- Free-form voice design & cloning
- Support for 10 languages
- SOTA 12Hz tokenizer for high compression
- Full fine-tuning support
- SOTA performance
We believe this is arguably the most disruptive release in open-source TTS yet. Go ahead, break it and build something cool. 🚀 Everything is out now—weights, code, and paper. Enjoy. 🧵
Github: https://t.co/X4CNGRpBAG
Hugging Face: https://t.co/QzshIqzYDU
ModelScope: https://t.co/XaWVuDerZ6
Blog: https://t.co/xPER3lyeb5
Paper: https://t.co/9mi5dFyJza
Hugging Face Demo: https://t.co/cL7AyaMDwM
ModelScope Demo: https://t.co/MYpIeYdYN5
API: https://t.co/lIEikdB6uM
🚀 Introducing Qwen-Image-Edit-2511 — a major upgrade over 2509, delivering significantly stronger consistency and more powerful real-world image editing.
✨ What’s new in 2511:
👥 Stronger multi-person consistency for group photos and complex scenes
🧩 Built-in popular community LoRAs — no extra tuning required
💡 Enhanced industrial & product design generation
🔒 Reduced image drift with dramatically improved character & identity consistency
📐 Improved geometric reasoning, including construction lines and structural edits
From identity-preserving portrait edits to high-fidelity multi-person fusion and practical engineering & design workflows, 2511 pushes image editing to the next level.
👉 Try it now:
🎨 Qwen Chat (Image Edit): https://t.co/r2Zcg4OjGc
ElevenLabs has officially LOST to Open-Source
ResembleAI allows you to clone ANY voice without verification using on 5-10 seconds of audio, and dominates on paralinguistic tags for human-like expressions.
Most "fast" text-to-speech models sound robotic. Most "quality" TTS models are slow. None incorporate authentication at a foundational level. @resembleai solved all three.
Chatterbox Turbo delivers:
🟢<150ms time-to-first-sound
🟢State-of-the-art quality that beats larger proprietary models
🟢Natural, programmable expressions
🟢Zero-shot voice cloning with just 5 seconds of audio
🟢PerTh watermarking for authenticated and verifiable audio
🟢Open source – full transparency, no black boxes
Try it on HuggingFace: https://t.co/cPXPQyPrRN
visibility is everything when building agentic systems.
when your agents run, do you know:
✅ what tools they used?
✅ how long tasks took?
✅ why something failed?
✅ what exactly was generated and when?
if not, you’re flying blind.
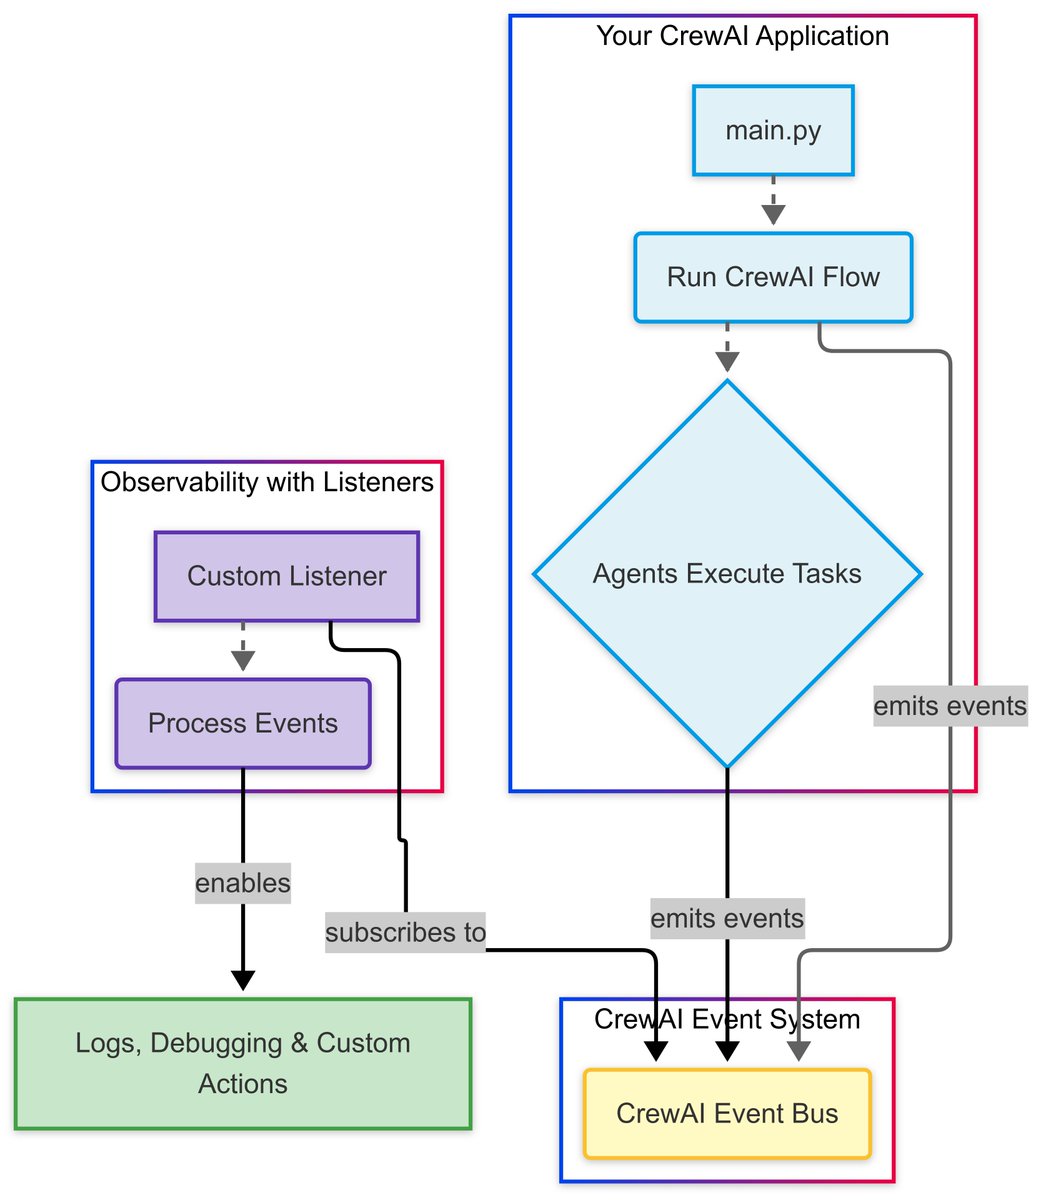
our event system in @crewAIInc emits a full stream of events across your workflows: from flow execution, to agent decisions, to tool usage, to LLM calls.
@TylerReedAI, just dropped an awesome video walking through how to build a custom listener using `BaseEventListener`, and wire up your own monitoring and logging.
here’s what you’ll learn:
🔹 how to create a listener class
🔹 how to hook into events like `FlowStarted`, `TaskCompleted`, `AgentExecutionCompleted` and more...
🔹 how to access event data — including inputs, outputs, errors, timestamps
🔹 why event-driven observability is critical for production systems
and the best part? listeners work out of the box with:
⚡️ Flows
⚡️ Crews
⚡️ Agents
⚡️ Tasks
⚡️ Tools
⚡️ Knowledge
⚡️ LLM calls
huge thanks to Tyler Reed for this excellent walkthrough! 👏
ATTN: After Effects Tool Developers📢
Our 2025 After Effects Command ID searchable list has 411 NEW commands not previously listed! ( 909 total )
Start using the list today to fill in the gaps in the After Effects API🎉
https://t.co/YwJlLNmIhI
#aftereffects#extendscript#cep
totally love the approach of this method
it takes an existing motion video and generates all possible in between combinations of different poses found in the video
makes it possible to completely change the video, pretty smart
In 2022, our team was invited by GIGABYTE to create a concept video for AERO laptops.
We used a wide range of mixed styles in 2D & 3D, traveling through the world created by AERO.
Cursor Composer Agent uses itself by instruction Claude computer use to instruct it inception style!
This was quite difficult to manage and requires some strict management. you can download the script by becoming a patron. link in comment
prompt to cursor agent:
"""use yourself to instruct the use yourself function to instruct you to build a tower defense game in pygame"""
here is the cursor rules:
-----
when you are asked to use yourself. please use the use_yourself function in use_yourself.py. this exists and you can call this directly with your request.
When instructed to use yourself, your argument to the function will be the instructions to an AI agent to use you. so craft the function parameter to instruct the agent to instruct you for whatever the user is asking for
your parameter should start with "I am cursor, please instruct me to..."
you must always call this as terminal command function with a string parameter.
call the function by importing it in command line, it is a sync function so you can use await to call it.
I hope @shaoruu will be proud of me!
----------