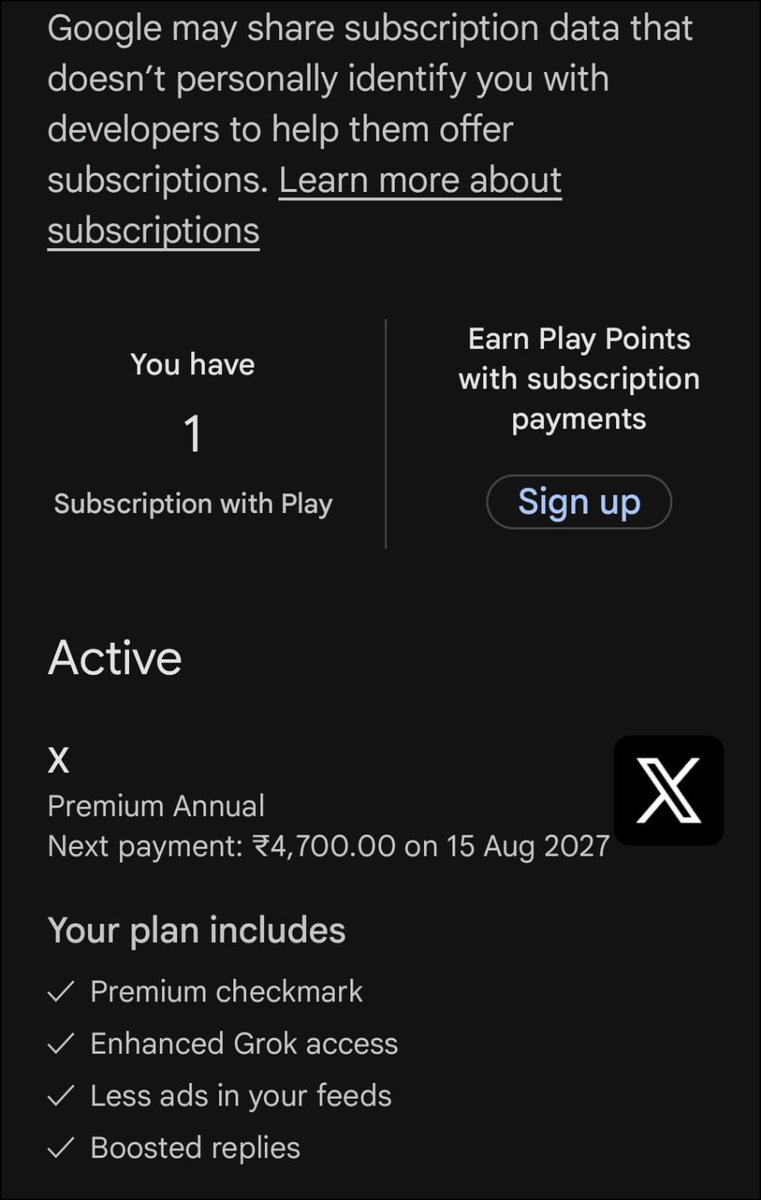
It's been a month @Premium@Support@elonmusk I paid ₹4,700 for X Premium Annual via Google Play, but Premium was never activated. Google confirms my subscription is active, yet X support has only said it’s “raised internally” with no ETA
Weeks of support, no Premium, no refund.
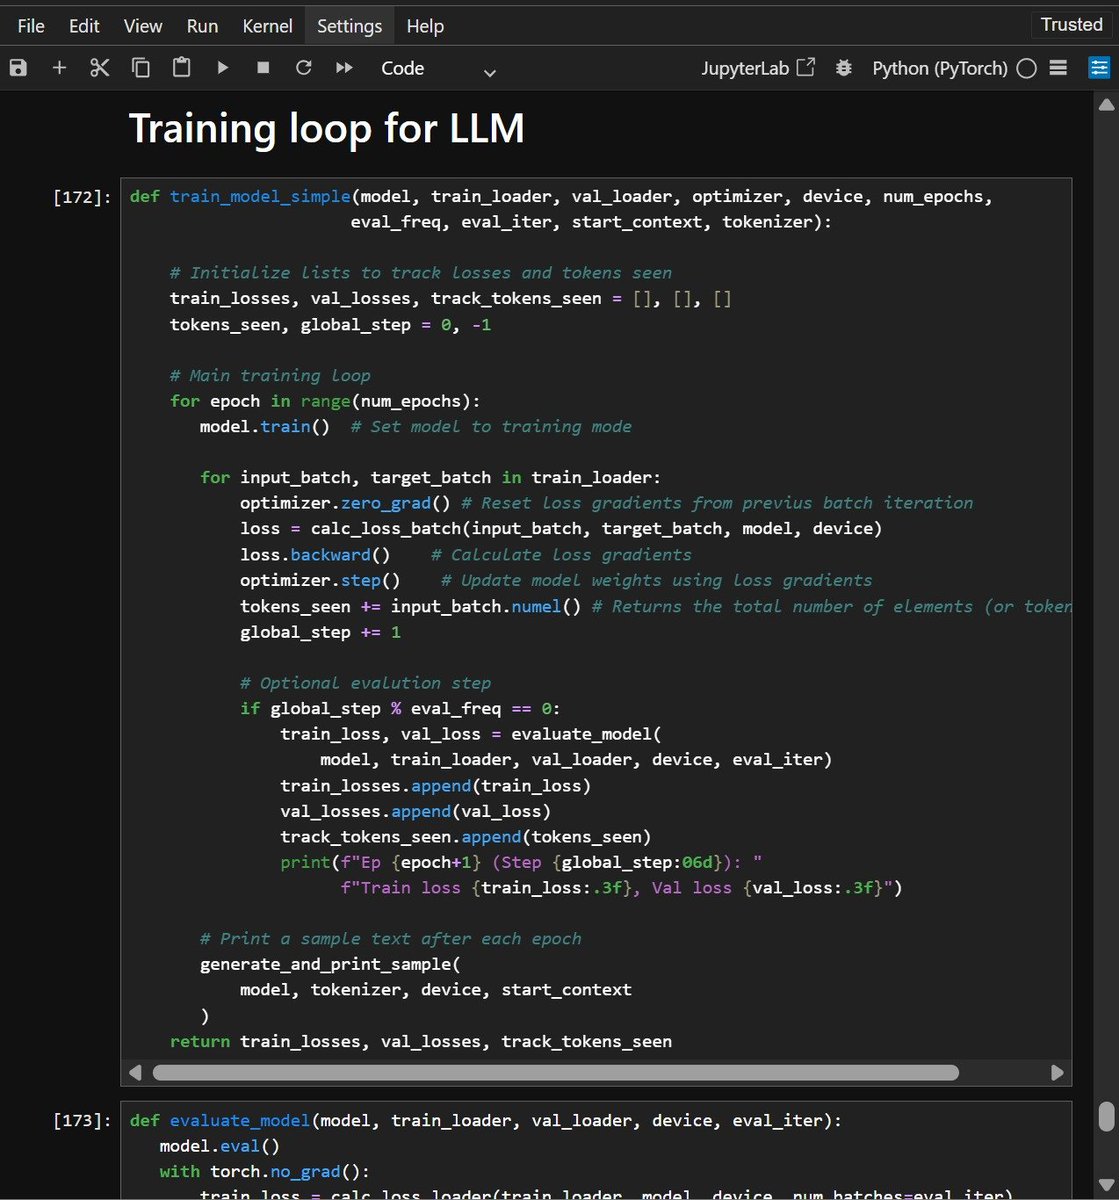
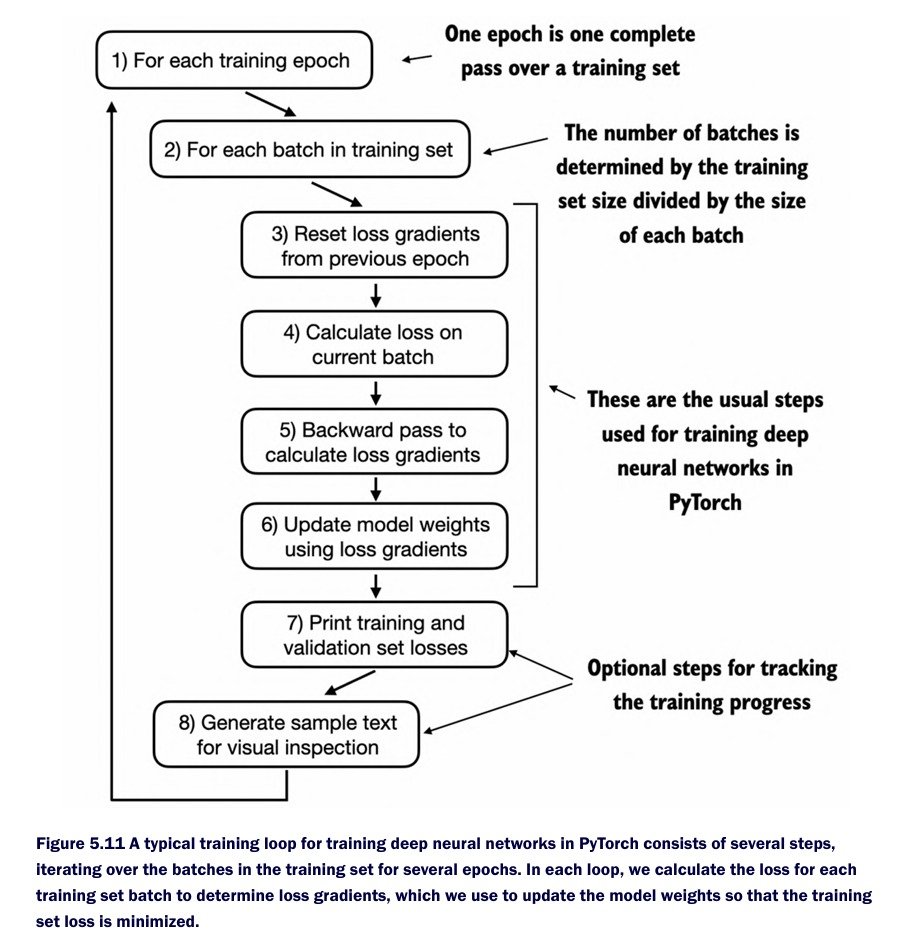
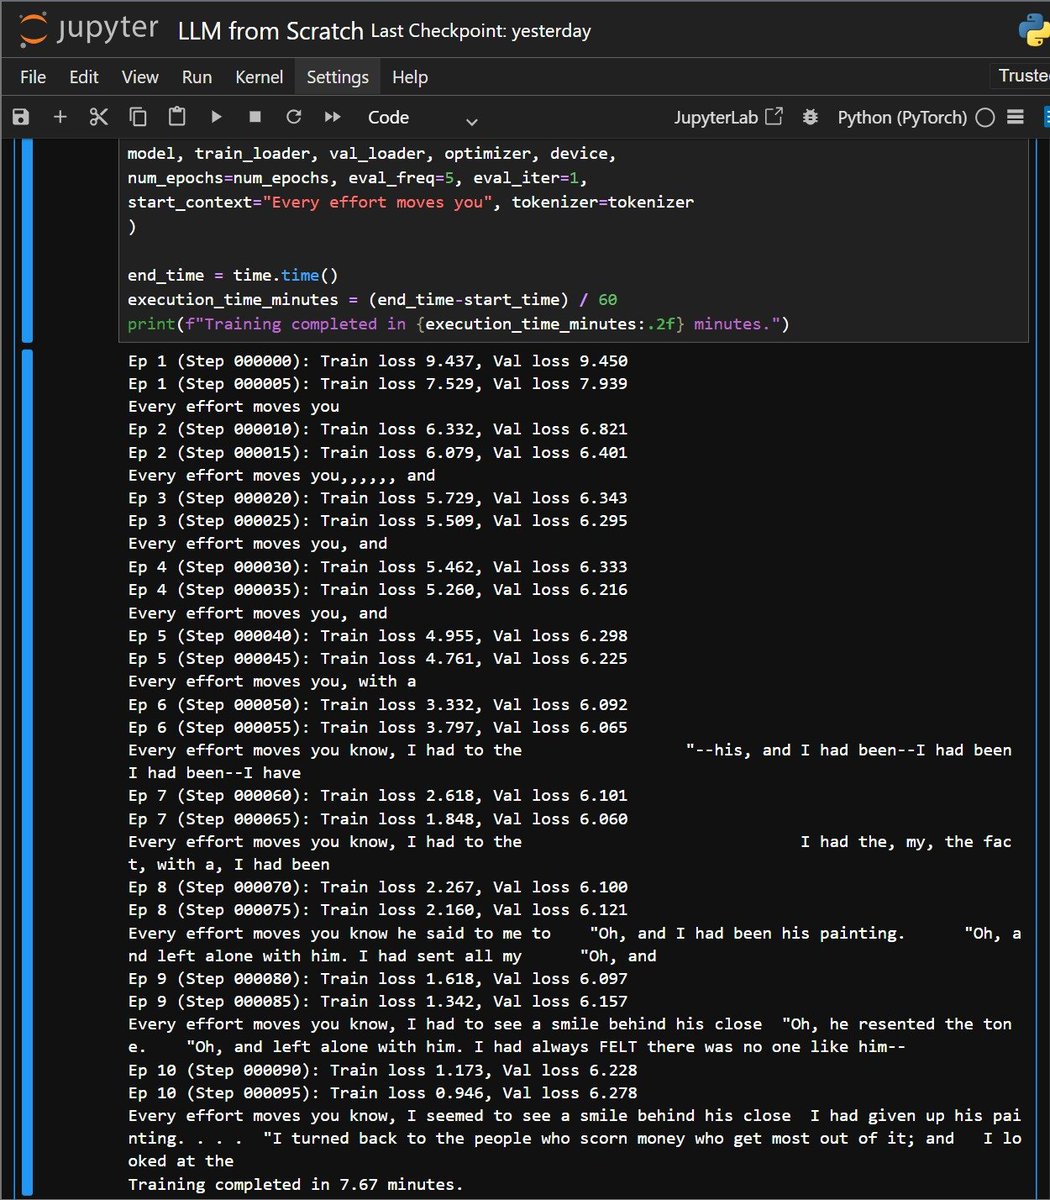
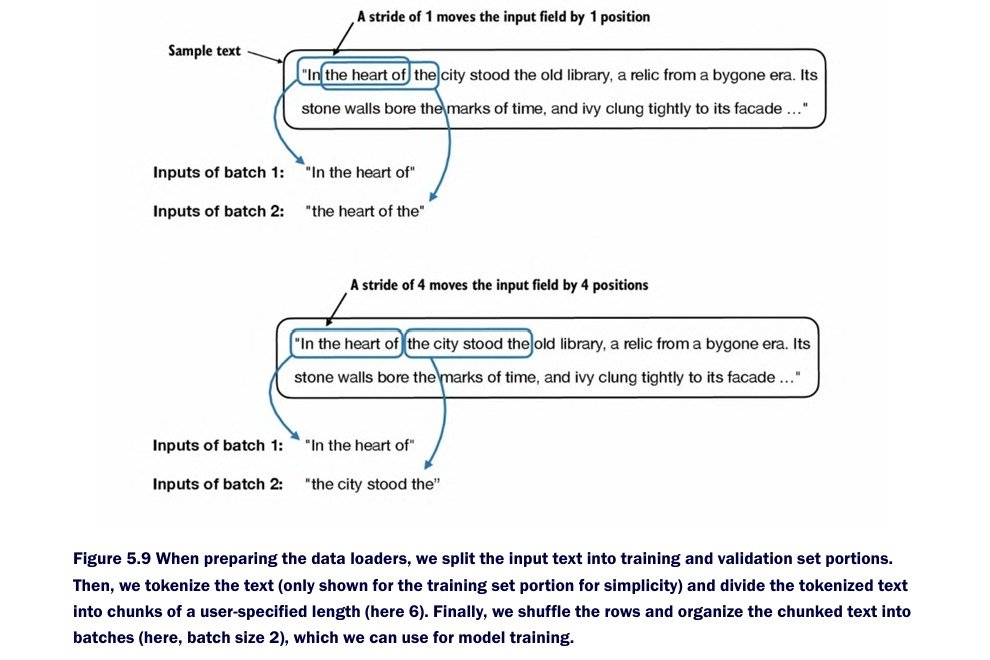
Day 124 —> Becoming an AI Engineer
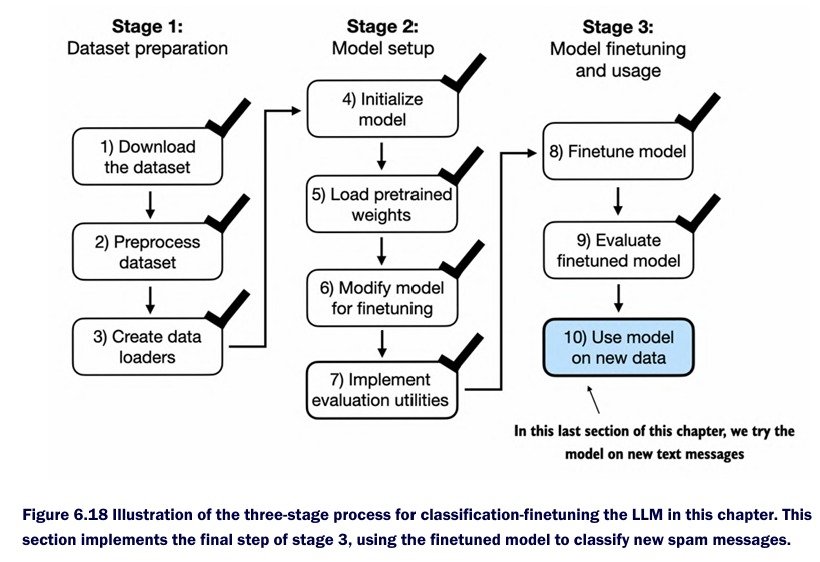
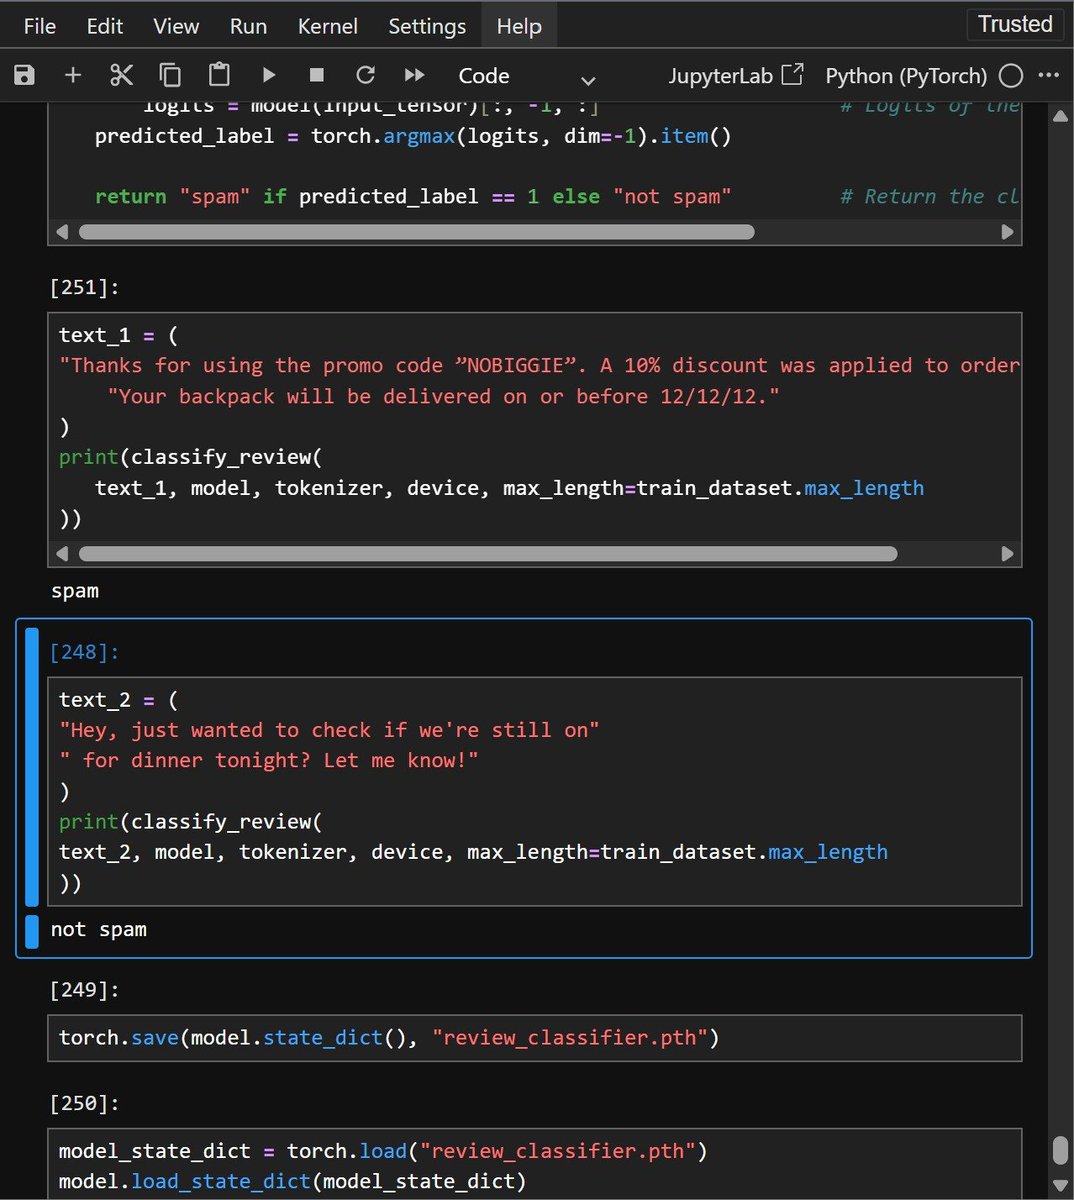
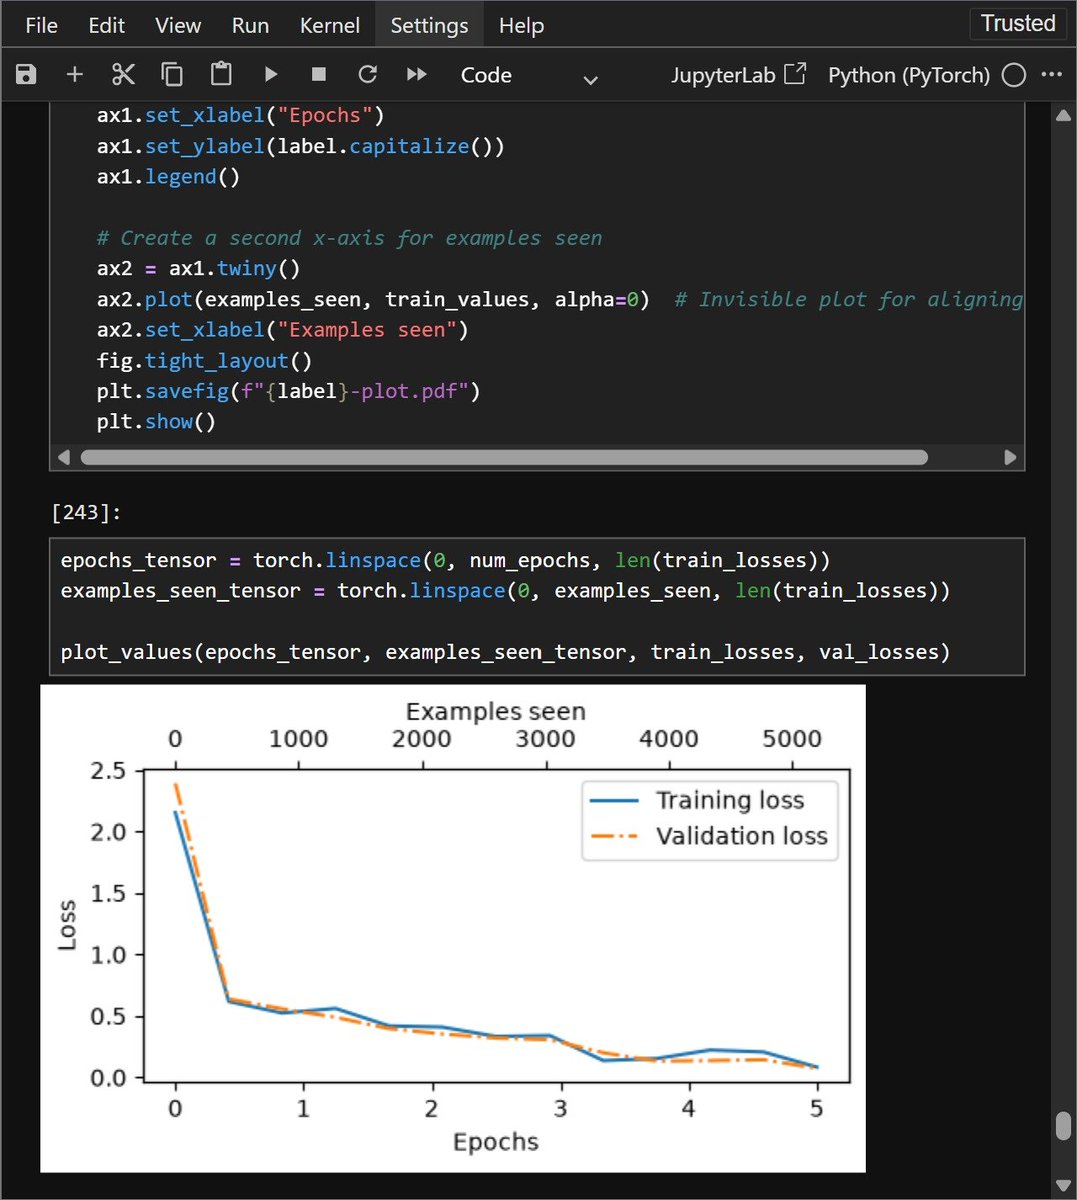
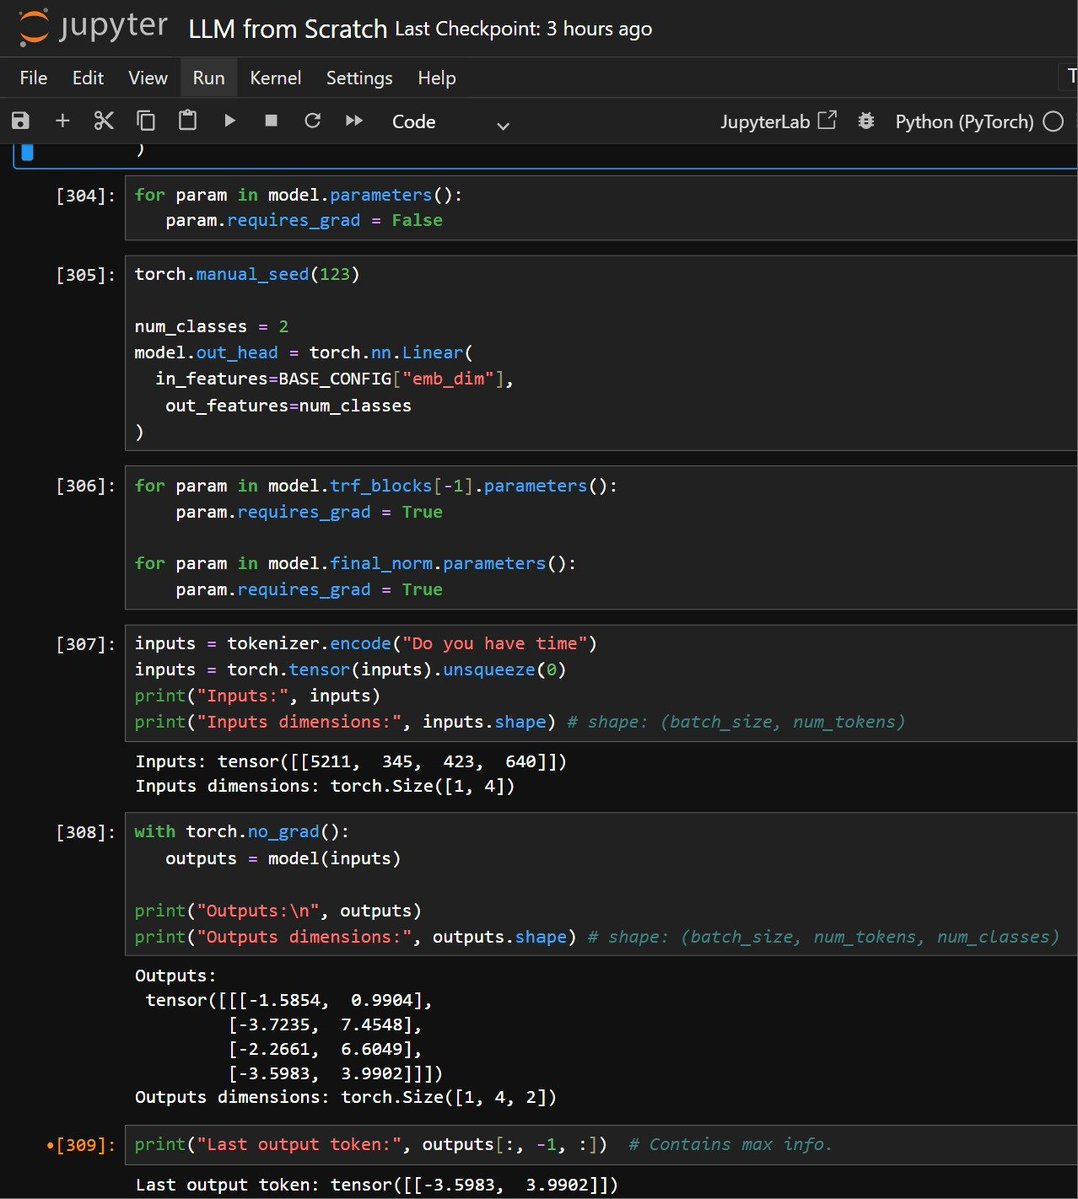
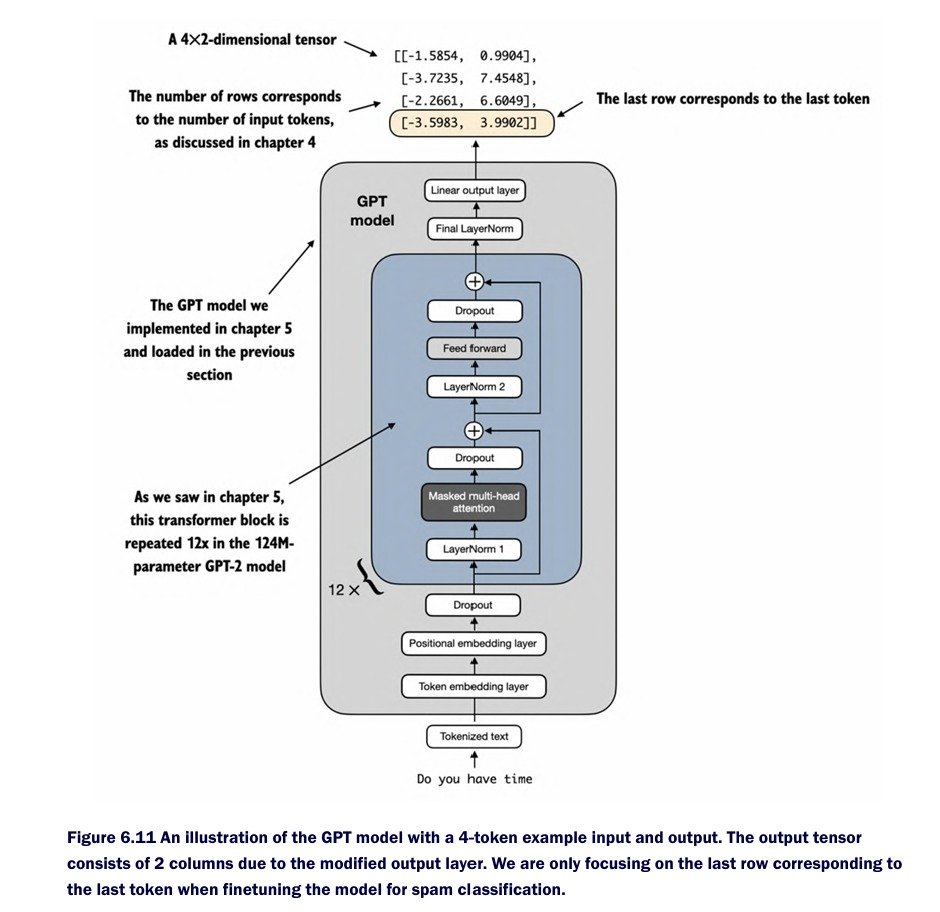
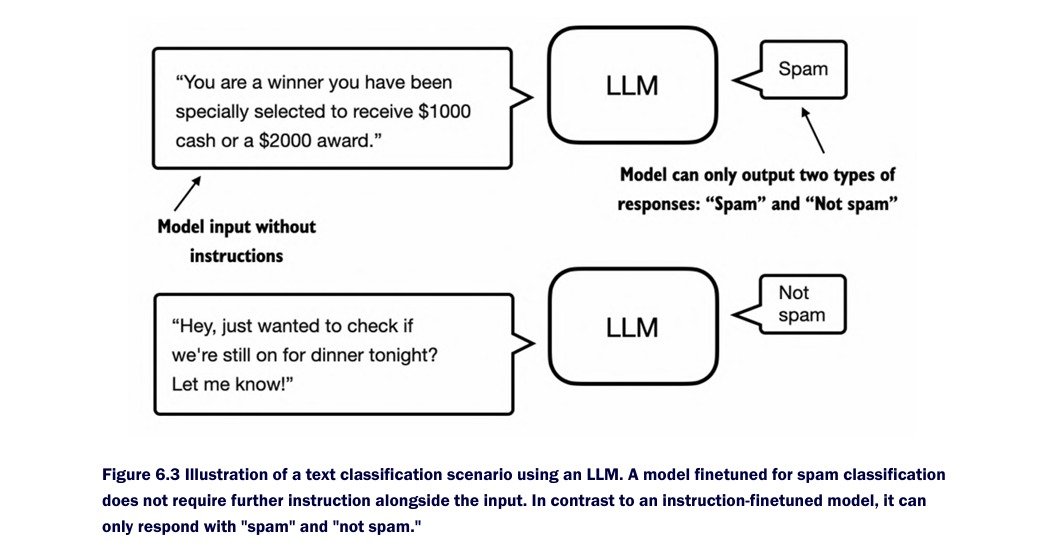
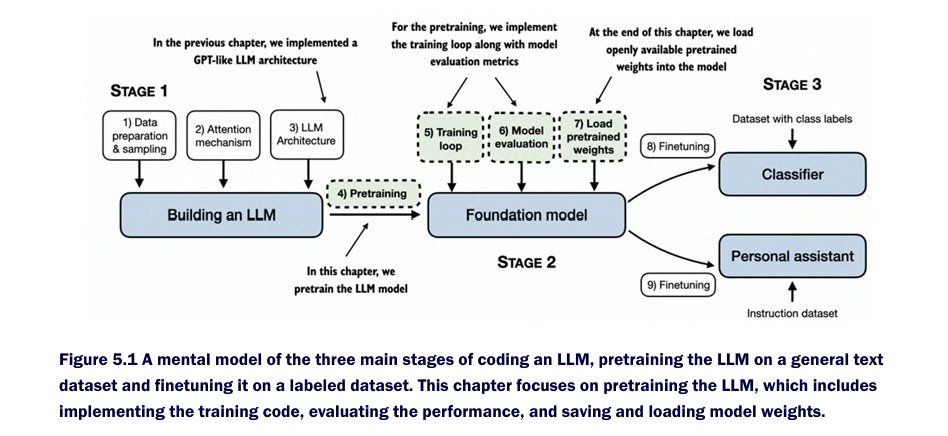
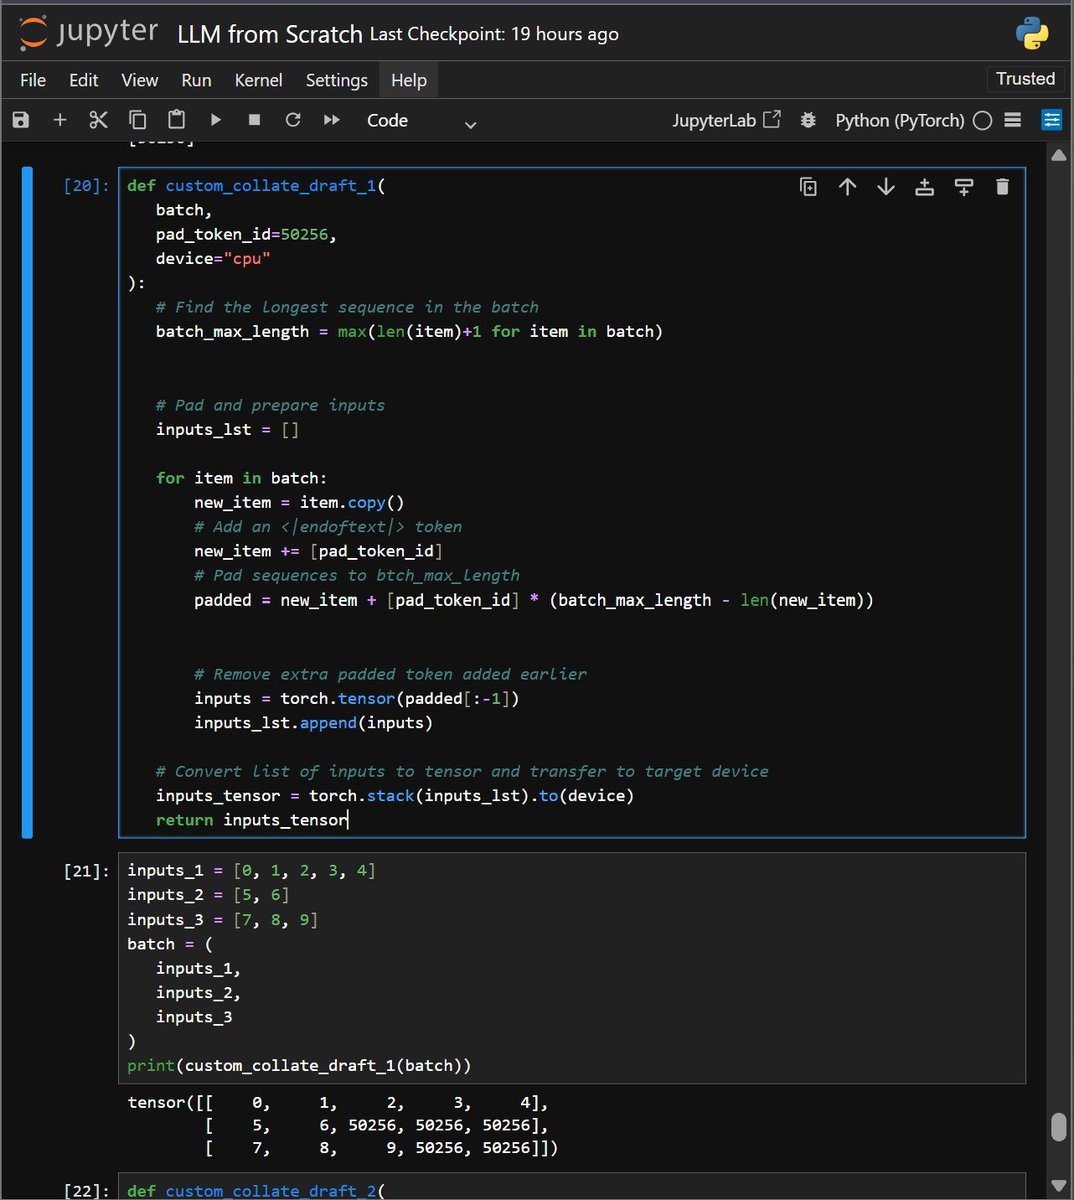
Built spam v/s Non spam :
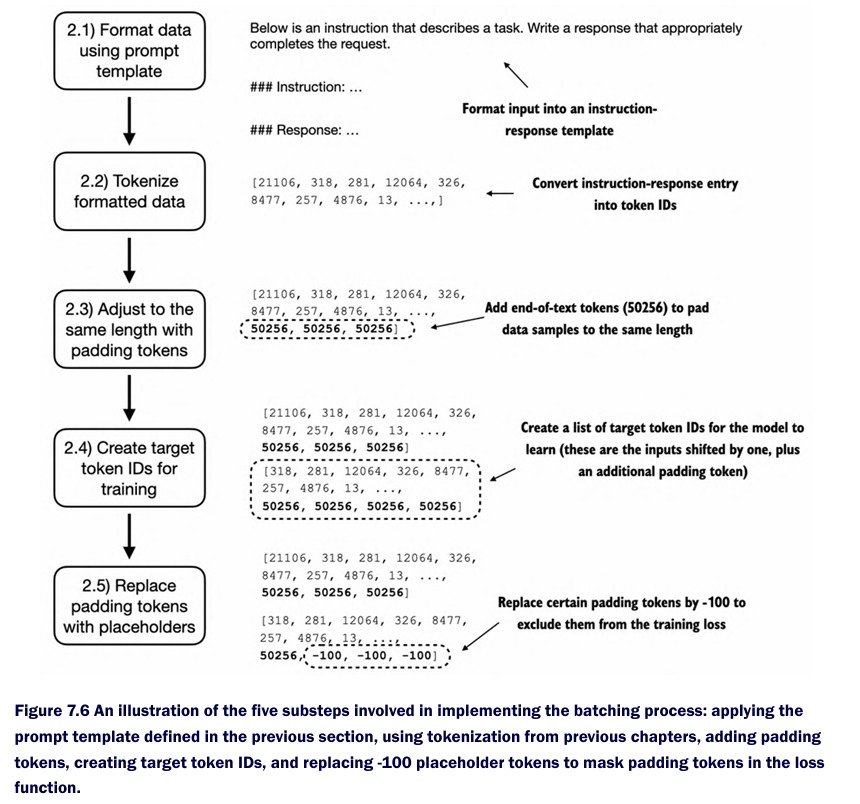
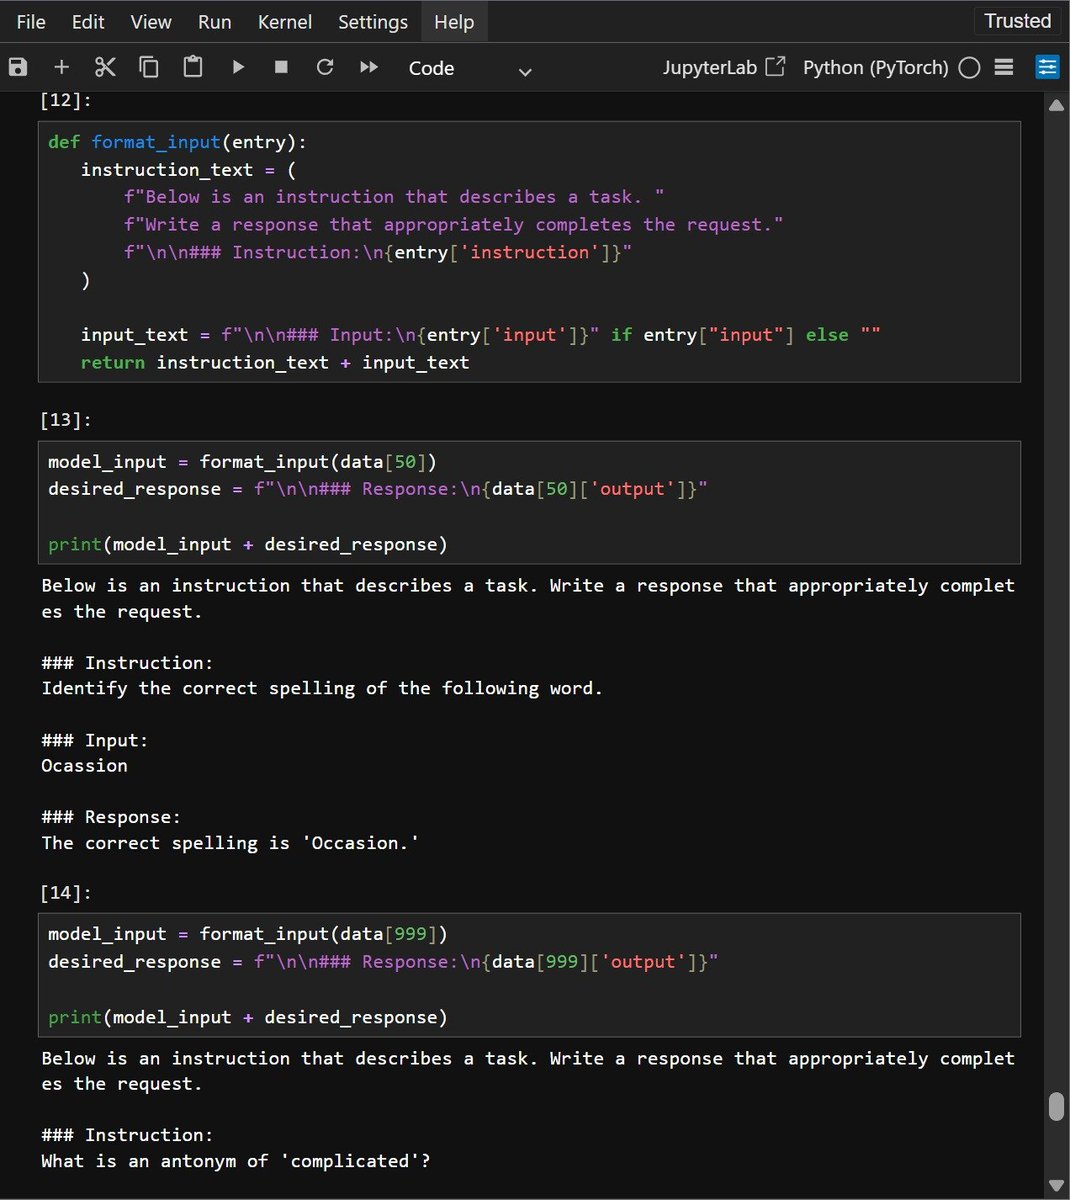
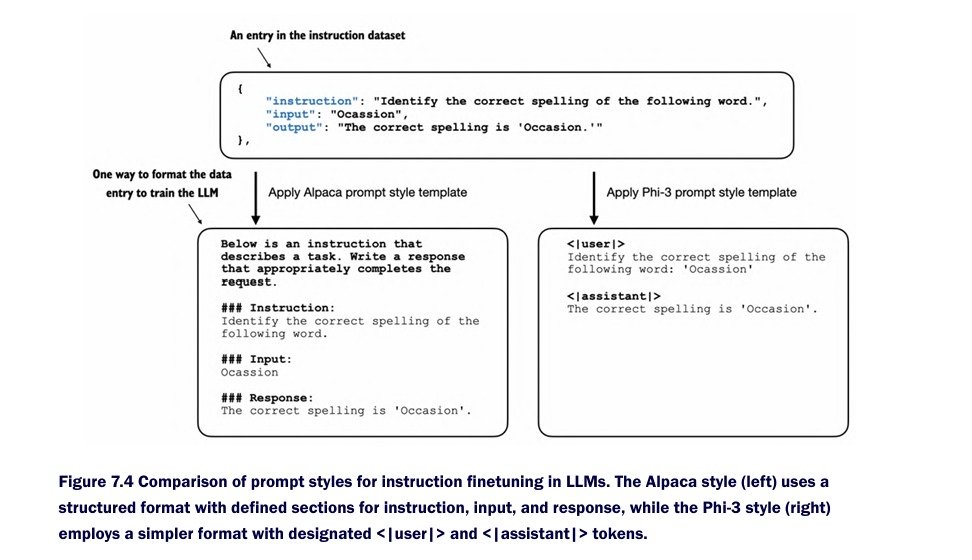
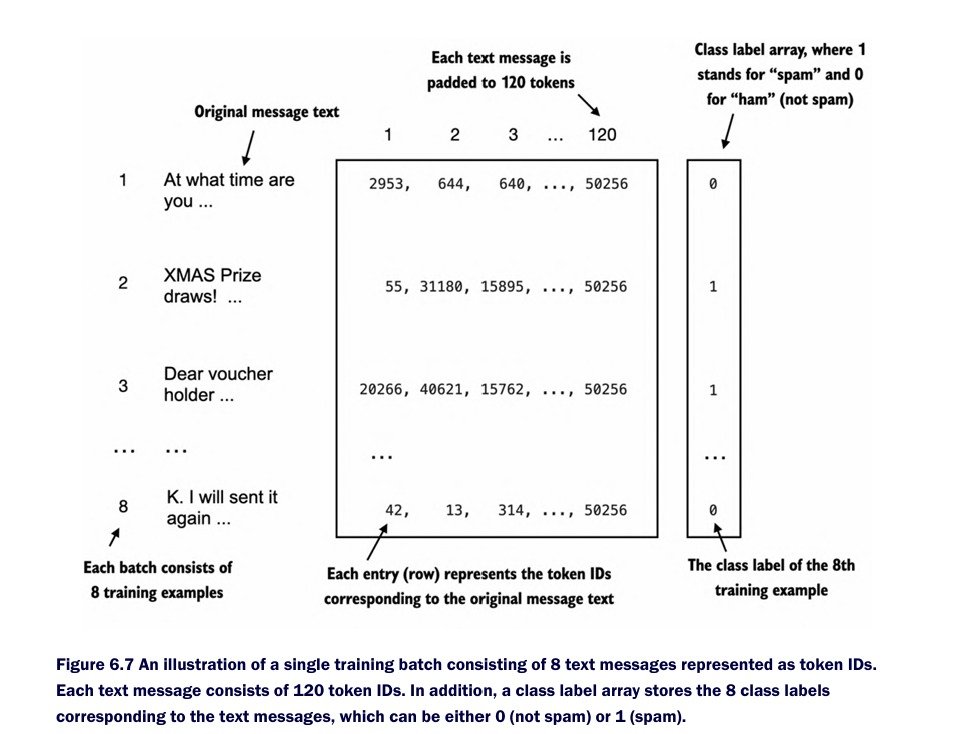
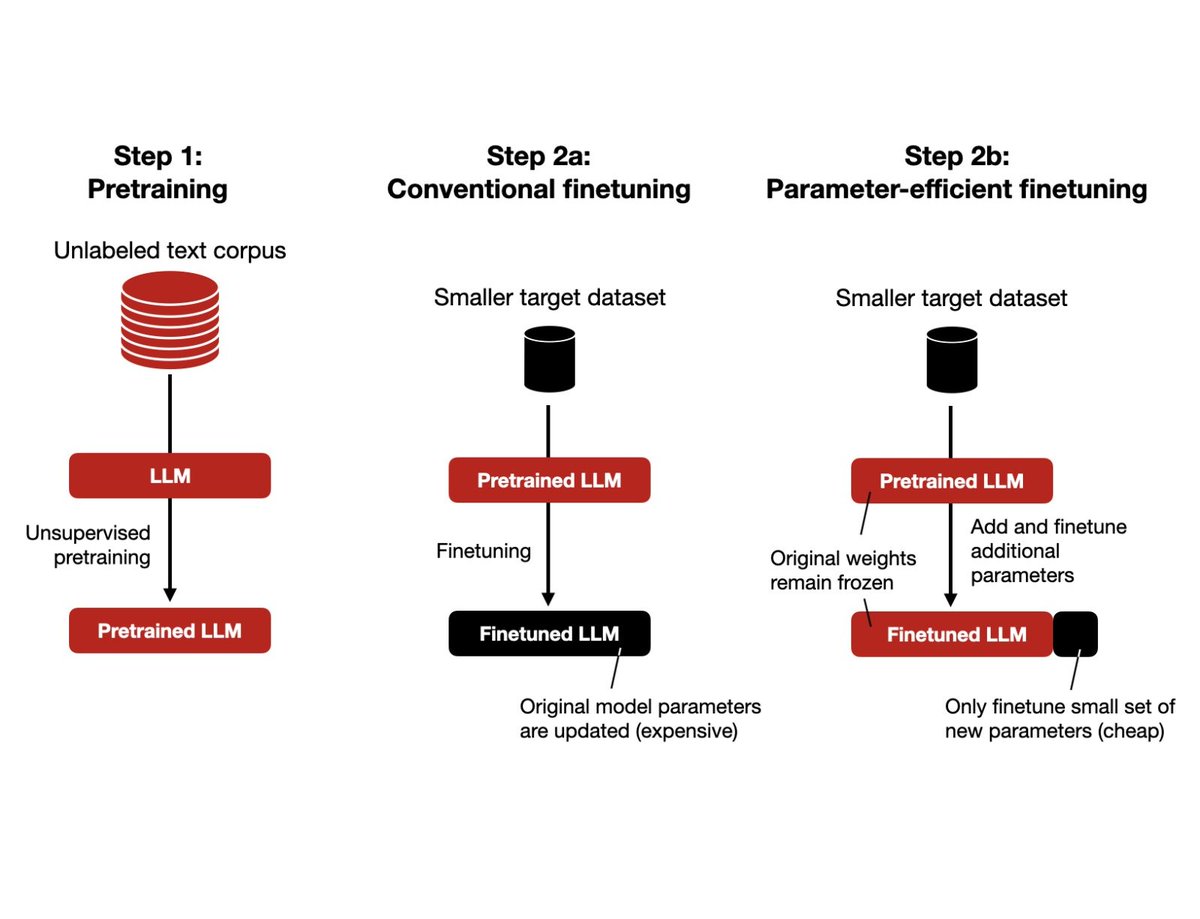
Data → Preprocess → Batch → Load Weights → Classification Head → Fine-tune → Evaluate
Insight: Fine-tuning reuses learned representations while optimizing the model’s decision boundary for a new task.
#LLM#AI
@shivam74689 Great!! Proud of you buddy, not for just who you are, but how you are, always inspiring, always looking up for those dreams, which even everyone dares to imagine, maybe you failed to build, but you never failed to inspire everyone around you, this is just the beginning 🤝
Day 123 —> Becoming an AI Engineer
Building Spam vs Non-Spam classifier
Done with: Preprocessing → DataLoader → Pretrained Weights → Classification Head
Insight: A pretrained LLM can be repurposed for classification by adapting its output space to the target task
#LLM#DL
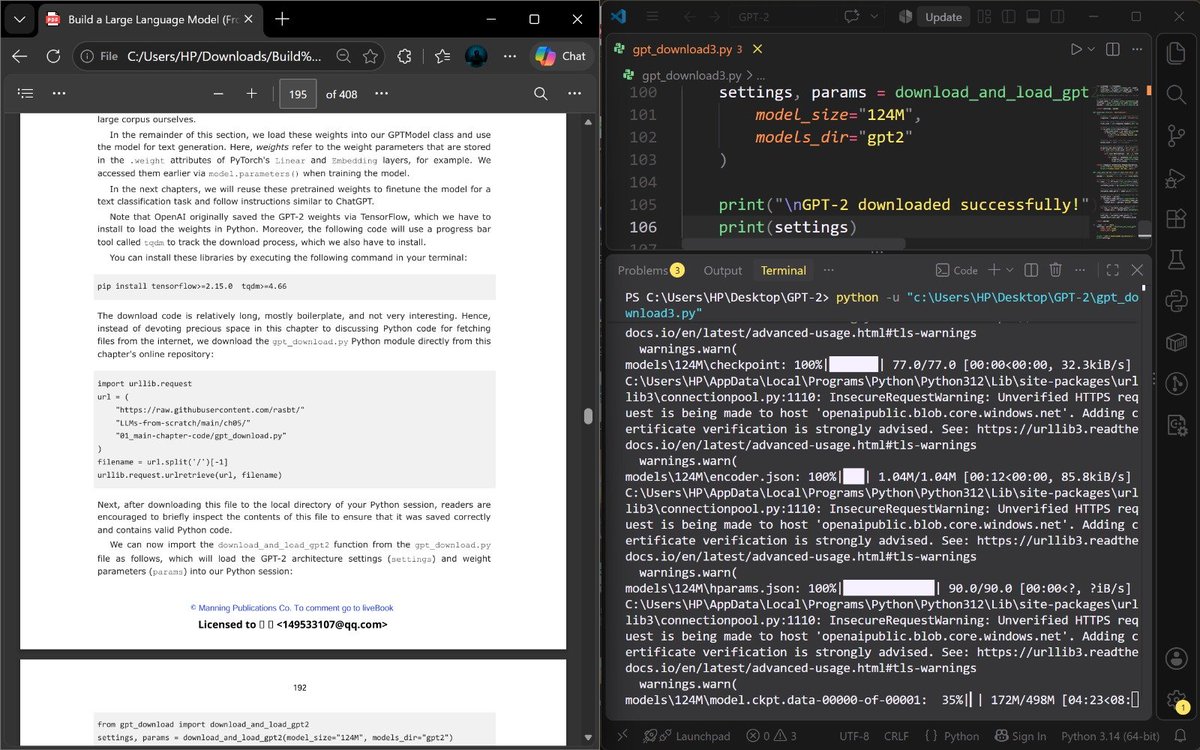
Day 121 —> Becoming an AI Engineer
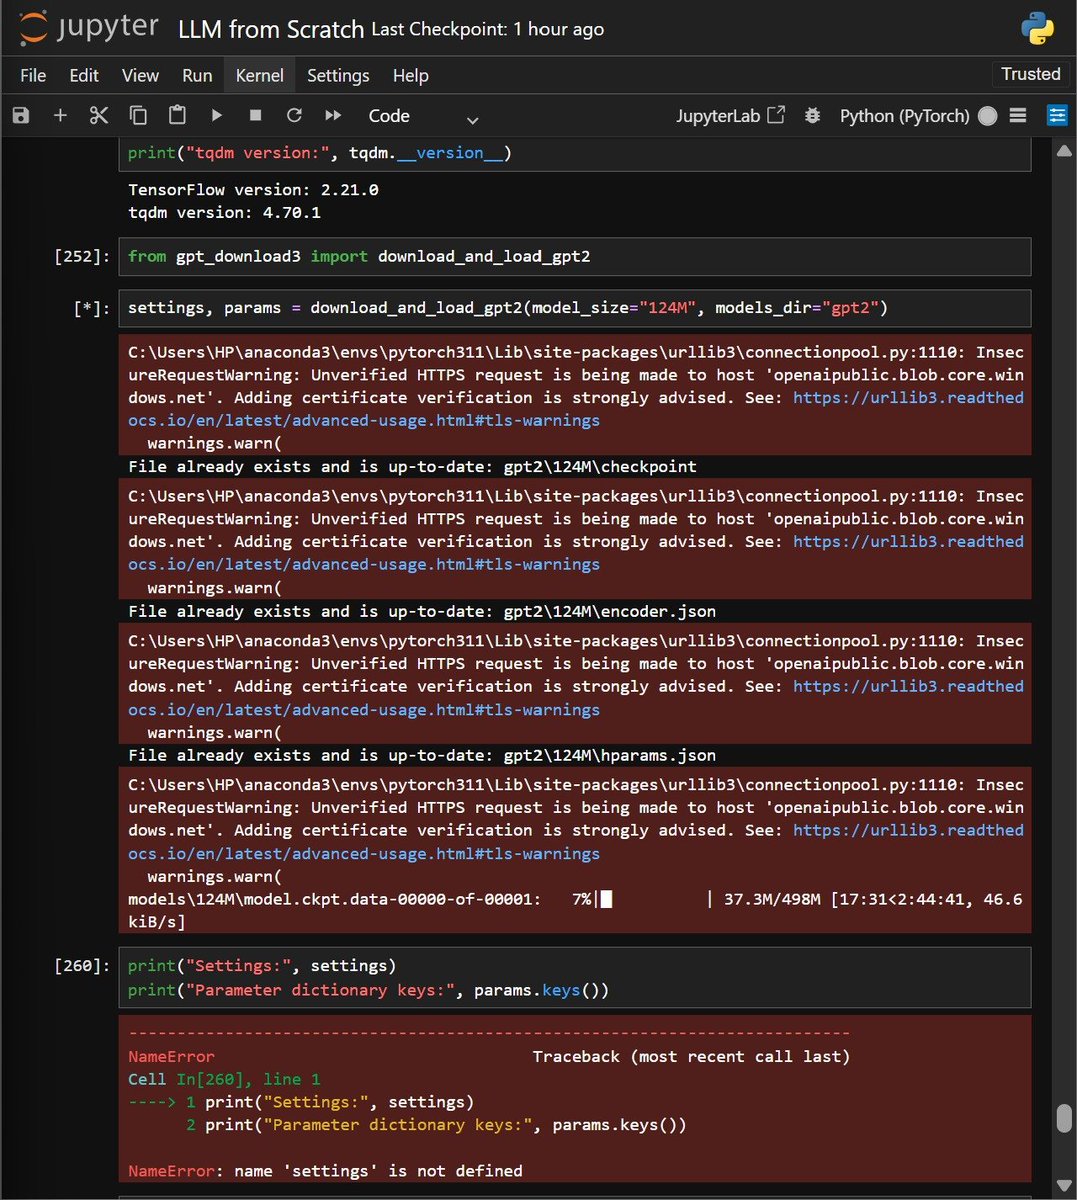
Tried loading pre-trained GPT-2 (124M) weights locally.
~500 MB download at ~55 KiB/s… patience became part of the training loop
Insight: Working with LLMs isn’t just about arch. —data, weights, storage & compute are engineering problems too
Day 120 —> Becoming an AI Engineer
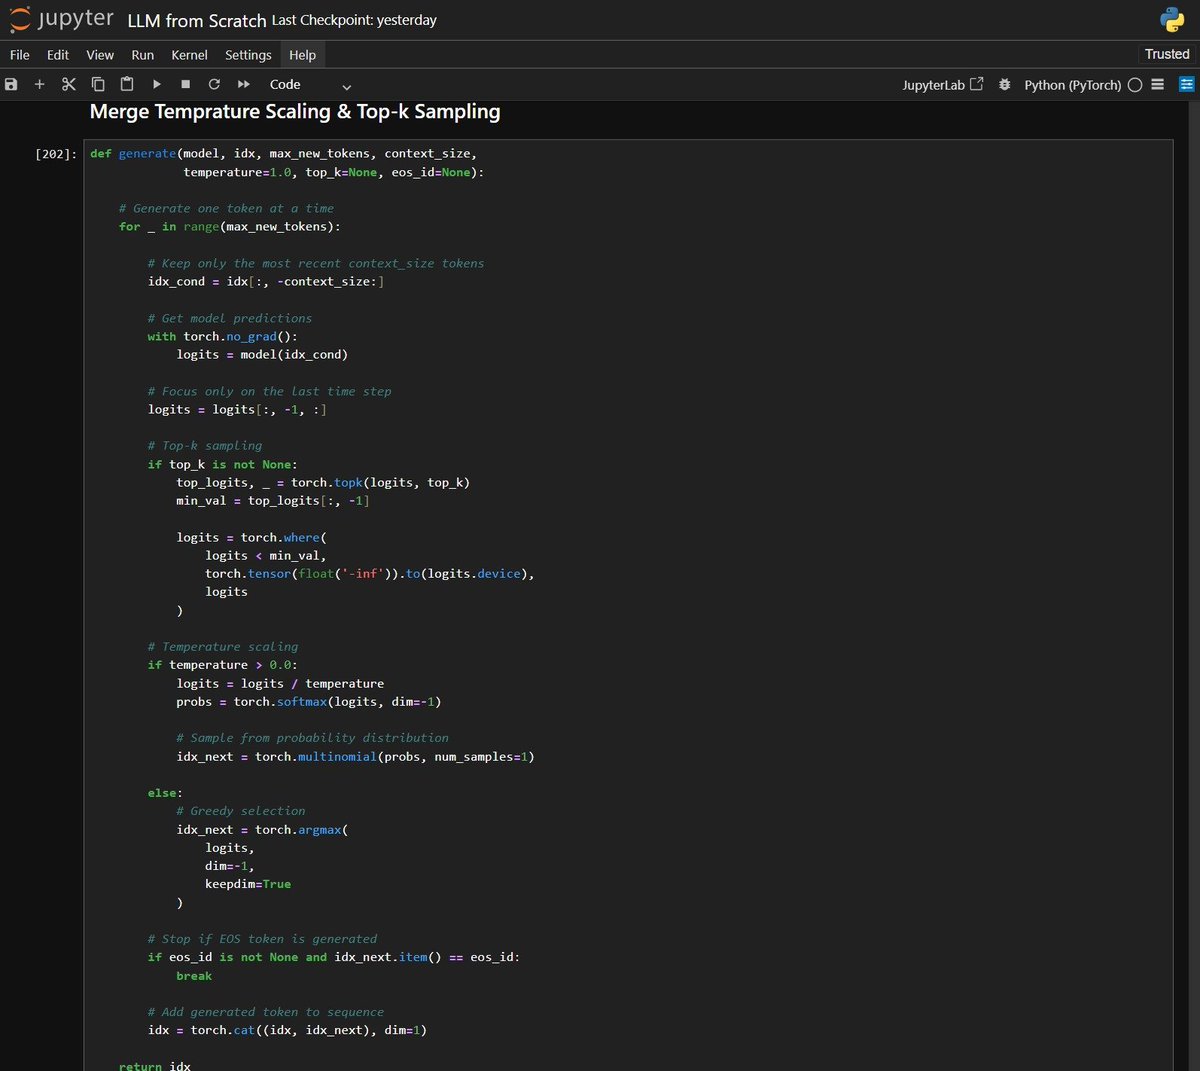
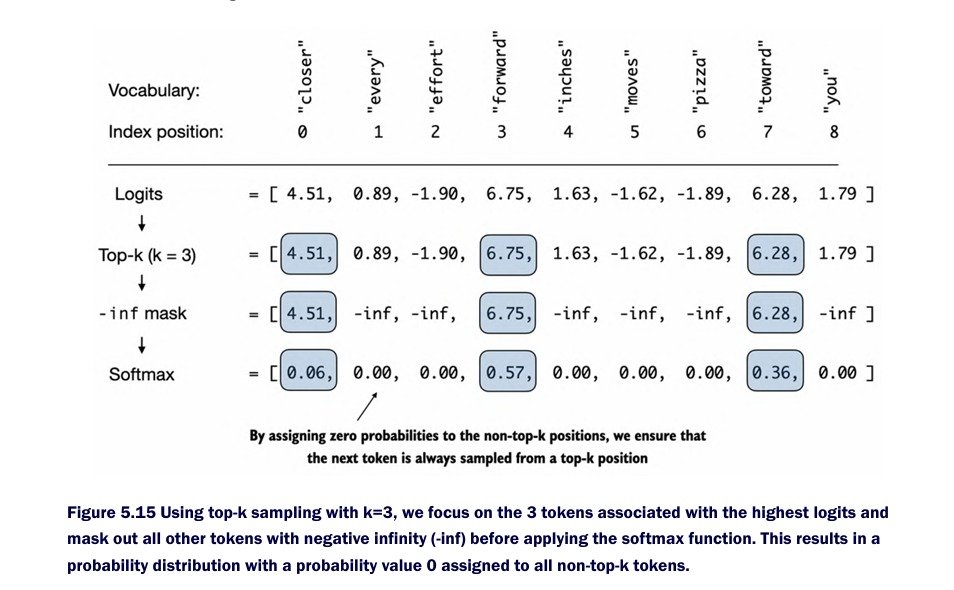
Temp. Scaling & Top-K Sampling for LLM generation.
Temperature → controls randomness
Top-K → limits candidate tokens
Insight: Decoding doesn’t change what the model knows—it controls how that knowledge is sampled into text
#LLM#GenAI#DL
Day 119 —> Becoming an AI Engineer
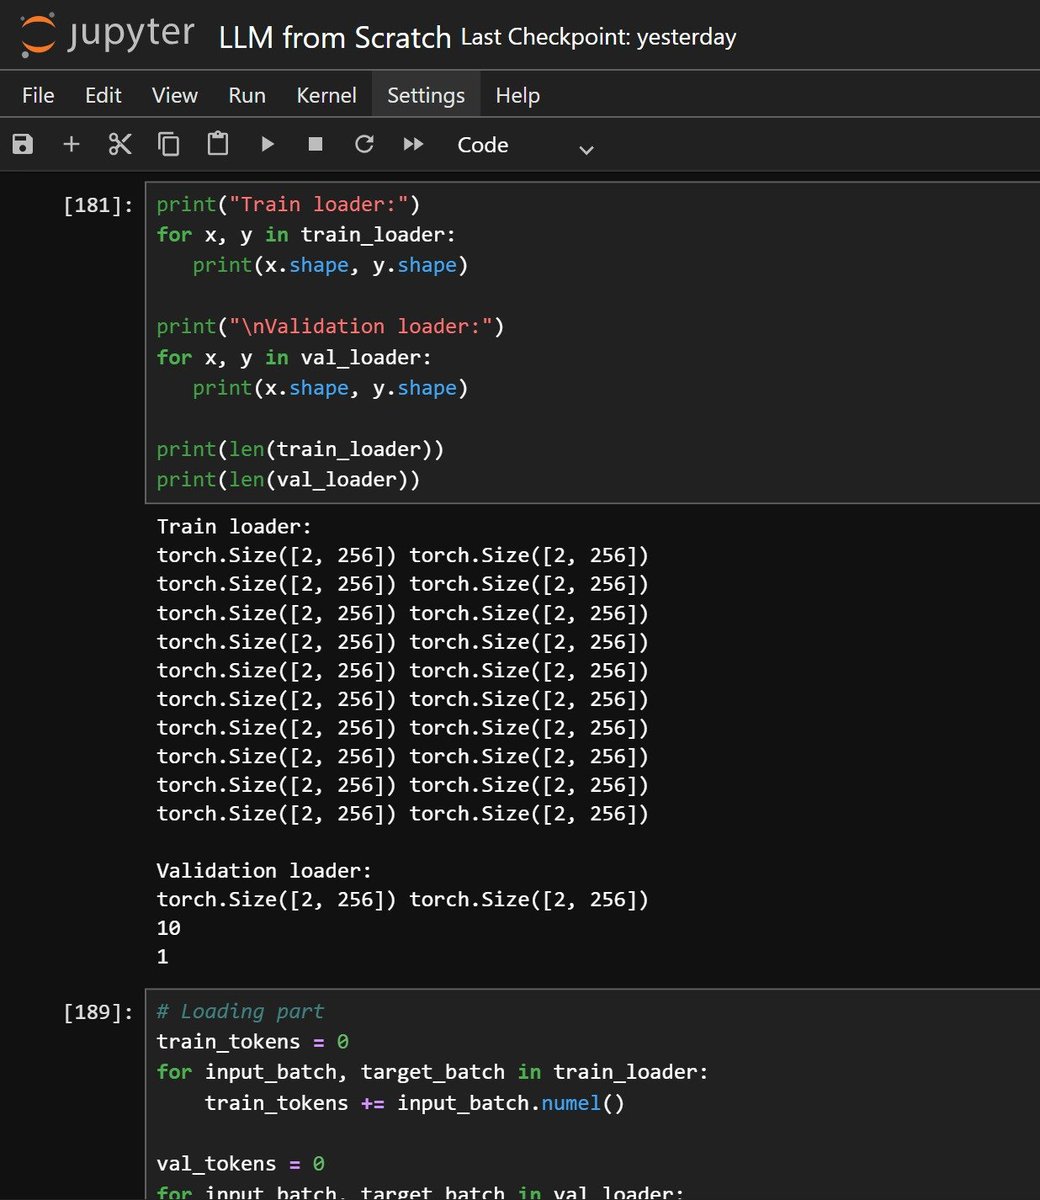
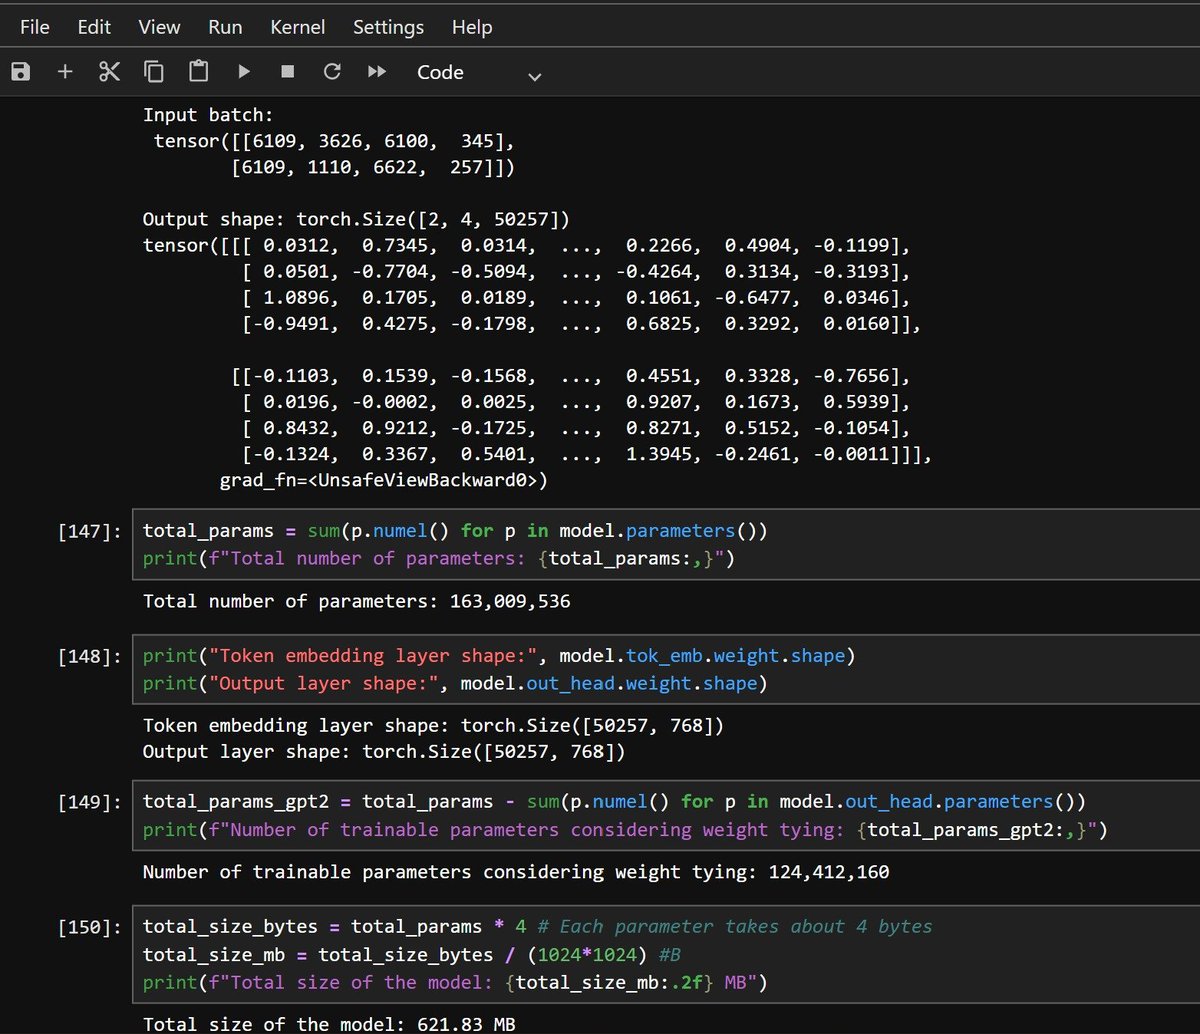
LLM from scratch, including --> full forward + loss + backprop pipeline.
GPT-2’s arch~164M parameters across embeddings, attention, FFNs & Transformer blocks.
Insight: Scale comes from simple operations × learned parameters.
#DL#LLM#GPT2
Day 118 —> Becoming an AI Engineer
My first small LLM . {Excluding Backprop. part}
Input → GPT → Generated Loss
Train Loss: 10.97
Val Loss: 10.98
Insight: Building an LLM makes the theory tangible — every token prediction is a learned probability distribution.
#LLM#GPT
Day 117 —> Becoming an AI Engineer
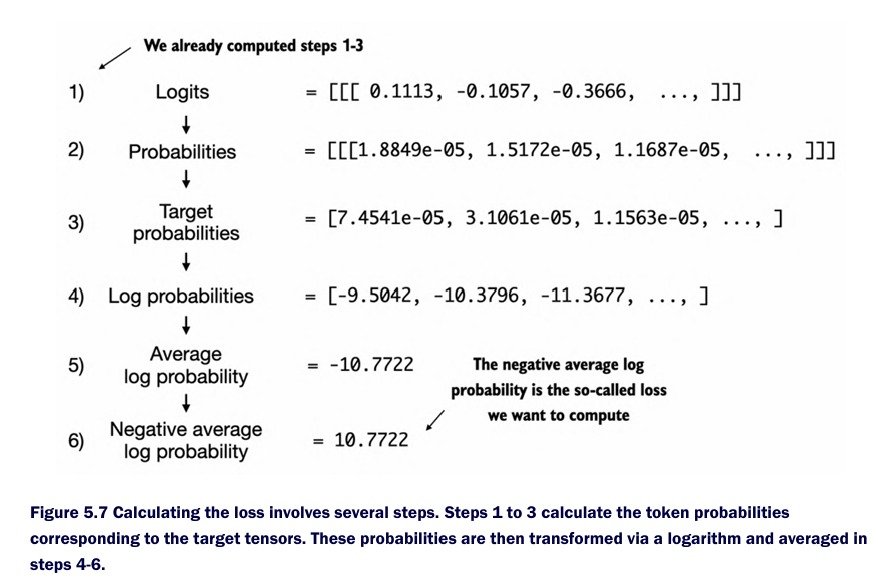
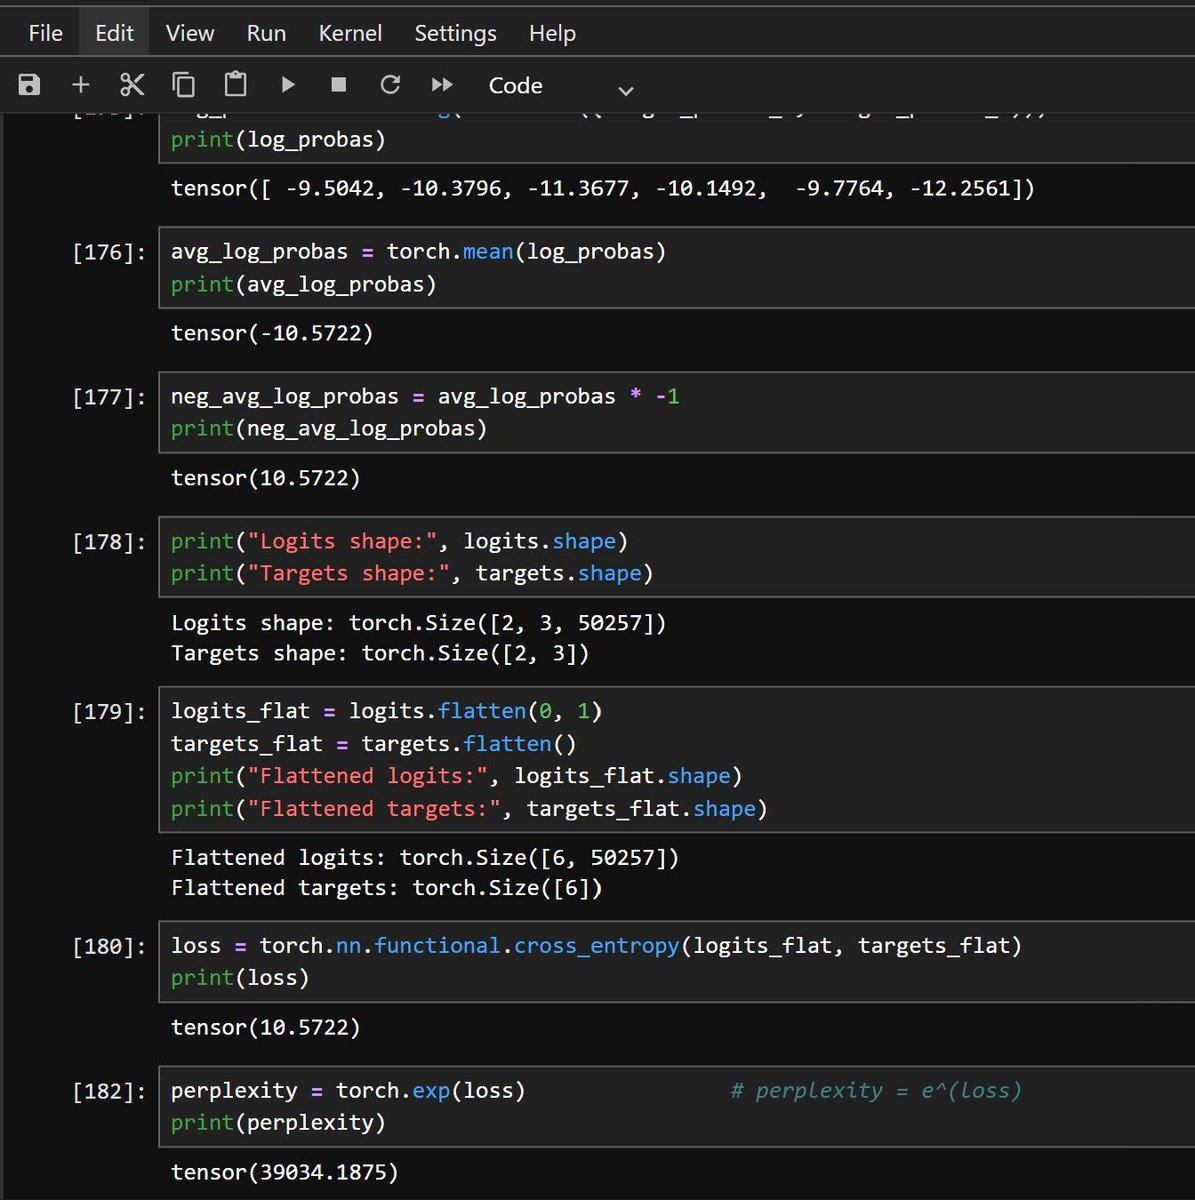
Losses :
BCE → measures how well predicted probabilities match the target.
Perplexity → measures how uncertain the model is when predicting the next token.
Insight: Lower perplexity = better next-token predictions.
#LLM#GPT#DeepLearning
Day 116 —> Becoming an AI Engineer
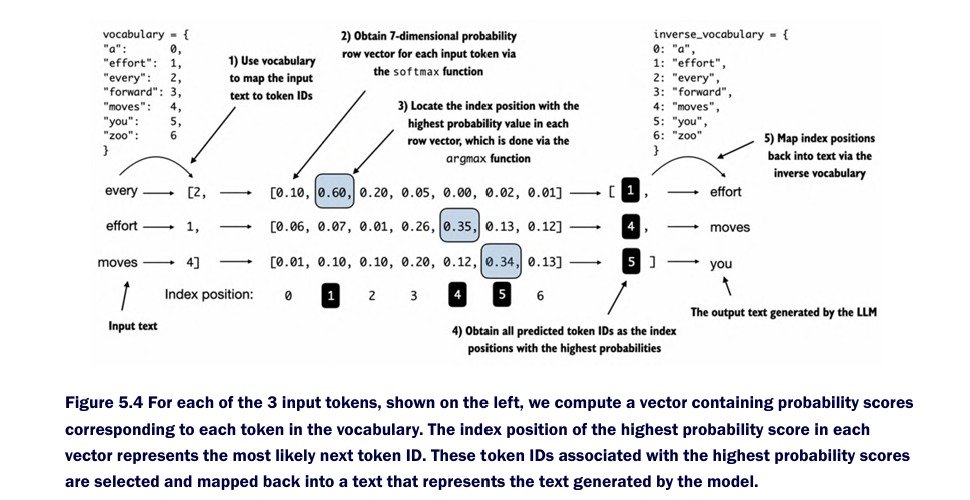
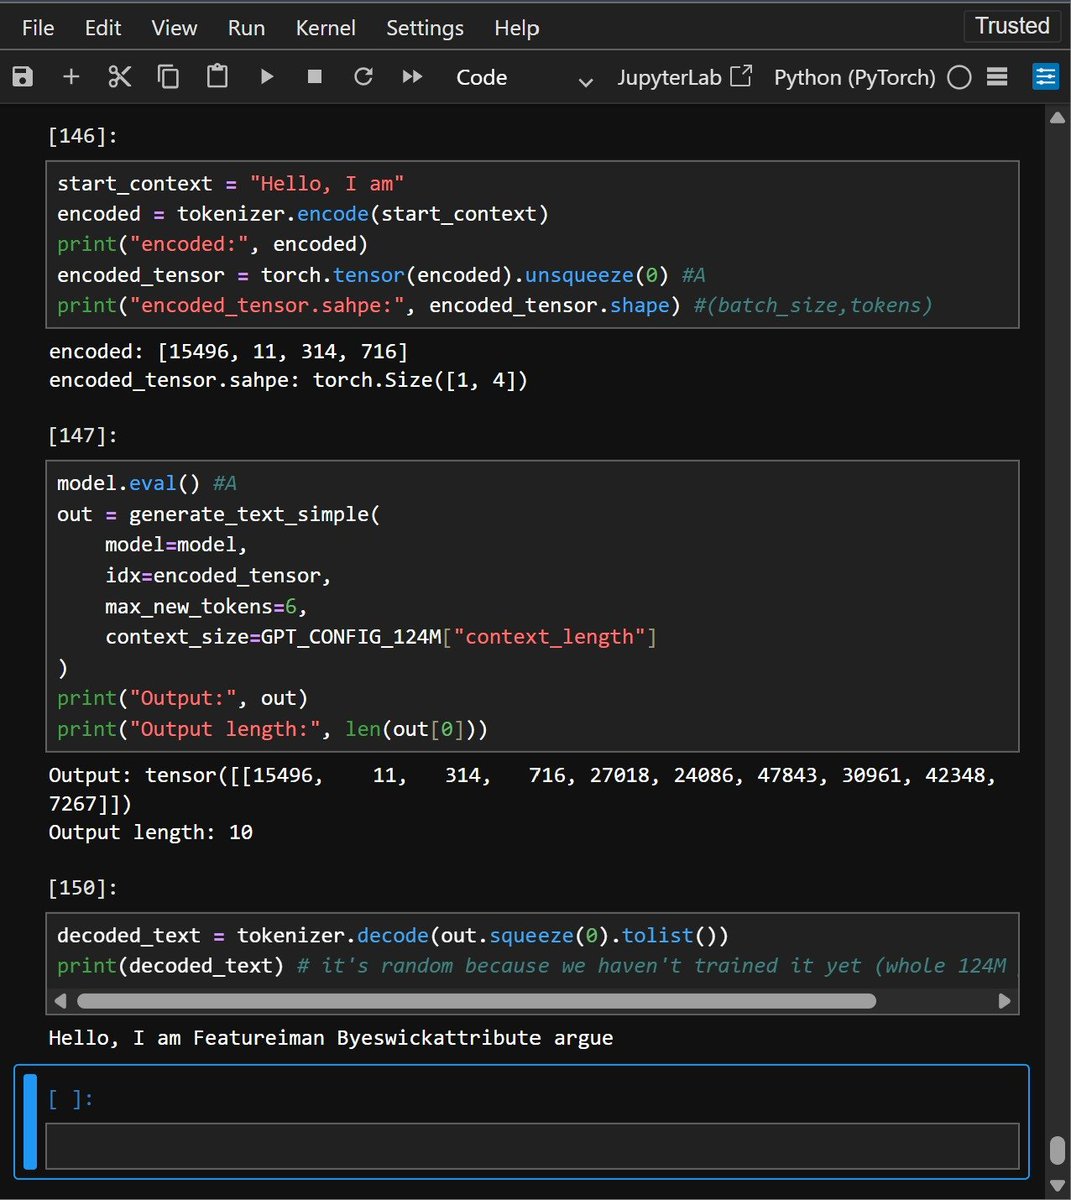
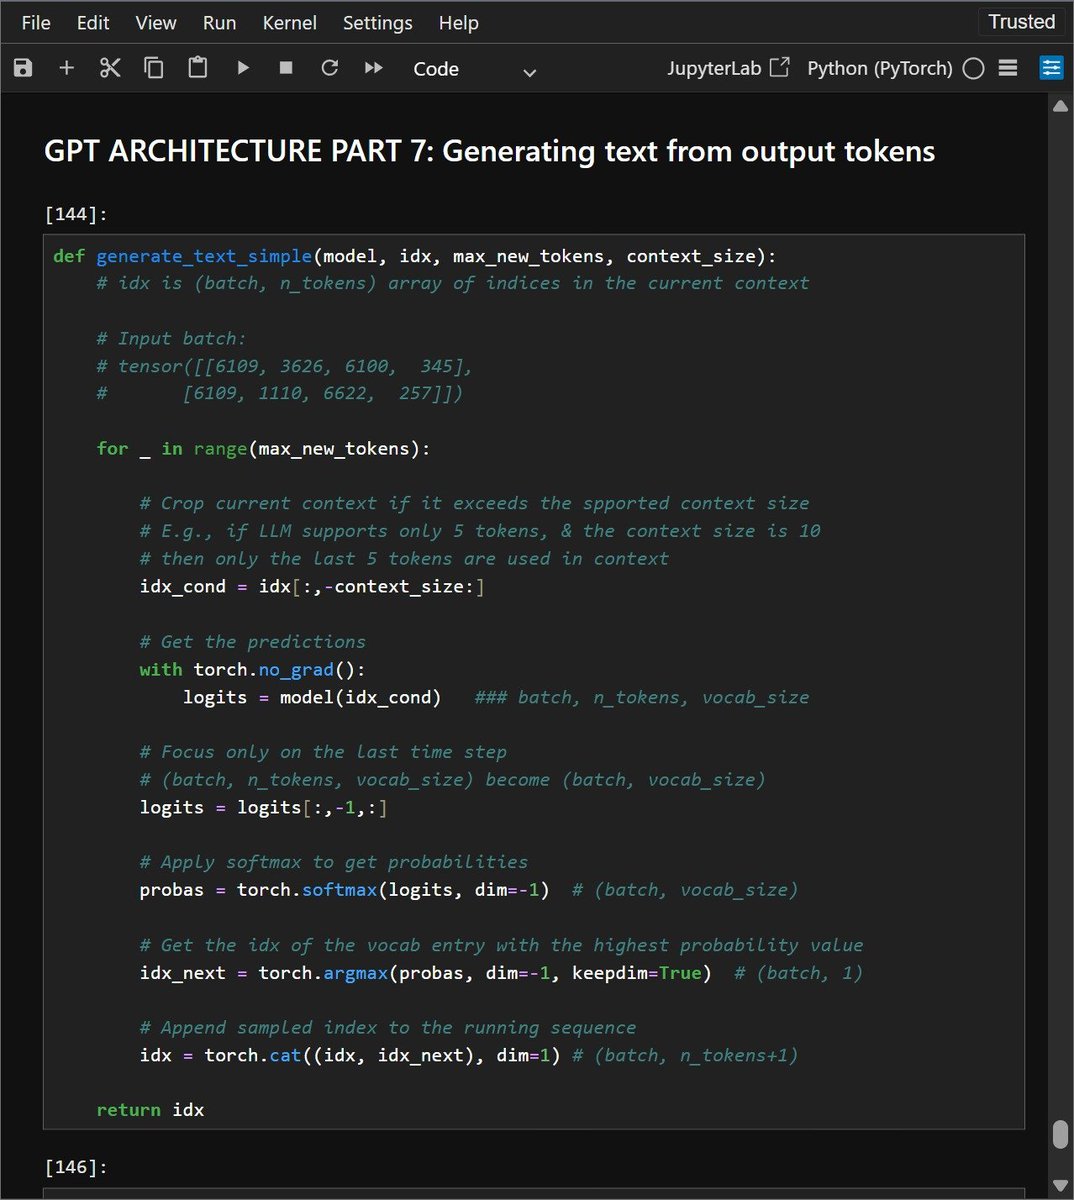
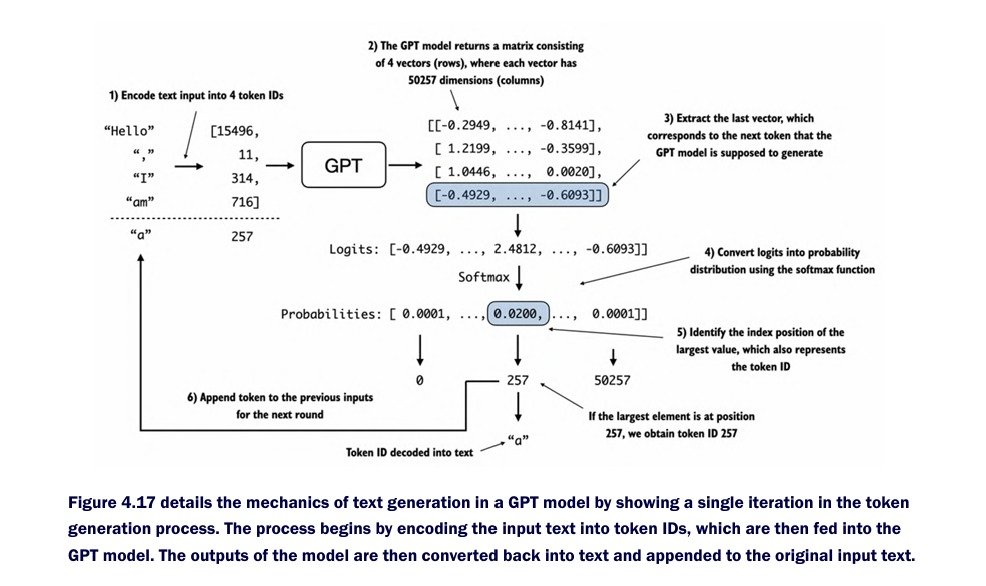
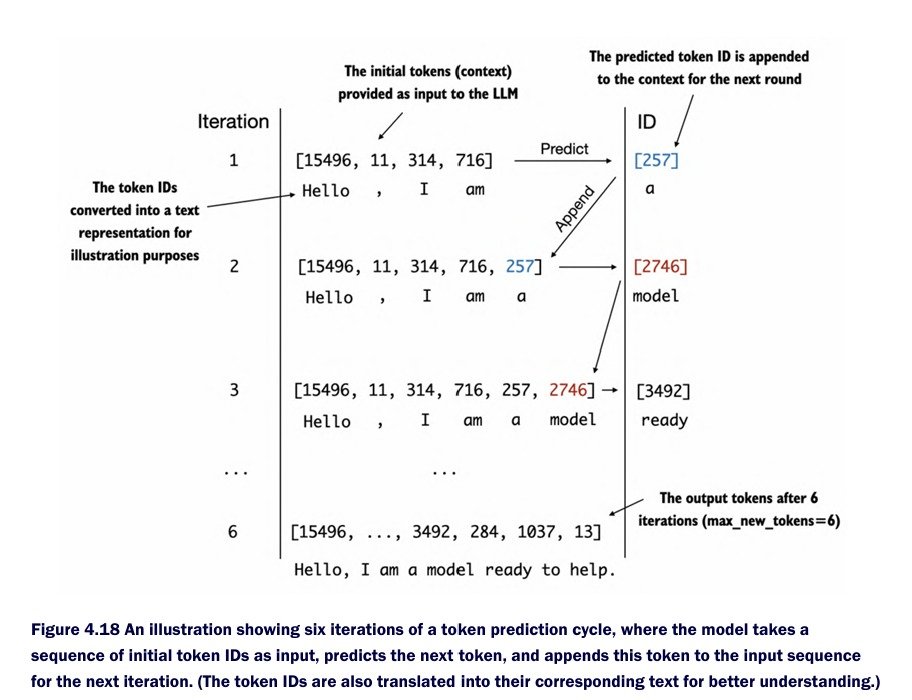
How GPT generates new text:
Tokens → GPT → Logits → Softmax → Next Token → Repeat
Insight: GPT doesn’t generate a sentence at once—it builds it token by token, turning probability into text.
#LLM#GPT#GenAI
Day 115 —> Becoming an AI Engineer
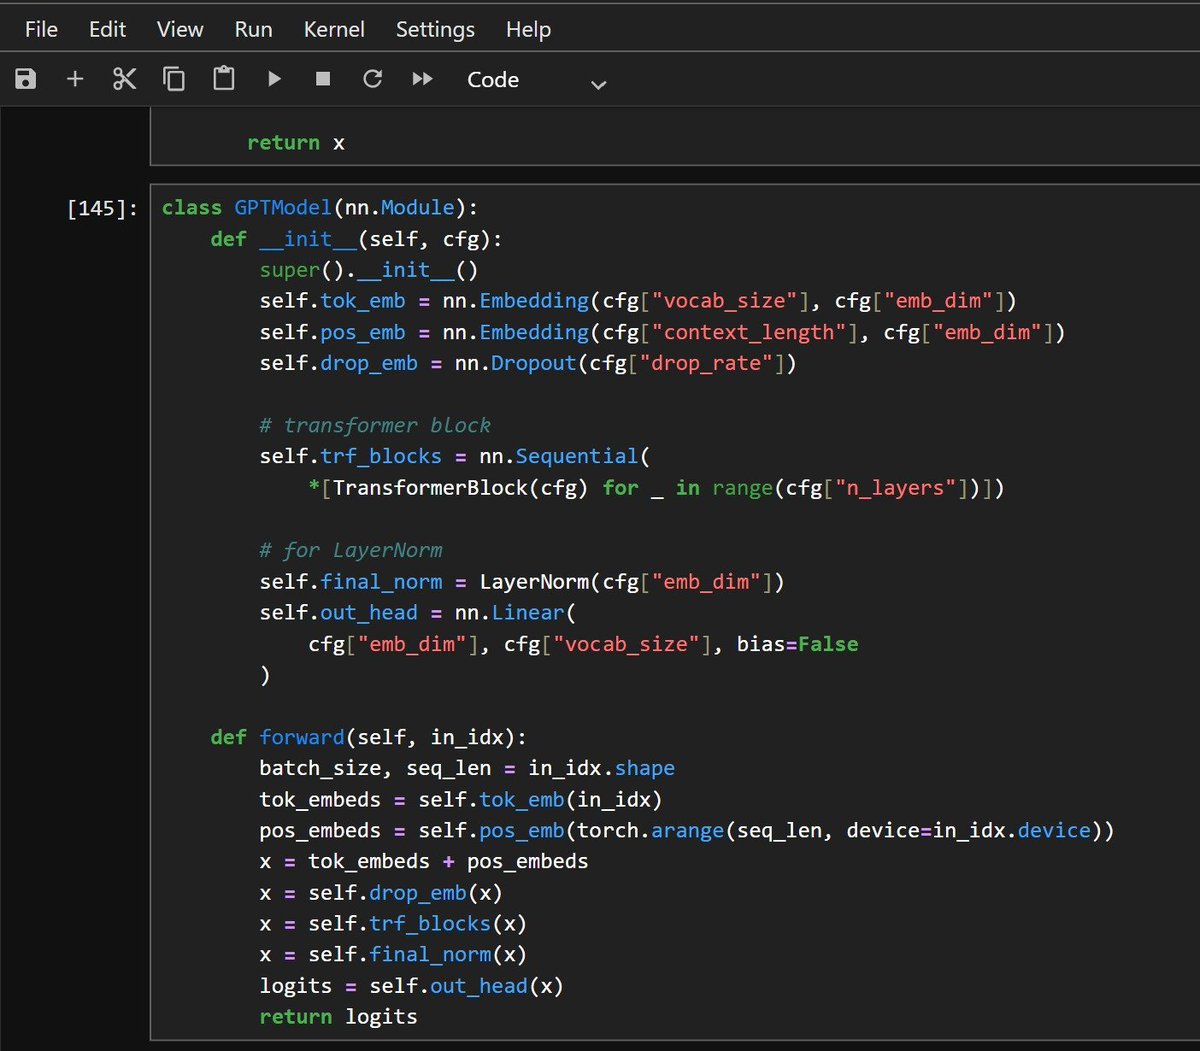
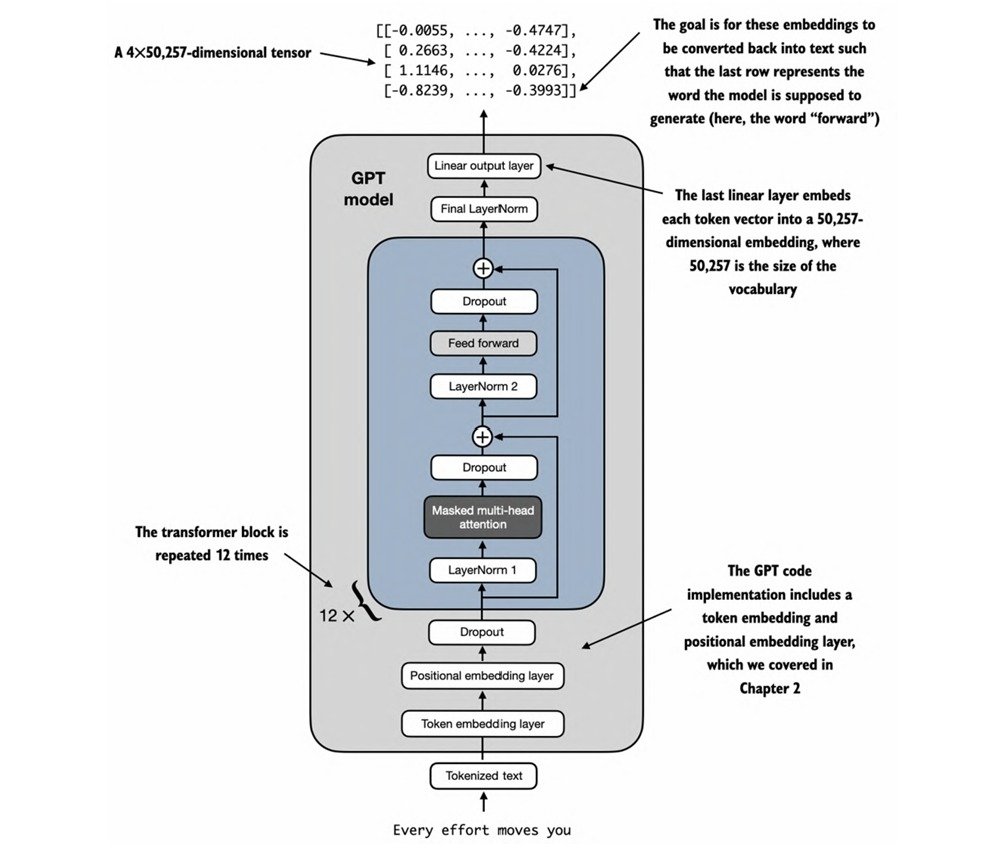
Implemented the GPT architecture from scratch.
124.4M trainable params | ~622 MB
Shocked how much engineering sits behind a seemingly simple architecture.
Insights : Simple blocks + scale → powerful capabilities.
#LLM#GPT#DL#NLP