We've come up with a completely unsupervised human-in-the-loop RL algorithm for translating user commands into robot/computer actions. Below: an interface that maps hand gesture commands to Lunar Lander thruster actions, learned from scratch.
https://t.co/JRYBSkkosI
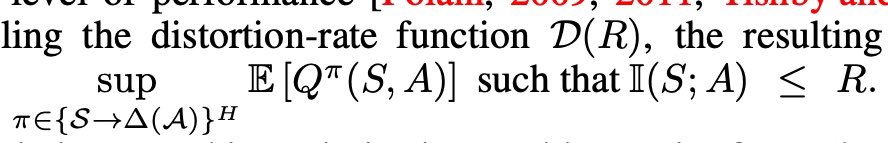
https://t.co/rd8aHqFSpi: you can model bounded-rational human behavior as the result of maximizing rewards + an information bottleneck between the state and action in the human policy
LIMIT: Learning Interfaces to Maximize Information Transfer
https://t.co/qtJtt47ZJR
maximizes conditional mutual information between user action and env state given observation produced by the interface
https://t.co/wnRXCKsAZm
appendix F: a human can learn to replicate adversarial attacks on a Go-playing agent. can we come up with a method that automatically discovers superhuman policies and teaches them to humans?
tinkering with a simple method for controllable text generation with LMs using multiple simultaneous prompts: compute the conditional distribution over next token independently for each prompt, aggregate distributions, then sample. https://t.co/5Bba3Q97DA
idea for improving the generality of https://t.co/P514fO680b in multi-agent RL: replace the future trajectory with a policy embedding that's trained end to end, similar to the fingerprint in PVNs (https://t.co/34cNJNVkeO)
ideas for improving policy evaluation networks (https://t.co/86WpHJLYor):
- instead of learning probing states, use sampled states
- instead of concatenating a fixed number of state-action embeddings together to form a fingerprint, mean-pool an arbitrary number of embeddings
ideas for improving policy evaluation networks (https://t.co/86WpHJLYor):
- instead of learning probing states, use sampled states
- instead of concatenating a fixed number of state-action embeddings together to form a fingerprint, mean-pool an arbitrary number of embeddings
- improve the fingerprint representation by using it to reconstruct actions, in addition to predicting returns
- regularize policy optimization by minimizing reconstruction error, in addition to maximizing predicted return
i recently started hacking on an RL method that combines meta-learning and upside-down RL (https://t.co/qcs7CurLPp), then found this paper that explores a similar idea https://t.co/f3hHgezJPH
i died 1000s of times and can't imagine any way around it, but there are gamers out there who (after years of planning and practice) have beaten all 6 souls-like games back to back in marathon sessions without getting hit a single time! https://t.co/qza8CGDpwE
recently finished dark souls remastered and elden ring. these games are fun (dsr is a masterpiece) because they reward you for exploring the state space *and the state transition dynamics* https://t.co/FV3buYimRE
idea for automatically designing maximally-fun games: tune the state space, action space, dynamics, extrinsic reward, etc. of an MDP such that, when you do RL on the *extrinsic* rewards, the agent maximizes an *intrinsic* reward like compression progress (https://t.co/OHpZdR9ZVR)
more fun from dynamics learning: dsr doesn't have many checkpoints and mostly doesn't let you warp, but the world turns out to be highly connected, and each discovery of a shortcut or link back to an old area brings a sigh of relief https://t.co/yy9khNyY1s
Communicating via Markov Decision Processes
https://t.co/swf2fTqzfN
possible explanation of noisy user inputs: the user is simultaneously performing a task and communicating a message through their trajectory
Dasher
https://t.co/l3BFDKTl7z
gesture-based typing interface from 2000 that uses arithmetic coding and a language model to minimize the number of bits the user communicates to the system
A Minimal Intervention Principle for Coordinated Movement
https://t.co/MfdI5lVTN2
possible explanation for noisy user inputs: with uncertain dynamics, an optimal user does not suppress task-irrelevant noise