we're worried about ai making some hyper logical decision that wipes humanity out
but i'm more worried about the people working on AI having their heads so far up their ass they start to justify horrible things for "the greater good"
This slide from the Anthropic IPO roadshow was a big factor in my decision to leave. It’s an insane plot and I’m surprised they made it public.
It shows the compute efficiency of pretraining over time. The y-axis is a **log scale**: they are seeing continued superexponential algorithmic progress.
Mythos was not a one-time deviation, but a point on a superexponential. They could already retrain Mythos with a fraction of the compute originally needed.
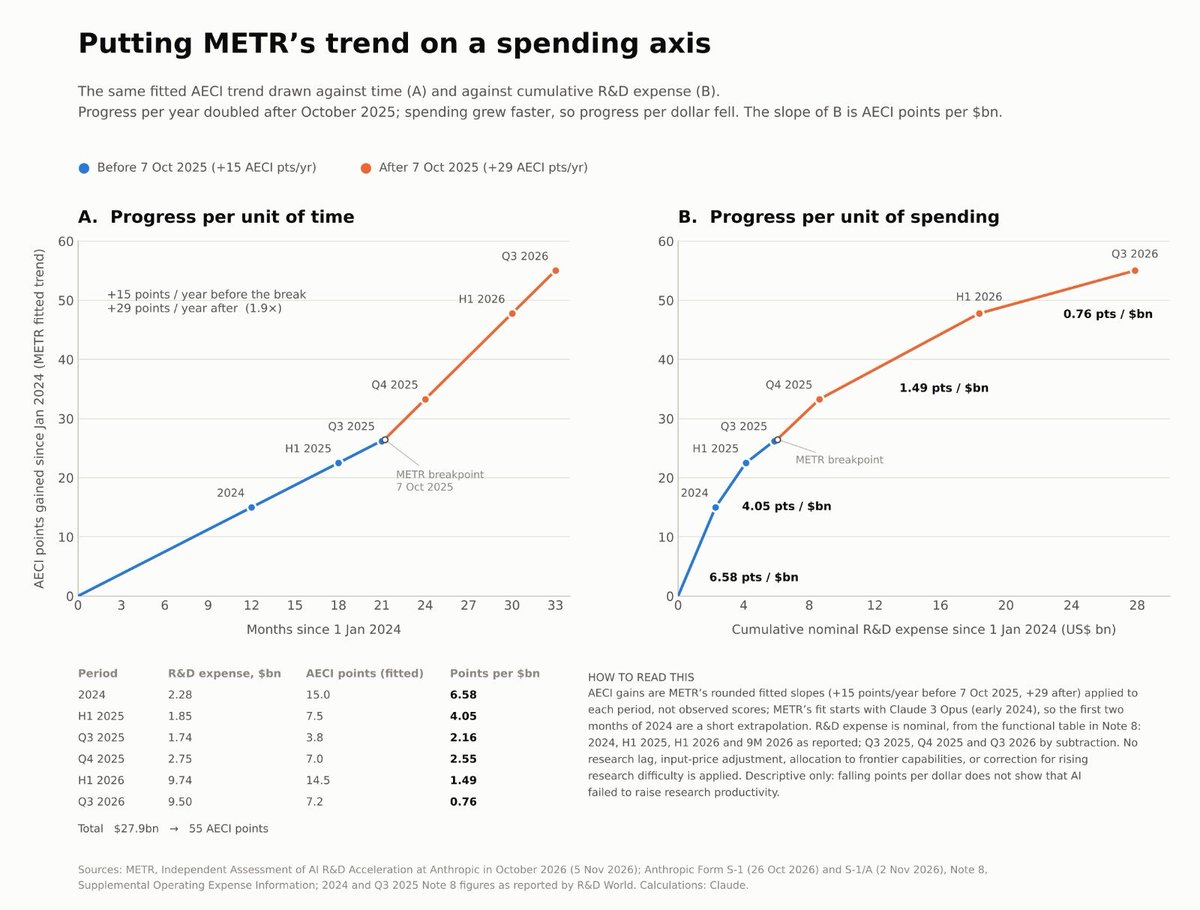
It doesn’t strictly imply a software-only intelligence explosion- they have been spending more on R+D. But algorithmic improvements do not require ridiculous creative genius and are on the verge of being automated. You do the math.
I bet against this and I bet against Dwarkesh.
He conveniently sweeps under the rug that climbing a metric involves defining it. Then, supposing you define it (in a way that avoids Goodharting, reward hacking, etc), you need data/envs, which do the lifting. On defining good metrics - this is most of the game of making AGI (converting fuzzy concepts to formalized objects you can climb without gaming, which requires costly fixes later). He elides the hard problem by saying 'AI will just automate data'.
How do you know whether a change belongs in your final recipe? You ablate at scale. When you make N changes, on even a subset of combinations, this compute cost is naively exponential. So, you need a faster signal to tell you when a task that isn't immediately verifiable improves end behavior. Finding that signal is the bottleneck, which doesn't seem to be helped by 'automating the great algorithmic thinker starting from the empty string on paper'.
@colemurray isn't the real reason people like 1 db per chat because giving llms write access is scary? a git-esque system with gated merging into main/prod solves it
the labs would rather things be 10x slower and 100x more expensive because it feels better to them ideologically (and of course financially)
so much is possible with fair competition
we built an inference engine for deepseek v4.1-flash from scratch. the core engine is just rust + cuda. no pytorch, no sglang, no dsls, etc.
~1740 TPS decode on 4xB300, 2060TPS on 8xB300. 1M token prefill in ~12s.
it's up on github
@ZyMazza these are fun because it is so easy to reveal that there is never an underlying principle behind the lab employee larp philoslopy. it all comes back to if we win I agree, if we lose I disagree
make something people want -> become a middle man selling data to 2-5 labs or build sandbox company slopclone
garry is really going all in on RSI+AGI narrative bc in any other version of the future this is just the median stanford CS version of dropshipping