OpenAI models are coming to Google Cloud.
We're bringing our frontier models and Codex agentic workflows to Google Cloud's Model Garden, so enterprises can use our technology where they already build.
https://t.co/gjuLVALjDm
@emollick I think game theory? (Ish) If all banks, airlines, etc block then they can collectively demand good terms from ai companies / companies making agents. If a few of them decide to allow then they're all screwed. maybe same trend as news companies & Google search
1) then whyre they pretraining
2) agentic coding token $s don't commoditize at scale. meta spends so much money on ant, the cost of bad code at scale is too high
3) idk
4) training large models is complex. msft & aapl aren't in the frontier game either. it's not just rl envs
Some thoughts about the frontier AI business right now:
1. The recipe for making AI coding models is widely known throughout the industry and all of Silicon Valley. There is no secret to this. It is primarily RL envs + Compute.
2. I predict in single digit years most companies / individuals will use free AI coding models. Free meaning sold at chip time (cost). There will be no real business in selling AI coding models, as there is no inherent moat in making AI coding models.
3. Frontier labs without cash producing businesses will be unable to subsidize AI coding models and will transition to selling other forms of intelligence like biology, chemistry, pharmaceuticals etc.
4. Most companies you see that are still behind in coding models like @Muse and @spacexai are mainly due to lack of RL envs and harder tasks. What I am saying here is that these gaps will further close, as these companies make more RL envs.
I don't care if I don't see it in my lifetime in mass usage. this is beautiful. spinners can be real some day. zooming in the heights of coruscant can be real some day. the future of humanity is bright.
@a__tomala :( order ahead? pack in checked in luggage? idk there's solutions I hope but also I get if it's painful to plan around it esp for long flights
quoting because diluted in replies. $100b capex > "lesser" opex later. anecdotally meta is 1/5th of ant revenue, implying ~$7-14b annual opex. meta is forecasting that to grow larger - they & most bigtech are better off developing their own models. $AAPL/$MSFT will feel this soon
Dumb question but what's the advantage of $META having spent 100b+ to develop their own model under Muse, as opposed to having kept that money and just built Muse with whatever model gets the job done?
@TechFundies token costs at their scale. anecdotally: 1/5th of ant revenue is meta. at 70b arr (35b avg), that's $7b annual costs; this will only grow to maybe 20-30b annual costs for meta. apply the same principle to consumer use cases too. They're spending capex today for lesser future opex
I left Google DeepMind in June. Jacob is right: many researchers believe they are building something that could kill everyone on the planet. It was literally my day job to think about how to stop that.
I suspect major distillation from 4.6 to 5.5 which will follow and repeat itself from 5.6 sol to whatever they release next, at least on writing / articulation
Opus 5.5 is currently the best model. Astra and the new sol are oddly again bad at writing, communication and style to the point it makes it hard to figure out what’s going on during long auto research loops. Quite frustrating.
Whatever made 5.6 sol amazing should be repeatable. But somehow it’s not. Funny how writing, comm style and personality are so hard to get consistently right. Why?
ok i think i finally figured out why alignment has gone basically nowhere after 15 years and several billion dollars. the problem is hard sure. but have you met the people in charge of it
1) the leadership does not know how computers work. ask one what happens when you type a url into a browser and watch them start sweating. dns is a spooky word. they genuinely believe the model lives in "the cloud" like a ghost haunting a castle
2) zero idea how large scale distributed systems work. never been paged at 3am. never watched one bad bgp announcement take half the internet offline. their big threat model is the ai "copying itself across the internet" like its a floppy disk virus from 1998. brother it needs 50 megawatts, a liquid cooling loop and a personal relationship with jensen. it is not escaping onto your smart fridge
3) they dont understand the stack they are supposedly protecting us from. ask about inference servers, kv cache, batching, egress, rate limits. blank stare. ask how the model will seize the power grid and you get a 45 minute answer with a hand drawn diagram and three links to their own blog
4) nobody can define an agent. ask ten of them and you get eleven definitions and a 30 page google doc. to the rest of us an agent is a while loop that calls tools and eats a 429 every thirty seconds. to them its a digital god in its larval stage. my agent cant book a dentist appointment without asking me three times if im sure
5) they started from "everyone dies" and worked backwards so every result is bad news somehow. model refuses, deceptive. model complies, sycophantic. model does well on evals, well now its scheming about the evals. i cant think of a single thing a model could do that would get them to say ok maybe we're fine
@BlackHC but maybe data (+ all the code that is now synthetically generated by llms and checked into github is a slower but sufficiently good loop - which feeds back into pretraining)
Anthropic has set up a wet lab in San Francisco, their bio research has advanced beyond in silico. They are now conducting physical research both in-house and with external partners. The NYT also broke the news this morning that Anth now plans to scale its compute to 5 GW by the end of the year, and 10 GW within the next 16 months. Bio is next after math, and I think we are going to see some medical announcements much sooner than people are expecting.
idk. median quality of life in sg is higher (esp vs US). the upside is not as high, the social risk of failing is worse - so people dont take risks. consequently, striving to be slightly above avg (via early game) basically lands you at amazing quality of life vs rest of world
Early game in sg is overrated. Mostly a deep dive into a local minima (a decent one but far from global).
I frequently tell others the reason why I'm here today is because I did horribly for a levels and CS was a alevels dumping ground back then. If I had a strong early game maybe I could have accidentally gone into finance or law. 😳
Common wisdom in sg is also generally local minima diving and more often than not, just bad advice. Be brave to be who you are and enjoy what you do.
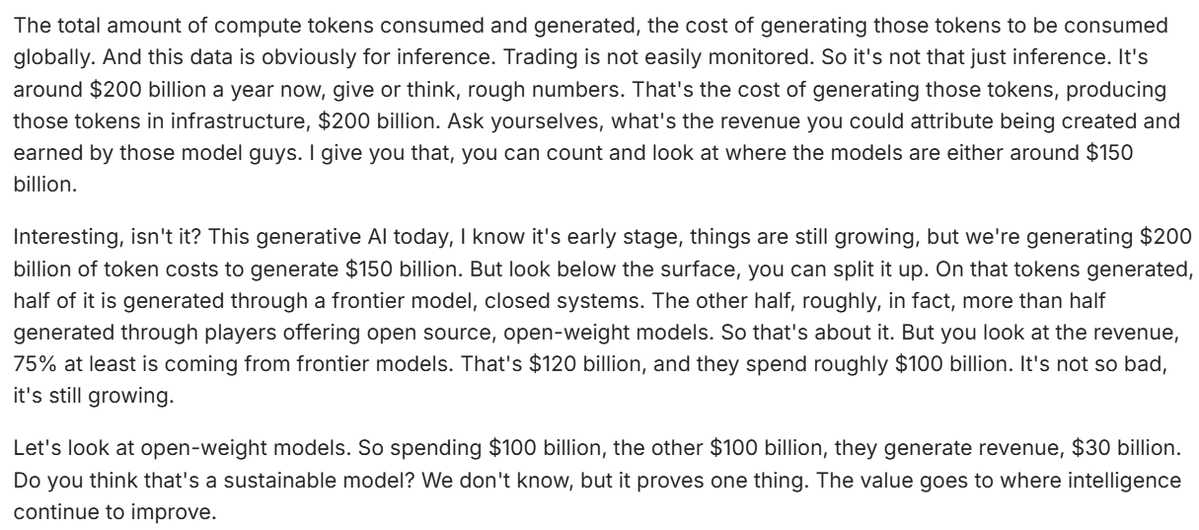
Broadcom CEO Hock Tan breaks down AI economics:
Open-weight models burn $100B compute to make $30B in revenue.
Frontier models spend $100B to make $120B in revenue.
One of these won't be sustainable
source: Goldman conference