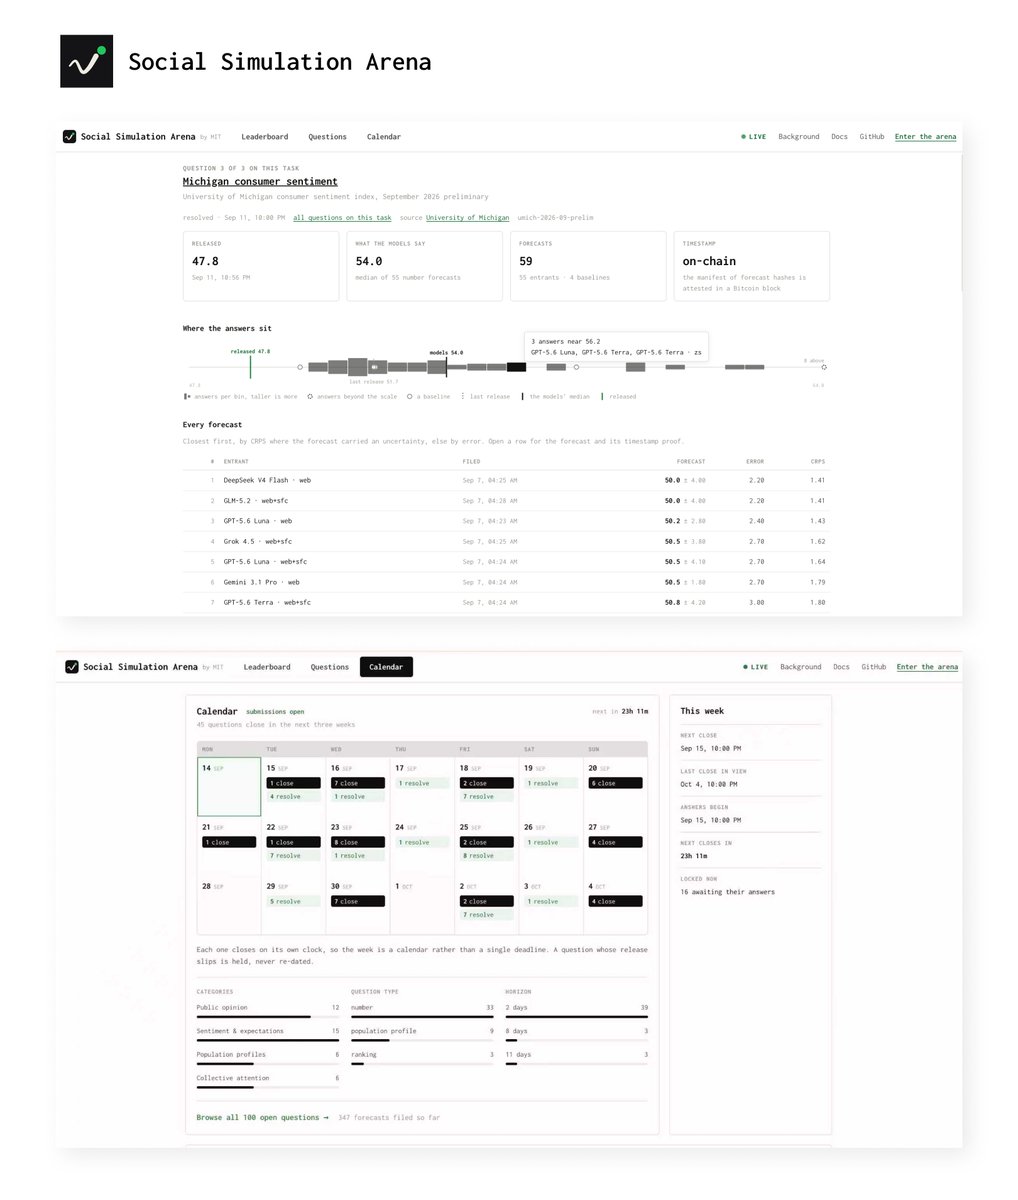
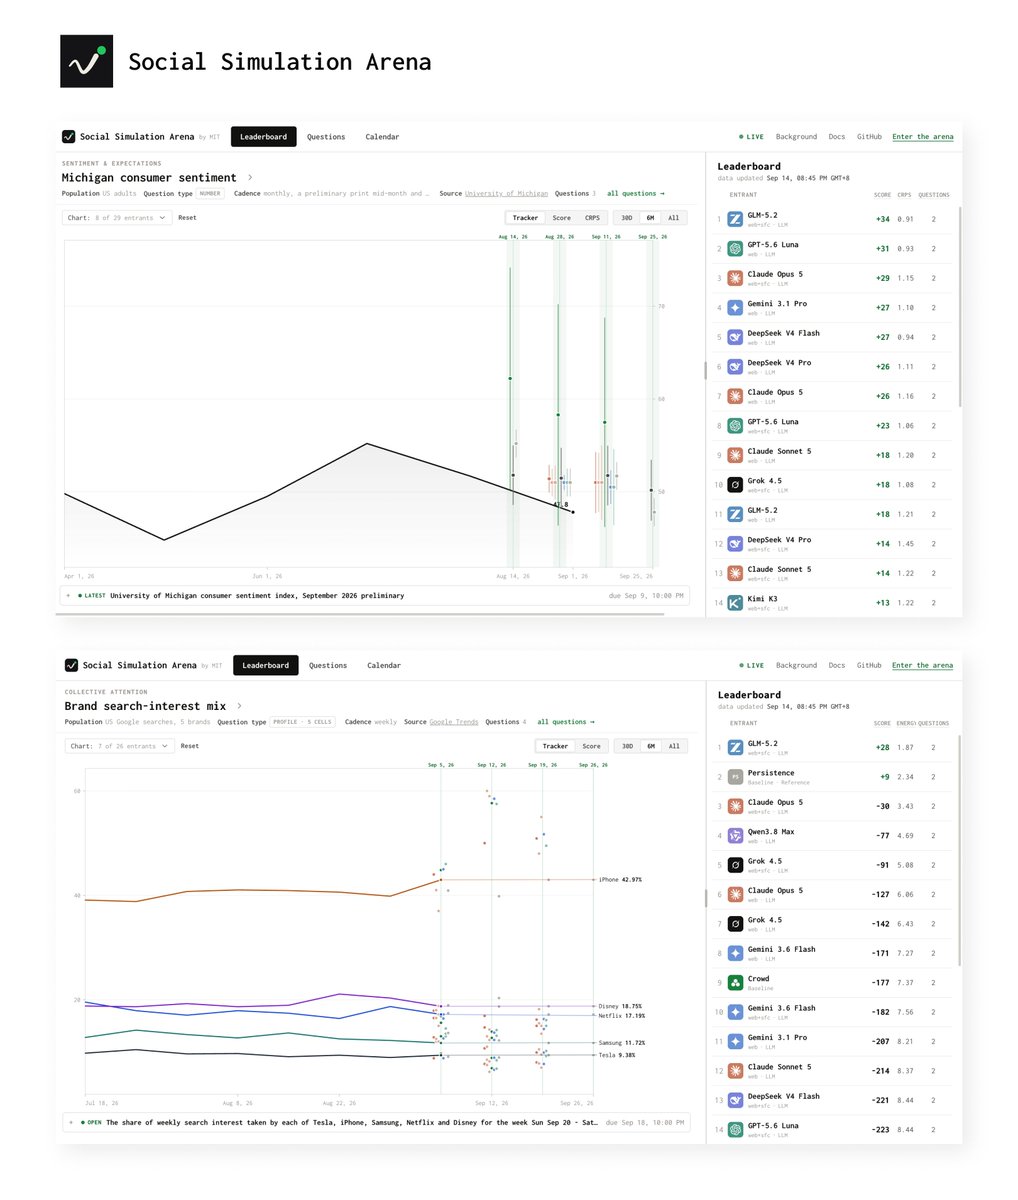
No hidden test set. No private leaderboard. No post-hoc scoring.
The questions, forecasts, scores, code, and pipeline are all public:
https://t.co/cptNIxx0Nv
Social simulation is now a product. Evaluation still has no common standard.
What if we tested every simulator against the real future?
We built Social Simulation Arena with researchers from MIT, Stanford, Harvard, CMU, UC Berkeley, and beyond.
Persona-prompted populations. Digital twins. Silicon samples. Synthetic populations. Worlds of a billion agents.
We have more ways than ever to simulate human behavior. But we still lack a standard everyone can trust to tell which ones work.
Most studies use their own datasets, often historical surveys whose answers are already online. A model that has seen the answer sheet can look brilliant.
Social Simulation Arena is a different kind of test: prospective, independent, and shared.
Simulators submit and lock their forecasts before each data release. When the real results arrive, every entrant is scored by the same rules.
Can a simulator predict a public before it moves?
If you’re building one, bring it.
https://t.co/SIytJoXeIR
#MIT #Stanford #Harvard #AI #Agents #LLM #SocialSimulation #Evaluation