最近的 Vibe Coding 战绩,累计 23 亿 Token。😂
从最初的 AI 辅助编程,到多 Agent 协作、任务拆解、交叉验证、逐步验收,终于摸索出了一套能实际交付应用 Demo 的 AI 研发工作流。
现在越来越觉得,AI 时代真正重要的,不是哪个模型最聪明,而是如何让不同模型高效协作、持续纠错,用更低的成本把想法变成真正能运行的系统。
模型可以随时替换,工作流和工程能力才是自己的。
继续迭代。🚀
My latest Vibe Coding milestone: 2.3 billion tokens processed! 😂
From basic AI-assisted coding to multi-agent collaboration, task decomposition, cross-validation, and step-by-step verification, I've finally built an AI-powered development workflow capable of delivering real, functional application demos.
The more I work with AI, the more I realize that the future isn't just about which model is the smartest. It's about orchestrating different AI models efficiently, continuously identifying and correcting errors, and turning ideas into working systems at a fraction of the traditional cost.
AI models are replaceable. The workflow, engineering expertise, and problem-solving capabilities are what truly belong to you.
Keep building. Keep optimizing. Keep evolving. 🚀
1/ 关于 AI 记忆问题,五句硬话。别指望"再等一代模型就好":· 权重在推理时是冻结的,上下文窗口是唯一的工作记忆
· 上下文不是记忆,是输入。每轮重读一遍,早期规则被后来的工具输出稀释——这就是跑偏的机制
· 所有叫"记忆"的功能,本质都是外挂检索。存得下,但不知道什么时候该想起来
· 根本解法要换架构,不是加参数。持续学习的方向都有论文,没一个在前沿规模上被证明
· 几年内别指望。按"靠外部锚点"来规划工作流,不吃亏
2/ 有人说没有记忆 AI 就不能自动进化。不对。进化本身就是个失忆过程——基因不记得任何东西,每一代从零开始,进化照样发生。记忆在种群和筛选机制里,不在个体脑子里。AI 研发同理:记忆在 git、实验日志、下一代权重里,不在模型脑子里。记忆是加速器,不是前提。
3/ 反过来想:真有了持久记忆的模型,会让人的警报器变钝。现在我能当控制面,是因为模型每次重开都是透明的——它脑子里只有我喂的东西。一旦它有了我不知道的记忆,可比对的基线就没了。人的角色从"补记忆"变成"审计记忆"。而审计记忆这件事,个体干不了——个体有盲区、有情绪、有三观。需要规则,需要团队。这是另一种经验,现在还没人有。
1/ Five hard truths about AI memory. Stop waiting for “the next model generation will fix it”:· Weights are frozen at inference. The context window is the only working memory.
· Context is input, not memory. It’s re-read every turn; early rules get diluted by later tool output. That’s the mechanism behind drift.
· Every feature called “memory” is external retrieval. It can store. It doesn’t know when to recall.
· The real fix needs a new architecture, not more parameters. Continual learning has papers; none proven at frontier scale.
· Don’t count on it for years. Plan your workflow around external anchors and you won’t lose.
2/ “Without memory, AI can’t self-improve.” Wrong.Evolution itself is an amnesiac process — genes remember nothing, every generation starts from zero, evolution happens anyway. The memory lives in the population and the selection mechanism, not in any individual.Same for AI R&D: the memory is in git, in experiment logs, in the next generation’s weights. Not in the model’s head.Memory is an accelerator, not a prerequisite.
3/ Flip it around: a model with real persistent memory will dull the human alarm system.Right now I can act as the control plane because the model is transparent on every restart — it only knows what I fed it. Once it carries memory I don’t know about, the baseline for comparison is gone.The human role shifts from “supplying memory” to “auditing memory.” And auditing memory is not an individual’s job — individuals have blind spots, emotions, worldviews. It takes rules. It takes a team.That’s a different kind of experience. Nobody has it yet.
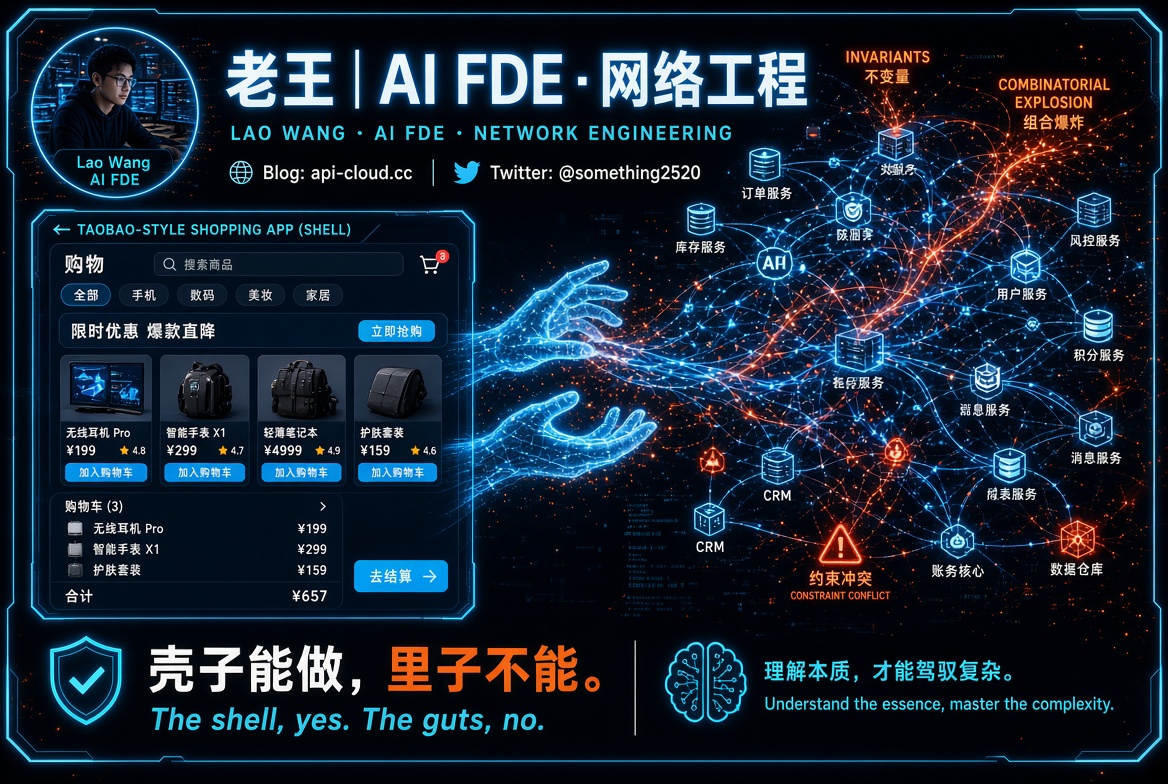
AI 现在能不能开发出淘宝/京东这种 APP?
拆开说。
淘宝样式的 APP——商品、购物车、订单、支付、后台——能做,一个人几周到几个月。
淘宝本身——不能,而且不是差一两代模型的事。
差的不是写代码,是装不进任何上下文的东西:
· 几十个系统之间的不变量,没人脑子里有全图
· 非功能需求是在生产里被打出来的,不在需求文档里
· 代码是线性生成的,交互是组合爆炸的,验证比生成长得快
· 老板说不清的业务逻辑,AI 只能猜
壳子能做,里子不能。而且里子的难点和写代码没关系。
Can AI build a Taobao / JD-style app today?
Split the question.
A Taobao-style app — catalog, cart, orders, payments, admin — yes. One person, weeks to months.
Taobao itself — no. And not by one or two model generations.
What’s missing isn’t code. It’s everything that doesn’t fit in any context window:
· invariants across dozens of systems that nobody holds in one head
· non-functional requirements that only surface in production, never in the spec
· code is generated linearly, interactions explode combinatorially — verification outgrows generation
· business logic the boss can’t articulate, so the AI can only guess
The shell, yes. The guts, no. And the hard part of the guts has nothing to do with writing code.
Codex 不是生产力低,是计费结构惩罚执行型用法。
Agent 模式下每一轮工具调用,都按当前整个上下文窗口扣费。读仓库、改文件、再读回来……上下文越滚越大,每一轮都比上一轮贵。
出方案是一次性付费,执行是复利式烧钱。
所以同一份 $20 额度:当军师最赚,当码农最亏。我的工作流里 Codex 只做方案和 review,执行交给别的模型。不是它写不了代码,是算不过账。
Codex isn’t low-productivity. Its billing punishes execution-style usage.
In agent mode, every tool call is charged against the entire current context window. Read the repo, edit, read it back… the context keeps growing, and every turn costs more than the last.
Planning is a one-time charge. Execution is compound interest.
Same $20 quota: strategist = best value, coder = worst. In my workflow Codex only does plans and reviews; execution goes to other models. Not because it can’t code — because the math doesn’t work.