Tried gpu-unlock on my RTX 3060 12GB.
BF16 matmul: 48.1 TFLOPS measured vs ~25 stock spec
TF32: 23.6 vs ~12.7
On paper that puts it between a stock 3070 Ti and a 3080 for ML training, on a 3060.
https://t.co/d9OybEvp1l
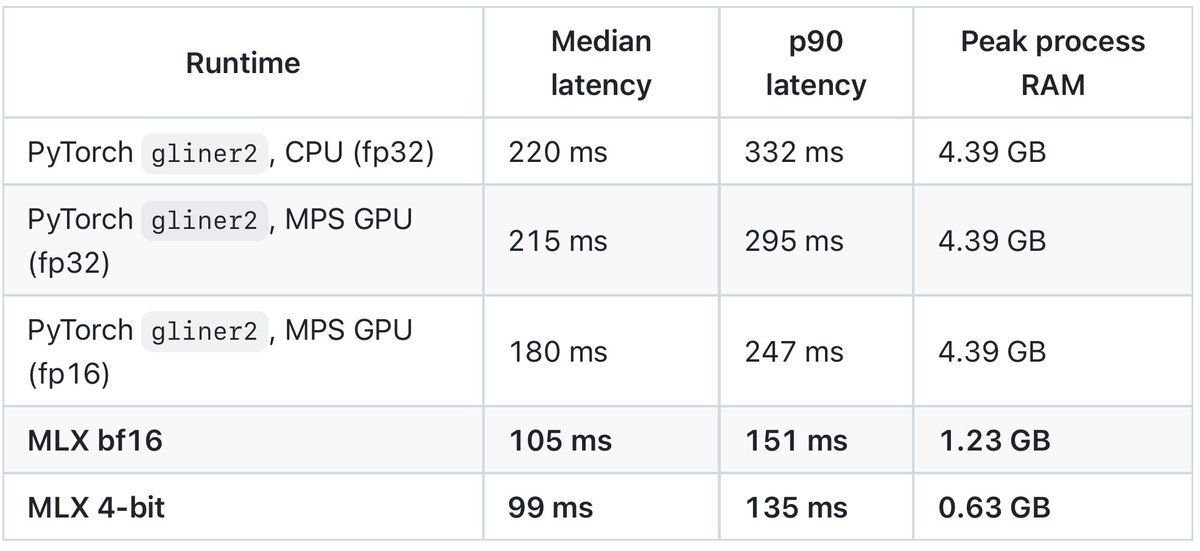
PyTorch's MPS backend is barely faster than CPU on GLiNER2.5-Decide (from @fastinoAI ). So I ported it to MLX.
On an M4: 99 ms vs 220 ms median, 0.6 GB vs 4.4 GB peak RAM, same 63.7% accuracy. No torch, just mlx + numpy + tokenizers.
GLiNER2.5-Decide from @fastinoAI now runs on MLX.
Three versions: 4-bit (350 MB), 8-bit and bf16. Native on Apple Silicon, no PyTorch. About 2x faster and up to 7x less RAM than PyTorch, with the same accuracy.
https://t.co/gQsngkTGeJ
https://t.co/gADJGuvPrv
@floragraeca@sseraphini Além das linguagens é legal olhar padrões de desenvolvimento e arquitetura. Provavelmente você conseguirá implementar em diversas linguagens. Esse site tem exemplos muito interessantes: https://t.co/CUn0b3nm9B
@flaviojmendes@sseraphini Conhecimento sempre é bom. Arquitetura, bons padrões de design, SOLID e lógica de programação também são pontos importantíssimos. Link interessante: https://t.co/Rjcs1ew3iy
@vilailus @sseraphini@srprogrammer MVVM é bastante utilizado pelo pessoal do Xamarin. Um pouco diferente do MVC mas nem tanto assim rsrs https://t.co/eyJXkhADIi.