Ora Frontier is now Sparset.
Fastest company in s16vc history from cohort to investment, and the only startup funded after bootcamp.
We’re building autonomous AI inference infrastructure, from datacenters to edge devices.
The future of AI runs everywhere.
https://t.co/RlEa03TeRU
Last week we announced our rebrand to Sparset. We'd like to introduce ourselves properly and share what we've been building.
Marcel Slowikowski, our co-founder and CEO, explains why running your own AI model is harder than it should be, what Sparset does about it, and what that looks like for a customer already running on it in production.
If your team is deploying AI models in production, or wants the inference you already run to cost less and go faster, let's talk: https://t.co/duc5X0dfDB
Introducing Ora Nanolite V2, a 4B parameter model addition to our family of local task models trained for faster reasoning on consumer devices.
Based on the Qwen3.5-4B model, Nanolite V2 achieved up to 15.3x speedup in output generation while outperforming its base model across GSM8K and MMLU-Redux benchmarks at an average of 92% fewer output and reasoning tokens.
V2 holds better reasoning capabilities for more advanced tasks compared to the first 0.6B parameter Nanolite model.
You can read more about both models and its benchmarks results in our most recent blog: https://t.co/KKLuXVhOT5
Are you looking for specialized local models for your own business' specific tasks? Send your inquiries to [email protected]
Introducing Task Models, our solution for enterprises and teams looking to own personalized intelligence.
Most day-to-day tasks don’t require the capabilities of large frontier AI and expensive hardware. Task Models are smaller local models trained to be the best at the one thing you need it to do.
Small enough to fit on any laptop, even phones, while still delivering the level of output required.
Ora Task Models are now available under Ora Fleet for any interested teams and businesses.
Read more about it in our blog: https://t.co/9z66mzh9B3
The future of AI is privacy and ownership, not larger datacenters for cloud models.
We compress open-source AI so you can permanently run, control, and truly own intelligence on-device, even with the world's best models.
Every API call is a transaction that introduces data privacy risks, network latency, and compounding usage costs. By shifting the execution layer directly to your own hardware, you eliminate the reliance on third-party servers.
It is time to move away from rented cloud compute and transition to fully owned, high-performance private AI powering your enterprise and personal systems.
Visit https://t.co/WyqMNK4IEt to read more about us
Own the power of an AI data center, without needing all the server racks and costs.
We compile open-weight models to compress that level of frontier performance directly onto your local machine.
Historically, running high-accuracy models locally meant investing in extremely expensive server setups, or compromising on data privacy by routing sensitive corporate files through third-party cloud APIs. We are building Ora Frontier to break this cycle by compiling and optimizing open-weight models specifically to run on consumer-grade local silicon.
By running on your own machine's CPU, GPU, and hardware, we deliver high-throughput, private inference right on your desk, keeping your files, prompts, and workflows entirely secure and offline.
If you're a business or someone who has been wanting to integrate the world's strongest local models but wants to avoid the unnecessary costs that come with it, email us at [email protected] or join the waitlist: https://t.co/WyqMNK4IEt
#Local #Private #Frontier #AI #Ora #OpenSource
The idea that behind every great AI model is a data center is now over. You no longer need specialized enterprise clusters to run frontier models at high speed and with high accuracy.
Running standard, unoptimized AI models locally often results in massive resource overhead. Current compression methods may help a little, but at the expense of quality.
However, we are dedicated to research ensuring running accessible local AI comes with very few sacrifices.
Ora's Foundry compiler and Pulse runtime serve as the dedicated optimization layer for your device. By compiling and restructuring how we run LLMs specifically for your consumer-grade hardware, we strip away structural inefficiencies and resource bloat.
Hardware that previously struggled with running 7B models can now execute more capable models at industrial-standard speeds, maintaining absolute data privacy with none of the hardware tax.
Join the waitlist: https://t.co/WyqMNK4IEt
#Private #Local #Frontier #OpenSource #AI
Keeping company and enterprise data private shouldn't require a dedicated data center.
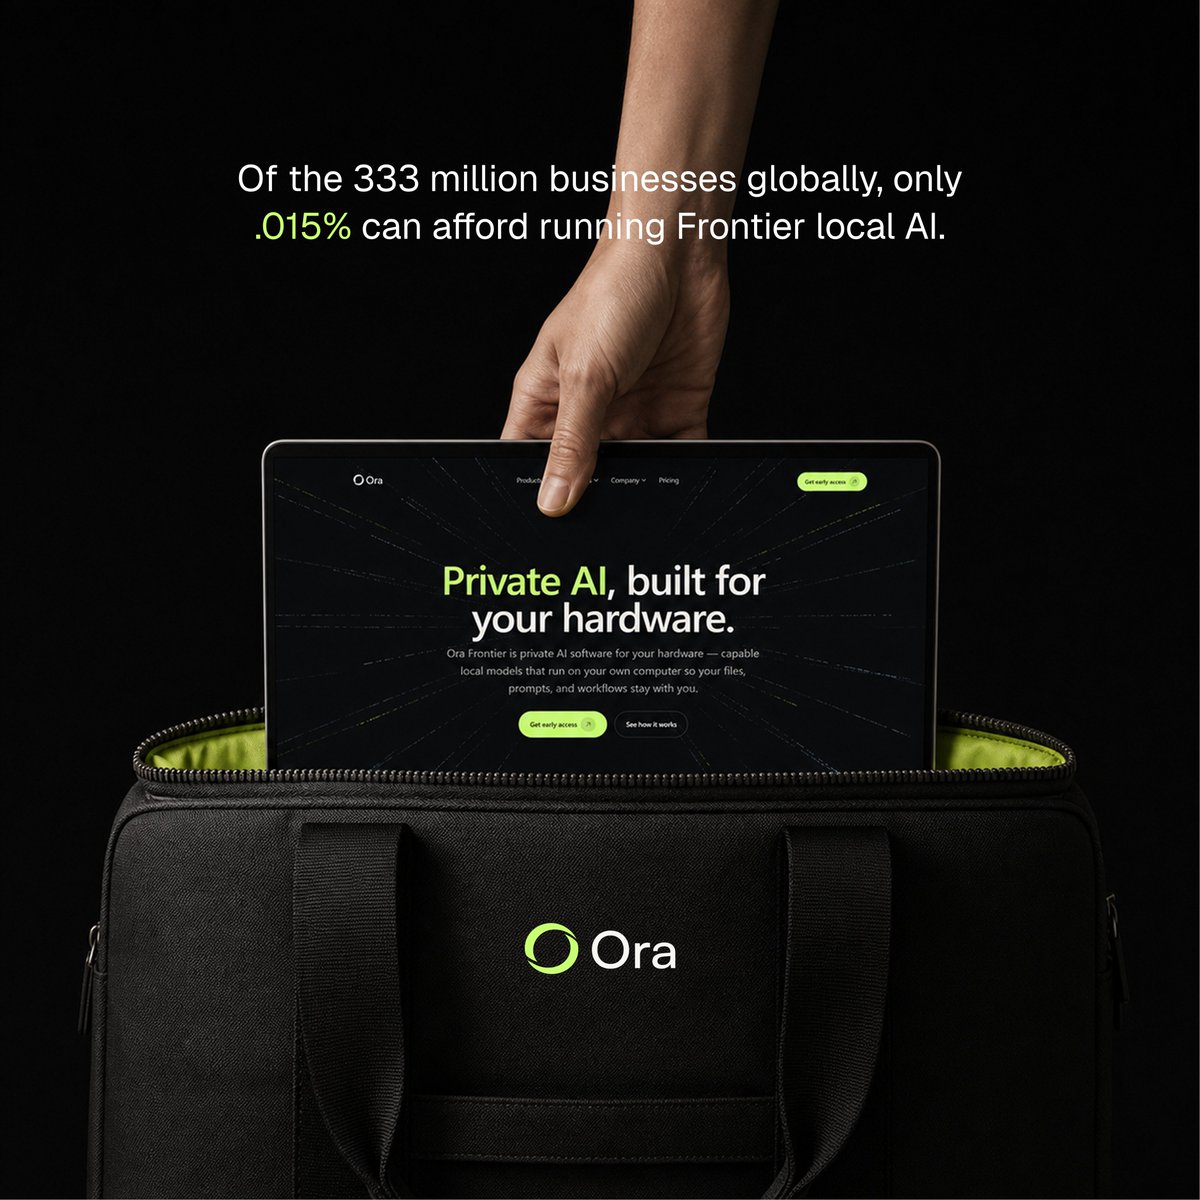
Most companies globally have announced efforts to adopt local, private AI on-prem for security and privacy.
However, the hardware requirements for local AI force a compromise: invest in expensive enterprise silicon, or send sensitive data to third-party cloud APIs.
@OraFrontier is private AI software built for the hardware you already own. By optimizing and compiling frontier open-weight models to run efficiently on standard consumer workstations, we keep your files, prompts, and workflows entirely secure on-device.
Have a proprietary model you'd like to optimize and compress to run on your hardware way cheaper? Ora Fleet takes care of your enterprise needs as well.
Check out our website for more and join the waitlist: https://t.co/WyqMNK4IEt
#LocalAI #Private #LLM #AI #Frontier #OpenSource
Frontier intelligence is no longer locked away behind an API or the cloud.
With Ora, you can now unlock the power of an AI data center inside the laptop that fits in your bag.
Discover more about how you can push beyond the potential of your machine's hardware in running local, open-source AI models through Ora Foundry and Pulse: https://t.co/WyqMNK4IEt
Join the waitlist so you stay at the front of the next big wave in the AI landscape.
#Local #Private #Frontier #AI #OpenSource #Ora
Why burn thousands on cloud AI models when you can get unlimited tokens through local AI?
With Ora, hardware is no longer the bottleneck for open-source local AI models. It's choosing the right one for your use case.
Join our waitlist and keep an eye out for our future compressed models on our website: https://t.co/WyqMNK4IEt
If you're a business wanting to escape the trap of AI cloud providers with your own proprietary local AI environment, check out Ora Fleet and keep your data private: https://t.co/RPEQ3MRHXv
#Ora #Local #Private #AI #LLM #Frontier #OpenSource
Announcing our official first set of planned models to compress and serve!
At Ora, we follow a key philosophy: Why rely on the cloud when your own hardware can do the heavy lifting?
We want to ensure more people are able to own private, local, state-of-the-art intelligence of all sizes. Therefore, we are officially introducing the first set of open-source models we will be compressing and providing through our compiler (subject to change):
1. Qwen3 Coder A3B (30B)
2. Qwen3 Coder Next (80B)
3. GPT OSS (120B)
4. DeepSeek V4 Flash (284B)
Interested in going beyond your hardware's perceived limits and seeing which of our planned models can run on your machine?
Check out our model catalog, and keep an eye out for any future updates: https://t.co/mPxnTv05kZ
#Private #Local #AI #Ora #Frontier #Intelligence #OpenSource
The gap between open-source and closed-source AI models is decreasing rapidly.
The ecosystem, reasoning, accuracy, and availability are all there ready for you. Yet, the real question is: are you and your hardware ready to leverage this shift in the AI landscape?
If the answer is "no" simply because you're not able to run the state-of-the-art open-source models on your current hardware, then you can turn that into a "yes" with us.
Make sure to join the waitlist at https://t.co/WyqMNK4IEt to have the opportunity to start owning your own frontier intelligence with local AI.
#Local #Private #AI #OpenSource #Ora #Frontier
Ora Frontier has the technology to shift the AI landscape, now we need someone to help ensure that change is delivered.
We are now looking to hire a Founding GTM Engineer to join our team.
This is a role for someone who wants to work at the intersection of engineering, product, customers, technical storytelling, partnerships, and company-building.
You will not simply explain a finished product after it has been built. You will work directly with users, help deploy Ora Frontier into real environments, discover where the product succeeds or fails, and bring those lessons directly back into engineering and product development.
As a founding member, we expect you to be someone who is willing to take risks, sacrifices, and the responsibility to help build the future of local AI from scratch alongside us.
Read more and view the job description on our website: https://t.co/uU1rm42Y38
#GTM #Engineer #Local #Private #AI
Introducing Ora Frontier: a new shift in what's possible with local and private AI on the machine you already own
A laptop that once could only run a 7B parameter model may now run up to 30B+ parameters comfortably, at 99% accuracy and industrial-standard speeds.
We're announcing this new launch alongside our flagship technologies Ora Foundry and Pulse, our proprietary compression and runtime stack that allows us to compress the world's frontier open-source intelligence down to a fraction of its original compute requirements with no noticeable drawbacks in model capabilities.
You no longer have to decide between sacrificing intelligence for privacy versus your own data for better reasoning from third-party cloud APIs.
With Ora, you can run the frontier on your own consumer-grade hardware beyond what was normally capable.
Read more and join the waitlist at https://t.co/WyqMNK4IEt so you don't miss out on the next new wave in AI.
#Local #Private #AI #Ora #Frontier #LLM #OpenSource