@o_at72@PeasantSmith And like I said. This is only the beggining, a small step, but I know we are gonna get real better... Also very soon they are releasing qwen4, We already can imagine how wonderful it is going to be with strata engine.
@o_at72@PeasantSmith Yeah 🤣🤣 mostly because my hyperfocus mode is on... so my last 48 hours was about trying to run it as fast as I could, and the result was good! We came from average 3.5tk/s to 16,9 tk/s today, now I believe I'm satisfied and was able to contribute to the community
@o_at72@PeasantSmith Also, on my box, when it grabbed ~45.3 GB the engine failed to start with "pinned disk staging did not allocate". I'm going to report that one to the dev.
Thanks for the AHEAD tip, it's what got me digging!
@o_at72@PeasantSmith One heads-up if you benchmark: the RAM tier is sized from free RAM at startup, so back-to-back runs get different tier sizes and that skews the numbers a lot. One of my runs got 4 GB less and lost ~10%. Pin it with STRATA_GLM_RAM_GB while comparing.
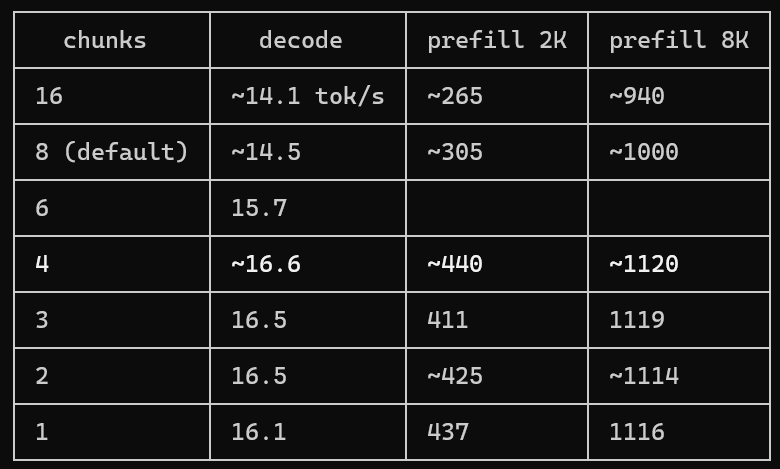
@o_at72@PeasantSmith But that's a guess, and since you're more disk-bound than me it could be even bigger for you, or nothing. Worth trying --env STRATA_GLM_READ_CHUNKS=4 and maybe 2.
@o_at72@PeasantSmith +15% decode just from that. Anything from 1 to 4 flattens out, so I kept 4. Disk wait per token dropped from ~30–37 ms to ~17–29 ms. My guess is that fewer, bigger reads suit my NVMe RAID 0 better, and the reader threads compete less with the CPU lane.
@o_at72@PeasantSmith Yeah, 64K is on purpose. That's all I need for my agent harness, and with KV_INT8 it only costs 0.68 GB of VRAM, so my expert pool stays at the full 2352 slots. 256K would eat ~1.2 GB more of the pool all the time, even on short chats, and I never fill it.
@o_at72@PeasantSmith For reference, I'm at ~14 tok/s decode, sometimes 20+ once the caches are warm on short answers. Disk misses are still about 40% of my per-token time, so that's where any further speedup would come from.
@o_at72@PeasantSmith My guess is the lookahead reads, including the wrong guesses, compete with the real ones on the same NVMe. The dev's bench notes saw the same thing, so I turned it off. It probably depends a lot on the machine: your RAM/VRAM/disk mix may be where it pays off.
@o_at72@PeasantSmith AHEAD=2: no gain for me. The averages were the same as before, around 11.5–12 tok/s. It cut disk reads per token by about a third, but each read got ~45% slower (2.0 → 2.9 ms), so total disk wait per token barely changed.
@kenznajd @PeasantSmith Now on real work I'm getting an average of 14 t/s and hitting up to 20t/s, and I'm talking about running the GLM 5.3 Flash locally on a mobile 5090 with 24gbvram + 64gb ram.. that is trully amazing!
@kenznajd@PeasantSmith but this is a beginning bro, 3 weeks ago you would need 3 dgx spark to run GLM 5.3 flash, that is a $21k dolar build, now people with a 5k rig can run it. And it is only one step, not the final step.
@BnnhZ47741@PeasantSmith@pebaryan That is awesome!!
After last update now I'm getting up to 20tks (and an average 14tks) working with MayaS, (with a mobile 5090 24gb + 64gb ram) that is really awesome!