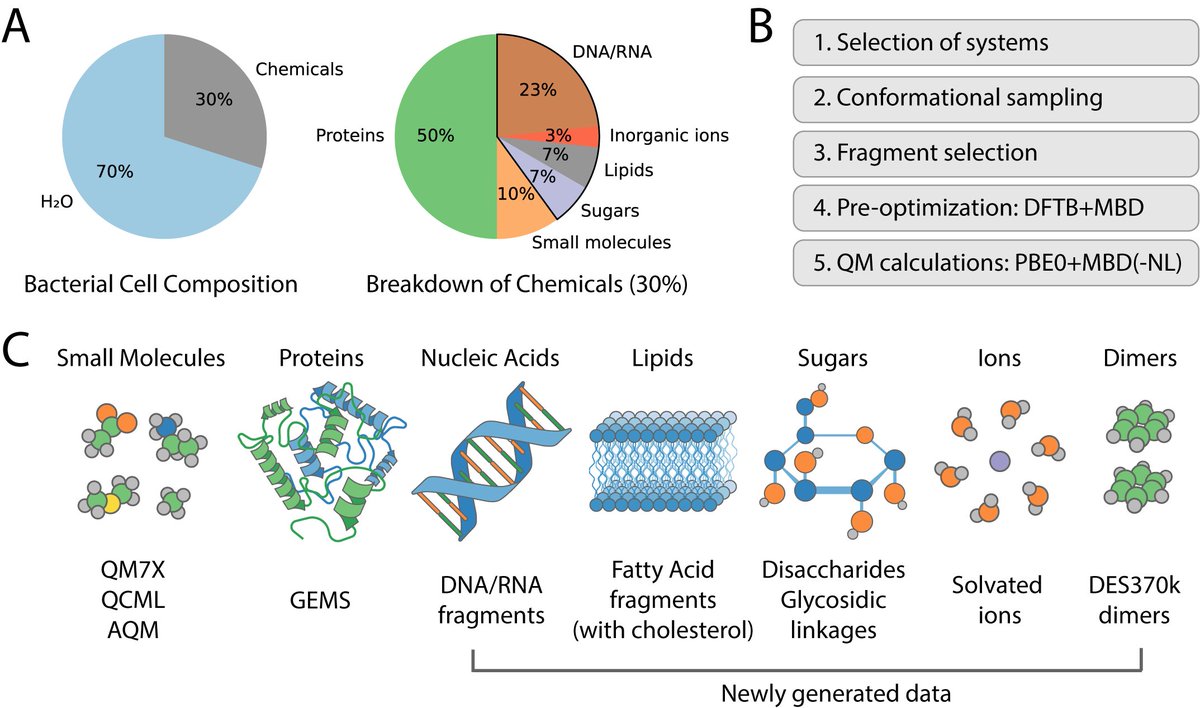
💫 As promised, we just released on GitHub the weights of the #FeNNixBio1 foundation machine learning model for drug design! 💫
Weights: https://t.co/QTLgyTZ3ad
FeNNol GPU code: https://t.co/ElYjDaNVDD
The models are distributed under the open source ASL license (i. e. restricted to non-commercial academic research).
You can also check the updated version of the preprint that includes a unified transformers architecture as well as the full computation of the Freesolv hydration free energies dataset etc...
https://t.co/eto2c2YXFO
Happy holidays and merry Christmas everyone! 🎅 🎄
Sorbonne Université / CNRS
@qubit_pharma
#machinelearning #moleculardynamics #drugdesign #compchem #GPU #biophysics
Thrilled to share our new work MatInvent, a general and efficient reinforcement learning workflow that optimizes diffusion models for goal-directed crystal generation. Thanks to @JeffGuo__ , @efssh , @pschwllr , @SchwallerGroup , @NCCR_Catalysis .
https://t.co/S7ibrRNdxp
@AlexShtf@HannesStaerk That is for sure. Your memory access should be coalesced. But even if you do everything right, shared memory is still much faster than main GPU memory, see, e.g., figure 2 from here https://t.co/PnV4aZJk3I
@AlexShtf@HannesStaerk I would say that the main speedup comes from using shared memory (L1 cache), and it is hardly achievable if using pure python. Nevertheless, there could be, indeed, some opportunities to speed up, if not so dramatically.
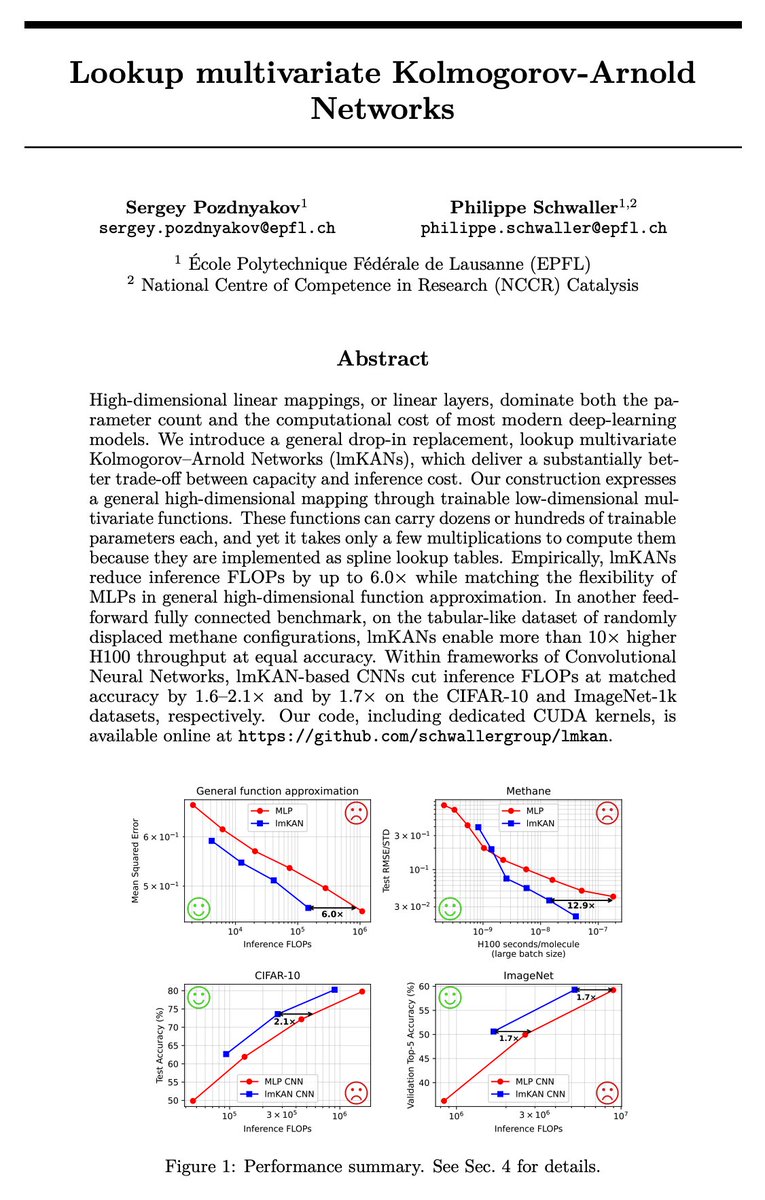
(*) CUDA kernels so that lmKANs > MLPs on modern GPUs and (**) multivariate extension.
GPUs & current ecosystem are made for dense matrix multiplications, not for lookup tables, so a naive implementation is very slow. With custom CUDA kernels, we made lmKANs Pareto optimal compared to MLPs on modern GPUs.
Also, the proposed multivariate extension of KANs relying on 2d functions performs way better than standard 1D KANs.
Reading group session on Monday: "Lookup multivariate Kolmogorov-Arnold Networks" https://t.co/W11eNHMlR9 with Sergey Pozdnyakov
On zoom at 9am PT / 12pm ET / 6pm CE(S)T: https://t.co/Kew3F4DXag
Exciting postdoc opportunity in the @SchwallerGroup at EPFL!
We're hiring a postdoc to advance ML-driven synthesis planning after Zlatko Joncev’s successful exit to co-found B-12 (YC '25) 🚀
Work on:
- LLMs for strategic synthesis planning
- Chemical reasoning at scale
- Building the next-gen framework for retrosynthesis
Our recent preprint shows that LLMs can guide synthesis planning with natural-language strategies — combining AI reasoning with traditional chemical tools (https://t.co/RYVkt5NRYA).
Join us at the intersection of chemistry & AI. Up to 2 years. Based in Lausanne 🇨🇭
Apply: https://t.co/c3Uh1wcRjt
#ChemTwitter #MachineLearning #SynthesisPlanning #PostdocPosition
@chaitjo Well, you need your NN to be able to express many body features of sufficiently large order to be expressive enough. Also, I don't think that restricting the body order really works as a preconditioning. Thus, I would say, the more the better, until it is computationally cheap.
Interesting question. Kolmogorov-Arnold Representation Theorem also requires one hidden layer, similarly to Cybenko's one. The difference is that the former states so for the finite (2n) number of neurons in the hidden layer. So, I would look into (and nearly certainly it is) that spline look-up-table KANs can fold the space similarly without the limit of an infinite number of neurons, as in the case of MLP.
High-dimensional linear mappings, or linear layers, dominate both the parameter count and inference cost in most deep learning models. We propose a general-purpose drop-in replacement with a substantially better capacity - inference cost ratio. Check it out!🧵
You don’t like molecular dynamics? We get it. That’s why at this year’s LLM hackathon for Chemistry and Materials Science, we built not one, but ✨two✨ AI agents for molecular dynamics 👇
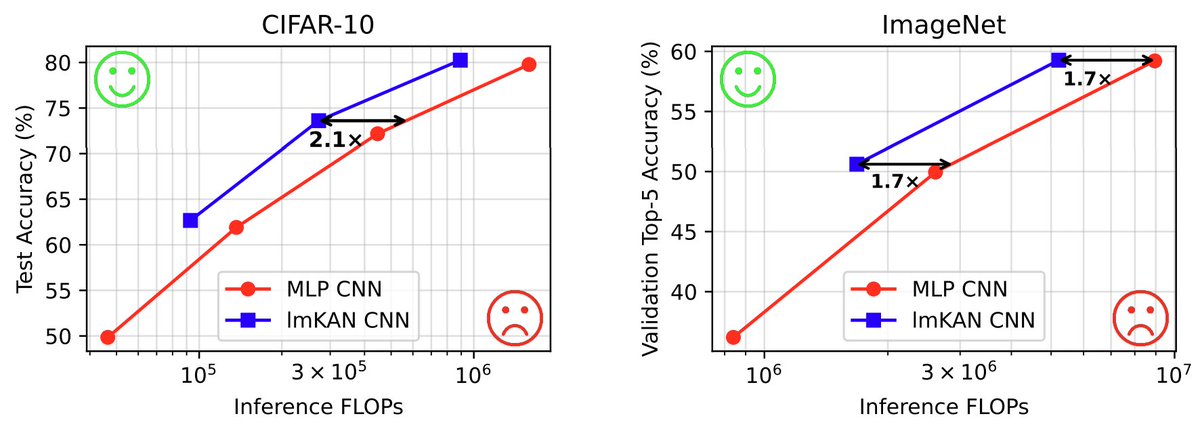
We did it for Convolutional Neural Networks, and it works too. lmKAN-based CNNs are Pareto optimal on both the CIFAR-10 and ImageNet-1k datasets, achieving 1.6-2.1× reduction in inference FLOPs at matched accuracy.