A Representation Sharpening Framework for Zero Shot Dense Retrieval
Amazon proposes a training-free framework that augments document representations with contrastive queries to improve zero-shot dense retrieval without retraining the model.
📝 https://t.co/vZM9cCIK5N
Token Pruning Optimization for Efficient Multi-Vector Dense Retrieval
Amazon proposes a learnable token pruning approach that reduces memory usage and inference time by up to 3.3x while maintaining competitive retrieval quality in zero-shot settings.
📝https://t.co/OxBcUimfsz
This past semester, I had fun creating a new course at Johns Hopkins @JHUCompSci on Multilingual NLP. Basically, people frequently talk about NLP and AI within the context of English. This class was about the cool problems that exist when we look beyond English. 1/7
On Tuesday 3:30-5:00pm, I will be presenting a poster of "C3: Continued Pretraining with Contrastive Weak Supervision for Cross Language Ad-Hoc Retrieval" that I collaborated with @srnair04@cramraj8 Rebecca Iglesias-Flores and @ApolloProf
https://t.co/62ql5knzDs
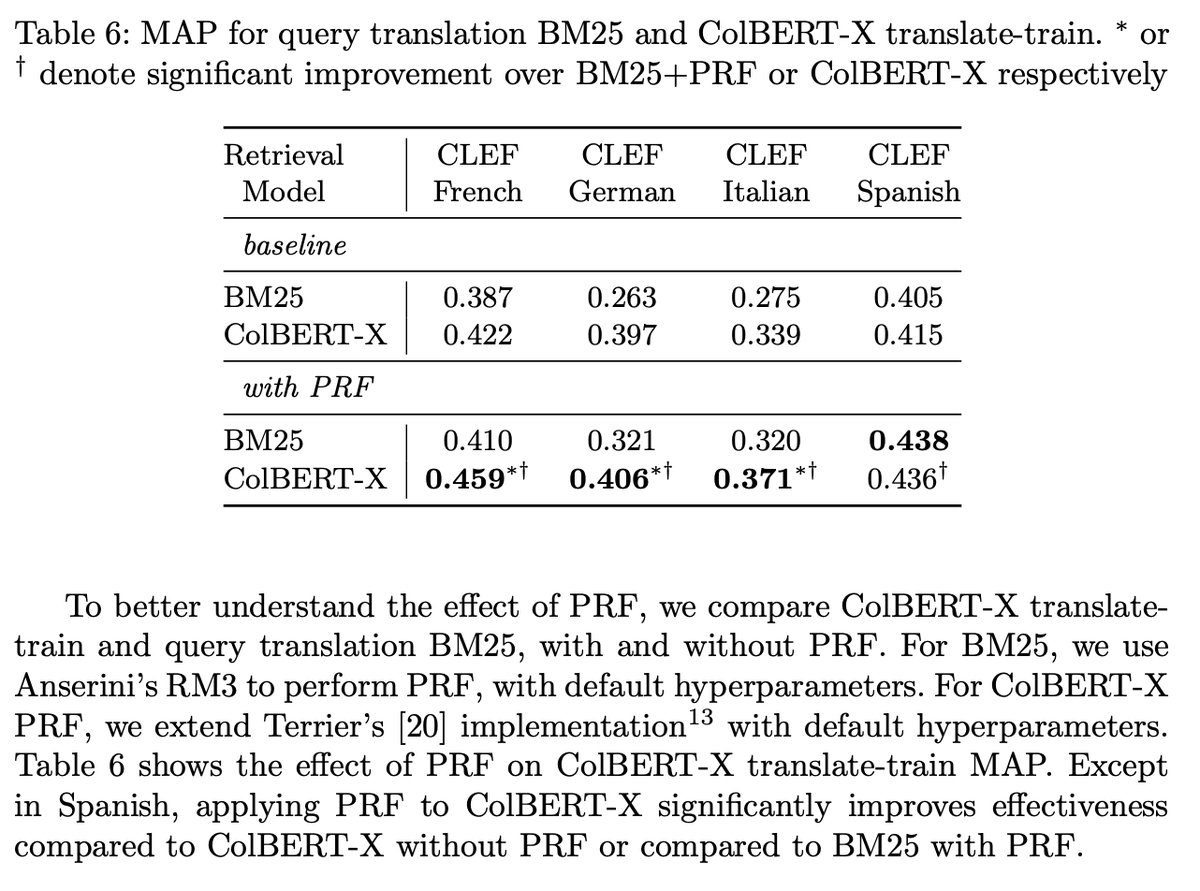
#ecir2022 paper (Transfer Learning Approaches for Building Cross-Language Dense Retrieval Models) by @srnair04 showing that our ColBERT-PRF approach (ICTIR 2021) works on a variety of languages
Happy to share that our paper entitled "C3: Continued Pretraining with Contrastive Weak Supervision
for Cross-Language Ad-Hoc Retrieval" (w/ @srnair04@cramraj8@tensorglow and @ApolloProf) at @SIGIRConf! Preprint coming shortly :)
@thibault_formal@cadurosar@sclincha@bpiwowar Thanks @thibault_formal and co. Just so you know, there is a weird issue with the training data. Some of the mined negatives include relevant passage ids. Here’s the associated Github issue: https://t.co/3Qv3flsLug
I am part of the organizing team of NeuCLIR track at TREC next year with Dawn Lawrie, James Mayfield, @macavaney, @soldni, @ApolloProf and Paul McNamee! Join us at one of the planning sessions on Dec 14 at 900 EST and 2100 EST to learn more about it and provide feedback.
@jobergum@luizhbonifacio@rodrigfnogueira Indexing sentencepiece tokens only might not be effective as shown in this paper: https://t.co/9rIvvwfW9s
However, in the past, character n-gram tokenization has been shown to be effective for retrieval in European languages.
https://t.co/l1sbMhM5yG
Check out our #ACL2021NLP paper "Cross-language Sentence Selection via Data Augmentation and Rationale Training" in Session 11D at 12-1pm (EDT) Tuesday Aug 3, 2021!
We present an effective approach for cross-language sentence retrieval in low-resource settings.
Working on narrative extraction, storyline and timeline generation, temporal reasoning, detection, and removal of bias in generated stories? Consider submitting to the 4th Text2Story Workshop [https://t.co/H6YnpbGjAz]
Submission deadline: February 8th, 2021
#ECIR2021@2021Ecir
@TomKenter Maybe this paper: https://t.co/0xxRUMLrOO
The idea is to
- split the document into overlapping segments
- apply BERT on each segment
- concat the segment representation which is then fed to LSTM/Transformer