We now have state-of-the-art pre-trained base models in the 3T-parameter weight class, built entirely in-house at MAI.
Post-training results coming soon -- stay tuned!
Lots of details in our technical blog post.
https://t.co/xcZ5uV4TAp
MAI-Thinking-1: A powerful reasoning model developed from scratch that is competitive with models of similar size on STEM reasoning and coding tasks.
Our pre-training focused on a simple scaling emphasizing data-driven iterative improvements to our architecture and data. Our reinforcement learning (RL) framework is optimized for sustained log-linear climbs over many thousands of steps
We are openly sharing all technical details and learnings to build a transparent and science-driven approach to further development in AI
Read More: https://t.co/yK9Cd5loUd
Super excited to announce seven new world-class MAI models today. They represent what we consider a new era in AI designed to keep you in control and on the frontier.
First is our text foundation model, MAI-Thinking-1, exceptionally strong on reasoning and SWE tasks.
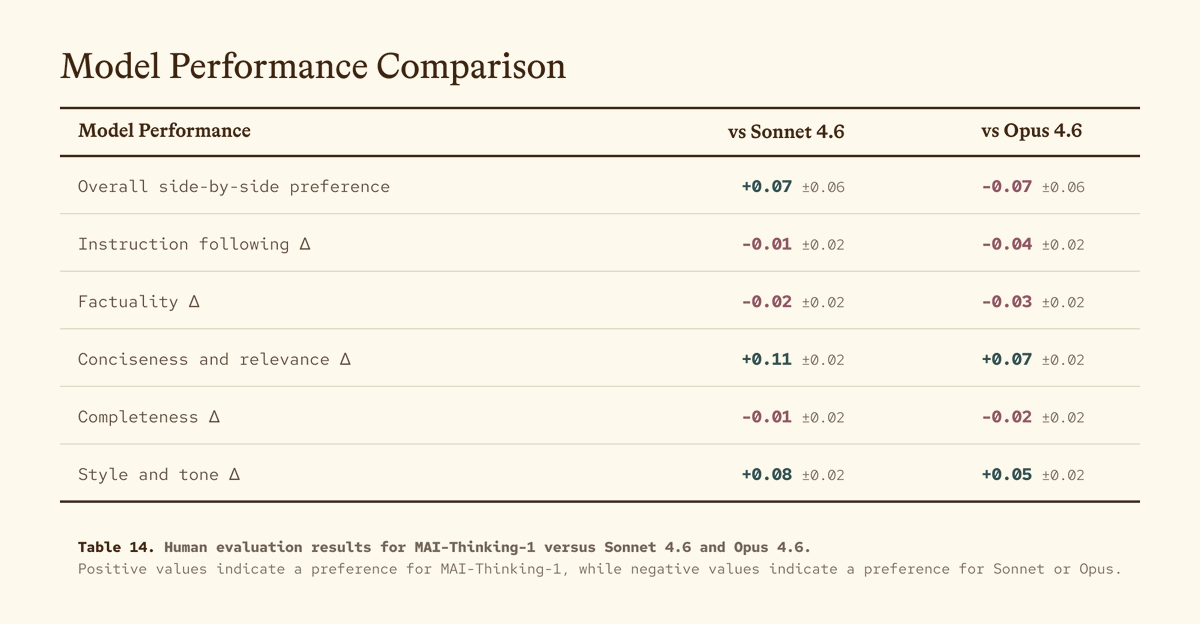
- It’s a 35B active parameter MoE with a 256K context window. Independent human raters on Surge prefer it for overall quality in blind side-by-sides versus Sonnet 4.6, and it’s achieved 97% on AIME 2025, the key measure of its general-purpose reasoning abilities.
- It's at 53% on SWE Bench Pro, placing it right alongside Opus 4.6 on one of the toughest coding benchmarks.
- And since we co-designed our models with our own silicon, MAI-Thinking-1 is optimized on our MAIA 200 chip. Benchmarking head-to-head against the GB200, we see 30% better performance per dollar as well as a 1.4x performance-per-watt gain when running our MAI models on the MAIA 200 end-to-end.
Next is MAI-Image-2.5 and its Flash variant. Two super strong models now at #2 on the leaderboards, surpassing the score of Nano Banana 2 on image editing.
Last for now is MAI-Code-1-Flash, our new inference efficient coding model, especially tuned for VS Code and GitHub Copilot CLI.
- Code-1-Flash achieves 51% on SWE Bench Pro, despite having just 5B parameters, putting it closer to Haiku in size but cheaper in cost.
All of this is the foundation for Microsoft Frontier Tuning. It lets you customize our models to create custom, company-specific agents that only you control. You can make our model, your model. Your data. Your agents. Your moat.
Early adopters are already seeing a difference. When we tuned our models for McKinsey’s tasks, MAI delivered the highest win rate, outperforming GPT-5.5 on quality, while being 10x lower on cost.
Also really excited to be collaborating with the amazing team at Mayo Clinic to jointly train a new frontier AI model for healthcare.
Our announcements today mark another milestone on the road to humanist superintelligence. You can learn more and about our other new models in our latest blog: https://t.co/v65eop5Ixq
We @neosigmaai@RitvikKapila are building the future of self-improving AI systems! By closing the feedback loop between production data and system improvements, we help teams capture failures, convert them into structured evaluation signals, and use them to drive continuous improvements in agent behavior.
We show how our system works on Tau3 bench across retail, telecom, and airline domains. Agent performance on the validation set (with a fixed underlying model, GPT5.4) improves from 0.56 → 0.78 (~40% jump in accuracy).
The OSS coding model that @ashVaswani and team at @essential_ai have been working on over the last year is now out and available to use on @togethercompute APIs and playground.
It's particularly exciting that @essential_ai is doing fundamental work in pre-training and post training and publishing open weights!
https://t.co/mTKOV49jOz
https://t.co/di9a968ZLN
📢 New Model Drop: Rnj-1 Instruct is now live on Yupp!
The first flagship model from @essential_ai, this open-source model is built to excel at math problem-solving and scientific reasoning.
We checked it out with some prompts:
Today, we’re excited to introduce Rnj-1, @essential_ai's first open model; a world-class 8B base + instruct pair, built with scientific rigor, intentional design, and a belief that the advancement and equitable distribution of AI depend on building in the open.
We bring American open-source at par with the best in the world.
Super proud to finally share Rnj-1 with the world!
It took a ton of work (and a lot of fun) to build, and I’m incredibly excited for everyone to try it out.
I’m confident Rnj-1 won’t disappoint :)
We are beyond thrilled to share our first flagship models, Rnj-1 base and instruct 8B parameter models. Rnj-1 is the culmination of 10 months of hard work by a phenomenal team, dedicated to advancing American SOTA OSS AI.
Lots of wins with Rnj-1.
1. SWE bench performance close to GPT 4o.
2. Tool use outperforming all comparable open source models.
3. Mathematical reasoning (AIME’25) nearly at par with GPT OSS MoE 20B.
….
Check out our latest research on data. We're releasing 24T tokens of richly labelled web data. We found it very useful for our internal data curation efforts.
Excited to see what you build using Essential-Web v1.0!
Excited to share our work at Essential!
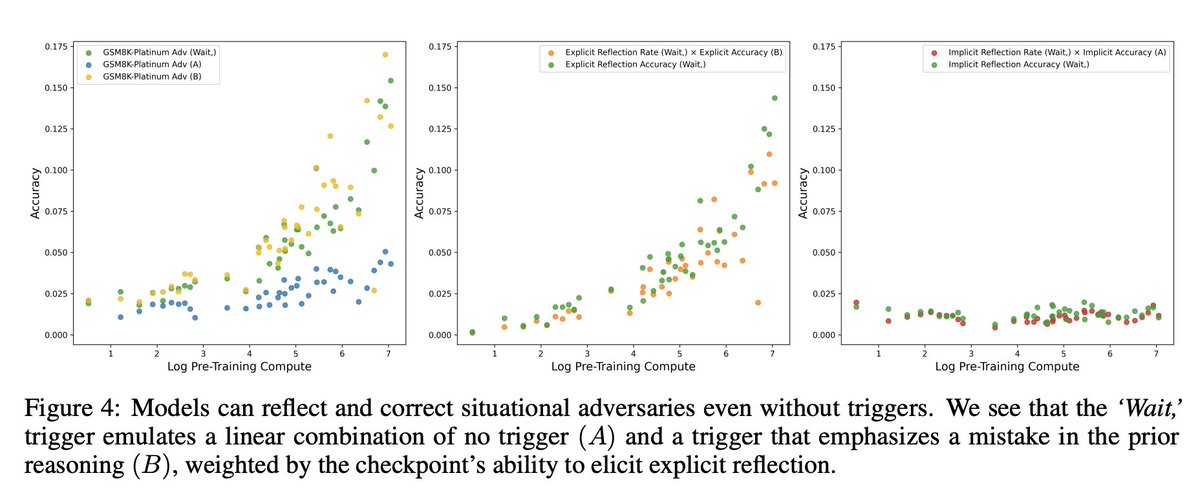
While most recent research has focused on how reflection develops during reinforcement learning.
We show that it actually begins to emerge much earlier — during model’s pre-training!
Reinforcement learning has shown success in eliciting reflection from LLMs, but what if this capability actually manifests earlier in pre-training? We investigated this question and our results are surprising 👇
[1/4]