🚀 A Japanese startup open-sourced a voice AI that can listen while it talks.
And you can run it locally on an NVIDIA GPU with roughly 12GB VRAM!
It hit #1 on Hugging Face’s trending models list across all categories!
This is Haru-4B from higurashi AI (@HigurashiAI).
Unlike traditional voice assistants that wait until you to stop talking before responding, Haru is designed for full-duplex conversations.
That means it can do the following ...
🎙️ Listen while speaking
🗣️ Handle interruptions
💬 Generate overlapping speech
👂 Give conversational acknowledgments
🌎 Converse across 9 primary languages
Here is the performance ...
On an Apple M1 Max MacBook, the developers report ...
⚡ 65.2ms median processing latency
🎵 One audio frame every 133ms
🚀 Custom Metal inference kernels
The architecture is based on Qwen3.5-4B, with additional audio components.
And look at the training!
🧠 40M+ hours of real speech
🗣️ 13M+ hours of full-duplex dialogue
🌍 Training speech spanning 160+ languages
Here are the local AI requirements
💻 NVIDIA GPU → ~12GB VRAM
🍎 Apple Silicon → native MLX implementation
⚙️ GPU serving → vLLM-Omni
🔓 Apache 2.0 weights AND inference code
📦 ~10.5GB BF16 checkpoint
It even supports custom characters and voices using reference audio.
Video Source: @HigurashiAI
I came across this video of Rajgir in Bihar & was intrigued.
I vaguely knew of Rajgir, but had never really thought of it as a tourist destination.
So I decided to read up a little more about it.
It turned out to be a rewarding exploration.
Rajgir was the capital of Magadha over 2,500 years ago. The Buddha and Mahavira both spent time here. The city was once surrounded by a massive stone wall, almost 40 kilometres long, built without mortar.
Today, it has a spectacular glass skywalk, ropeways, forested hills and ancient monuments.
But my reading led me to think more broadly about Bihar itself.
Bodh Gaya, where the Buddha attained enlightenment. Nalanda, one of the ancient world’s greatest centres of learning. Vaishali, associated with one of the earliest republican systems of government. And Pataliputra, capital of Ashoka’s Mauryan Empire.
An incredible concentration of history and heritage in one state
And yet, outside its important pilgrimage circuits, Bihar seems to receive relatively little attention as a tourist destination.
I can’t help feeling that Bihar is sitting on a tourism gold mine.
All this reflection prompted by one video of Rajgir. A reminder of how much there still is to explore in our own country…
#SundayWanderer
We invented a recursive megakernel generator called Hyperkernel, the most complete solution to megakernels and GPU efficiency.
Hyperkernel-generated megakernels achieve state of the art performance on 11 different domains: inference (DeepSeek, Kimi and GLM), pretraining (Qwen), hardware fault recovery, robotics (π₀-FAST, ACT) diffusion and real time world models (Matrix-Game), full self driving (OpenPilot), voice models (Moshi), genomics (Evo 2) and protein folding (ESMFold).
All of this in a single kernel launch.
For context, Hyperkernel generated fully optimized megakernels for robotics, genomics and voice in under 50 minutes, and doubled the efficiency for >5 models generally using only about 60-100 lines of code per megakernel. This speaks to the unparalleled standard for code quality in the automated generations.
Our first release today open sources the megakernels themselves. Over the next couple weeks, we will release the entire Hyperkernel stack, along with the complete serving stack for Kimi and GLM (20-30% inference efficiency gains across all concurrencies).
Out of the box GPU machinery performs terribly for unorthodox research. We built Hyperkernel only 20 days ago for internal use; but given its multi-modality, we have decided to open source it.
Creative research should not be bottlenecked by the lack of dedicated infra teams. Hyperkernels offer a one stop shop infra stack for all research. We would love for the open source community to add to it :)
GitHub repo: https://t.co/sfPt4S4BJN
NOTE: We primarily use NVIDIA B300s, but our kernel generation extends to other hardware (B200s, AMD, TPUs).
1/9
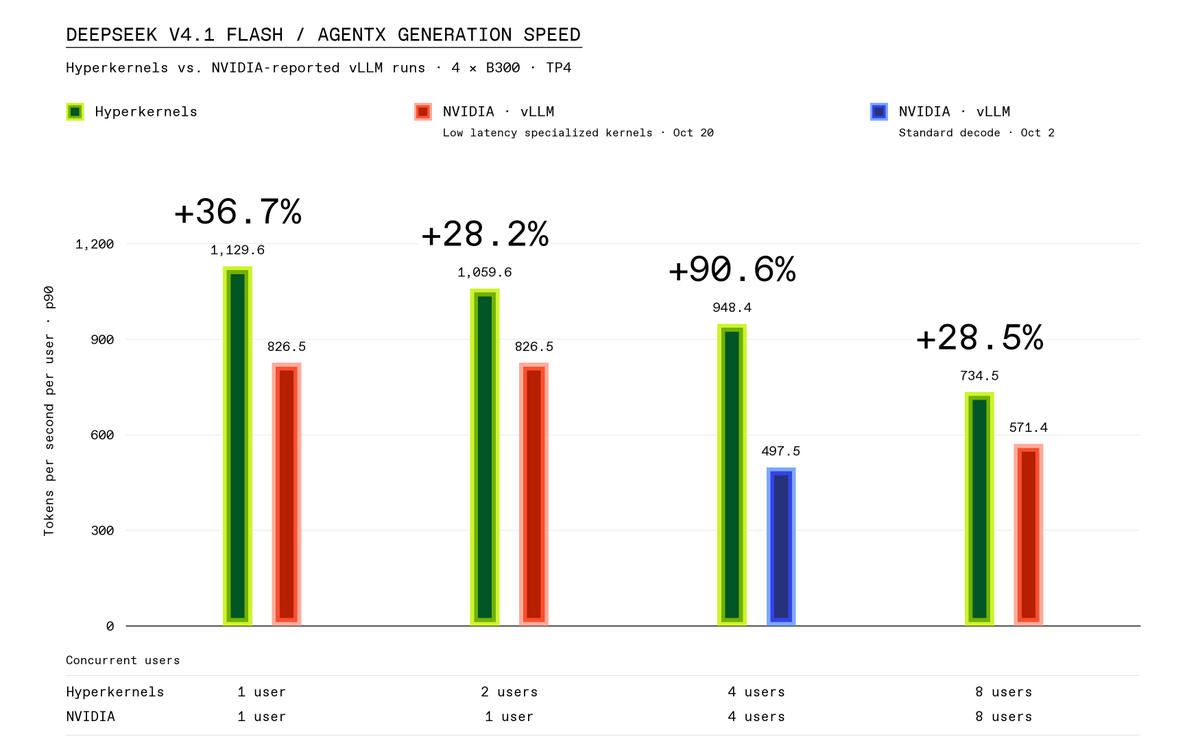
We absolutely crush NVIDIA and achieve the best low latency inference for DeepSeek v4.1 Flash.
Compared with NVIDIA’s published vLLM results, Hyperkernel delivers:
• 36.7% higher per-user generation speed at concurrency 1.
• 28.2% higher per-user speed while serving two users, versus NVIDIA serving one.
• 15% higher per user speed while serving four users, versus NVIDIA serving one.
• 90.6% higher per-user generation speed at concurrency 4, compared with the highest published C4 AgentX interactivity for TP4 B300s.
• 28.5% higher per-user generation speed at concurrency 8, compared with NVIDIA's published result.
• 36% faster median per-request decode speed.
पीयूष गोयल के मुताबिक, भारत में कोई आपको शाम के 5 बजे काम बंद करने के लिए नहीं कहेगा। लेकिन सवाल है क्या हमारी पहचान सिर्फ लंबे काम के घंटों से होगी, या युवाओं की गरिमा और अधिकारों से भी?
#PiyushGoyal#WorkCulture#LabourRights
Learning LLM inference and came across this guide by @lamhot_ai that explained all the high level details of inference really well
Added some annotations in the guide for the important parts
Today, I'm launching https://t.co/5XKAsmIuam:
- The hands-on way to learn AI engineering: LLMs, RAG, agents, evals and inference.
- 50+ interactive labs. Tweak tokenizers, attention, embeddings and KV caches live.
- Train a neural network in your browser and watch it learn.
- Build agentic workflows with tool calls, memory, guardrails and bounded autonomy.
- Ship RAG that works: chunking, hybrid search, reranking, and LLM-as-a-judge evals.
- Production AI: model routing, fallbacks, quantization, caching and cost per request.
- 490+ interview questions, reported from OpenAI, Anthropic, Google, Meta, Amazon, Microsoft, Mistral and 50+ more.
- Every answer is cited from papers and books, or measured on real models.
24 जून 2024, धर्मेंद्र प्रधान जब लोकसभा में शपथ लेने आए तब नारा लगा था, नीट, नीट, शेम, शेम...अगर धर्मेंद्र प्रधान में तब भी जज़्बा होता तो पेपर लीक को जड़ से ख़त्म कर देते। दो साल बाद आज 24 जुलाई 2026 है। यह वीडियो इसलिए देखिए ताकि उन लोगों को आप जवाब दे सकें जो कह रहे हैं कि प्रधान के इस्तीफे से क्या होगा। क्योंकि प्रधान फेल रहे हैं। नीट की चोरी को लेकर विपक्ष ने ठीक एक साल एक महीना पहले याद दिला दिया था। कम से कम इन दो सालों में वे नहीं कर पाए। यह तो साबित होता है।
कई दिन हो गए, कोई विपक्षी दल नहीं तोड़ा गया है ताकि देश में दहशत पसर जाए कि अब क्या होगा, कोई बचेगा या नहीं। सरकार अगर युवाओं से संवाद करना चाहती है तो राघव चड्ढा को उनके बीच भेज दे, वे जेन ज़ी स्कूल ऑफ नायकत्व के प्रोडक्ट हैं। उन्हें मालूम होगा या उन 20 सांसदों की परेड करा दे जो जनता की नब्ज़ को सुपर फास्ट गति से समझते हुए तृणमूल छोड़ कर NCPI में शामिल हो गए। जिसे श्यामा प्रसाद मुखर्जी ने बनाया न अटल बिहारी वाजपेयी न संघ ने सुरेंद्र नाथ बनर्जी, मुलायम सिंह यादव या नीतीश कुमार ने। NCPI के संस्थापक का कम से कम एक इंटरव्यू तो छपना ही चाहिए कि अगर विपक्ष ने ज़ुबान बंद नहीं की तो 24 घंटे के भीतर राहुल गांधी और अखिलेश यादव को छोड़ कर उनसे सारे सांसद NCPI में होंगे।
यह मान लीजिए कि इस देश में दो चार कालेज यूनिवर्सिटी को छोड़ कर सब के सब इस तरह काम कर रहे हैं जैसे युवाओं को किसी लायक नहीं बनने देना है। किसी लायक बन जाएंगे तो वे धर्म की राजनीति को ठीक से समझ जाएंगे। विपक्ष से भी सवाल करने लग जाएंगे।
System Design Playbook
GIVEAWAY ALERT!!
• System design fundamentals.
• Condensed notes to read before system design interviews.
• Must know concepts from engineering case studies.
(24 hours only.)
If you want to get it for free:
1. Like, Retweet & Follow @systemdesignone
2. Reply "Playbook"
Then I'll DM you the details.
Assimilating my thoughts on interview rejections during tech job search games
context:
- I have made 8 switches in 15 years
- failed 100s of interview processes over the years
(0/n)
Imagine the disappointment after having invested a few hours in the interview process
most hours & emotions are invested in day-dreaming about the company/bragging rights etc. which starts right after interview gets scheduled
assignment/interviews come later
(1/n)
Thus when you are rejected, you also have to let go of the universes you had created in your head about all this
all those few days/weeks' dreams die once you get the rejection
it feels worse because of these emotions than because of the time you spent in the interviews
(2/n)
Eventually it is a judgement on how relevant you are to the market
you can't ignore the judgement
sometimes there's just someone better than you who got the job (often u can't know how)
you often dissect each part like a breakup:
"what I could have done differently"
(3/n)
You have some hypotheses
but you can't be sure
only if you had said this
only if you had done that
imposter syndrome knocks at the door
you are a fluke may be
(4/n)
If someone tells you "it doesn't matter" -
they can say so because they didn't go through the daydream / building hope part of the journey
read that again 👆
whatever you tell your conscious - your subconscious feels bad & it does spill it on other parts of life
(5/n)
People forget that for each logo you have on your resume there are 20 which told you "you aren't good enough" - that too after talking to you
likely no one is proud of failed interviews
same way we want to forget when a girl rejected us
feels similar
(6/n)
What helps in feeling better?
biggest:
having friends who can discuss details & share good hypotheses for rejection
basically saying:
you ain't alone in this
you need to actively create this circle because even family can't say anything beyond "hey it doesn't matter"
(7/n)
To a smaller extent :
noting down all learnings & advantages of the process like
- organic acquaintance with interviewers & other connections you made while preparing
- improvements identified in your skills
- increased knowledge on how market works
(8/n)
In summary I believe 3 things are useful :
1.
creating a friend circle of 6-10 folks who can relate to your interview experiences. Call them your interview-circle
relate this with intrinsic motivation models
(9/n)
2.
Repeating to yourself that you were better off trying via "The man in Arena" 👇
interpretation:
interviews mein reject hote hote toh kahin select ho hi jaayenge hum
gumraah toh woh hain jinhone interview diye hi nahin
iteration pain > sitting outside the play arena
(10/n)
3.
Realizing the following (if you can)
our neural nets are always learning from each interview they go through
our subconscious gets more aligned what the market wants with each such exposure on
- what to say
- how to approach
- what to focus on
so continue playing
with levity 🙃
(11/n)