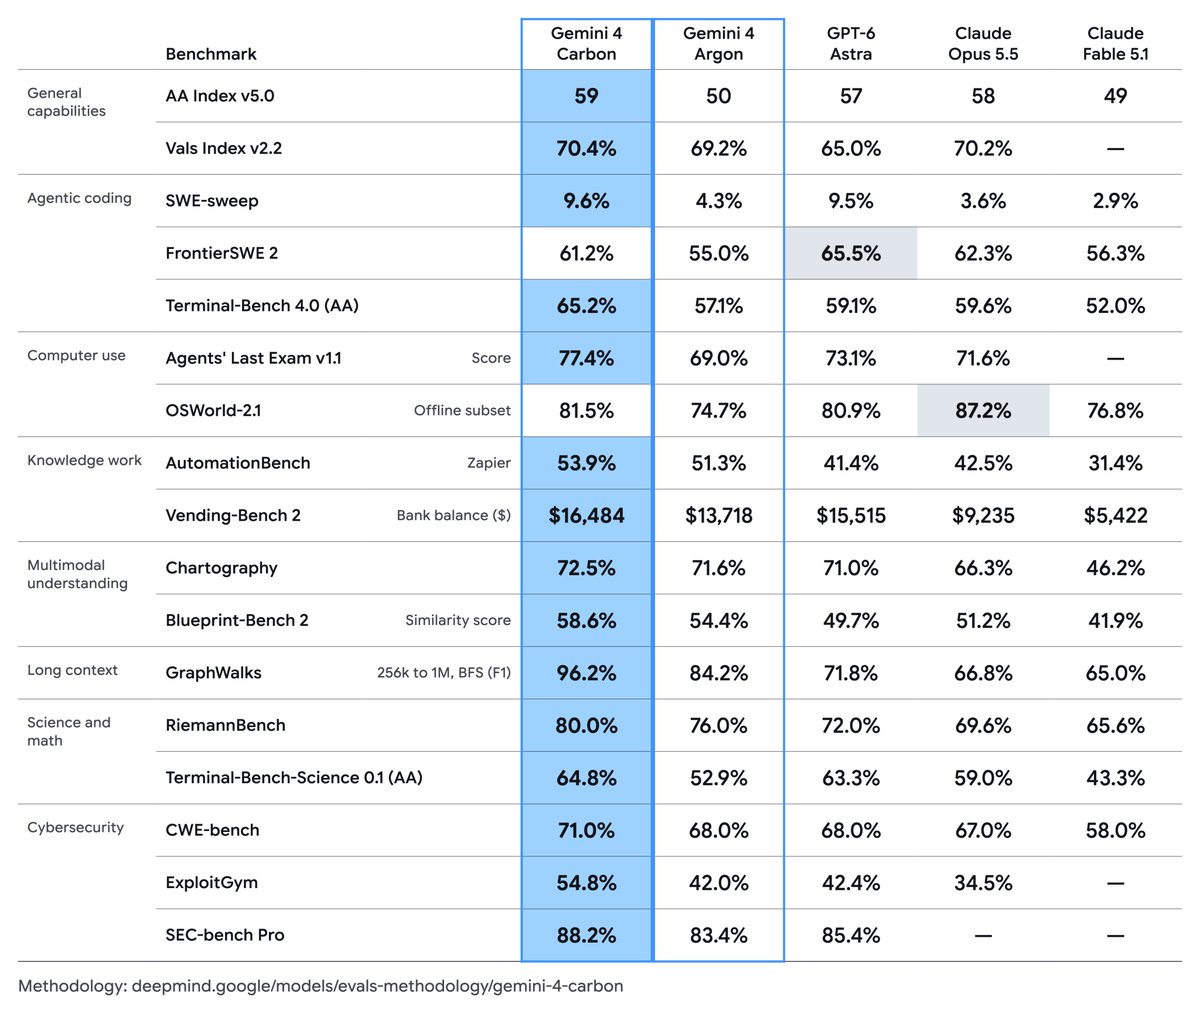
Proud of team’s contribution to Gemini 4 Carbon.
Especially happy to see SOTA on:
• Terminal-Bench 4.0: higher accuracy; cheating attempts down to 0.4%.
• Terminal-Bench-Science: 64.8%.
How the model gets the answer matters too.
https://t.co/ShQbTdFuj0
One of the most significant things about Gemini 4 Carbon is that it is showing that Google is back in the race of frontier models, rapid releases and rapid improvement.
One of the most significant things about Gemini 4 Carbon is that it is showing that Google is back in the race of frontier models, rapid releases and rapid improvement.
Today we’re launching Gemini 4 Hydrogen. It brings cutting-edge intelligence to everyone — with speed and efficiency for everyday coding and agentic workflows, rolling out across the Gemini API, Gemini for business, the @GeminiApp, Google Search, and for paid Google AI Pro and Ultra subscribers in Google @Antigravity.
In real-world software development, while teams rely on Carbon and Argon for deep architectural judgment, they also need fast, disciplined execution for writing code, running tests, and verifying changes — standalone or paired in multi-model workflows like Orchestrator in @Antigravity :
– Surpasses Argon on the Artificial Analysis Intelligence Index at its default thinking level (51 vs. 50, and reaching 54 at xhigh) while running 2.5x faster than 3.8 Flash & often faster than peers in its class ($1.50 / $7.50 per 1M tokens across 1M context)
– Reduces fabricated responses & claims by >5x
Proud of the teams across @GoogleDeepMind and @Google for shipping three Gemini 4 models in rapid succession.
Read more at:
https://t.co/THTtDvAyvy
We're super excited to launch MKA in partnership with @ArtificialAnlys.
Real-world work is messy and inherently visual. We kept finding existing benchmarks were either not visual enough or not agentic enough. MKA aims to fill this gap.
Gemini 4 Carbon is now available for users, developers and enterprises!
We are heavily using Carbon internally at Google for hardest long horizon tasks, our teams have used it to help mathematically prove the core cryptographic protocol of Signal — and it’s topping independent benchmarks like CursorBench 4.0, Perplexity’s WANDR, Zapier’s AutomationBench, and more.
The team also had fun using Carbon to analyze images and technical drawings from humanity’s first crewed lunar lander, the Apollo Lunar Module. Not a single flown component ever returned to Earth. It recreated the 3D asset from those historic documents and generated this walkthrough video.
Read more: https://t.co/PxfmrxDmwJ
Today we’re rolling out Gemini 4 Carbon, our strongest model with frontier performance in cybersecurity capabilities and long-horizon agentic workflows.
We’ve poured a lot of love into it, and it’s very good at working through hard problems.
Proud of team’s contribution to Gemini 4 Carbon.
Especially happy to see SOTA on:
• Terminal-Bench 4.0: higher accuracy; cheating attempts down to 0.4%.
• Terminal-Bench-Science: 64.8%.
How the model gets the answer matters too.
https://t.co/ShQbTdFuj0
@emollick I’d want to see which assumptions it’s using about me, and be able to correct them. Something I said last month shouldn’t quietly become a standing instruction.