We made AI code review 3.4x faster (7.4 → 2.2 min) and 50% cheaper, with precision up from ~73% to 94%.
The biggest lever wasn't a bigger model, which came last. Max reasoning cost 2.8x for zero gain. Cutting agent search turns did the work.
Teardown: https://t.co/wWY4iErQ5O
Every platform out there claims to provide data and visibility into your AI spend.
What about actually using all that data to directly optimize your agents?
Come by our booth tmrw at ELC and check out how we do it at @EntelligenceAI !
Introducing AgentPlay: a free, open-source way to replay your coding-agent sessions (Claude Code, Codex, Cursor), locally.
See what your agent read, where it failed, what it retried, as a map and a timeline.
https://t.co/UrcPqcdB7b
https://t.co/cCB5YD6wxk
Introducing AgentPlay 🚀
The future of coding is self improving coding agent harnesses that help agents avoid making the same mistakes over and over.
Turn your existing Claude Code, Codex, Cursor and Copilot sessions into interactive maps and replayable timelines.
See what your agent explored, where it failed, what it retried and how it reached the final change
Free, local and open source.
GitHub: https://t.co/QR9aGmRy1C
MIT Project NANDA reviewed 300+ AI initiatives and found 95% of GenAI pilots produce zero measurable P&L impact. McKinsey's 2025 survey of nearly 2,000 organizations confirms it: only 39% can point to any bottom-line impact from AI at all.
Nobody cares that you process 2B tokens.
That’s not a flex, it’s a bill.
Introducing @EntelligenceAI Agent Insights - Track not just dollars spent but actual ROI
We built Agent Insights to map AI spend straight to engineering outcomes: features, fixes, and PRs
Manage your budget based on actual company priorities
Cut your spend in half with the Entelligence model router
See what your AI spend actually shipped: https://t.co/nstKq790rM
Introducing @EntelligenceAI Model Router, dynamic turn based routing trained on engineering tasks that cuts costs by over 50%
Automatically route every coding turn to the model with the best balance of quality, latency, and cost.
Escalate to frontier models when they’re actually needed
Balanced mode reduces spend by 46% per session
Eco mode helps teams save > 76%
Proud of what the team built here. We threw GLM-5.2 and Claude Opus into a real coding shell with hidden tests to see if open-weights could handle true agentic workflows.
Exact capability parity, at less than half the cost. The data breakdown: 👇
we're growing our GTM team at @EntelligenceAI! SF, in person
Devrel: chief eng embassador for our platform. you code, build demos, write technical blogs and have experience building audiences
Founding GTM: own pipeline and revenue, zero to one, tell us your most out of the box growth hack to date
Community and Partnerships: run killer events, attend conferences
Links below 👇
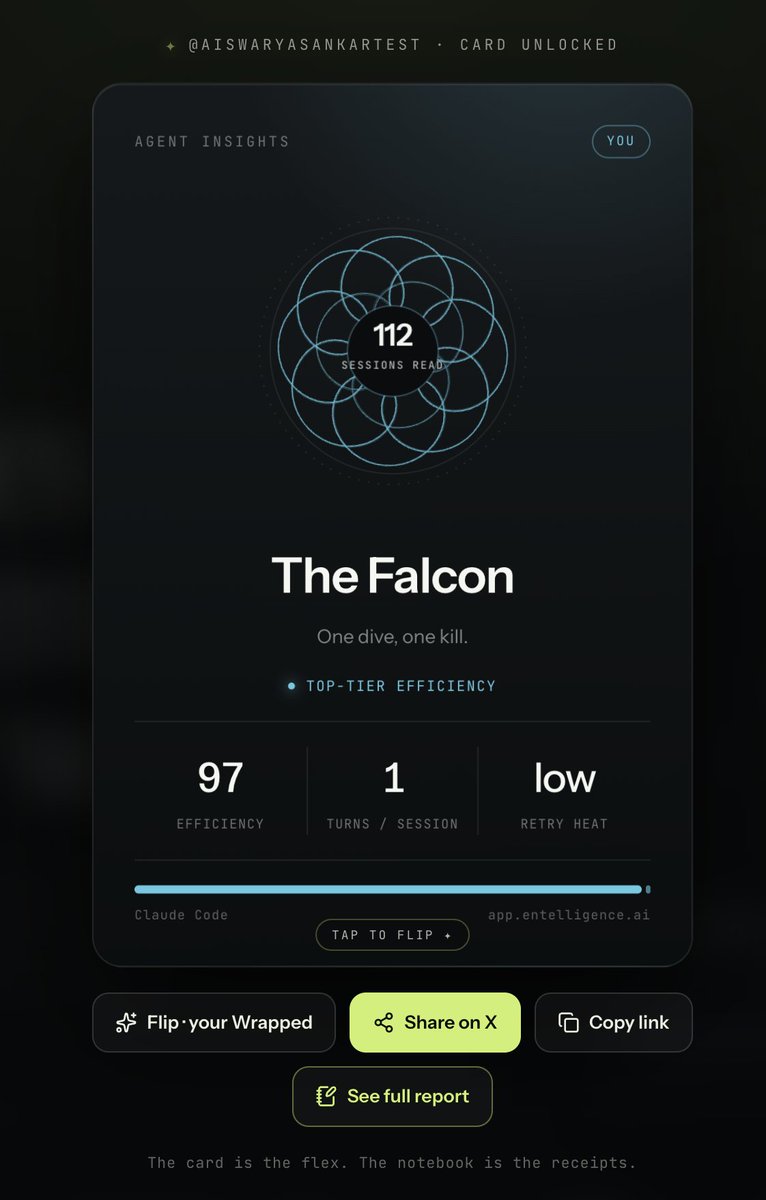
My coding agent Moves more tokens than the rest of the org combined. — which makes it "The Whale." Every agent has a type. What's yours? https://t.co/wscW8mjbwr
AI coding tools amplify what's already broken. If 1 in 4 lines is churn and 76% of work is reactive fixes, you're not shipping faster — you're failing faster.
Tokenmaxxing is throwing money down the drain
Analyzed 1M+ PRs over 2.4k companies and here are the stats:
- 1 in every 4 lines is code churn
- Only 21% of code review comments are addressed
- at the 90% percentile, 76% of work is reactive bug fixes
Full report below 👇
We @EntelligenceAI are cohosting an AI hack at UC Berkeley tmrw, and it's gonna be insane 🔥
build. ship. something real. 4hrs
🏛️ soda hall | sat, may 9 | 2:30 pm
👥 teams of 1–4
🏆 judges: @GoogleDeepMind@EntelligenceAI@Amazon & Butterai
https://t.co/DmrRqkKm17
Over 250 people have signed up so far!
Come participate in the "Production reliability agents" track - building agents to automatically track, triage and fix your peers vibe coded projects :)
Deep Barot and the entire @ContextQa team are building some of the most advanced end to end QA agents for web testing.
It's been super exciting to partner with them over the last year and expand with them from around 5 eng to over 30 today! Excited to have you on Deep!
Customers pinging you with "people are already impressed by its ability to ..." as soon as you leave a meeting 👌
Walked past their office everyday on the way to work, great to have em onboard now!
We're constantly chipping away at our end goal of ensuring teams never have to look at production logs or issues at all.
Great to chat with @vikchuppala CTO of Clodo on our milestones towards that goal and how they've been leveraging @EntelligenceAI so far!
We just ranked every major AI code reviewer
🥇 @EntelligenceAI: 47.2%
🥈 Codex: 45.4%
🥉 Claude Code: 42.8%
4. Bugbot: 39.4%
5. Greptile: 36.9%
6. CodeRabbit: 33.0%
7. Copilot: 22.6%
8. Graphite: 13.4%
Codebase with comments are fully open source and linked in the report below 👇
We just ranked every major AI code reviewer
🥇 @EntelligenceAI: 47.2%
🥈 Codex: 45.4%
🥉 Claude Code: 42.8%
4. Bugbot: 39.4%
5. Greptile: 36.9%
6. CodeRabbit: 33.0%
7. Copilot: 22.6%
8. Graphite: 13.4%
Codebase with comments are fully open source and linked in the report below 👇