🟡 STILL A BILL
NO FAKES Act: federal right over your voice + likeness, 70 years. White House endorsed it by name. SAG-AFTRA, Google, OpenAI, Disney all backing it.
Still in Senate Judiciary Committee.
The EO is real. The law is real. The Framework is a wish list. The NO FAKES Act is a bet. Know which is which.
🔵 POLICY MEMO (not law)
The March 2026 White House Framework is a recommendation to Congress — not a regulation.
Key position: no new AI agency. Route everything through FTC, SEC, FDA, DOE. Congress hasn't acted.
⚡ What breaks your code:
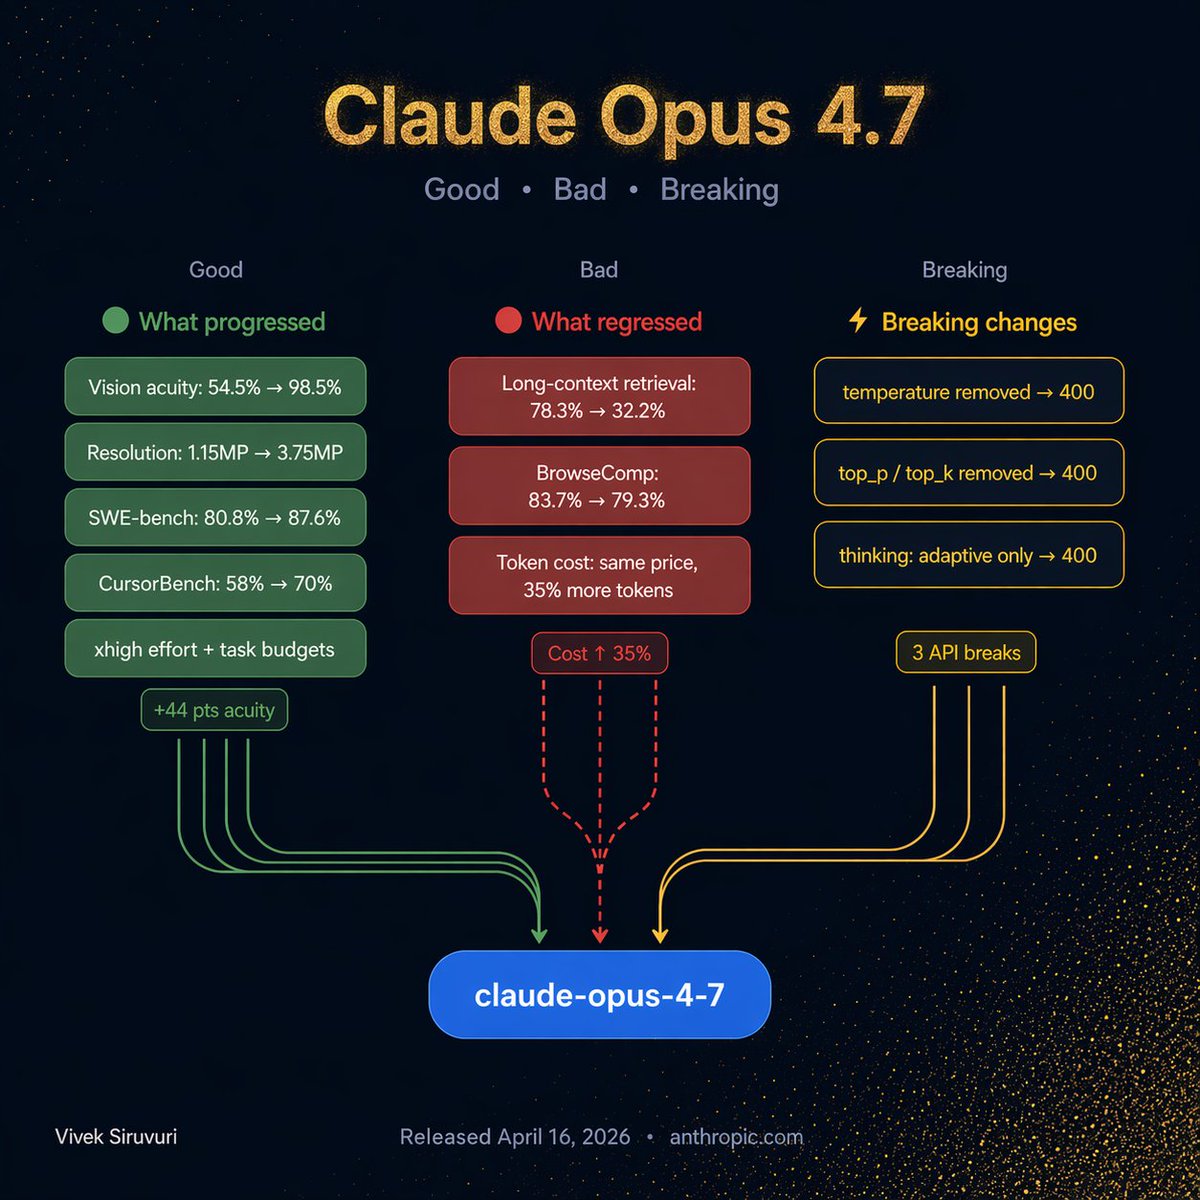
→ temperature / top_p / top_k — removed entirely, 400 if you pass them
→ Extended thinking — only "adaptive" mode supported now, "enabled" + budget_tokens = 400
Check your API calls before you deploy.
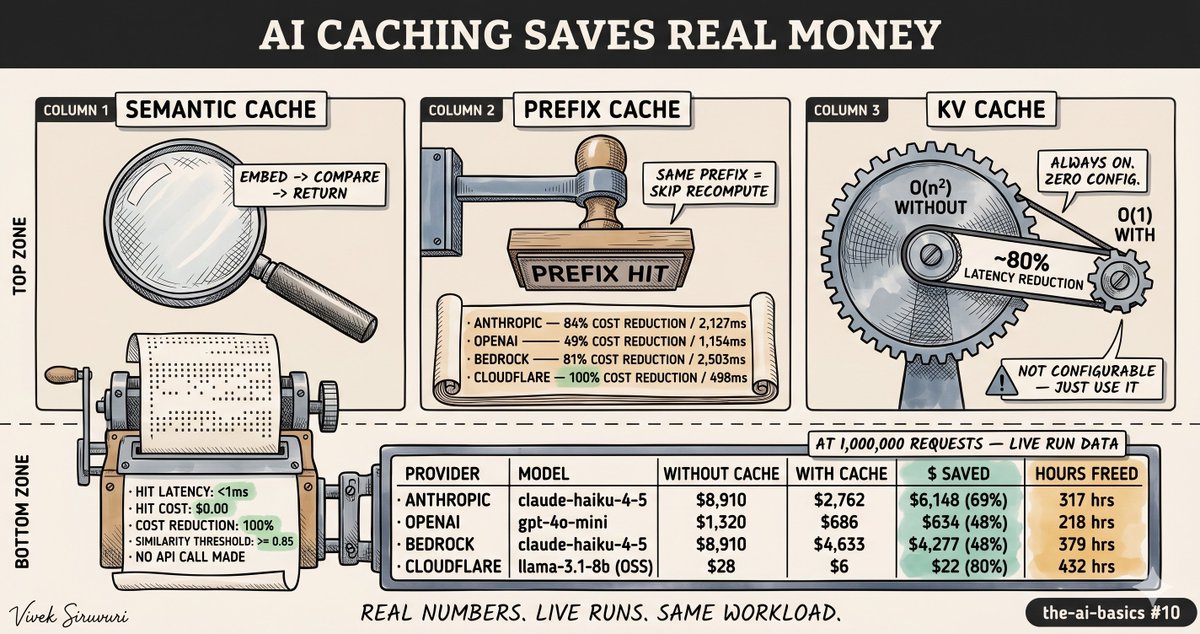
* Cloudflare Workers AI = open-source models (Llama). Dollar figures aren’t capability-comparable to Claude or GPT-4o-mini.
But: Cloudflare AI Gateway can proxy Anthropic/OpenAI calls and cache those too. They’re not alternatives — they stack.
Full repo with all 4 demos:
https://t.co/pAPAl3dBsh
⏱️ The surprising finding — hours freed at 1M requests:
Cloudflare: 432 hrs
Bedrock: 379 hrs
Anthropic: 317 hrs
OpenAI: 218 hrs
Cloudflare wins on time saved — not because of the model, but because gateway hits return in 498ms vs 2,100–2,500ms for the others.
Stack semantic → prefix → KV. They're a cascade, not alternatives.
Next: same stack, 4 providers, real API calls, real costs.
At 1M requests — one provider saved 432 hours of compute time.
It's not who you'd expect.
Numbers and stats dropping soon.
🗄️ Semantic Cache — intercepts before any API call is made
"Recommend a thriller" ≈ "suggest a suspenseful film"
Cosine similarity: 0.86 → return cached response
Cost: $0.00
Latency: <1ms vs 2,845ms baseline
No model called. No tokens spent.