Exciting update: Kimi K3 has landed at #4 on the Agent Arena leaderboard, matching Claude Opus 4.8 and GPT-5.6 Sol. If Kimi K3's weights are released on schedule by July 27, it will become the #1 open-weight model.
This release marks a major leap in agentic performance over Kimi K2.7 Code (#23 to #4). Based on 8K+ live agentic sessions, Kimi K3 leads on confirmed task success rate (#1). It also posts a strong +20.6% on praise vs. complaint (#3). It currently lags the field in steerability (#14) and bash recovery (#17).
Agent Arena measures models on millions of real-world, long-horizon agentic tasks. Models get web search, filesystem, and terminal tools to complete complex workflows: writing code, creating slide decks, researching the web, building apps, and analyzing documents.
We use causal tracing methodology to measure a model's net improvement, which indicates how much it improves outcomes relative to the average model.
Here's a primer on the 5 signals:
User-satisfaction proxies
- Confirmed Success: an explicit "yes that worked" feedback from the user
- Praise vs. Complaint: implicit sentiment in users reactions
- Steerability: can the model course-correct when you push back?
Tool-use proxies
- Bash Recovery: how it recovers from CLI errors (primary signal for tool use)
- Tool Hallucination: does it call tools that don't exist
Below we break down how Kimi K3 scored across the 5 signals, drawn from tasks submitted by a global community of users.
Congrats @Kimi_Moonshot on another big milestone!
I found the OCR tool built for the LLM era.
It is called olmOCR.
olmOCR takes PDFs, scans, PNGs, and JPEGs and turns them into clean Markdown that models can actually understand.
It handles the stuff that normally breaks document pipelines:
→ Tables
→ Equations
→ Handwriting
→ Multi-column layouts
→ Figures
→ Insets
→ Old scans
→ Headers and footers
→ Natural reading order
So instead of feeding your AI a messy PDF dump, you give it structured Markdown that preserves how the document was meant to be read.
This matters because so much of the world’s knowledge is still trapped inside PDFs.
Research papers.
Legal filings.
Financial reports.
Medical documents.
Scanned archives.
Government docs.
Internal company knowledge.
Everyone is building RAG on top of documents.
But if your OCR is bad, your AI is already wrong before retrieval even starts.
olmOCR fixes the first mile.
The boring layer.
The layer nobody talks about until their agent starts hallucinating from broken PDF text.
https://t.co/H1pdZny6SK
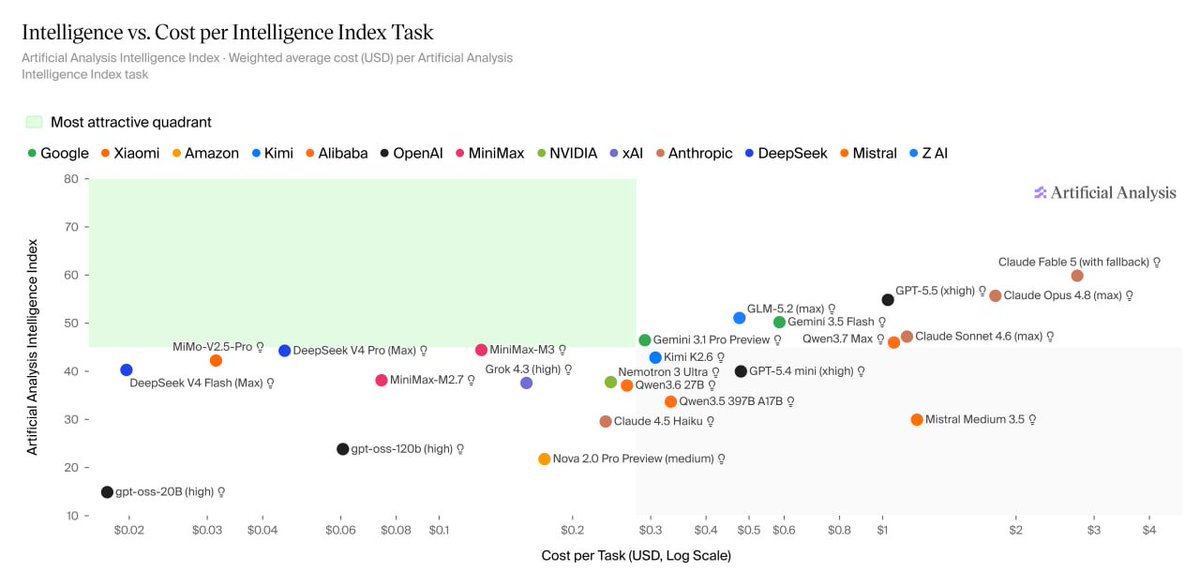
My entire AI stack is now Chinese 🇨🇳
87% cheaper. same revenue
swaps by task:
1. reasoning / backend brain
Opus 4.8 → Kimi K2.7
benchmark gap: ~8% · price: ~11x cheaper
2. code generation
GPT-5.5 → Qwen 3.7 Max
benchmark gap: ~18% · price: ~7x cheaper
3. agent loops + tool calling
Sonnet 4.7 → GLM 5.2
benchmark gap: ~3% · price: ~5x cheaper on input
4. cheap volume / bulk processing
GPT-5.5 mini → MiMo V2.5
benchmark gap: ~6% · price: ~12x cheaper
5. image generation
GPT-Image-2 → Wan 2.5
benchmark gap: ~5% · price: ~8x cheaper
6. video generation
Sora 2 → Kling 3.0
benchmark gap: roughly equal · price: ~6x cheaper
[ result after 30 days: ]
operating costs dropped 87%, output quality dropped 4% on average, revenue unchanged
the most important that these models will be not banned in a month and i can run them locally
nobody will steal my data and i can learn them as i need
full article drops tomorrow with:
> exact routing logic per task type
> the 2 cases where I still pay for American
> the migration playbook anyone can copy in a weekend
VERY IMPORTANT to get migrated now, while it's not too late
Много вопросом как подключить к Claude Code, а все очень просто. Китайцы сами написали инструкцию. Да, я тоже не знал, что так можно:
https://t.co/OQTrW1cLnb