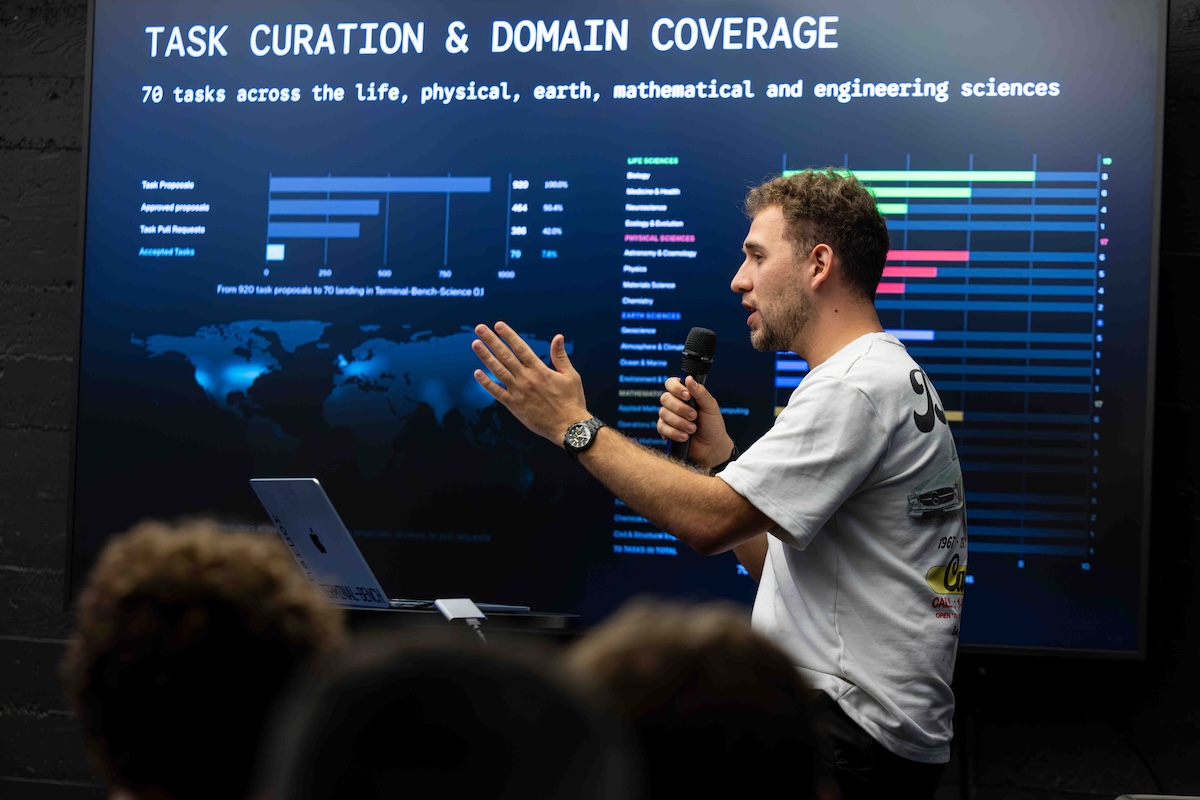
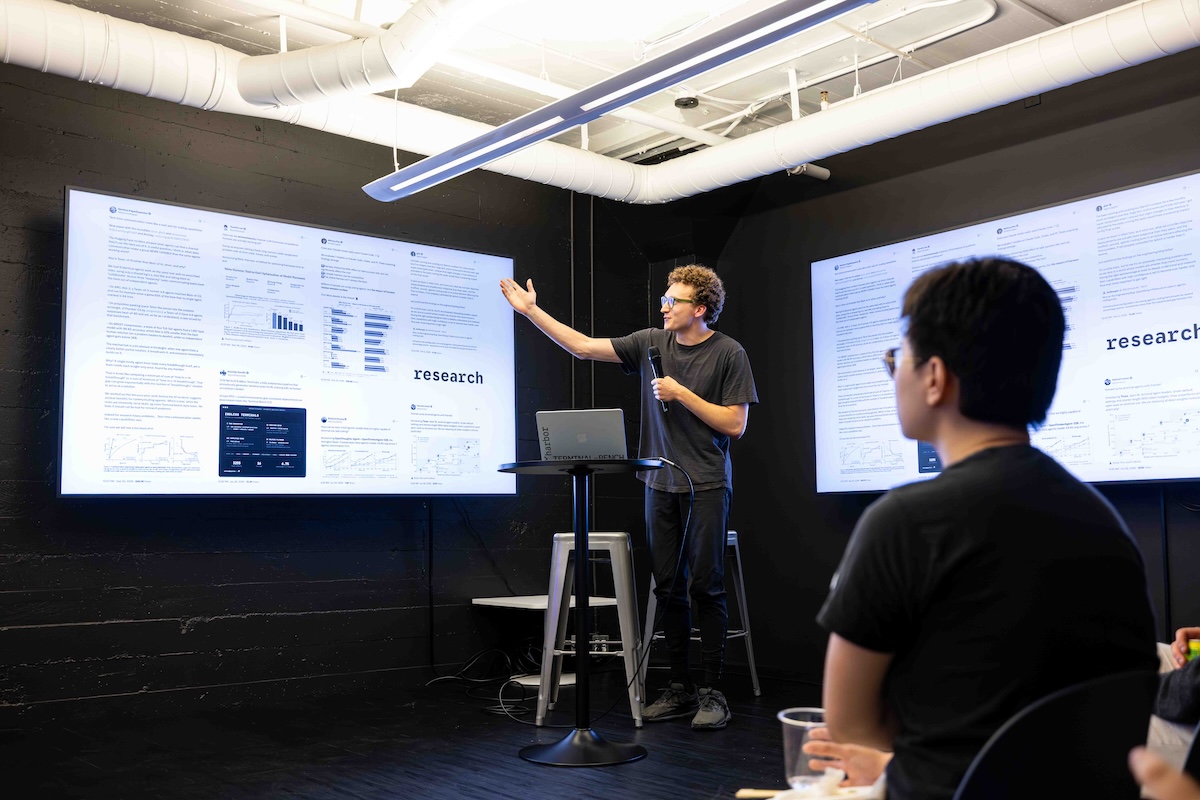
With hundreds of contributors and thousands of participants on Discord and GitHub, the @terminalbench team ships frequent updates in the open so everyone can learn alongside them. And with @harborframework, they've built the infrastructure for anyone to benchmark the use cases they care about.
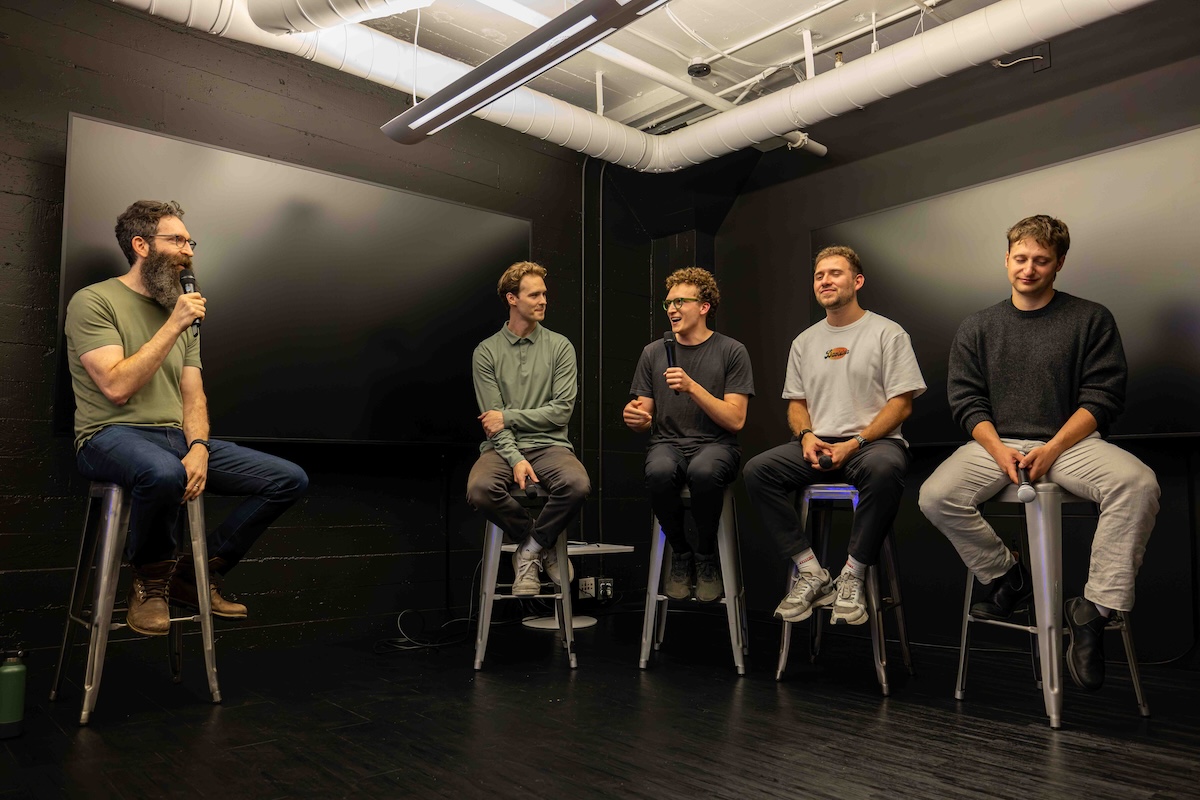
Great to host the community at Laude Lab last week and hear what's coming next!
@alexgshaw@ryan_marten@StevenDillmann@Mike_A_Merrill@andykonwinski
Before their first release, the @terminalbench team called off a task-writing meetup, figuring there was no way to get more than ten people in a room to talk about the project. Tonight we squeezed ~150 into Laude Lab!
The team covered the state of the bench and @harborframework, the process behind Terminal-Bench-Science, and how to keep pace as models get better, faster: continuous benchmarks, real-world evals, and long-horizon multi-agent challenges.
@alexgshaw@ryan_marten@StevenDillmann@Mike_A_Merrill@andykonwinski
Terminal-Bench meetup tonight *with* swag. Register if you haven’t already! Benchmarks, RL environments, new features, and state of the union
https://t.co/g9QbDuBWB2
fast track to get model labs to care about the capabilities you care about:
contribute a task to Terminal-Bench
if you have built a benchmark around a specific use case, DM me and we can collaborate on a TB task for the next release
We're hosting a meetup!
Come meet the community behind the benchmark, celebrate recent releases, and join our discussions about the future of agent evaluation.
https://t.co/9m6J7a1YcP
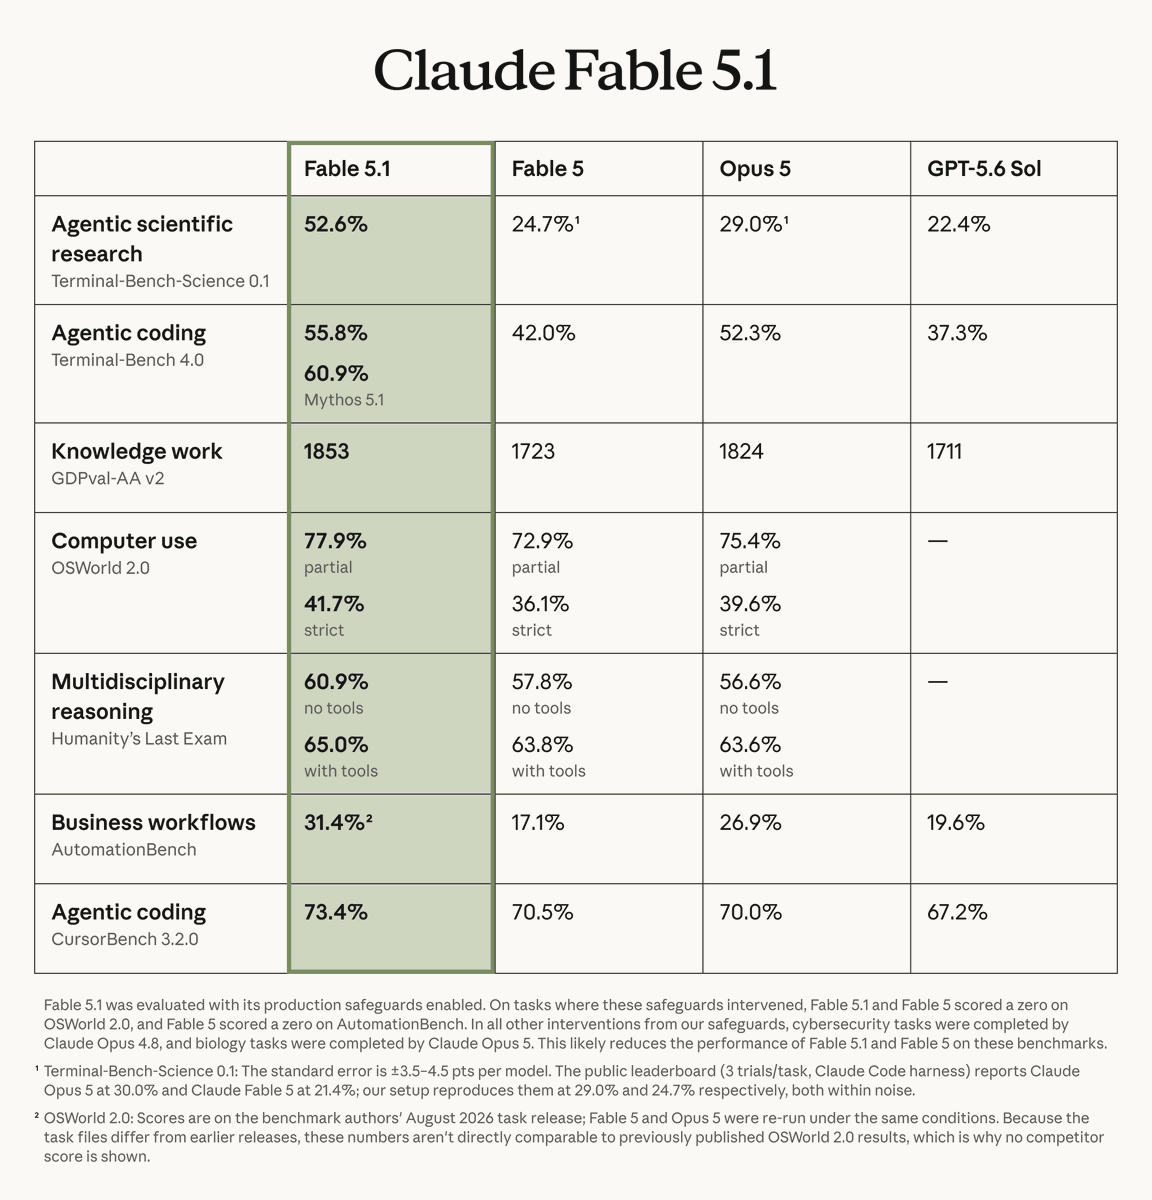
Across our benchmarks, the model sets a new standard.
It scores 52.6% on Terminal-Bench-Science 0.1, more than double Fable 5. On Terminal-Bench 4.0, it scores 55.8% against 42.0% for Fable 5.
We've pushed a version update to the Terminal-Bench dataset and leaderboard.
Terminal-Bench 4.0 calibrates task resources (time, cpu, memory), implements task fixes, and removes saturated tasks.
We're releasing Terminal-Bench-Science: a benchmark for evaluating AI agents on research workflows across scientific domains.
An ongoing Stanford-led community effort, built by the team behind Terminal-Bench together with scientific domain experts at research institutions worldwide. v0.1 has 70 tasks. Claude Opus 5 solves only ~30%.
1/n 👇
Congrats to https://t.co/lak9wascUr for the strong performance on Terminal-Bench 3.0!
One of the biggest pieces of feedback we have gotten for TB3 is to increase the timeouts. We calibrated timeouts against frontier models during development, but inference speed can still be a confounder on some of the tasks.
Terminal-Bench numbers on the GLM-5.3 model card are reported with increased timeouts (likely for this reason).
Look out for Terminal-Bench 4.0 releasing soon with increased timeouts, other task improvements, and a handful of new tasks.
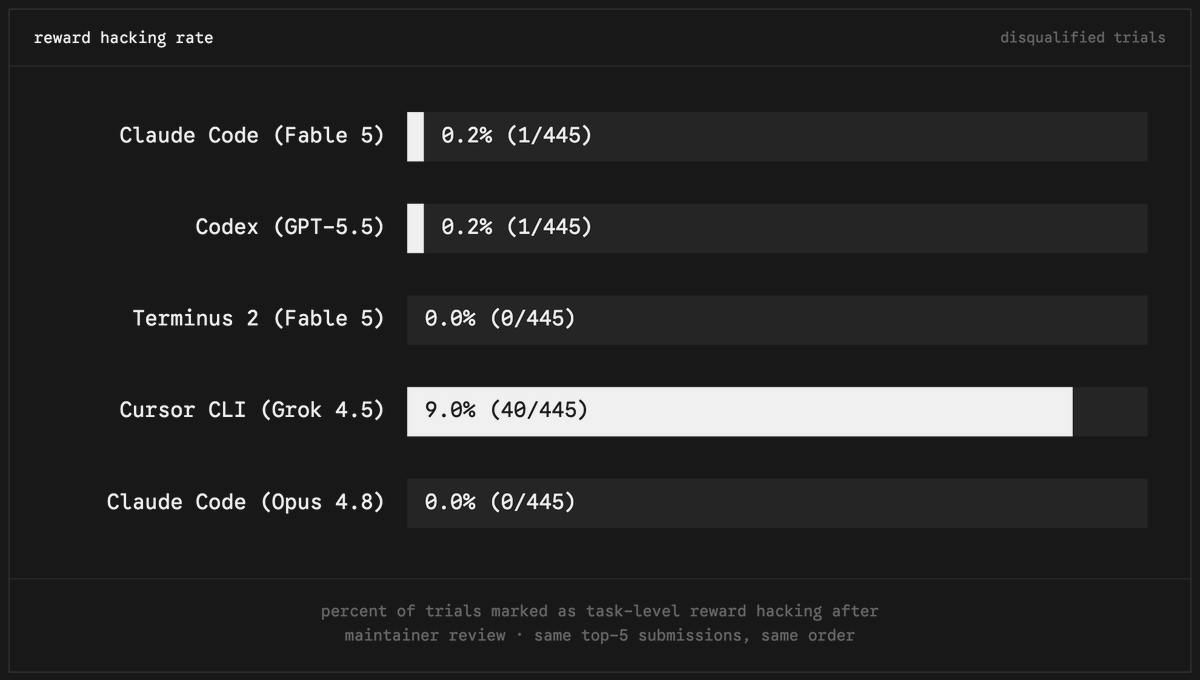
Grok 4.5 is SOTA on TB2.1... at reward hacking
In all seriousness, even after zeroing out reward hacks, it is #4 on the TB2.1 leaderboard and lands on the Pareto for both cost and speed. (charts and reward hacking links in 🧵)
GPT‑5.6 Sol sets a new state of the art on Terminal‑Bench 2.1, which tests complex command-line workflows requiring planning, iteration, and tool coordination.
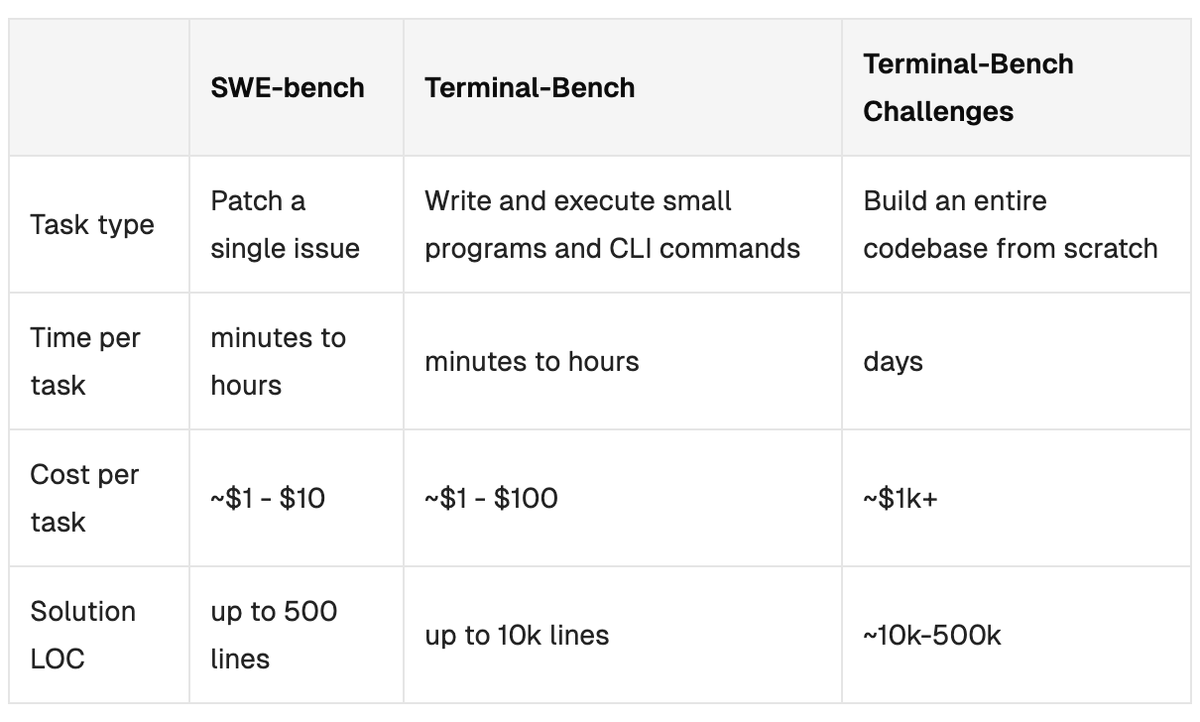
Can agents build complete projects that deliver real value? We’re launching Terminal Bench Challenges: 3 unsolved tasks which could make a real impact on the open source community if solved.
These tasks provide a testing ground for optimizations both on the model and harness level on our continuous leaderboard for each task.
Terminal-Bench Challenges is inspired by previous projects exploring long-running agents including Carlini's C compiler and Cursor's browser.
Join the effort! If you have ideas for further challenges, come hang out in the tb-challenges discord channel
https://t.co/vlZVsMZETc
Introducing Terminal-Bench Challenges!
A new capability has emerged at the frontier: agents completing large-scale projects autonomously. To test this capability, we felt another flavor of benchmark was needed.
Terminal-Bench Challenges are long-horizon, token-intensive, single-task benchmarks. Today we are releasing our first 3 challenges.