New release from https://t.co/torVpwoD7B! Dictate test documentation, run manual tests directly from your browser, and build richer integrations with Public API v2 🚀
Here's what's new 👇
• 🎙 Voice Mode — dictate test steps, requirements, comments, and exploratory testing notes
• 🧩 https://t.co/torVpwoD7B Browser Extension — create tests, record browser actions, and execute manual runs without switching tabs
• 📊 Manual-to-Automated Analytics — track how your test suite’s automation coverage changes over time
• 🤖 AI-generated project structures + Mermaid diagrams for visual test design
• 🔌 Public API v2 improvements — branch-aware requests, aggregated counts, run statistics, analytics access, and clearer pagination
• ✨ Easier manual run editing, search within Test Plans, advanced relaunch improvements, and more!
Storm Charles might have weathered out MEO Arena at #WebSummit2026, but the Agentic AI hype is only getting hotter. 🔥
How do you test at AI speed without breaking production? Our CEO @mpoliarush is in Lisbon through Nov 13 showing teams how https://t.co/torVpwoD7B bridges AI speed with QA control:
🔹 AI Test Generation from Jira, Figma & Confluence via MCP
🔹 Explorbot for autonomous testing
🔹 Chat with Tests & BYO-LLM (OpenAI, Anthropic, Bedrock)
Free slot today or planning Day 3 tomorrow? DM Mykhailo on LinkedIn or the Web Summit app for a coffee! ☕️
#Testomat #WebSummit #AI #QA #DevOps
Your automated test suite shouldn't run long enough for you to brew coffee, drink it, and question your career choices. ☕😅
If CI/CD feedback takes 40+ minutes, developers bypass it.
The cure? Smart test orchestration, parallel runs, and running only what actually changed. Fast feedback = fast shipping.🚀
How long is your pipeline taking today?
#WebSummit2026 in Lisbon is officially underway! 📍🚀
Our CEO @mpoliarush is on the ground until November 13. If you lead QA or engineering, let’s connect to talk test management, automation reporting & scaling QA.
Hit him up here or via the Web Summit app! 🤝
#WebSummit #QA #TestManagement
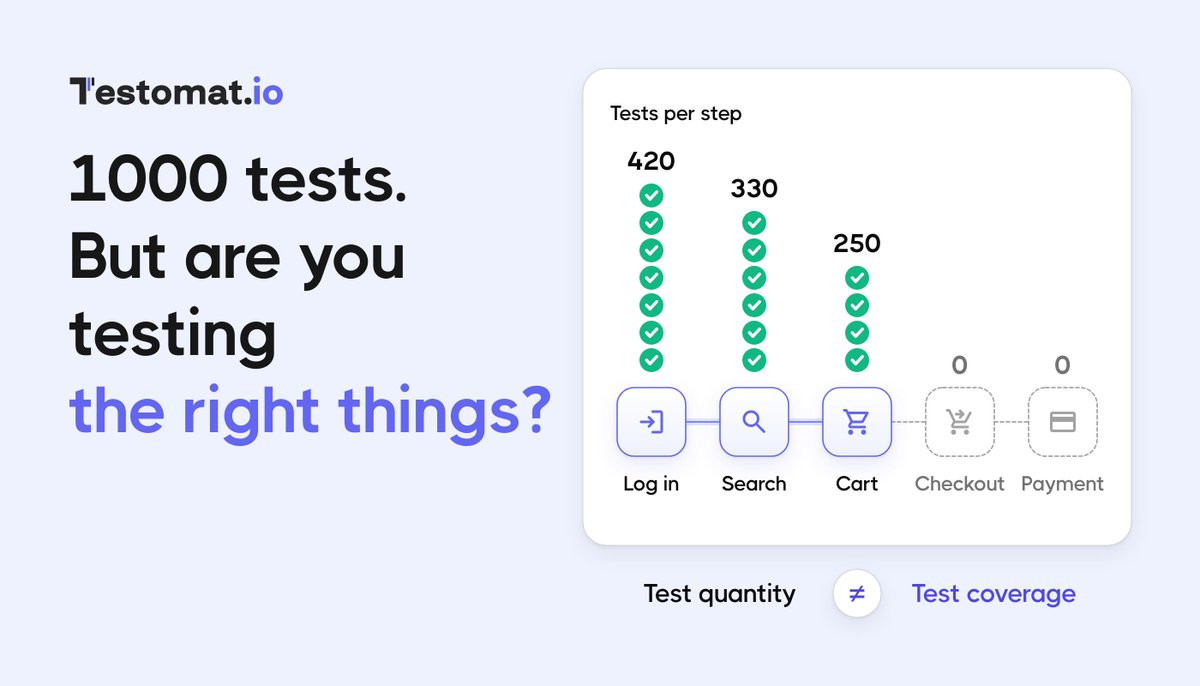
More tests ≠ better test coverage.
You can have 1,000 test cases and still miss critical user scenarios.
The real question is: are you testing the right things?
Good test coverage means knowing what's covered, what's missing, and where to focus next.
How does your team track coverage gaps?
#SoftwareTesting #TestCoverage #QA
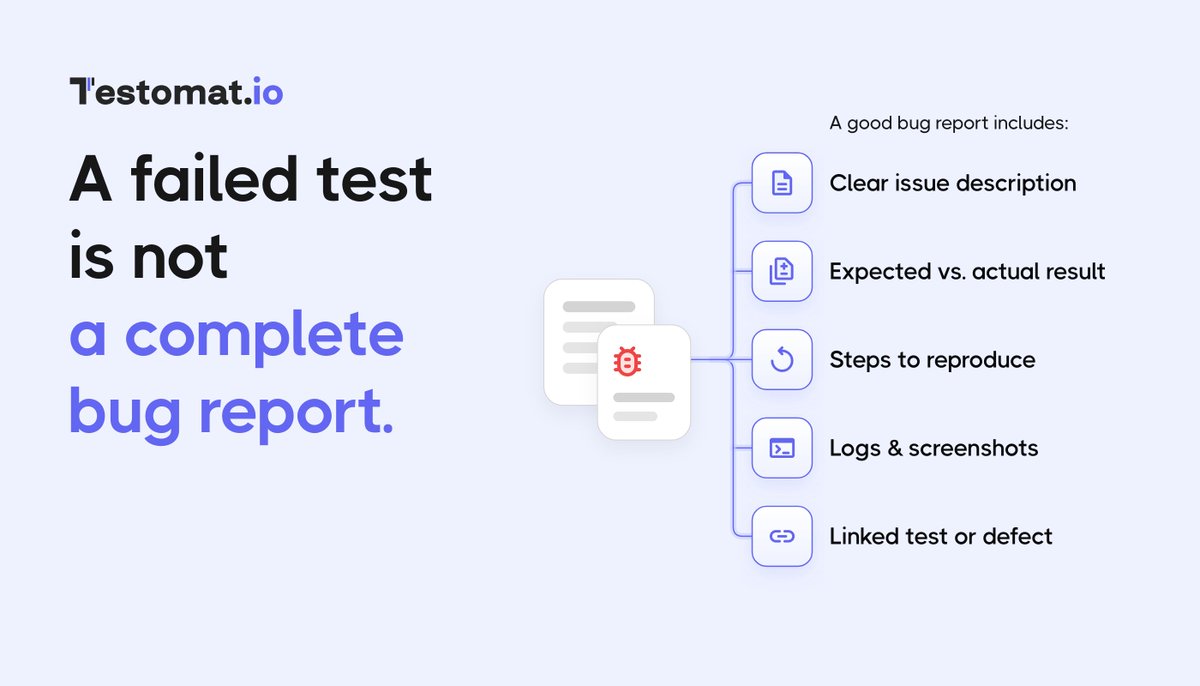
A failed test isn't enough.
Developers need context:
→ What failed?
→ What was expected?
→ How to reproduce it?
→ Where's the evidence?
A good bug report saves time for the entire team.
What's the one thing every bug report should include?
#SoftwareTesting#BugReporting #QAEngineering
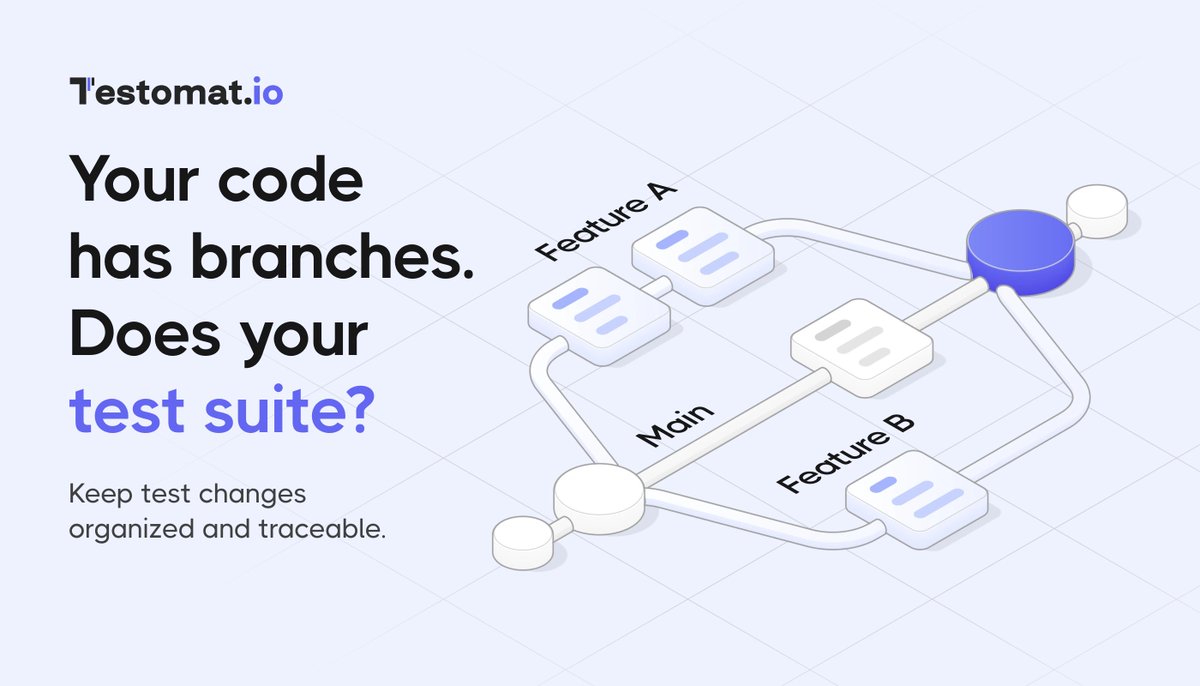
Your code has branches. Does your test suite keep up?
When multiple features are developed in parallel, test cases change too.
Without proper versioning, it's easy to lose track of:
🔵 what changed
🔵 which version is relevant
🔵 what needs to be merged
Test management should fit the development workflow.
How does your team handle test changes across branches?
#SoftwareTesting #TestManagement #QAEngineering
It is 2026 and prompt engineering is still a thing
We fully delegated prompt writing to agents. The fact the we concealed prompts under "claude make a skill" doesn't mean they do not exist anymore
once you look inside you may get this:
"verified ledger is not a valid envelope"
I compared all Playwright alternatives for end2end testing
Including @lightpanda_io Obscura and Moli
TLDR:
With rendering you gain x2 speed
No rendering - x5-x6 in speed
Have you heard of e2e framework from @TesterArmy ?
It's AI-native @playwrightweb alternative for browser and mobile testing
Where you combine classical code with AI prompts to achieve the test goals
Let's go through lightweight browser engines that you can use today to speed up your testing and development
I tried all them and I would like to share my experience
Save this list of agentic browsers. You will need it one day!
And let's go:
It's 2026, no one writes e2e tests by hand
And no new fancy framework can solve that
That's why we created Explorbot which takes test cases in markdown format and executes them
You don't have test cases? It takes web page and tests whatever is reasonable there
AI test case generation moves QA work from writing tests to reviewing them.
That shift only works when AI has more context than a pasted user story. A standalone chat can draft test cases, but it doesn't know what your team has already covered or where the real gaps are.
In https://t.co/torVpwoD7B, AI works inside your test project. It analyzes the requirement, suggests suites and tests, and keeps them linked to the source. The tester can edit, accept, or reject every suggestion.
@mpoliarush explains the workflow, its limitations, and where human judgment still matters:
https://t.co/5A3AsPhux8
Jev, Jev, Jev. Have you added it to your QA workflow yet?
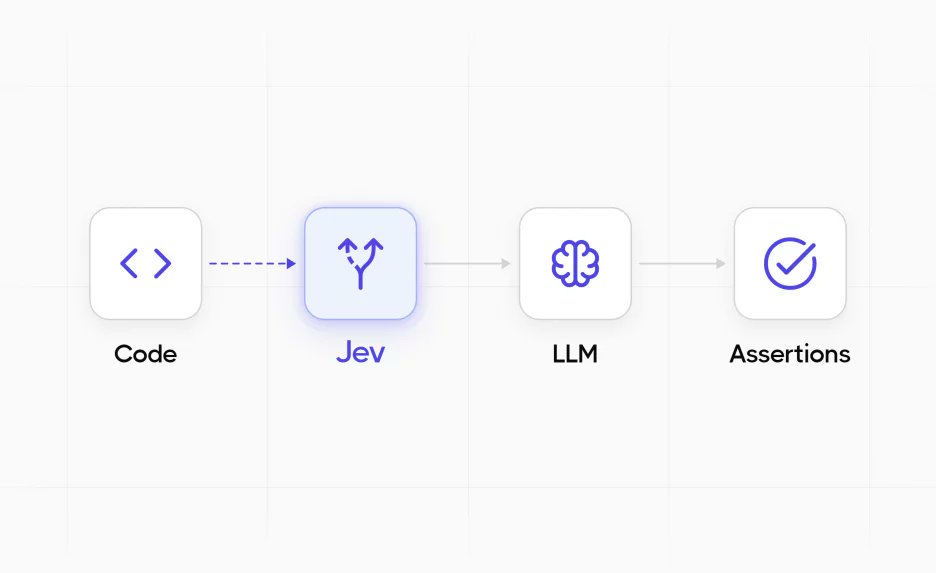
Explorbot can now use Jev as an optional decision model for the small, closed questions that come up during a test: which of several similar elements to click, whether the run is still making progress, or whether an expected result is already verified.
Jev picks one of the available options and returns a confidence score. If confidence is low, Explorbot falls back to its usual behavior.
The models that plan and run the test stay the same. Jev is a faster layer for questions that need one clear answer, not a paragraph.
Coding agents write unit tests cheaply and in volume. But they rarely see a running database.
So the test count grows, and the contracts between components stay untested.
Unit vs. integration tests, and how to balance them in CI:
https://t.co/ECF3BQi6EG
Your load test passed before the last release. How many PRs have changed checkout since then?
Set a p95 limit your pipeline checks (800 ms at 1,500 users), run 2 minutes of load on every PR, schedule the heavy tests.
Tetiana Khomenko on the setup: