BidirLM-Omni is live right now at COLM poster #28!
Looking for an open source encoder training method that sits right on the Pareto frontier alongside @googlegemma recent omnimodal embedding? Come talk to us! 🚀
Huge congrats to @N1colAIs@theodb_ml and @gisship 🎉
@GoogleDeepMind just released EmbeddingGemma 2, and the @googlegemm launch blog benchmarks against BidirLM-Omni-2.5B on the Massive Audio Embedding Benchmark. Our model sits right on the Pareto frontier!
@GoogleDeepMind@beirmug Congrats on the release! ��� Happy to see our BidirLM-Omni-2.5B sitting on the Pareto frontier of your MAEB chart 🎧
Presenting it at #COLM2026 tomorrow if anyone wants to discuss multimodal encoders
@googlegemma Congrats on the release! 👀 Happy to see our BidirLM-Omni-2.5B sitting on the Pareto frontier of your MAEB chart 🎧
Presenting it at #COLM2026 tomorrow if anyone wants to discuss multimodal encoders
@tomaarsen@GoogleDeepMind Happy to still see our BidirLM-Omni-2.5B sitting on the Pareto frontier of the MAEB chart 🎧
Presenting it at #COLM2026 tomorrow if anyone wants to discuss multimodal encoders
@osanseviero Congrats on the release! 👀 Happy to see our BidirLM-Omni-2.5B sitting on the Pareto frontier of your MAEB chart 🎧
Presenting it at #COLM2026 tomorrow if anyone wants to discuss multimodal encoders
I'm at #COLM2026 in San Francisco this week 🌉
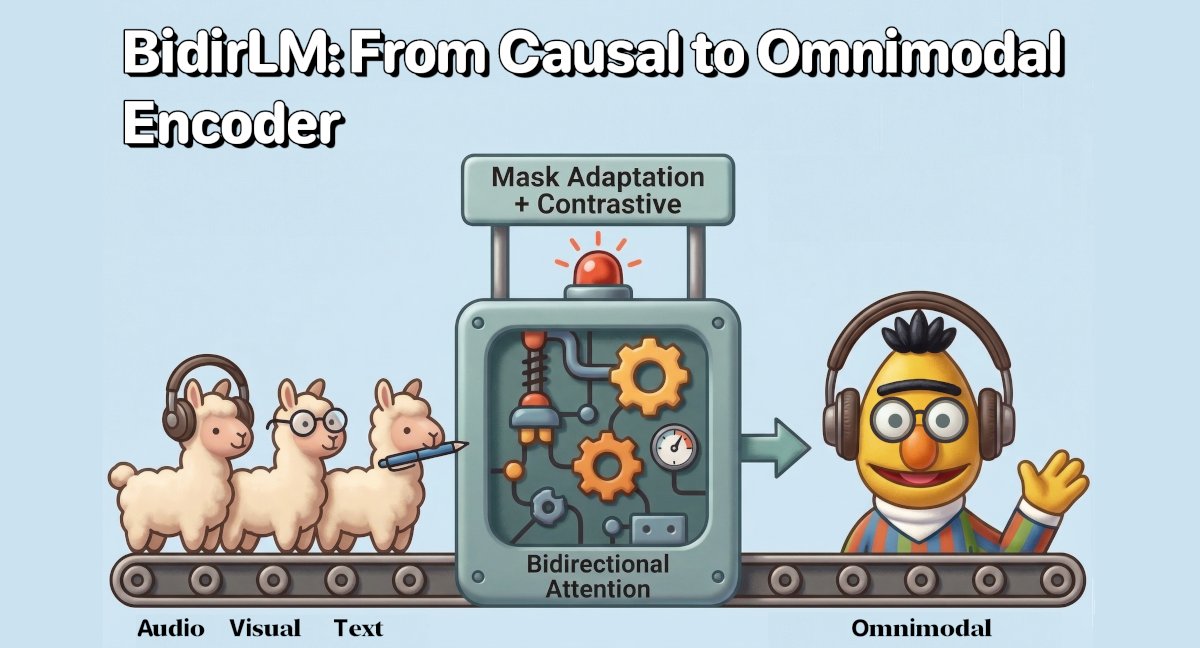
I will be presenting BidirLM-Omni (/w @N1colAIs) open-source recipe that turns causal decoder LLMs (like Gemma 3 and Qwen3) into strong bidirectional encoders for text, image and audio
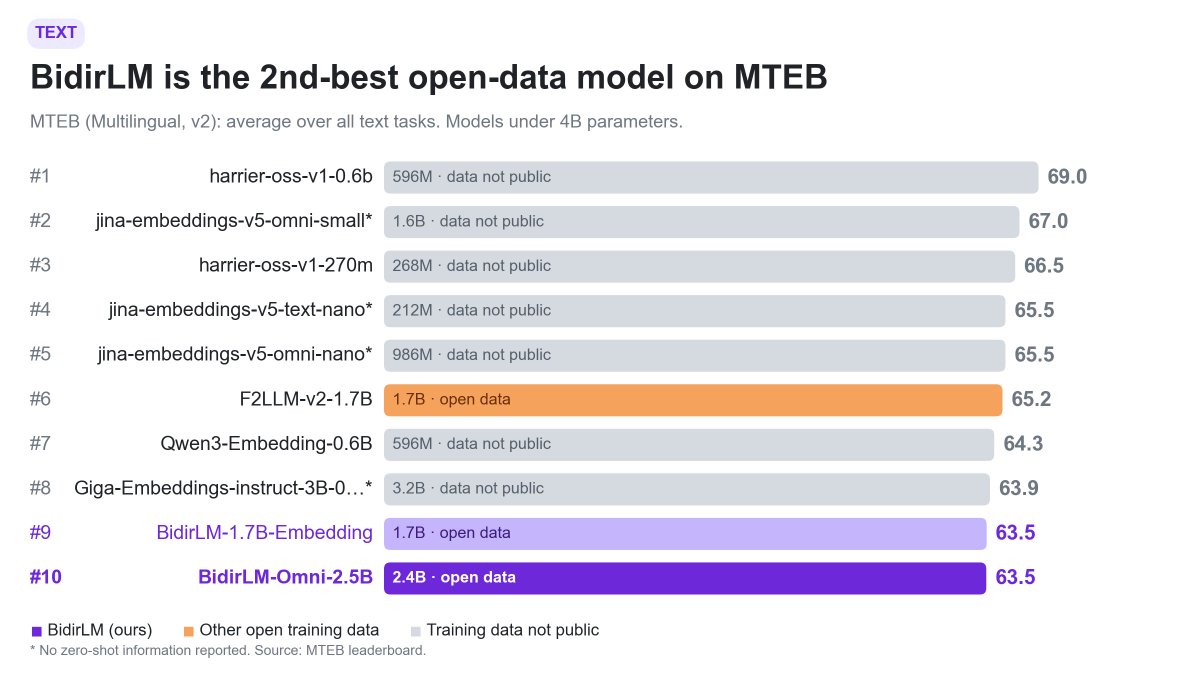
@N1colAIs Among models under 4B parameters, BidirLM-Omni-2.5B is #1 on MAEB (audio), the best model with open training data on MIEB (image) and the 2nd-best open-data model on MTEB Multilingual (text)
The weights, training data and recipe are all public (https://t.co/3WwEukpACX)
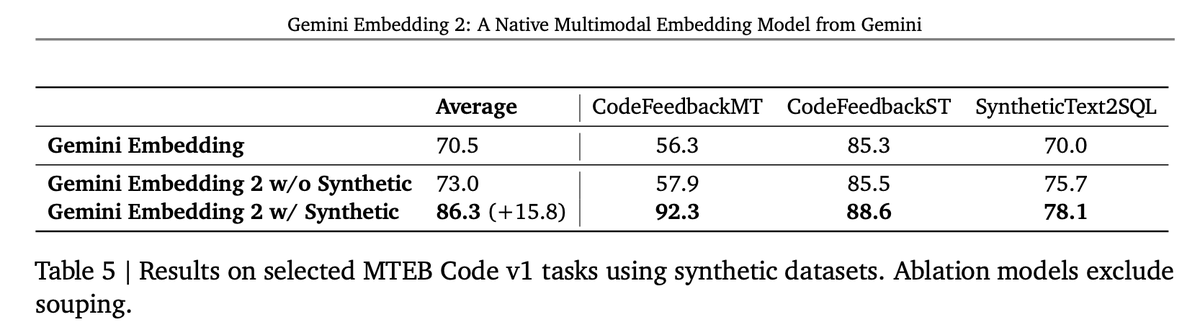
Awesome to see them build on the same tricks as BidirLM-Omni, like the decoder-to-encoder adaptation and cross-modality model merging. The synthetic data ablation is also a huge highlight with a +15 gain for code retrieval domains
Tldr: we feed more data into llms and it trains faster, then we resume as usual. Very easy to reproduce, significantly better loss at equal flops, imo worth an A/B if you pretrain models :)
BidirLM-Omni-2.5B-Embedding is live: a single bidirectional encoder that embeds text, images, and audio into the same space!
Three modalities, all in one 2048-dim space.
🧵
BidirLM-Omni is on MTEB and Sentence-Transformer!
https://t.co/JRqmipX5xl
🥇#1 Open-Source Model on MTEB (#15 overall)
🖼️#1 across all sizes on MIEB (Image)
🎧#1 sub-7B model on MAEB (Audio, #2 overall)
Small size, massive performance, Fully open
Model: https://t.co/AZzOJ6ZhhN
🚀 New model family release with an OMNIMODAL version !
After Eurobert, I'm excited to introduce BidirLM, a family of 5 frontier bidirectional encoders including an OMNIMODAL encoder at just 2.5B parameters.
🧵👇
https://t.co/AZzOJ6ZhhN