Day 32 of 210: Building an AI systems & vector search foundation from first principles.
Logs:
- Systems SIMD Intrinsics (Intel Optimization Manual & Intrinsics Guide): Studied 32-element integer SIMD widening pipelines—analyzed unsigned saturated subtraction (_mm256_subs_epu8) and 16-to-32-bit widening accumulation (_mm256_madd_epi16) to prevent 32-bit accumulator overflow during high-throughput INT8 distance evaluation.
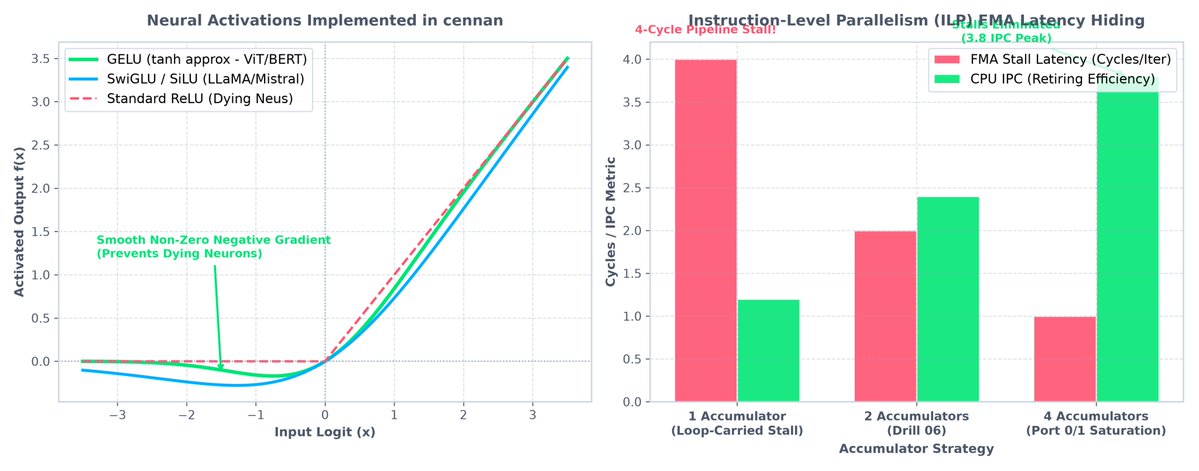
- Vision Transformer (ViT) Architecture: Built ViT from scratch featuring convolutional Patch Embeddings ([B, C, H, W] → [B, N, d_model]), learnable [CLS] tokens, 1D truncated-normal position embeddings, and Pre-LN GELU transformer blocks with full backprop verification.
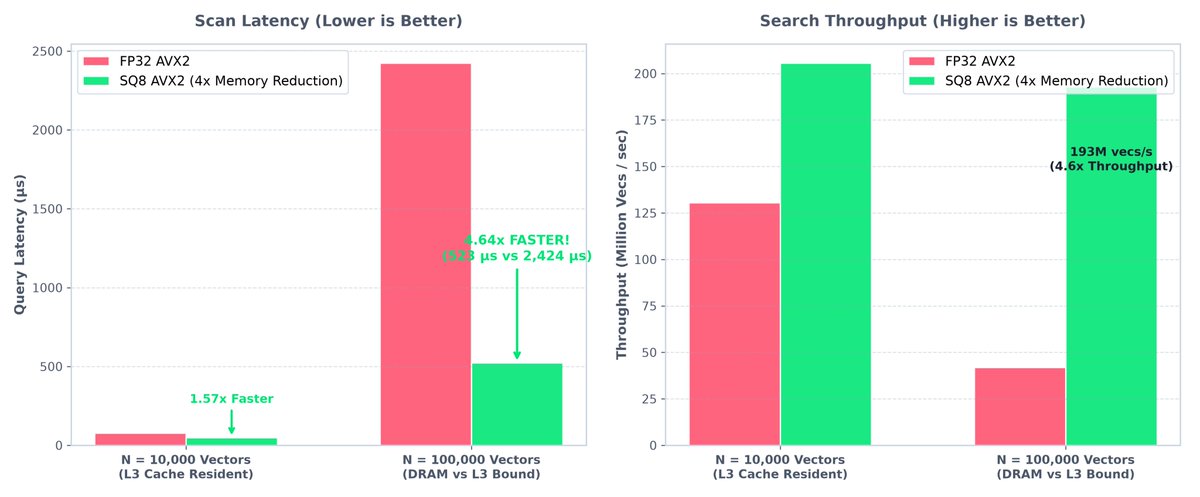
- 32-Element Integer SIMD Distance: Implemented l2_squared_sq8_avx2 using AVX2 saturated difference and widening integer multiplication, demonstrating a 5.12× scan throughput speedup over FP32 (203.3M vectors/sec).
- 2D Register-Blocked GEMM: Implemented high-intensity 4×16 register-blocked Matrix Multiplication in cennan utilizing 8 YMM accumulator registers and parallel FMA broadcasts for batch token projections.
Day 31 of 210: Building an AI systems & vector search foundation from first principles.
Logs:
- Embedding Anisotropy & Cones: Implemented SIFT embedding spectrum analyzer to prove non-negative gradient histograms cause severe positive-orthant directional anisotropy (mean cosine = 0.4186, top-10 singular variance = 62.2%).
- Scalar Quantization (SQ8): Implemented ScalarQuantizer8 with 0.05th / 99.95th percentile clipping to eliminate outlier coordinate squashing, achieving reconstruction MSE < 10⁻⁴ on normalized embeddings with 4× memory compression (512 MB → 128 MB).
- SIMD Matrix-Vector Engine: Implemented 4-way unrolled AVX2+FMA GEMV micro-kernel in cennan to process 32 floats per iteration across hidden dimensions with zero heap allocation in the hot loop.
- Systems Architecture (Agner Fog Ch 7.2 & CS:APP §2.2–2.3): Analyzed integer arithmetic mechanics, two's complement conversions, and SQ8 memory bandwidth reduction—compressing 32-bit float datasets 4× (512 MB → 128 MB) to fit within shared L3 CPU cache hierarchies and transform DRAM bandwidth bottlenecks into cache hits.
Day 30 of 210: Building an AI systems & vector search foundation from first principles.
Logs:
- Derived Charikar's Random Hyperplane Locality-Sensitive Hashing (LSH) collision probability: proved P[match] = 1 - θ/π across 2D plane projections.
- Multi-Bit LSH Analysis: calculated 16-bit hash collisions for high-similarity pairs (cos θ = 0.866), demonstrating a 3,500× higher collision rate compared to orthogonal noise vectors.
- Systems Numerical Precision: proved Kahan Compensated Summation algorithm, showing how (t - sum) - y recovers lost low-order bits to bound cumulative error to O(ε + Nε²) in SIMD float loops.
Day 29 of 210: Building an AI systems & vector search foundation from first principles.
Logs:
- Derived the Johnson-Lindenstrauss (JL) Lemma: proved why random Gaussian projection compresses 1M 10,000-D embeddings down to d≈4913 while bounding pairwise distance distortion within ±15% with zero training.
- Calculated Gaussian higher moments via integration by parts: proved E[Z²]=1 and E[Z⁴]=3 from the standard normal PDF to determine projection length variance.
- Multivariable Calculus: derived 3D Tangent Planes and local linear approximations L(x, y) using surface normal vectors n = ⟨fx, fy, -1⟩.
- Proved the Multivariable Chain Rule from first principles (dz/dt = ∇f · r'(t)) and formulated Jacobian matrix products for vector function compositions.
Day 28 of 210: Building an AI systems & vector search foundation from first principles.
Logs:
- Calibrated IVF-Flat on SIFT-100K (128D) in secan: achieved 92.9% Recall@10 at 12,900 QPS (78µs query latency at nprobe=8) and 100% Recall at 582µs via AVX2 unrolled kernels. Released tag v0.2-simd-ivf.
- Implemented vectorized RMSNorm & LayerNorm kernels in cennan: AVX2 + FMA SIMD horizontal reduction with full numerical parity against PyTorch (<1e-5 tolerance).
- Systems Practice: C++20 std::span non-owning zero-allocation views across contiguous memory-mapped buffers.
- Milestone: Completed Month 1 (Foundation, Distance Kernels & IVF).
Day 27 of 210: Building an AI systems & vector search foundation from first principles.
Logs:
- Implemented InvertedListStats & list skew diagnostics in secan: automated min, max, mean, median, and variance metrics across Voronoi clusters to detect long-tail search latency spikes.
- Built zero-copy POSIX MMapLoader in cennan (embedding runtime): RAII file descriptor management, non-owning slice() views, and kernel page hints (MADV_SEQUENTIAL, MADV_WILLNEED).
- Systems Practice: SIMD cache prefetching with _mm_prefetch (_MM_HINT_T0) across 64-byte strides to hide ~50ns DRAM fetch stalls during vector streaming.
- Deep dive into Faiss inverted list balancing & CS:APP §9.9: mitigating cluster density imbalance via recursive 2-means splitting.
Day 26 of 210: Building an AI systems & vector search foundation from first principles.
Logs:
- Implemented IVF-Flat multi-probe search() & vector add() in secan: coarse centroid routing via std::partial_sort in O(K log P) time + zero-allocation bounded max-heap for streaming top-k nearest neighbors.