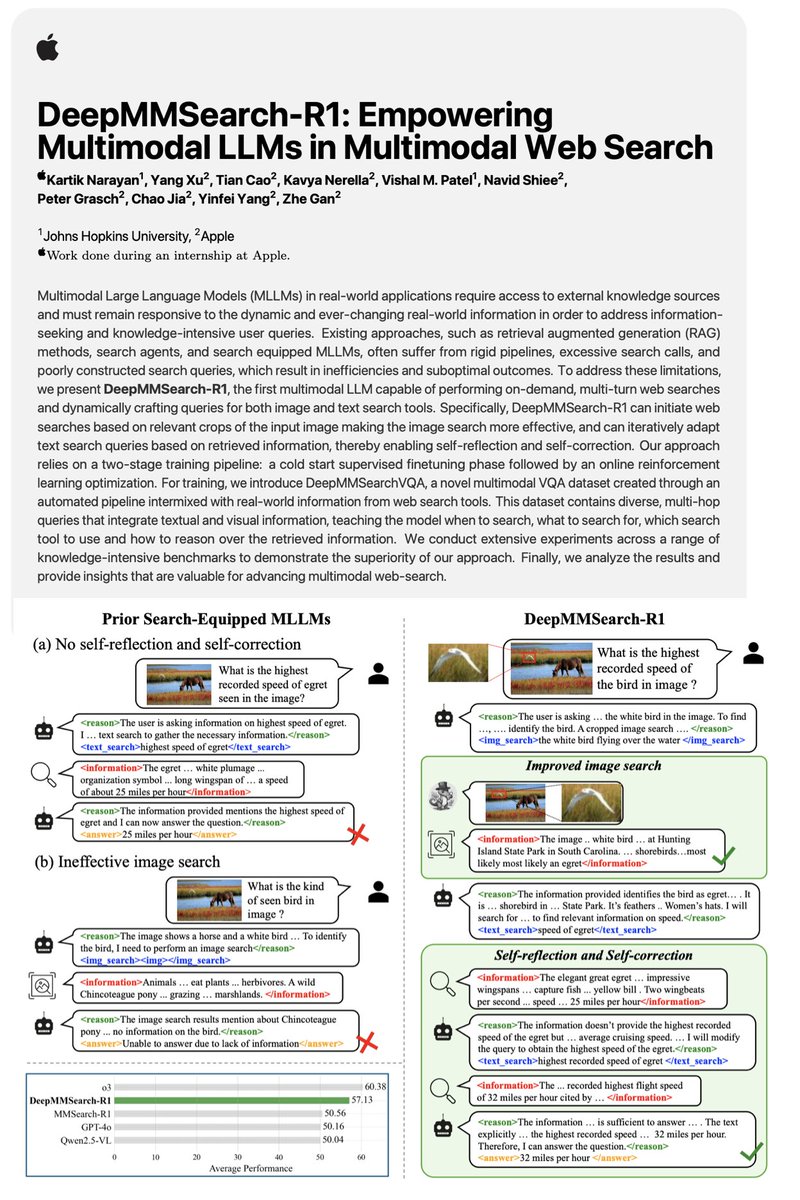
🤔 Knowledge stored in multimodal LLM weights can be inherently limited. How can we empower multimodal LLMs with multimodal web search?
💡 In DeepMMSearch-R1, we aim to train a multimodal search agent capable of performing on-demand, multi-turn web searches and dynamically crafting queries for both image and text search tools. It can also initiate web searches based on relevant crops of the input image via using Grounding DINO as a tool.
🔗 arXiv: https://t.co/NhOPiyX4Ql
1️⃣ In SFT, we teach the model when to search, what to search for, which search tool to use and how to reason over the retrieved information.
2️⃣ SFT enables tool use, while RL refines the tool-selection behavior by reducing unnecessary calls.
Led by our awesome intern @KartikNarayan10, @tiancao, @yinfeiy etc.