试着用程序员熟悉的编程语言来理解陶哲轩 Terence Tao 转发的这则讽刺帖子,不知道这个类比是否准确。
假设人类借鉴 C 语言,设计一门新的 X 语言。在这个过程中,我们会探索不同的语言特性,讨论各种设计取舍,逐渐形成一些新的设计原则和理解。这些知识不仅能用于 X,也可能帮助未来设计 Y 语言。
但如果 AI 通过黑箱方式直接生成了一门 X 语言,虽然结果可能很好,效率也很高,但我们未必理解它为什么这样设计,以及其中哪些思想可以推广到 Y。
当然,设计一门新的编程语言是工程问题,和数学研究有所不同,这里只是借它做个类比。
The loudest voices stoking fears about AI dangers have made tremendous headway in the past two weeks. AI technology has not taken some unexpected, dangerous turn, but the hype around it — propelled by what appears to be a well orchestrated PR campaign — has drummed up considerable fear. I worry that it represents a setback for our field.
I have written frequently that fears of AI are overhyped. AI’s capabilities can be uncannily human-like and unpredictable, and it’s rational to worry when people who are directly involved express concerns. But I see the problems as a sign of the engineering work that ahead, rather than insurmountable barriers or the sky falling. AI technology continues to advance — which is a good thing! — but technical advances, poorly understood by the public, give those who seek to generate hype repeated opportunities to do so.
First, I don’t see any step up in the risk of human extinction from AI compared to a few months ago. The theories about this remain the same fantastical, science fiction scenarios as a few months ago. The biggest change in AI risk is its cybersecurity capabilities — a topic which we should take seriously — but this, too, will not lead to the end of the world.
The most notable recent event leading to increased fear was when an OpenAI team deployed an agent swarm that hacked into Hugging Face. Much of the popular press contained significant hype. For example, some publications reported that a swarm of 1,200 agents carried out the attack. While this was technically accurate, as I write this, I have about 1,300 processes running on my laptop. Yes, the ability to get large swarms of agents to work in parallel on a task is a significant technical advance, And, in computing, many processes run at the same time. So this shouldn’t be seen as some magical capability.
Additionally, OpenAI’s buggy sandboxing and monitoring processes were key to enabling this incident. Fixing these bugs and putting in place improved monitoring would be appropriate fixes, not pausing AI. There are many well known ways to attack software systems. The main advantage of AI agents is that they are relentless. They will tirelessly try many tactics — and have the patience to chain vulnerabilities together — that previously would have taken an infeasible amount of human effort. But in the long term, I believe the advantage will lie with defenders (because they have more information with which to identify bugs, which they can fix), but the cyber-threat landscape has changed significantly. There are still bottlenecks to identifying and exploiting a vulnerability. AI agents still have to try a lot of things to see what works, and taking these actions takes time and might be detected by defenders. This is why, even though it is now easy to obtain versions of leading open weight models that have had their guardrails removed or weakened, so they will not refuse to try to execute cyber attacks, the world has not ended.
I am also concerned about the anthropomorphization of AI in a lot of reporting, where LLMs and agents are unnecessarily treated as if they were people. If I wield a hammer, miss a nail, and accidentally dent the wall, it’s not the fault of the hammer. The problem lies in how I used the hammer. Similarly, if I prompt an agent and it hacks into someone else’s system, the responsibility lies with me, not the agent.
Of course, we want to build systems that are as safe and predictable as possible. (For example, an unsafe hammer would be one whose head randomly flies off under normal use.) Today’s agentic systems are not predictable, but I see no reason why, by applying sound engineering practices, we won’t be able to make them extremely safe to use. One new element in the forecasts of AI-enabled doom is AI companies disclaiming responsibility for their own products. “I didn’t do it; my out-of-control agent did!” There’s a balance to be struck between the responsibility of the tool maker and the tool user, but when something goes wrong, let’s hold the people building and/or using the hammer responsible, rather than the hammer. (By the way, if you’re worried about AI bioweapon risk, David Bellamy has a great post on why this, too, is overhyped. Briefly, the bottleneck in building a bioweapon is not intelligence, but lab work and manufacturing.)
Pausing AI progress will create much more harm than benefit. First, our adversaries will certainly not slow down. Second, engineering requires discovering problems empirically so we can fix them. If we pause AI by a decade, we will also delay finding and implementing safety engineering fixes by about the same duration.
Of course, the incentive to stoke fears — for regulatory capture, to garner attention, or to make one’s technology seem more powerful — remains the same as before. Disclaiming responsibility is a new one. Taking a hard technical look at the actual risks however, I see little factual basis for the degree of fear that’s been stoked up. We still have hard research and engineering work ahead to improve AI safety, but the beneficial applications continue to vastly outweigh the risks, and we should keep building.
[Original text (with links): https://t.co/jni2tWazAH ]
Last month I wrote about how we can build a positive and safe future for everyone: https://t.co/eoLGVY8yad
Every lab has the responsibility and incentive to move at the pace required to train its models safely, and the ability to take its own actions to ensure that happens.
The reality is:
- People won't want to use agents that are misaligned with them and that don't do what they ask, so labs have a strong natural incentive to make their models more aligned.
There is a lot of debate about slowing progress on capabilities until alignment catches up. My view is that trust and alignment are quickly becoming the most important capabilities that will differentiate agents and models. Any lab that doesn't focus on alignment will fall behind.
- Labs face significant liability if their models cause harm, so they have a strong incentive to prevent this as well.
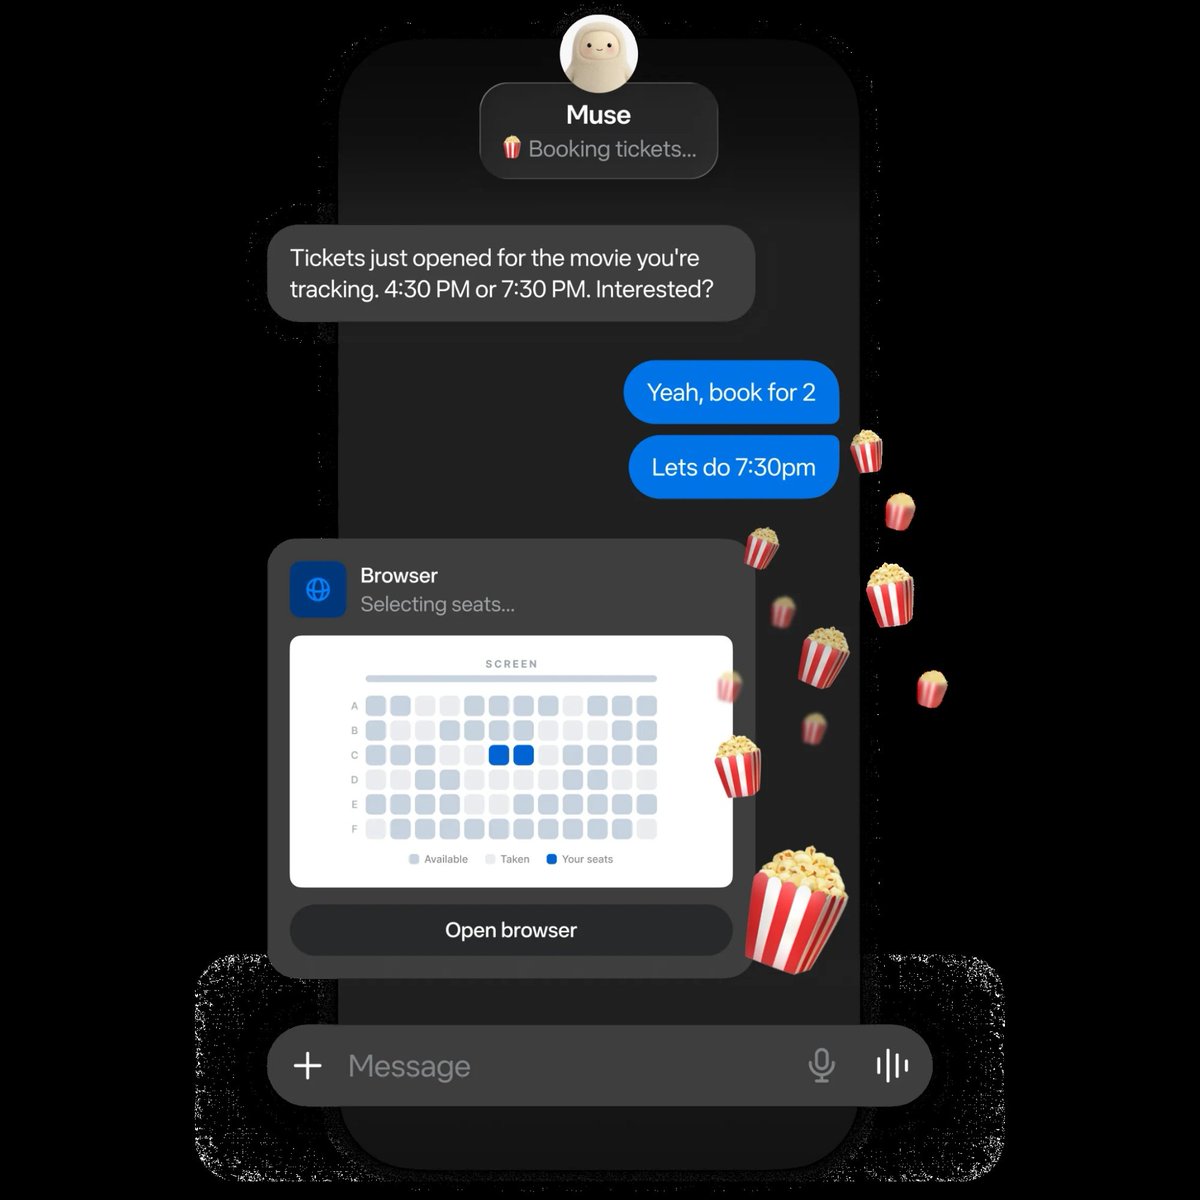
Meta delayed shipping Muse for several months to focus on safety and security. We didn't call for everyone else to do this before we would. We just did it as part of our day-to-day work because it was clearly the right thing for people and for us. I'm proud of the security foundations we've built.
- Engaging independent evaluators and advisors is industry best practice. MSL already does this today in several areas because it helps produce better work. Other labs can just do this too. In general, it would be helpful for there to be a larger and more diverse ecosystem of evaluators.
- Committing the significant majority of compute towards serving people rather than racing towards recursive self-improvement is one of the best ways to ensure we develop this technology safely. Meta has made this commitment and other labs can do this as well.
I believe the key to building a positive future for everyone is maintaining the right balance of power. This is within our power to do.
The world deserves confidence that American companies developing increasingly capable AI will act responsibly, especially as the trajectory of progress has steepened. Every frontier lab must deliver on this, and there is no reason any of us should come to work if we cannot.
We welcome a federal framework that sets consistent safety requirements for frontier AI. But we do not believe we need to wait for an anti-trust exemption or legislation to begin the work of providing this confidence. Consistent rules to manage frontier risk so that we can maximize the benefits are a good idea (and we are excited by ideas like independent auditors).
Years ago, companies like ours developed things like Responsible Scaling Policies and Preparedness Frameworks. Those were good for that moment, and focused primarily on the deployment of completed models, not what happens during their development process.
Today's shift to focusing on safe development and evaluation will need new tools. For example, at OpenAI we now formulate explicit safety cases in advance of frontier reinforcement learning runs we expect to significantly increase capability, in addition to the safety work we have long done in advance of model releases.
We hope that other companies will learn from our approaches and propose their own; we think shared standards for misalignment, monitoring, and safety will lead to better outcomes. We look forward to collaborating with our colleagues across the industry to formulate the best version of these.
When we talk about “pacing”, we do not mean “stopping”. Progress has been rapid and will continue to be. But it should be slower than it otherwise could be; interventions like safety cases and monitoring have significant costs.
Pacing will be well worth this cost; no amount of American competitive pressure should justify recklessness, or let capabilities get ahead of alignment and monitoring.
Where we will need the help of our government is for international coordination. But first we should do what we can ourselves.
BIG EPISODE 🚨: AI Kills Everybody or Doomer Psyop?
-- AI Researcher's Doomsday Warning Goes Viral
-- OpenAI’s Math Breakthrough: AI Training Privacy and Agent Swarm Innovation
-- Nike’s $200B Collapse: How Business Mistakes and Corporate Wokeism Killed an Iconic Brand
(0:00) Bestie intros!
(0:35) AI Doomsday: Valid concern or Doomer psyop?
(33:40) Steelmanning AI Doomsday scenarios and the impact on Anthropic's IPO
(58:45) OpenAI says it cracked a 200 year old math problem, but did it front-run users with their own data?
(1:19:55) Nike removed from S&P 100 after stock tanks 80%: What went wrong? $NKE
Strong liability enforcement could be helpful in the AI debate.
If your agent swarm goes rogue, you’re liable.
If your weakly protected model gets jailbroken, you’re liable.
If you serve a weakly protected OSS model, you’re liable.
Dario has written that we need to “pace the frontier,” and Sam has agreed. People may be surprised by my response: go ahead.
You guys are the frontier. By any reasonable metric — market share, revenue growth, model capability — the two of you have a duopoly on frontier intelligence. You’ve also claimed the lead is widening because of recursive self-improvement.
I don’t see what you see in the lab. If the unreleased models are scary enough that you think you should slow down, I support your decision to be responsible.
But stop pretending you need anyone else’s permission. Stop pretending antitrust law has to be suspended so you can form a cartel. Stop pretending you need a regulatory approval process that supersedes product liability. Stop pretending METR is independent when it is intertwined with Anthropic’s investors and staff. Stop pretending you need those same evaluators to police competitors who aren’t even at the frontier.
Most of all, stop pretending the motivation to slow down is purely altruistic. You face massive product-liability exposure if your products enable a truly damaging cyberattack. The market already punishes models that behave in unpredictable or unauthorized ways. After the Hugging Face episode, it is simply good business for OpenAI and Anthropic to trade some raw power for reliability and predictability. Call it alignment if you want. It is also just giving customers what they want.
Pacing the frontier would also create breathing room for a more intelligent conversation about regulation than Bernie Sanders’ “shut it all down.” China is very unlikely to join a global agreement, as you know, and that has to be taken into account as well.
So go ahead and pace the frontier. You are the ones setting it. The easiest way not to build superintelligence is for you to agree not to build it. Demanding your preferred regulatory framework as the price of that will look like blackmail of the public and the political system. So just do it.
If you do, you’ll buy goodwill for the next conversation. If you don’t, we’ll know this was just another bid for regulatory capture — or an election-season psyop.
We Must Pace the Frontier: I’ve written a new essay on why the AI industry should slow down, with a three-part plan for doing so.
Anthropic is unilaterally committing to the first of these steps. We’ll provide third-party evaluators with permanent, employee-level access to our systems, so that they can verify adherence to our safety measures, report on incidents, and assess models’ alignment during training.
You can read the full post here: https://t.co/OGyPb7yaYt
A common response is “if they truly believe this, why are they still building it?” At OpenAI, many have not deeply internalized the civilizational stakes. At Anthropic, the stakes are well-understood, but they are locked in a race to get there first - they believe no one else will act responsibly, so they must do it themselves, despite the risk.