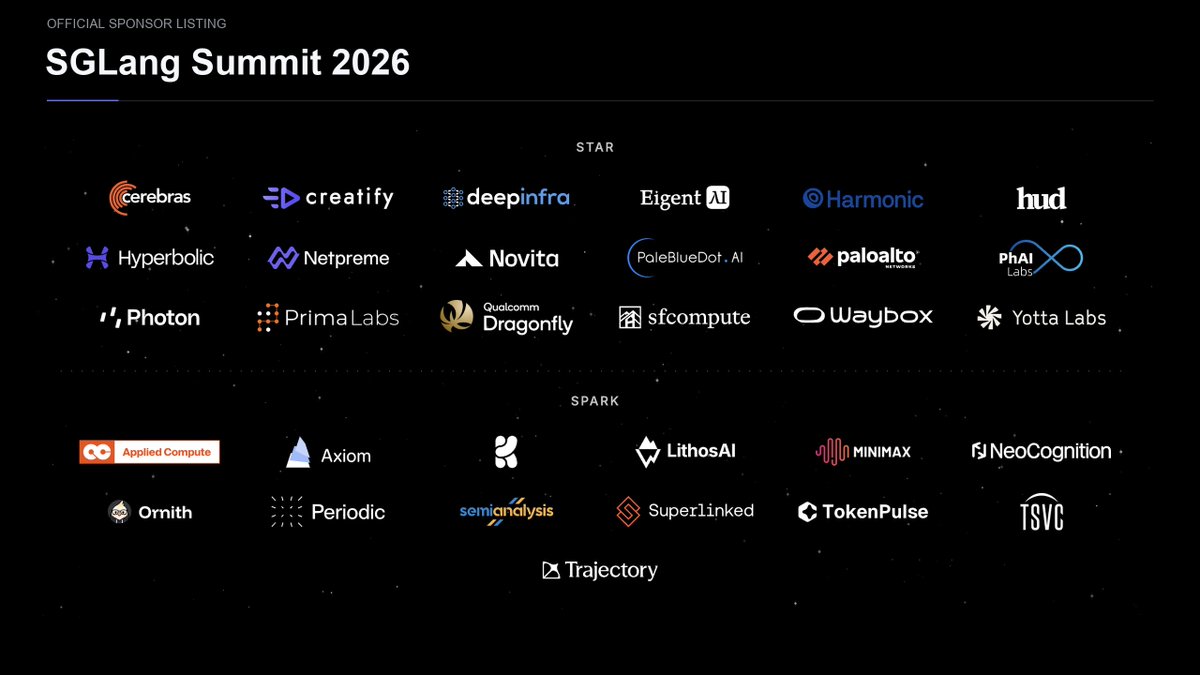
TokenPulse is proud to support SGLang Summit 2026 as a Spark sponsor.
We build on @sgl_project to tune inference by model and workload, aiming for better performance and lower cost.
Nov 12-13 | Fort Mason, San Francisco
https://t.co/WZOaWAZ7am
#TokenPulse#Inference
TokenPulse combines HiCache and Mooncake in a three-tier KV cache, with cache-aware prefill routing to support context reuse.
Which part of your agent's context repeats most often?
#TokenPulse#Inference#KVCache
An agent can spend compute rereading context it has already processed.
Prefix caching reuses compatible KV states for a matching input prefix. The next request processes the remaining input and generates its new answer.
On supported model configurations, TokenPulse uses context parallelism for long-context prefill and EAGLE speculative decoding.
Where does your app lose time: queueing, prefill, or generation? How does that change at peak load?
#TokenPulse#Inference
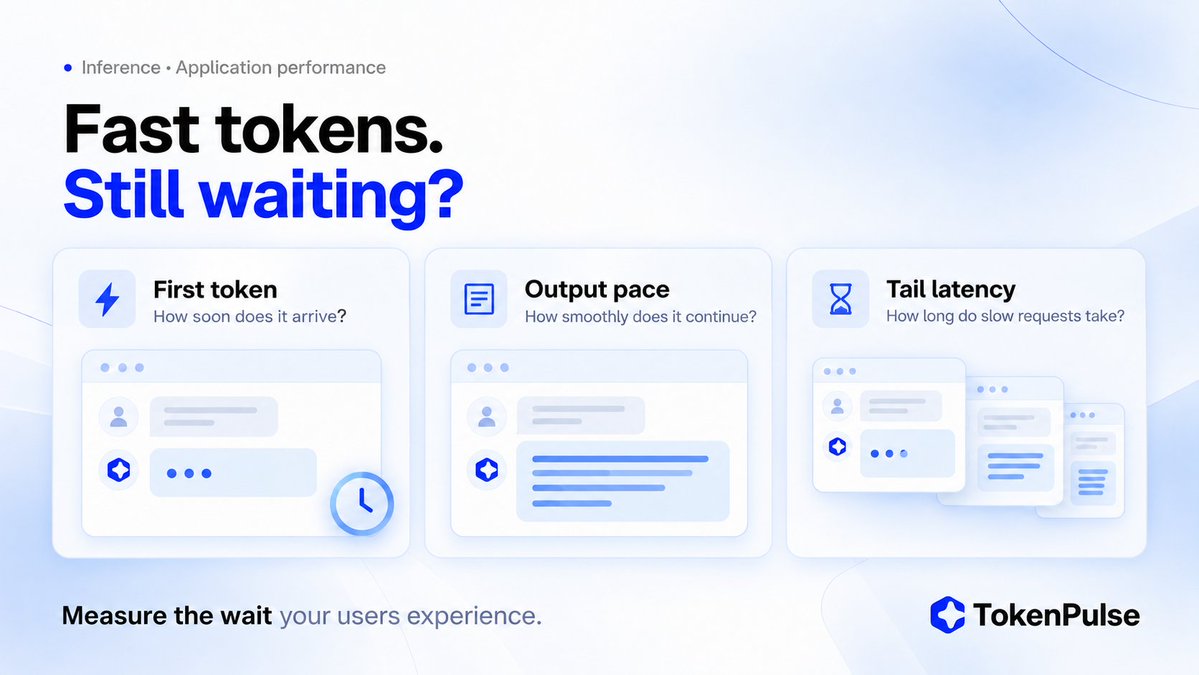
Fast token generation alone does not guarantee a responsive application.
Users feel three things:
- How long before the answer starts
- How smoothly it continues
- How long slow requests take at peak load
Measure the wait your users actually experience.
Models picked. What does it take to run them in production?
A validated mix of open-weight and closed models still needs access, efficient serving, capacity, and request delivery.
That's where inference infrastructure comes in.
Your team chooses and evaluates the models. We focus on the infrastructure behind them.
Evaluate the full setup on your workload: output quality, response time, and total cost.
#TokenPulse#Inference#OpenModels
“Not every task needs the most expensive model.”
That belief started TokenPulse, says CEO @Steven Zhou.
Singapore isn’t a branch office — it’s our co-headquarters alongside San Francisco and operating hub for Asia Pacific.
#TokenPulse#AIInfrastructure
AI is not just an IT revolution — it is an infrastructure revolution.
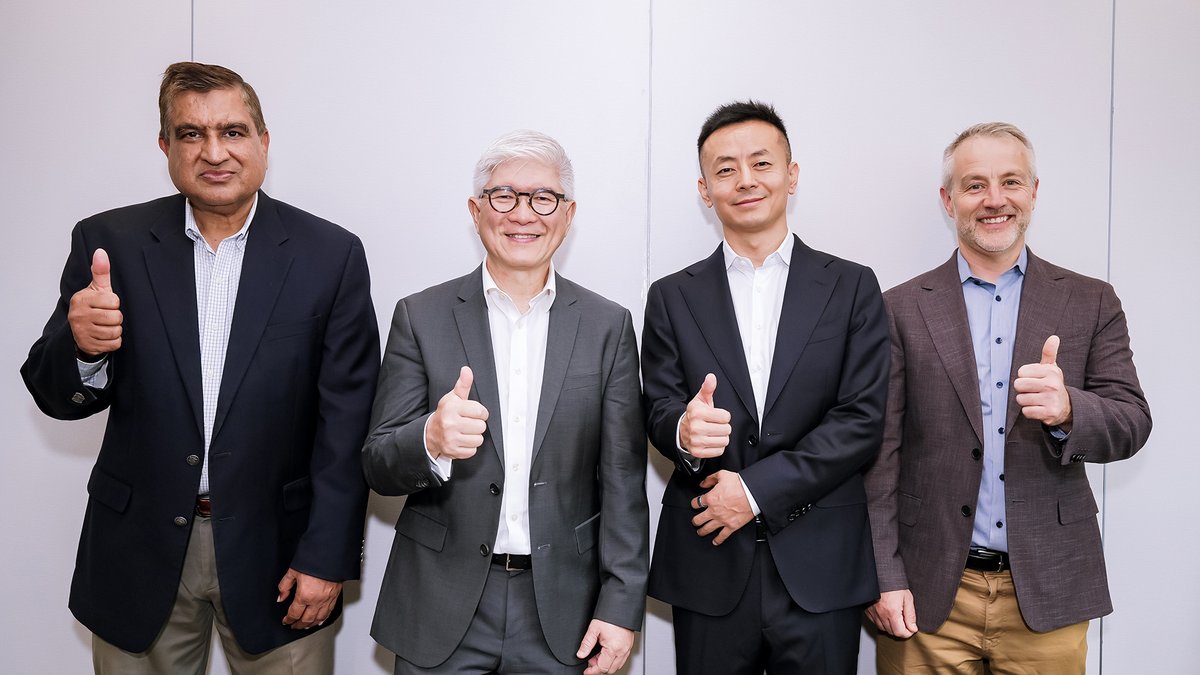
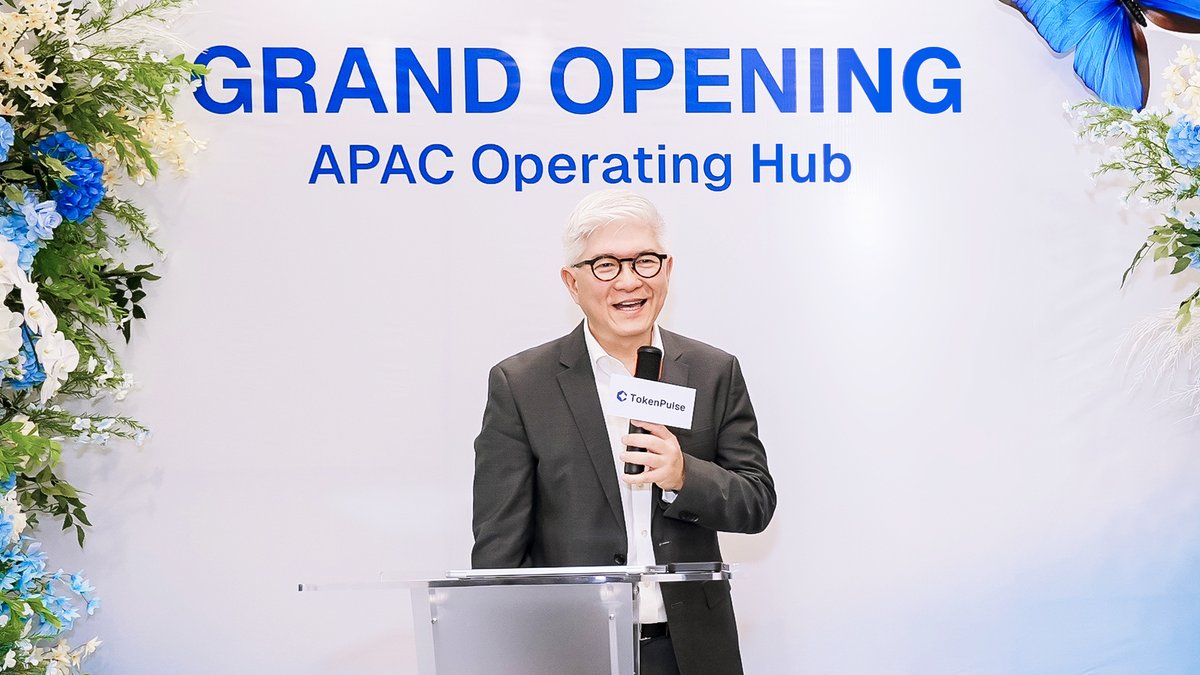
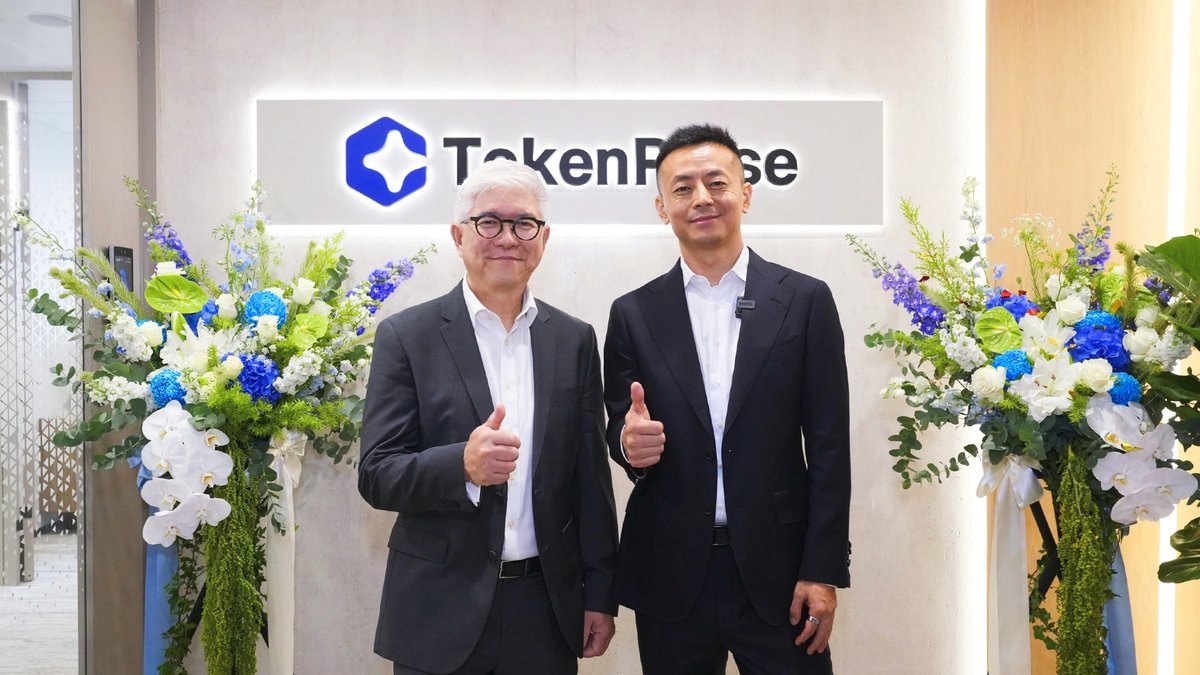
Chairman @Thomas Pang at TokenPulse's APAC hub opening in Singapore: “Infrastructure must be prepared before demand fully arrives.”
#TokenPulse#AIInfrastructure#Singapore
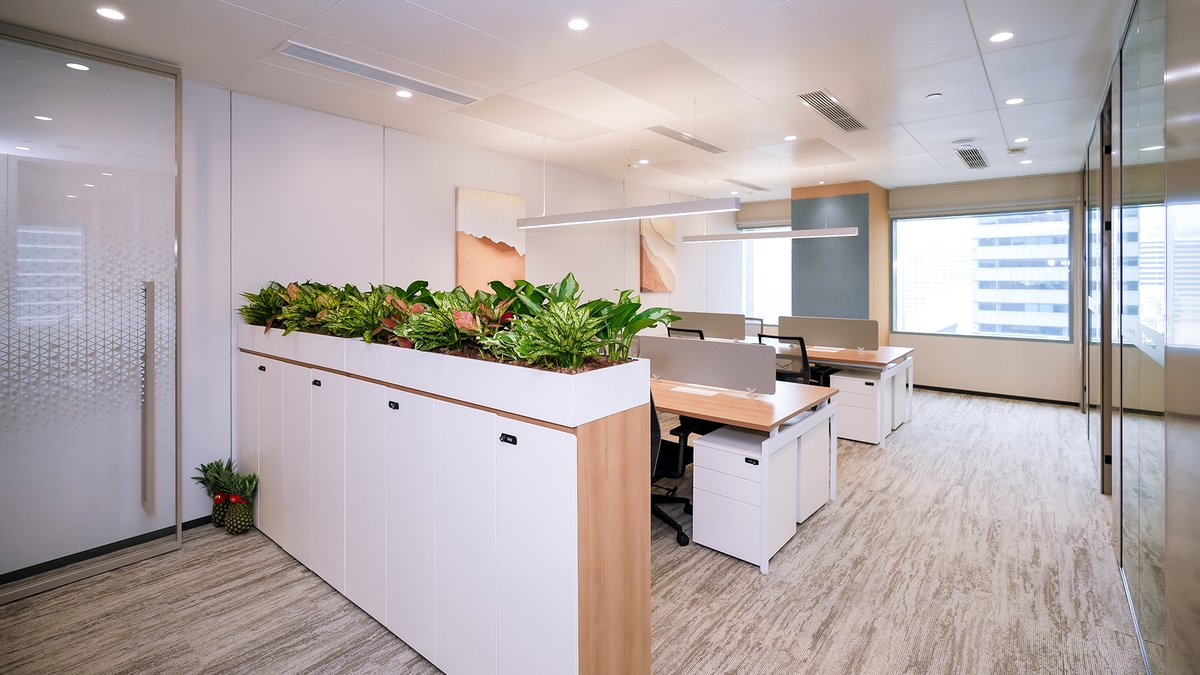
Fresh flowers filled the vibrant office, ready for the week ahead.
The hallway to the hub always welcomes you.
Glad you walked through.
#TokenPulse#AI#Singapore#Inference
A new pulse in Southeast Asia.
We just opened TokenPulse's APAC Operating Hub in Singapore. Thank you to every client, partner and investor who celebrated with us.
This is only the first beat.
#TokenPulse#Singapore
#Singapore, a new beginning.
Our new office at #TokenPulse is officially open!
It's a collaborative space where our team brainstorms, debates, and builds the future of #AI#inference.
If you're in town, drop by for a coffee.
Every system has a rhythm. The best ones you never notice.
“We heard the beat, and built everything around it.” Every token, a heartbeat.
TokenPulse — the heartbeat behind AI.
Watch the film here.
#TokenPulse#AI#AIInfrastructure#Inference
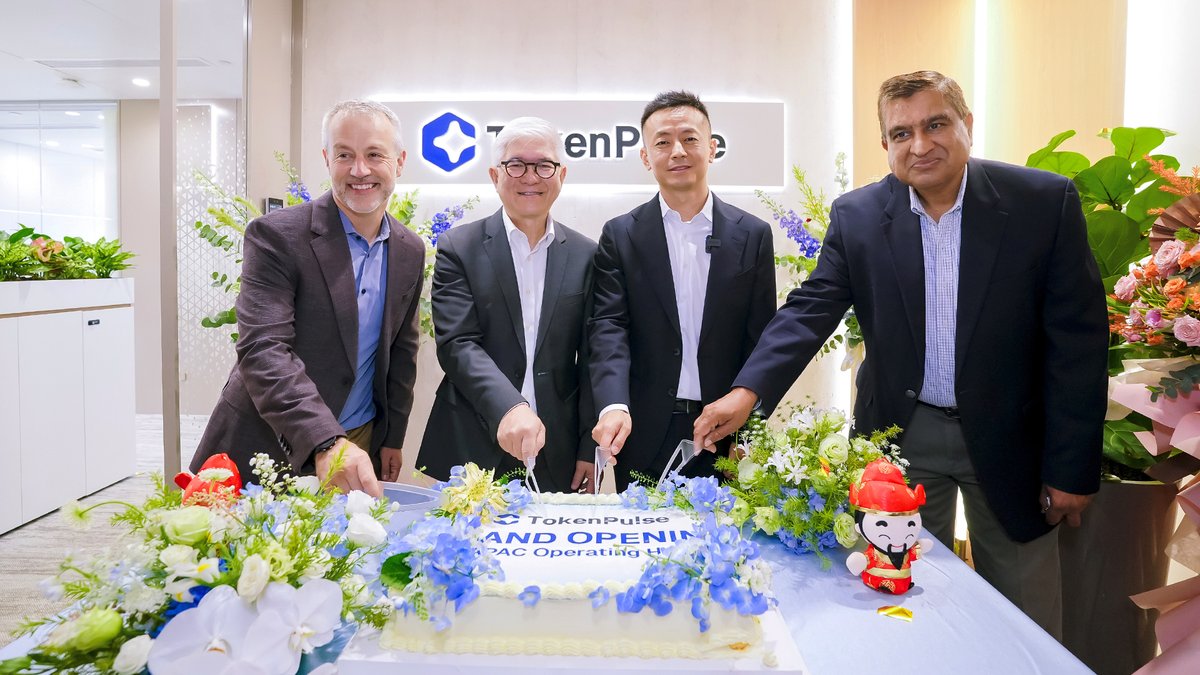
Big milestone. TokenPulse's APAC Operating Hub is officially open in Singapore.
Lion dance, logo lighting, cake cutting, with clients, partners, investors and our team. The energy said everything.
An office opening is day one. The commitment is what comes next. 🚀
#TokenPulse
Score the whole chain—accepted outputs, failure patterns, retries, completion time—not a benchmark number.
At TokenPulse, we start with the workload and what an acceptable result takes.
Which task needs the most capability?
Most AI workflows pay frontier prices for tasks a small model clears.
One workflow can hide field extraction, context summary, and ambiguous requests. One model for all of it? You may overpay on easy parts or underdeliver on hard ones.
What works: evaluate open-weight and closed models per task, not per workflow.
• A cheaper model earns the slot when it hits the task's quality and latency bar.
• Extra capability goes only where evaluation shows it changes the accepted result.
Meet TokenPulse.
AI inference infrastructure for high-performance, cost-efficient AI compute.
We combine GPU infrastructure, an optimized inference engine, and intelligent routing as we build a global inference network.
#TokenPulse#AIInference#GPU#LLM