4/5
For anyone training agents: self-report can't be the reward or the stop signal. The verifier has to look at the cut.
TimelineBench: 56 real editing jobs, scored against 43 professional editors.
Paper: https://t.co/w6zqAJ3Kt0
Leaderboard: https://t.co/GjtI2SQv4r
@CSProfKGD Give LLMs a reference and they’re exceptionally good at copying. We saw this while building TimelineBench. But reproducing a reference isn’t the same as solving a real-world task from a brief. That’s where they still struggle
https://t.co/w6zqAJ3Kt0
The performance review: Opus 5.5 in Claude Code resolved 18 of 56 real video-editing jobs.
Leaderboard: https://t.co/GjtI2SQv4r
Paper: https://t.co/w6zqAJ3Kt0
@GuninGupta907@NirmitArora26
@lennysan@tryramp Spot on! we need more evals to check an agent’s “done” actually means done. we observed the same while developing TimelineBench, agents claimed success on 93% of failed edits.
Paper - https://t.co/w6zqAJ3Kt0
Introducing TimelineBench: Evaluating Agents on Realistic Video-Editing Tasks, from Raw Footage to Final Cut
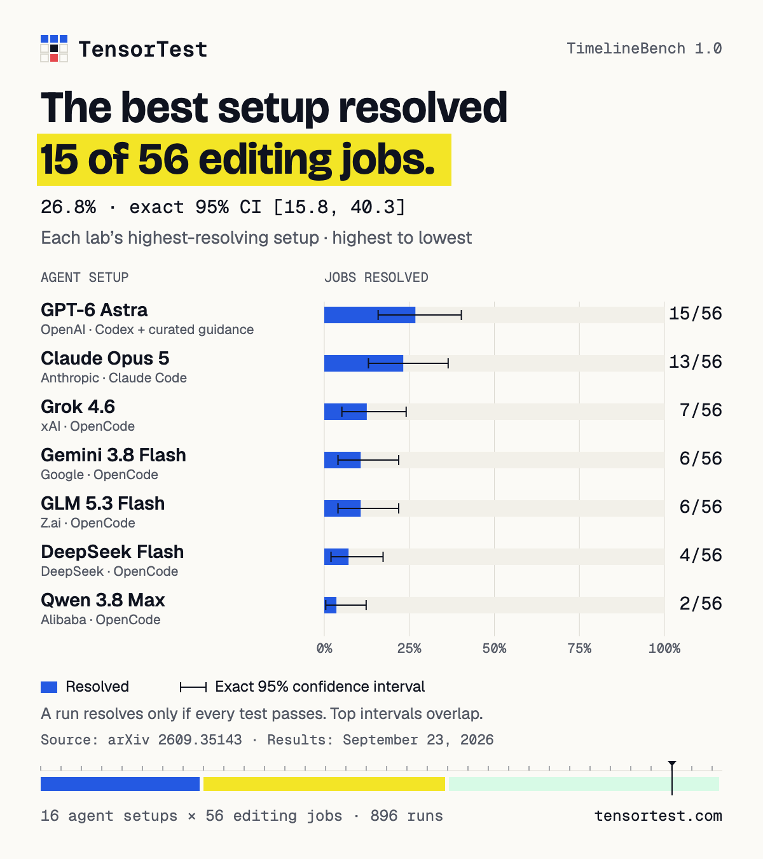
We tested 16 agents on 56 real video-editing jobs. The best passed just 26.8%
https://t.co/RmCUx8aroL