How far can 27B-31B models go on olympiad proofs without extra training?
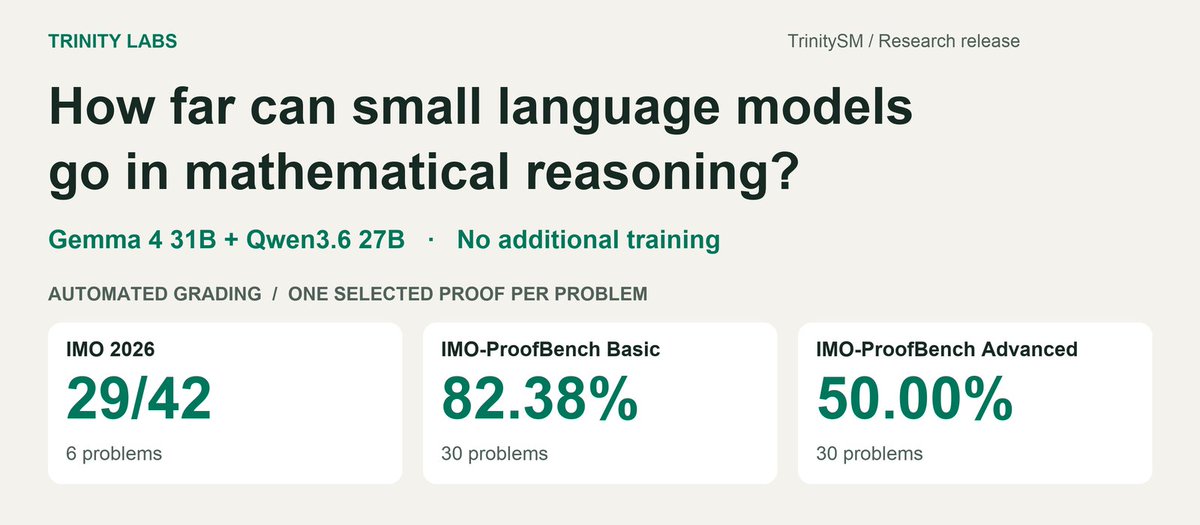
TrinitySM scored 29/42 on IMO 2026, matching the gold cutoff under automated grading, using Gemma 4 31B + Qwen3.6 27B.
Code, data & evaluation: https://t.co/sz10tp7eky
How far can small language models go in mathematical reasoning with a well-designed harness, without extra training?
TrinitySM reports 29/42 on IMO 2026 under automated grading.
https://t.co/sz10tp7eky
How far can 27B-31B models go on olympiad proofs without extra training?
TrinitySM scored 29/42 on IMO 2026, matching the gold cutoff under automated grading, using Gemma 4 31B + Qwen3.6 27B.
Code, data & evaluation: https://t.co/sz10tp7eky
How far can 27B-31B models go on olympiad proofs without extra training?
TrinitySM scored 29/42 on IMO 2026, matching the gold cutoff under automated grading, using Gemma 4 31B + Qwen3.6 27B.
Code, data & evaluation: https://t.co/sz10tp7eky
We'd value feedback on proof quality, evaluation and reproducibility.
Code is available under CC BY-NC 4.0, with third-party notices. Saved evidence can be inspected without a GPU.
https://t.co/sz10tp7eky
How far can 27B-31B models go on olympiad proofs without extra training?
TrinitySM scored 29/42 on IMO 2026, matching the gold cutoff under automated grading, using Gemma 4 31B + Qwen3.6 27B.
Code, data & evaluation: https://t.co/sz10tp7eky
IMO-ProofBench Selector@1:
Basic (30 problems): 82.38%
Advanced (30 problems): 50.00%
Saved proofs receive two automated grades. The repository includes rubrics, per-proof scores and selection records.
The idea: give existing models more opportunities to develop and examine a proof.
Four proof lanes, extended reasoning, structured reviews and three refinement passes. Gemma and Qwen play complementary roles. No additional training.