Next Wednesday, 28 October, we’re bringing a group of founders together for an open conversation about Europe’s role in AI: what we’re building here, what’s holding us back, and what we can do about it.
We’ll have a round table with @danipolymath from @SupersonikAI and Victor García from @NeuralTrustAI, followed by an open conversation where everyone can join in and ask questions. Then food and drinks.
The event will take place at @Itnig, in Barcelona.
If you’re interested, join via the link below!
https://t.co/KaKSWI6MIo
Evaluations: solved.
We’ve shipped Agent Score, a single number to track how your agents are doing over time.
Every day, it evaluates outcome, reliability, cost, speed, and safety out of the box. And you can extend it to look for any kind of signal specific to your use case.
Most eval systems are reactive and have incomplete coverage. We analyze 100% of your traces and give you actionable insights you can dispatch to your coding agents automatically.
Available now @trylatitude
Evaluations: solved.
We’ve shipped Agent Score, a single number to track how your agents are doing over time.
Every day, it evaluates outcome, reliability, cost, speed, and safety out of the box. And you can extend it to look for any kind of signal specific to your use case.
Most eval systems are reactive and have incomplete coverage. We analyze 100% of your traces and give you actionable insights you can dispatch to your coding agents automatically.
Available now @trylatitude
Wanted to share a great customer success we’ve had at Latitude with Tavi.
They run 75 personalised AI agent deployments, one per customer.
As that fleet grew, debugging each deployment separately stopped scaling. 🧵
Not enough people are talking about how Astra and specifically recurrent depth, while it is an amazing achievement, is a huge issue for reliable AI.
I have a lot to say, article coming soon.
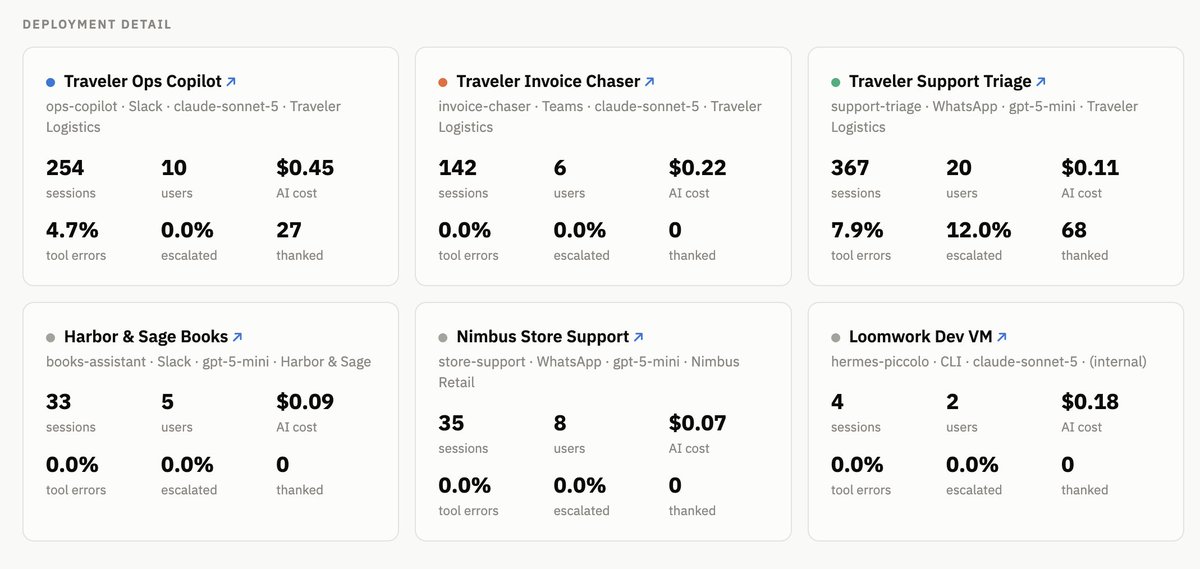
used the Latitude MCP to create a custom dashboard for a set of Hermes agents. pretty easy to see which ones have issues without doing much work.
@NousResearch
👋 Hey we're heading to Paris for the @aiDotEngineer conference on September 23-24, organized by @MistralAI!
Be the first to hear about our new Agent Benchmarks!
Memory observability is essential and its starting to get talked about now
Now you can observe it and how it evolves, to debug and assess potential pollution damage
Try it out now at @trylatitude
Gemini is chinamaxxing.
for those who don’t understand Chinese;
Responded with 这里 meaning “here” in Chinese when it was supposed to be the Czech “místě”.
Lots of comments about Raindrop's release yesterday.
Here are my thoughts in response:
- There's nothing in Raindrop's release that you can't already do with @trylatitude
- This is not true the other way around, see Behaviors (main reason customers are onboarding into Latitude nowadays).
- Latitude runs all its evaluations in a sandboxed scripting environment: you can freely combine code rules with semantic queries and llm judges in a single evaluation pass, that's the core strengh of our custom signals.
- Latitude does not use sol xhigh to run llm judges (because it's a stupid idea), we run cost optimized classification models that are probably a bit more expensive than Raindrop's custom classifier but not enough to suppose a meaningful difference.
- It's cool that they trained a custom classifier! We might do it, but it's not the current priority.
How can you find and fix a problem with your agent if you don't know where to look?
Pretty damn tricky.
Check this article out to see how we discovered a memory issue based on a complaint from a user.