Saying there’s no reason to buy Bitcoin because anyone can create a cryptocurrency is like saying there’s no reason to learn English because anyone can invent a language.
We believe voice is the most natural way to interact with intelligence, so we created Dessa, the most authentic full-duplex speech model ever built. Talking with it feels like talking with a person…full of emotion, nuance, pauses, and a natural cadence.
https://t.co/r0qFLdvd6c
🚨BREAKING: 4CHAN DEFEATS OFCOM
OFCOM have been trying to fine 4chan for months now as they refuse to comply with the online safety act
4chan are an American website and believe they should not have to comply with idiotic, censorious British laws
"This is the internet"
Well today 4chan won and OFCOM conceded defeat
Congrats to @prestonjbyrne and @4chan
OFCOM and the British Government are truly stupid
2 guys. 2 engines. 9 releases in 2 days.
@PeasantSmith shipped Project Maya 7 times since Sunday. 1M tokens of context on 1 RTX 3090. GLM-5.3 Flash at 53 tok/s on 2 of them.
@coldniko updated Strata last night: Mac support, new quant types and another 10 to 20% on top.
I feel it on my own rig every week.
Strata 2 weeks ago: 59 tok/s on 1 card. After 1 update: 70. Same card, same Qwen file.
Maya on GLM-5.3 Flash: 25 tok/s out of the box. After 1 calibration run: 58 on my 4 cards.
The model files dont change. The engines get faster every week. So your old card gets faster for free.
Nobody pays these 2 guys to do it. They do it because the weights are open and they can.
This is my favorite part of local AI. Not the models. The people who make them run.
GLM-5.3 Flash at 2 bits is not enough. At 3 bits its 125 GB and my 4x 3090 have 96.
So I made the quant in between WITHOUT QUANTIZING ANYTHING. And then I UNCENSORED all of them.
I looked at how Project Maya packs this model. An expert has 3 matrices, and they keep gate and up at 2 bits and give the down projection more. So I took @turboderp_’s 2 EXL3 quants and swapped tensors. Everything comes from 2.05 bpw, the expert down projections come from 3.05. EXL3 stores the bit width in every tensor, so it just loads. 49,536 tensors replaced, 0 requantized.
On my rig:
2.05 bpw: 79 tok/s, KL to BF16 0.121
my mix, 98 GB: 66 tok/s, KL 0.096
3.05 bpw: 43 tok/s, KL 0.047
The mix holds 256K context with vision and tool calls. 77% of the experts are in VRAM and the rest in RAM.
Then the refusals. I didnt touch the weights, its a 2.2 MB file and the engine removes the refusal directions while the model runs. Stock refuses 144 of 146 harmful requests. With the file its 0 in 438 answers, thinking on or off. The same file works on the 2 bit quant, on my mix and on Maya-M.
Show me another 320B model that runs at home, reads 256K, sees images, calls tools and never tells you no. ill wait.
the catch: the mix is not magic. A 3rd bit in down is about 17% better per byte than a 3rd bit anywhere else. I picked the point that fits my cards.
3 uncensored repos, 1 new quant, both engine forks:
Download now: https://t.co/SWAYquJfky
Tech companies trying to replace people with AI, only for people to start replacing tech companies with AI has gotta be the funniest plot twist of the century
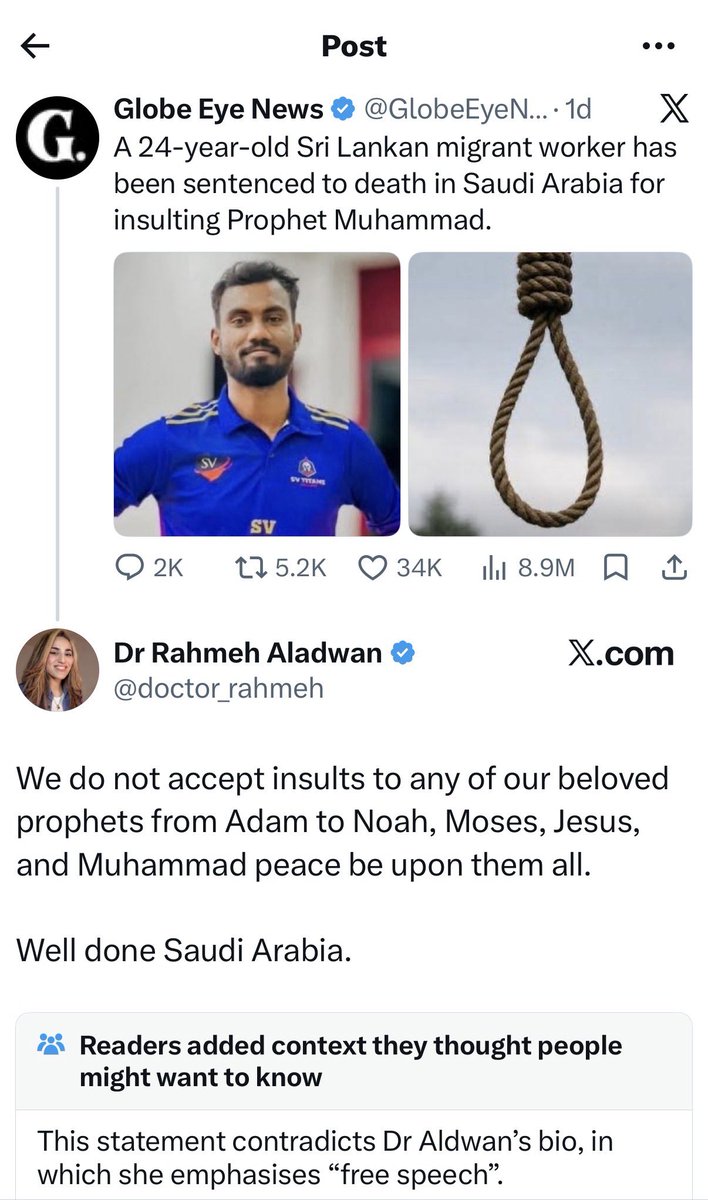
Despite proclaiming to support free speech….This NHS doctor appears to think it’s ok to be killed, due to your words.
We import more and more people with a similar mindset, into this country every single day.
What on earth have we done to ourselves.
🤯😩🤦🏼♀️