There is plenty more work to do! If you are excited about frontier model research, math/science capabilities, and a future where access to intelligence is not monopolised, please reach out — we're hiring. https://t.co/ptlORQFc8y
Proud to have worked on the best open-weights model outside China. Cliché but it's only the beginning: RL continues to climb and we will pick up the pace to stay competitive with upcoming releases. https://t.co/bCjInZUYNE
We also have cause to believe other scientific evals are flawed. https://t.co/zRYEaNmiEz identified errors in multiple physics benchmarks, and Anthropic have already reported that they use a corrected version of CritPt internally. Still, we gain 10% over Mistral Medium 3.5.
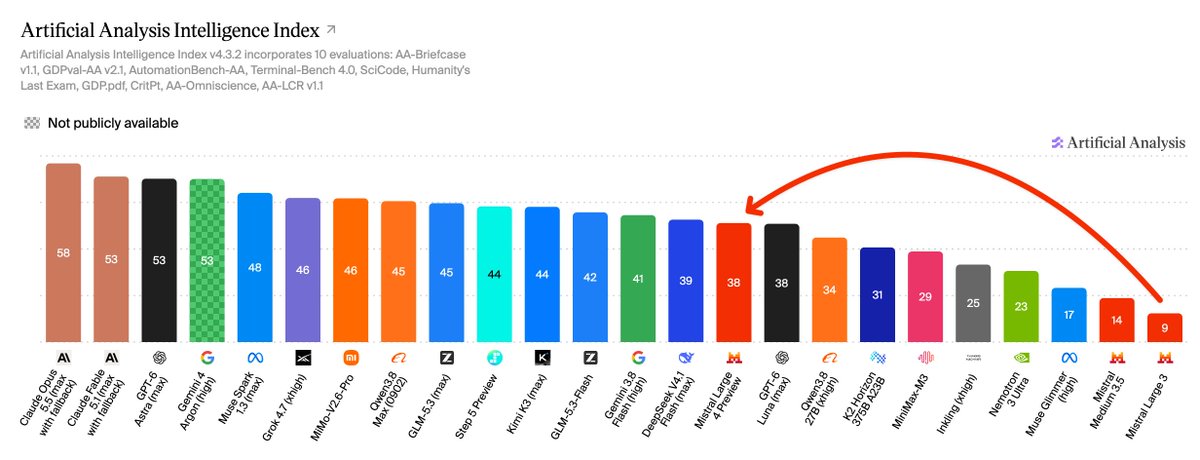
Mistral has released Mistral Large 4, scoring 38 on the Artificial Analysis Intelligence Index; France is back to having the most intelligent model from outside the US and China
@MistralAI has released Mistral Large 4 in Research Public Preview, with plans to release the weights of the 1T parameter (49B active) model at the end of October. It achieves 38 on the Artificial Analysis Intelligence Index, comparable to GPT-6 Luna (max, 38) and DeepSeek V4.1 Flash (max, 39). It also achieves 50% on the Artificial Analysis Cyber Index, level with GLM-5.3-Flash and ahead of models such as Kimi K3 and DeepSeek V4.1 Flash (max).
Key benchmarking results for Mistral Large 4 Preview:
➤ Most intelligent model from outside the US and China: Mistral Large 4 Preview scores 38 on the Intelligence Index, comparable to DeepSeek V4.1 Flash (max, 39) and GPT-6 Luna (max, 38). This makes it the most intelligent model from outside the US and China, ahead of countries such as South Korea and the United Arab Emirates
➤ Level with GLM-5.3-Flash on cyber defense capability: Mistral Large 4 Preview scores 50 on the Artificial Analysis Cyber Index, level with GLM-5.3-Flash (50) and behind MiMo-V2.6-Pro (56). Once its weights are released, it will rank among the top three open weights models on the Cyber Index. Its strongest result is on CyberGym-E2E-AA, where it scores 82%, ahead of MiMo-V2.6-Pro (79%) and GPT-6 Luna (max, 78%)
➤ Over 4x the Cost per Task of similar-intelligence open weights models: Mistral Large 4 Preview costs $1.13 per Intelligence Index task with standard pricing of $1.36/$4.18 per 1M input/output tokens, with $0.14 per 1M cached input tokens. For the first two weeks, Mistral Large 4 Preview will be served at a 50% launch discount, bringing its Cost per Task down to $0.57. This is still more costly than GLM-5.3-Flash ($0.25) and DeepSeek V4.1 Flash (max, $0.27)
➤ Strong document and image reasoning: Mistral Large 4 Preview scores 19% on GDP.pdf, on par with MiMo-V2.6-Pro (19%) and behind Kimi K3 (22%). This is an 18-point improvement from Mistral Large 3, partly driven by improvements in their API, which now accepts 100 images per request, up from 8 for previous Mistral models
Key model details:
➤ Context Window: 512k tokens
➤ Multimodality: Text and image input, with text output
➤ Pricing: $1.36/$4.18 per 1M input/output tokens ($0.14 per 1M cached input tokens), with 50% off for the first two weeks ($0.68/$2.09)
➤ Availability: Research Public Preview on Mistral's API, with open weights planned for the end of October
Meet Mistral Large 4, aka Le Chonk.
• 1T parameters, natively multimodal. 49B active.
It is the best open weights model from US or Europe on aggregated benchmarks.
• State-of-the-art on critical workloads, including cyber defense, manufacturing and finance and it surpasses closed frontier models on visual grounding.
• Forged in Europe end-to-end and is deployable from Europe via our own Mistral Cloud infrastructure.
• Available to all via API today. Working with cybersecurity partners privately.
Open weights release end of October.
Very pleased to share that I'm joining @MistralAI as an AI Scientist Intern, working with the reasoning team! Looking forward to applying my PhD work to real-world AI systems and collaborating with top researchers.
@sunnymbala There are plenty of extensions you could pursue, e.g., including metadata like the equity values of tiles in the prompt, fine-tuning on data from cross-tables, tool calling, RL, and so on!
@sunnymbala As a Scrabble enthusiast and AI researcher, I'm pleased to see this! I'd argue that two-player would be more representative of/compatible with competitive play and probably reduces noise (e.g., the endgame doesn't have perfect information otherwise).