Latest Llama 3.2 offers lightweight models + multimodal large language models that can see, reason, and understand
Model Size:
• Lightweight: 1B and 3B
• Multimodal: 11B and 90B
- Outperforms most open and closed multimodal models on industry benchmarks!
-Takes Llama 3.1 to the next level with vision adapters and cross-attention layers.
Key Use Cases:
• Visual Question Answering (VQA): Ask questions about an image and get accurate answers!
• Document Visual QA: Understand complex docs like maps and contracts through images
• Image Captioning: Generate captions that tell a story from visual data
• Image-Text Retrieval: Match images and descriptions seamlessly, like an AI-powered search engine
• Visual Grounding: Pinpoint specific objects in images through natural language
Flash Sigmoid Attention (SA) - 17% faster than Flash Attention (FA) 2
> Paper proved SA is a universal function approximator on seq-to-seq tasks
> Extend FA 2 with the sigmoid kernel, reducing kernel inference wall-clock time by 17% and real-world inference by 8%
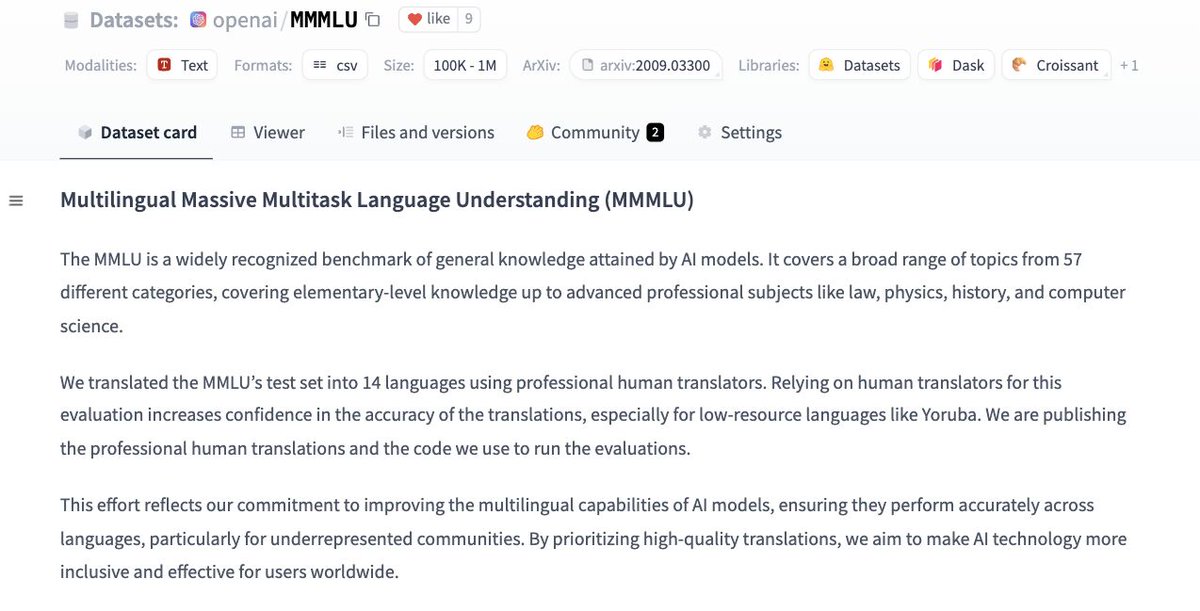
- MMLU test set available in 14 languages, translated by professional human translator
- Covers 57 categories from elementary to advanced professional subjects
- Evaluates AI models' general knowledge across diverse cultures, used in openai/simple-evals
Open #Dataset release by OpenAI! #OpenAI just released a Multilingual Massive Multitask Language Understanding (#MMMLU) dataset to evaluate multilingual #LLMs more easily!
Dataset: https://t.co/gC3qayrkKl