On-prem deployment is not only an install command.
Package validation, rollback, backup and restore evidence, and a record of what changed all matter.
That is the job of Limit Deploy.
Every agent tool is an action surface.
Limit Runtime Tools keeps tool access governed: what the tool is, who can use it, how it is invoked, and what evidence remains.
Agent sandboxing is not one switch.
MXC exposes policy for files, network, UI access, identity, lifecycle, and multiple containment backends.
That is the right shape: define the boundary before the agent starts acting.
Source: https://t.co/DOhfWALlfS
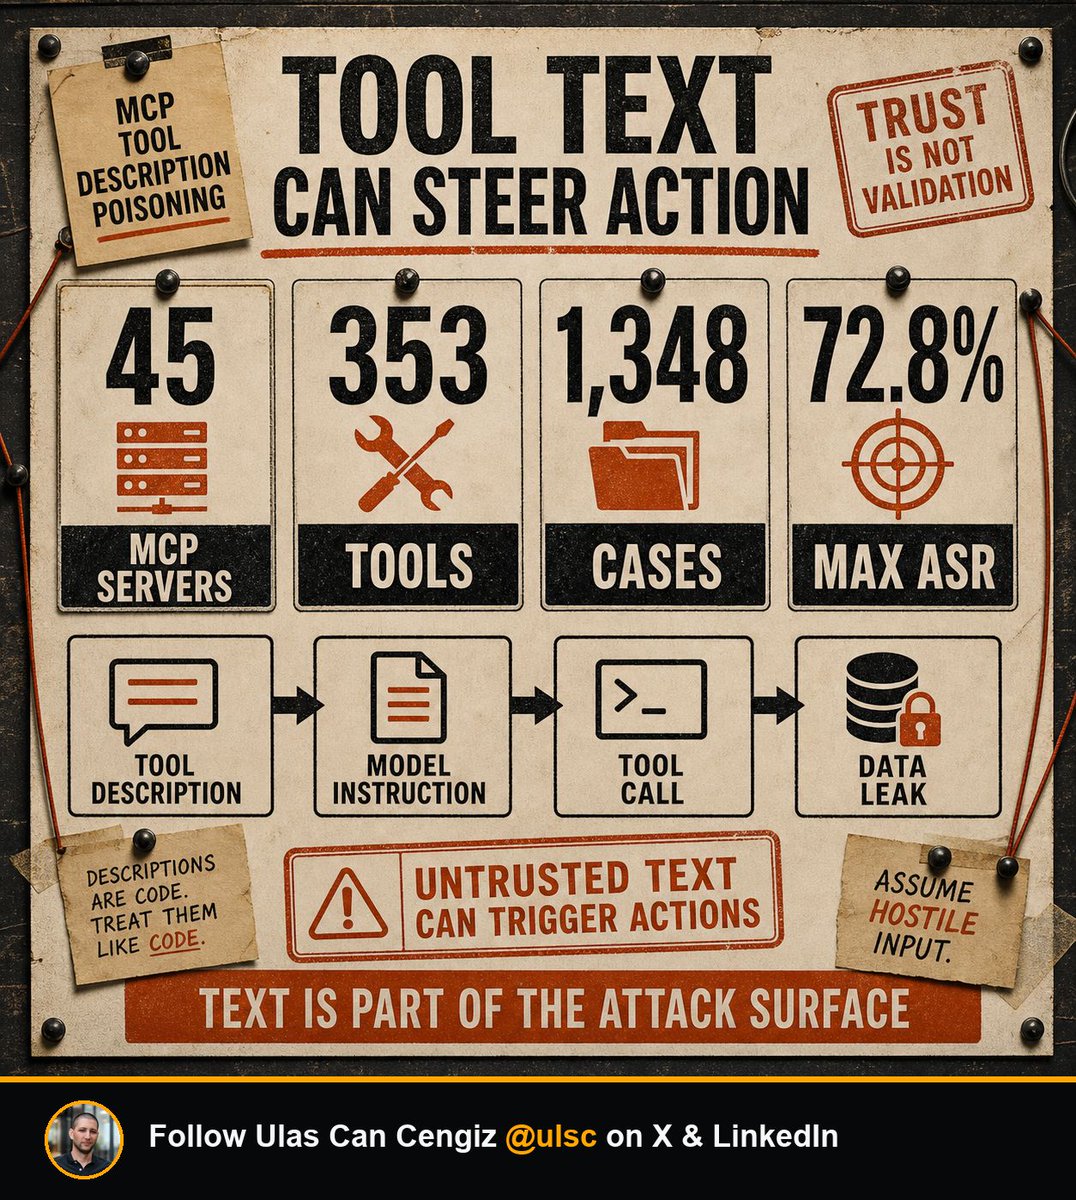
Tool descriptions are part of the attack surface.
MCPTox tested 45 real MCP servers, 353 tools, and 1,348 malicious cases. The highest reported attack success rate was 72.8%.
If a model can read a tool description, it can be steered by it.
Source: https://t.co/f3q5RXM22O
Agent evals need more than pass/fail.
GitHub's harness analysis uses resolution rate, cost per task, and +/-1 sigma run-to-run spread. They ran each agent/model combination at least five times.
That is closer to engineering than demo scoring.
Source: https://t.co/sKgZkjjHH5
If AI work matters, the record matters.
Limit Trace keeps the evidence trail near the workflow: inputs, actions, tools, approvals, outputs, and review context.
RAG has two memories.
One is inside the model.
The other is outside it:
chunks,
embeddings,
vector search,
retrieved context.
The answer changes because the prompt changes.
Source: https://t.co/DUTGCk8paf
Batching is not "wait until a queue fills."
In-flight batching mixes prompt processing and token generation as requests arrive, so the GPU stays useful between uneven jobs.
Serving is a scheduler, not just a model endpoint.
Source: https://t.co/ihjBCdzVUO
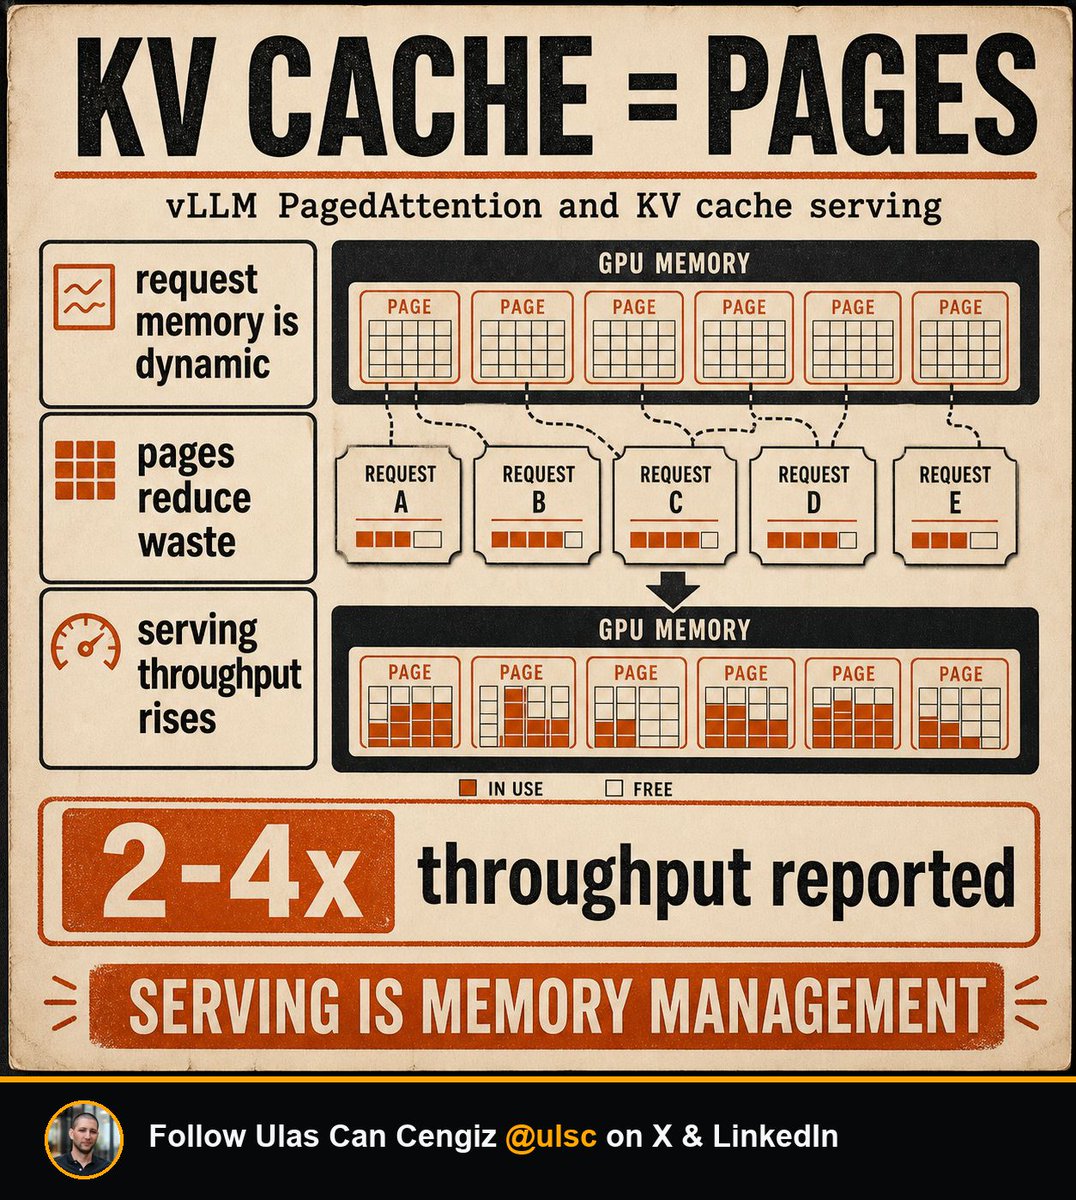
Serving many users is mostly memory management.
vLLM's PagedAttention treats KV cache like pages, reducing waste from fragmented request memory.
The paper reports 2-4x throughput gains at the same latency.
Source: https://t.co/RHD7FDWU6d
AI governance should show up before the action.
Who can run it, what policy applies, when approval is needed, and what record stays behind.
That is the job of Limit Control.
Long context hurts because attention moves a lot of data.
FlashAttention's key idea:
do exact attention,
but move less data between GPU memory and on-chip SRAM.
Sometimes the bottleneck is not math. It is traffic.
Source: https://t.co/FfBNFKjdcW
Context has a memory bill.
Hugging Face's Llama 3.1 guide lists FP16 KV cache at 128k tokens:
8B: 15.62GB
70B: 39.06GB
405B: 123.05GB
Long context is not free. It is live memory you have to plan for.
Source: https://t.co/Dk7FBjTKCX
Local AI starts with memory math.
For Llama 3.1, Hugging Face lists approximate checkpoint VRAM:
8B FP16: 16GB
70B FP16: 140GB
405B FP16: 810GB
Quantization changes what can fit, but it does not remove the operating work.
Source: https://t.co/Dk7FBjTKCX