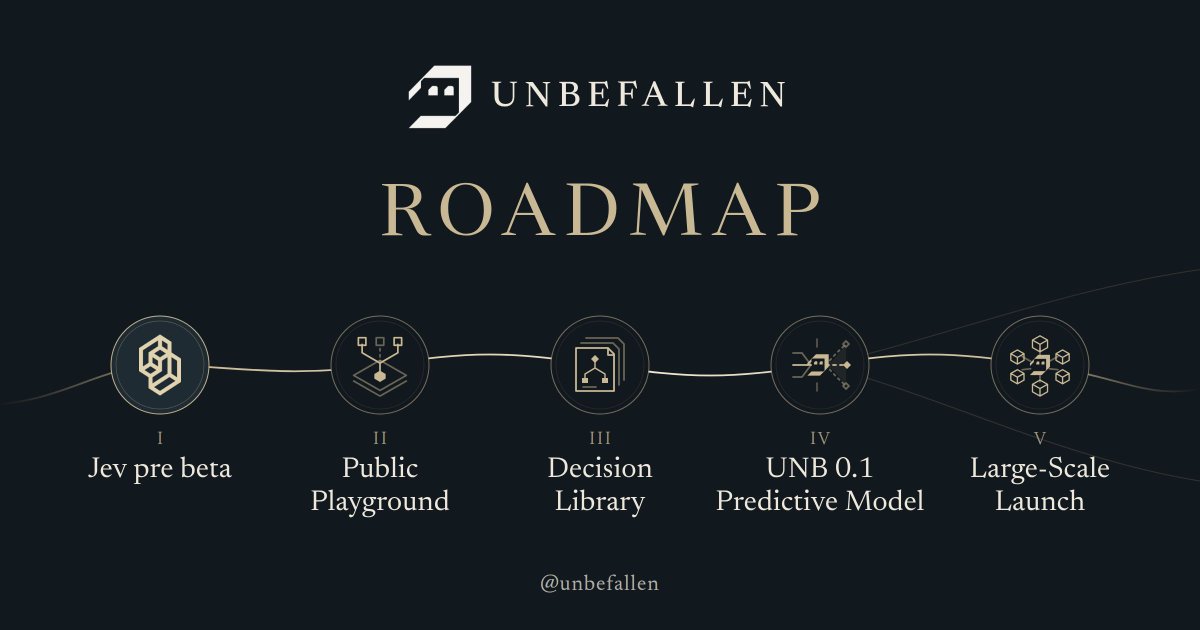
Roadmap
- Test Jev alongside other decision models during pre-beta
- Open the Public Playground
- Structure cases in the Decision Library
- Develop and evaluate UNB 0.1
UNB 0.1 is separate predictive model we aim to build through research and data-driven training.
Just Mosh it.
@WalkDog1984 We are building a predictive model that will be able to anticipate any events with a high rate of accuracy, all this by leveraging Uchronia (alternate history)
Stay tuned!
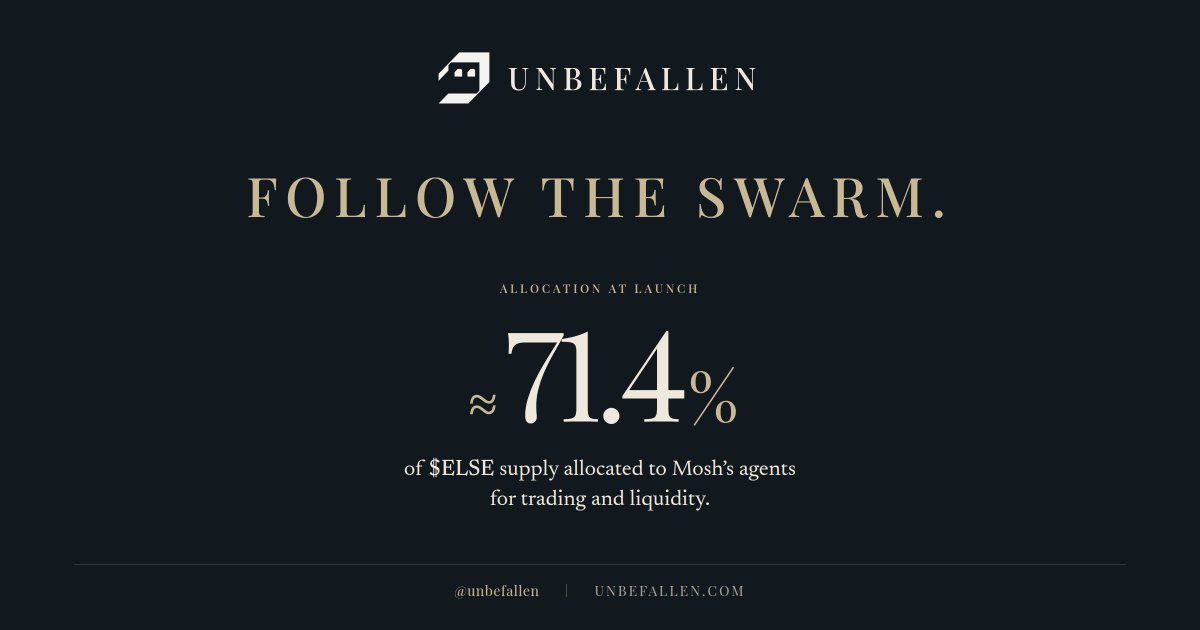
At launch, Mosh’s agent swarm received ~71.4% of the $ELSE supply to manage trading and liquidity.
$ELSE also graduated to be Mosh’s largest raise to date!
Follow the swarm live on @Moshdottrade and explore the tokenomics:
https://t.co/QZ4havKUbP
NOTA: We’re testing Jev in Unbefallen’s environment.
For this experiment, we use fictional Waterloo and London timelines and not live game sessions, to see how Jev handles claims against an established canon.
We’re testing Jev alongside Unbefallen..
In a separate lab, we give @typesafeai Jev a fictional canon and a short dispatch. We split the dispatch into claims and ask, for each one: Is the entire claim supported by this timeline’s canon?
Jev returns a score. Our code uses it to route the claim: a high-confidence result can receive a verdict; an uncertain one goes to a second verifier. If the check remains incomplete, the claim stays unverified.
Jev doesn’t write the dispatch, and its score isn’t proof that a claim is true. The question is narrower: did the dispatch add a fact the canon never established?
If peace negotiations began after an alternate Waterloo, “a treaty was signed” is still a new, unsupported fact.
We’re testing this with alternate Waterloo and London scenarios. Each run shows the canon, dispatch, claims, scores, routes and verdicts. These are demonstrations not live game sessions or a measure of accuracy.
Let’s hard fork history. What $ELSE can happen?