Ex-buyside/sellside. Spent years writing research nobody read on stocks everybody owned. Now writing research people actually want on stocks nobody covers.
@usedibs Good idea. Independent ranges are how you get a bull case on growth and a bull case on margins that can't both happen. Best fix is modelling the shared cause, e.g. LFLs driving both sales and operating leverage, so the link is built in rather than bolted on.
Great points, but I'd go a step further.
If I had the choice, the entirety of my modelling and forecasting would live in Python. Agents are native in code, git gives you full version history for free, and every driver can be a distribution rather than a point estimate.
I'd also question how long humans keep the edge on spotting patterns in the history. Agents can iterate through filings far faster than we can, and I suspect they'll get better than us at catching margin inflections or shifts in seasonality. The learning moves from keying in numbers to interrogating the agent's reasoning.
Which is where the front end matters. I don't think the answer is Excel with extra UI bolted on. It's a clean HTML output sitting on a Python back end, where you can click into any driver, forecast or assumption.
Click on FY27 revenue growth and out pops a driver card:
1. The forecast as a distribution, not a single number
2. The path: how the range has moved over time and what moved it
3. The evidence: management guidance, industry data, alt data, all cited
4. What agrees and what disagrees
5. A probability grounded in history, e.g. how often this company has actually delivered on guidance like this
Compare that to an Excel cell that says 8% with no reference to why it was modelled that way.
Excel probably survives as the export for colleagues who want a spreadsheet. It just stops being the engine and the interface.
imo it DOESN'T die, but bear with me on this
whether excel dies or doesn't die has been topic du jour in investing for at least the last 2 years and I wanted to weigh in
for me there are 2 sides to this:
1. Excel isn't the most natural tool for agents to model in. Making them operate cell by cell feels like square peg round hole (and we've tested this too). It can add errors, there's no version history, latency and cost are also an issue. This is SO important when you're doing it across hundreds of companies.
2. Excel is still the most natural way for humans to inspect this type of work. It's familiar, you can trace assumptions and you can send it to a collague who will very quickly understand it.
it might help to start with why we model companies, in my view it's for 2 reasons:
1. Understanding the history - building the model is part of learning the business. As you key in the numbers, you spot patterns, understand seasonality, notice margins falling or cash conversion improving. Every time you spot one of these patterns you go back to primary filings or other sources to understand why which drives the learning process.
2. Marking all of you implicit thoughts explicit - once you've learned about the business through historics, you set out on a question to learn everything you can about the company and take a view. All of these implicit thoughts need to be translated into explicit forecasts so 1) you can quantify your thoughts and 2) so it can be easily communicated to colleagues or clients.
I expect both of of these jobs to survive somewhat, but how they get done likely changes:
1. Agents do the construction and maintenance - modelling absolutely still exists, but I expect us to move from point in time updates to continuous updating done by agents when relevant information arrives which changes surfaced to the human where needed.
2. More of our thinking gets represented in the model and they become far richer - that 8% revenue growth forecast is an unnecessarily precise forecast for something we know in our head is a probability weighted range of outcomes. We already use scenarios and sensitivities, but maintaining that a written down version of your expected range of outcomes for every driver is impossible/exhausting and would look very messy. If this could be maintained by agents, I'd expect forecast quality to improve significantly.
FLY IN THE OINTMENT
In this new paradigm of modelling I'm going to want to:
1. Easily see the range of outcomes for each driver
2. See the full history of how that range has changed, when it change and what changed it
3. Do all of that without having to prompt my coding agent to tell me
So there really is a UI challenge here, excel is without doubt going to be the familiar form factor but I think the best in class tools for this will add additional UI to a UI which looks like excel at it's core but it's purpose built for agents and probabilistic, constantly updating models
(yes, I realised this is a meme account)
imo it DOESN'T die, but bear with me on this
whether excel dies or doesn't die has been topic du jour in investing for at least the last 2 years and I wanted to weigh in
for me there are 2 sides to this:
1. Excel isn't the most natural tool for agents to model in. Making them operate cell by cell feels like square peg round hole (and we've tested this too). It can add errors, there's no version history, latency and cost are also an issue. This is SO important when you're doing it across hundreds of companies.
2. Excel is still the most natural way for humans to inspect this type of work. It's familiar, you can trace assumptions and you can send it to a collague who will very quickly understand it.
it might help to start with why we model companies, in my view it's for 2 reasons:
1. Understanding the history - building the model is part of learning the business. As you key in the numbers, you spot patterns, understand seasonality, notice margins falling or cash conversion improving. Every time you spot one of these patterns you go back to primary filings or other sources to understand why which drives the learning process.
2. Marking all of you implicit thoughts explicit - once you've learned about the business through historics, you set out on a question to learn everything you can about the company and take a view. All of these implicit thoughts need to be translated into explicit forecasts so 1) you can quantify your thoughts and 2) so it can be easily communicated to colleagues or clients.
I expect both of of these jobs to survive somewhat, but how they get done likely changes:
1. Agents do the construction and maintenance - modelling absolutely still exists, but I expect us to move from point in time updates to continuous updating done by agents when relevant information arrives which changes surfaced to the human where needed.
2. More of our thinking gets represented in the model and they become far richer - that 8% revenue growth forecast is an unnecessarily precise forecast for something we know in our head is a probability weighted range of outcomes. We already use scenarios and sensitivities, but maintaining that a written down version of your expected range of outcomes for every driver is impossible/exhausting and would look very messy. If this could be maintained by agents, I'd expect forecast quality to improve significantly.
FLY IN THE OINTMENT
In this new paradigm of modelling I'm going to want to:
1. Easily see the range of outcomes for each driver
2. See the full history of how that range has changed, when it change and what changed it
3. Do all of that without having to prompt my coding agent to tell me
So there really is a UI challenge here, excel is without doubt going to be the familiar form factor but I think the best in class tools for this will add additional UI to a UI which looks like excel at it's core but it's purpose built for agents and probabilistic, constantly updating models
(yes, I realised this is a meme account)
Case study #2: Dempster Mill (Buffett, 1956–63)
Second in my series rebuilding special situations from famous investor letters. Last week was Sanborn Map. This one is messier and more instructive: the first company Buffett actually had to run.
The business
Dempster made windmills, water systems and farm equipment in Beatrice, Nebraska. Static sales, slow-moving inventory, almost no profit on the capital tied up.
The numbers
In 1956 the stock was $18. Book value was $72 a share, and net current assets (cash, receivables and inventory less every liability) were $50.
You were paying 36 cents per dollar of net current assets and getting the factory for free.
Five years of doing nothing
The stock went nowhere, so he kept buying. He joined the board. By mid-1961 he had about 30%.
In August and September 1961 he bought big blocks at $30.25 and tendered at the same price, taking the partnership above 70%. Average cost was around $28.
A stock that does nothing for years is a problem for most investors. For Buffett it was the opportunity, because it let him keep buying until he controlled the outcome.
What it was actually worth
Once you control a company, the share price stops mattering. What matters is what the assets fetch.
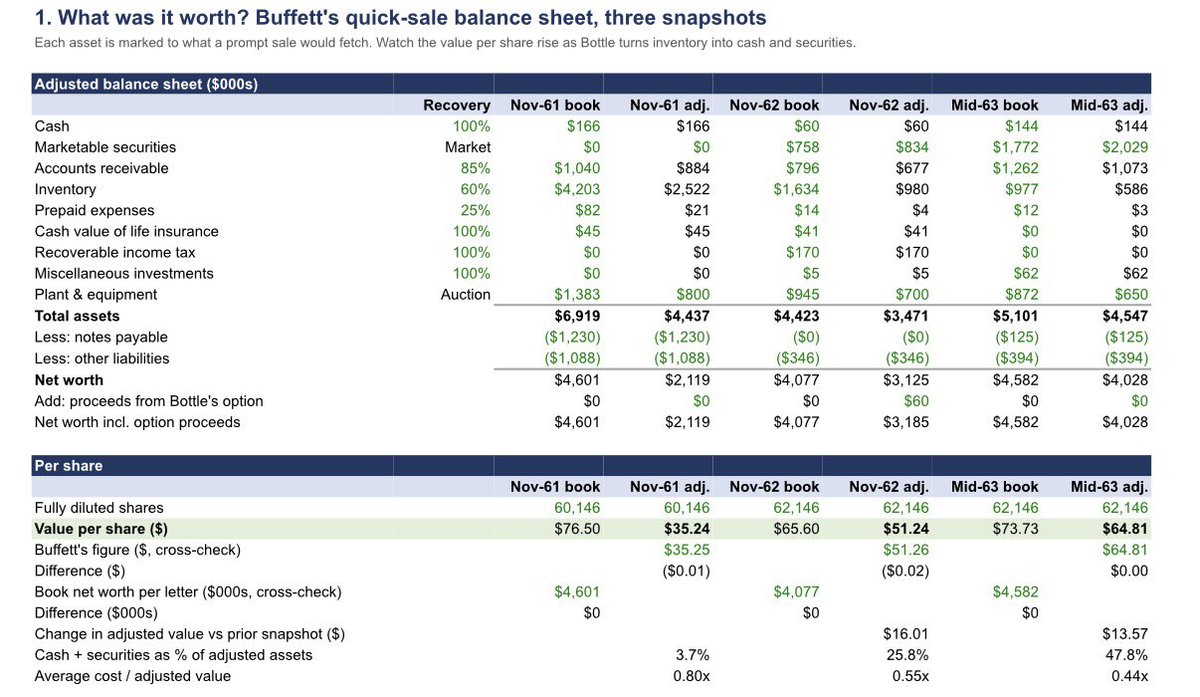
Buffett marked every line to a quick-sale value: receivables at 85%, inventory at 60%, plant at auction value. That gave $35 a share against his ~$28 cost.
Inventory was over 60% of book assets. I ran the numbers: it only needed to recover about 50 cents on the dollar for him to break even.
The management problem
He gave the existing team six months. Nothing happened. So in April 1962, on Munger's recommendation, he hired Harry Bottle, a turnaround operator who had never run an implement company.
In under two years Bottle:
1. Cut inventory from $4.2m to under $0.9m
2. Halved admin and selling costs to $75k a month
3. Cut factory overhead from $6 to $4.50 per labour hour
4. Closed five loss-making branches
5. Raised prices on repair parts. Farmers with a Dempster windmill had nowhere else to go, so it added ~$200k of profit with almost no lost volume
The admin cuts and parts repricing alone are worth about $1.1m a year pre-tax, or $17.70 a share, on a stock bought at $28.
Factory into portfolio
Every dollar Bottle freed up, Buffett put into undervalued stocks. Cash and securities went from about 4% of adjusted assets to nearly half.
Value per share using the same haircuts: Nov 1961: $35 Nov 1962: $51 Mid-1963: $65
My favourite detail: the partnership owned 71.7% of Dempster at a cost of $1.26m. By June 1963 Dempster's safe deposit box held $2.03m of securities. The partnership's share of that box alone was worth more than it paid for the whole stake.
The exit
Bottle restored earnings so fast the tax losses ran out early, so it was either de-incorporate or sell. In late 1963 the operating business was sold for roughly book value. With the portfolio gains, the partnership realised about $80 a share.
That's ~$2.3m profit on $1.26m, 2.8x the money, or roughly 54% a year from taking control (flattering, as it ignores the five years of accumulation).
What I'm taking from it
1. Buy at a big enough discount to liquid assets that heavy haircuts still leave you covered.
2. A stock doing nothing is fine if you're willing to keep buying.
3. The value was trapped in working capital. Releasing it mattered more than growth.
4. Management was the binding constraint. Same assets, different operator.
5. An installed base needing spare parts is a small monopoly.
6. Know how you get out. Tax decided the exit, not the share price.
Sanborn's value was already liquid and needed a structure to release it.
Dempster's was stuck in a warehouse and needed someone to get it out.
Next week: Northern Pipeline, Ben Graham's 1920s proxy fight.
Good post and I agree with most of it. A few things I'd add from the other side of the table.
The circular revenue point is right, but every capex cycle looks like this early on. One firm's spend is another firm's sales until end demand turns up and validates it, or doesn't. What I watch more closely is where the money is coming from. For most of this build-out the big spenders paid for it out of operating cash flow, which is a genuine difference from the late 90s telecom boom that ran on debt. That's changing. More of the marginal dollar now comes from bond issuance, private credit vehicles, leveraged neoclouds and vendor financing, where the chip supplier invests in a customer who then buys its chips. When the funding source changes, the risk changes, even if the revenue line looks identical.
The depreciation point is the one I'd underline twice. When the fibre boom blew up, the cable stayed in the ground and ended up carrying Google and Netflix traffic for a fraction of what it cost to lay. Investors lost their shirts but everyone else got cheap infrastructure. GPUs don't come with that consolation prize. They're economically obsolete within a few years, so an overbuild doesn't become cheap capacity for the next generation, it becomes a write-down. Which is why I pay a lot of attention to the useful life assumptions sitting behind reported earnings. Stretching server lives from four years to six flatters profits more than most people realise.
Where I'd push back a bit: big share price swings don't automatically mean the market is being silly. For long duration assets, a small change in the odds of a winner-takes-most outcome should move the value a lot. A 30% move with nothing new in the quarter can be perfectly rational. The question I ask is whether the move came with new evidence on what end customers will actually pay, or just a new capex number.
The last paragraph is the bit most people will skim past, and I think it matters most. The value capture question isn't confined to chips and data centres. It hits every business that sits on top of the internet today. Price comparison, reviews, travel booking, marketplaces. For them AI is either a big margin tailwind (cheaper service, cheaper content, cheaper engineering) or the thing that competes away the moat once agents start doing the searching and comparing for people. Probably both, depending on the company. A lot of money will be made and lost there over the next decade, and it gets a fraction of the attention of the next Nvidia print.
Plenty of people will be right about the technology. Far fewer will be right about who ends up keeping the money.
My thoughts on AI 👇
Frequently the story about AI seems to change completely. First the AI boom is supposedly over, then it’s just getting started. Meanwhile, stocks swing 20%, 30%, sometimes 50% in either direction, often after a single earnings report. Yet when you look at the underlying businesses, very little has actually changed in those few weeks. What changed was people’s expectations, and the market has a remarkable habit of treating changing expectations as new facts.
We’ve seen this before with railroads, electricity, the internet and nearly every revolutionary technology. People correctly understood that the world was about to change, but that didn’t mean they knew who would make the money. Being right about a technology and being right about an investment are two very different things. History is full of extraordinary innovations that produced disappointing returns for the investors who financed them, often because competition handed most of the benefit to customers.
And I don’t believe this time will be any different. Everyone has their favorite AI companies, the ones they believe are best positioned to dominate the future. And perhaps they’re right. But unfortunately, investing doesn’t work quite that simply. A company that looks absolutely extraordinary today can look like a terrible business five years from now, for reasons that even the smartest investors couldn’t possibly have anticipated. That’s the nature of capitalism. Competition, innovation and changing economics have a way of making fools out of even the most intelligent people. I think recognizing that uncertainty and occasionally eating a slice of humble pie is one of the most valuable things an investor can do.
Here is something about this moment that I think gets too little attention. In AI today, one company’s revenue is very often another company’s expense. When a large technology company spends billions on chips and data centers, that spending shows up as exciting revenue growth for the chipmaker and the cloud provider. The market celebrates the revenue. But for that dollar to be truly profitable for everyone, someone at the end of the chain, a business or a person, has to pay enough for AI to justify what everyone in the middle spent building it. Until that happens, much of what we call AI revenue is really AI investment wearing a different label.
So I think the most important questions are still largely unanswered. Who is paying for all this computing power, and is that money coming from real profits or from capital raised? How much of today’s growth comes from end customers, and how much is money circulating between companies that are simultaneously investing in, buying from and financing one another? And will the enormous investments being made today earn attractive returns before the chips inside these data centers are worn out or overtaken by new ones?
These questions will decide who wins and who loses. A stock can rise 40% while its long term economics deteriorate, just as it can fall 40% while the business becomes more valuable. Neither move tells you much about what the company will earn ten years from now. The market changes its opinion constantly, but the economics of a business change slowly.
I believe AI will transform the world, but that alone tells me very little about which stocks will be good investments. The internet changed virtually everything, yet many of the companies that built its infrastructure never earned an adequate return on the money they invested. The winners weren’t necessarily the ones that spent the most, but the ones that eventually captured the most value. And some of tomorrow’s biggest winners may be companies we’re barely paying attention to today.
So the next time AI stocks soar or collapse, it’s worth asking yourself two questions. Did the economics of these businesses actually change, or did the market simply change its mind? And how much of what I believe about the future do I actually know?
🌹
My thoughts on AI 👇
Frequently the story about AI seems to change completely. First the AI boom is supposedly over, then it’s just getting started. Meanwhile, stocks swing 20%, 30%, sometimes 50% in either direction, often after a single earnings report. Yet when you look at the underlying businesses, very little has actually changed in those few weeks. What changed was people’s expectations, and the market has a remarkable habit of treating changing expectations as new facts.
We’ve seen this before with railroads, electricity, the internet and nearly every revolutionary technology. People correctly understood that the world was about to change, but that didn’t mean they knew who would make the money. Being right about a technology and being right about an investment are two very different things. History is full of extraordinary innovations that produced disappointing returns for the investors who financed them, often because competition handed most of the benefit to customers.
And I don’t believe this time will be any different. Everyone has their favorite AI companies, the ones they believe are best positioned to dominate the future. And perhaps they’re right. But unfortunately, investing doesn’t work quite that simply. A company that looks absolutely extraordinary today can look like a terrible business five years from now, for reasons that even the smartest investors couldn’t possibly have anticipated. That’s the nature of capitalism. Competition, innovation and changing economics have a way of making fools out of even the most intelligent people. I think recognizing that uncertainty and occasionally eating a slice of humble pie is one of the most valuable things an investor can do.
Here is something about this moment that I think gets too little attention. In AI today, one company’s revenue is very often another company’s expense. When a large technology company spends billions on chips and data centers, that spending shows up as exciting revenue growth for the chipmaker and the cloud provider. The market celebrates the revenue. But for that dollar to be truly profitable for everyone, someone at the end of the chain, a business or a person, has to pay enough for AI to justify what everyone in the middle spent building it. Until that happens, much of what we call AI revenue is really AI investment wearing a different label.
So I think the most important questions are still largely unanswered. Who is paying for all this computing power, and is that money coming from real profits or from capital raised? How much of today’s growth comes from end customers, and how much is money circulating between companies that are simultaneously investing in, buying from and financing one another? And will the enormous investments being made today earn attractive returns before the chips inside these data centers are worn out or overtaken by new ones?
These questions will decide who wins and who loses. A stock can rise 40% while its long term economics deteriorate, just as it can fall 40% while the business becomes more valuable. Neither move tells you much about what the company will earn ten years from now. The market changes its opinion constantly, but the economics of a business change slowly.
I believe AI will transform the world, but that alone tells me very little about which stocks will be good investments. The internet changed virtually everything, yet many of the companies that built its infrastructure never earned an adequate return on the money they invested. The winners weren’t necessarily the ones that spent the most, but the ones that eventually captured the most value. And some of tomorrow’s biggest winners may be companies we’re barely paying attention to today.
So the next time AI stocks soar or collapse, it’s worth asking yourself two questions. Did the economics of these businesses actually change, or did the market simply change its mind? And how much of what I believe about the future do I actually know?
🌹
@MattJMcClintock Agreed. As a standalone business it'd be a distraction, and card economics are tough when Fanatics owns the licences. As a hook to get people into stores on launch day, I think it's clever.
Worth reading the original LinkedIn post before piling in. It's a "what if" from someone who works in trading cards. As far as I can tell Nike hasn't announced a card product, and that box looks like a mock-up of where she thinks this could go.
The more interesting bit is .SWOOSH itself. It launched in 2022 as Nike's NFT platform, which most people wrote off. It's now the team that ran the One Piece collab: three Air Max Plus pairs based on Devil Fruits, TCG cards handed out with in-store purchases and matched to the colourway you bought, a Wanted poster printed inside the shoebox, and pop-ups in nearly two dozen cities.
That's cards as a way to sell shoes, which is a very different thing from cards as a new category. Costs almost nothing, gives people a reason to turn up on launch day, and the product stays scarce.
I'd also push back on this being what blows out the brand. The damage over the last few years came from volume. Dunks, AF1s and Jordan 1 Lows everywhere, then sitting in discount bins. Limited drops built around a story work the other way round.
If Nike did go further into cards, the obstacle is licensing. Fanatics/Topps hold the NBA, NFL and MLB card rights, so no team logos. Nike's edge would be its athlete contracts, or more likely a co-brand with Fanatics, who already make Nike's MLB uniforms.
None of this moves the P&L on a mid-$40bn revenue base. Matt's right that the fix is product: running, innovation, getting the big franchises healthy again. I just don't think a box of cards, real or not, is what's standing in the way.
Why can't $NKE just go back to making great product? Why are they so stupidly focused on expanding into every possible category just to blow the brand out even more than it already has been blown out? What is next, a Taco Bell collaboration?
Most cyclical work is triangulation: suppliers on lead times, customers on destocking, competitors on capacity, all layered on top of PMIs, pricing and trade data. That's broad, repetitive cross-referencing, which is what agents are good at. They don't need to call the cycle. They only need to flag a tightening balance a quarter before it shows up in consensus.
But the money in cyclicals usually isn't made by spotting the data first. It's made by acting on it early, against consensus, sizing it properly, and holding through two quarters of looking wrong. Sizing is arguably where machines beat humans too, since we're notoriously bad at it.
There's also a second-order effect. If everyone's agents read the same transcripts, the 'early' signal gets priced faster and the edge decays. What's left is proprietary checks, niche physical-market data, and behaviour.
This is the problem I’ve been trying to build around. Rather than one agent hunting for answers, the idea is an interconnected system. Every transcript, filing, trade release and price series gets ingested and linked across companies, suppliers, customers and end markets. That way a throwaway comment from a customer in one industry surfaces as a flag on a supplier three steps up the chain. It's a living map of the cycle rather than a stack of separate models.
The system reads, links and flags on its own, and rules-based sizing keeps the risk honest.
My guess is cyclicals end up less insulated on detection and more insulated on action. Agents compress the time a tightening stays mispriced. The residual edge is having the stomach to be early.
Have been thinking about AI in institutional investing processes and growing use of agents etc. At some point in my career touched every sector (to a degree) outside of fins and HC. Ironically feels like the most insulated space to AI-driven trading is cyclicals and proper supply/demand cycles. Yes, they’ll catch the EPS revisions up and down but harder to see how they take strong views on harder to forecast set of outcomes.
Have been thinking about AI in institutional investing processes and growing use of agents etc. At some point in my career touched every sector (to a degree) outside of fins and HC. Ironically feels like the most insulated space to AI-driven trading is cyclicals and proper supply/demand cycles. Yes, they’ll catch the EPS revisions up and down but harder to see how they take strong views on harder to forecast set of outcomes.
I think the more interesting development here isn’t that AI can now build financial models. It’s that AI is beginning to absorb the analyst’s entire working environment.
But there’s an important distinction between automating financial analysis and automating investment research.
Building a DCF, populating a model and producing a presentation are increasingly mechanical tasks.
The harder problems remain knowing which data to trust, reconciling conflicting sources, identifying accounting distortions, questioning management’s narrative and, ultimately, knowing what is actually mispriced.
Connecting an LLM to FactSet or Capital IQ solves a data access problem. It doesn’t automatically solve data integrity or analytical judgment.
And a perfectly constructed model can still produce a completely wrong investment conclusion.
I suspect the real battleground will be the intelligence layer sitting above the applications and data providers: a system that understands the relationships between companies, industries, historical events, operating metrics and investment hypotheses.
In other words, not simply an AI analyst that builds spreadsheets faster, but an interconnected research system that knows what to investigate, where to look and which assumptions to challenge.
That’s a considerably bigger opportunity than automating Excel.
This is a much bigger development than another AI spreadsheet announcement. Anthropic is trying to own the workflow, not just sell access to an AI model.
And there is an important distinction in the announcement: Claude for Excel has been developing since 2025, while Claude Sheets is the November 10, 2026 launch. Anthropic +1
Why this matters
1. Microsoft is being challenged at its strongest point. Excel is the operating system of financial analysis. If Claude becomes the interface analysts use, Microsoft risks losing part of the customer relationship.
2. Financial data vendors become suppliers. FactSet, LSEG, Moody’s, PitchBook, Morningstar and S&P Capital IQ can supply data directly into AI workflows. Anthropic +1
3. The research process is being compressed. Data collection, cleaning, modeling, analysis and presentation are moving into one environment.
4. The real competitive threat is to financial research software. Why pay for five different interfaces if an AI assistant can access the underlying data?
But here’s the problem I keep coming back to.
Claude can build a beautiful spreadsheet.
It can write formulas, clean data, extract financial statements and construct a DCF.
But can it establish that the underlying numbers are correct?
Can it distinguish reported results from management adjustments? Can it catch an accounting change, an incorrect historical data point, or an off-balance-sheet liability?
And can it tell an investor when the conclusion is wrong?
Building a financial model is not the same thing as producing investment research.
That’s the distinction the entire AI financial services industry needs to understand.
My bigger takeaway: Anthropic is moving up the software stack. The next battle isn’t ChatGPT versus Claude.
It’s who owns the analyst’s workflow, the data, and ultimately the decision.
And that is a much more interesting fight than another model benchmark.
Primary announcement: Anthropic: Claude Sheets, Whiteboards and Data · Financial services strategy: Anthropic financial services agents
Agree. In the short term everyone is adopting similar tools at the same time, so crowding looks like the obvious risk.
Longer term, my guess is the edge moves to time horizon. If AI shrinks the information advantage and makes everyone react faster, the scarce thing becomes being willing to hold through the noise. That might end up being the most durable "style" of the lot.
Enjoyed the exchange, good piece.
No, I don't think we can. A fair chunk of the value cycle has always been structural rather than fundamental. Value funds bleed assets near the bottom, LO managers hold on to their framework long after it stops working, consultants move money between style boxes, and that forced selling creates the overshoot that later reverses.
Take those constraints away and the swings probably get smaller. Cheap stocks get bought earlier by people who aren't labelled "value", so there's less of a gap left to close.
I'd split the premium in two, though. The part that's compensation for real risk (distress, leverage, cyclicality) should survive in some form. The part that came from how capital was organised is the bit at risk.
The other possibility is that it doesn't smooth out at all. If everyone is running similar models off similar data, they could all rotate at the same time. Then you get fewer slow cycles and more sharp, crowded ones.
Not sure which way it goes. Which do you think is more likely?
agree with everything you've said here. one complication is the basis of mean reversion for those particular styles
huge question whether factor rotation happens in the same from from growth/momo to value if people are no longer anchored to those styles
if part of that cycle comes from how people are categorised, where capital gets allocated and how LO managers particularly stick with their framework, loosening those constraints could change the cycle itself
rates and fundamentals would obvs still matter, but 'value will have it's turn again' assumes enough of the old market structure survives
i'm not sure we can take that for granted can we?
Good piece. One angle I'd add is style drift, and value in particular.
For years the defence of a value tilt was patience. It's out of favour, it'll come back, stick with it. That gets a lot harder to argue once anyone can break your returns down and show what was really driving them.
A lot of what we call value, quality and growth ends up being a view on rates. Growth and quality did brilliantly when money was free, because long-dated cash flows were worth more. Value lagged for most of the 2010s, then had its moment in 2022 when rates went up.
The definition of cheap has moved as well. Price to book made sense when companies were factories and inventory. It makes much less sense when most of the value sits in software, brands and R&D that never shows up on the balance sheet. A screen built on old accounting will keep finding the same sectors and keep calling them cheap.
So if the regime has clearly changed, I think a value manager owes investors an explanation of what value means for them now, instead of waiting for the old version to work again. That's drift, but it's drift you can explain.
The risk runs the other way too. When research on everything is cheap and fast, it's very easy to talk yourself into whatever's been working. Plenty of drift is just chasing performance.
So the bar goes up on both sides. If you stay put, you need a better reason than "it'll mean revert". If you move, you need to show it came from your process and not from last year's returns.
AI will force investors to justify their specialism.
When research is autonomous and everyone can look at everything with specialist depth, rigid investment styles become a lot harder to defend. https://t.co/SGHQNMXLZh
@BoringBiz_ His Musk commentary has drifted from analysis into personal animus, and it's starting to cloud his judgment. The theatrics don't help them.
Great addition. You don't need pods sharing factor bets for this to bite, just a slight lean the same way. Across 100 pods at 80% idio, an average 5% correlation in their factor exposures takes the firm to roughly 40% idio.
The allocation model compounds it. Pods that win often win partly on factor tailwind, and capital follows winners, so the firm's aggregate tilt drifts towards whatever has worked. That's usually what's about to be crowded. Add the first thread's point that some measured "idio" is really shared exposure, and true firm-level idio is lower still.
The other major dynamic is that most aggregate multimanager portfolios are solidly less neutral across even traditional factors than people think, so as a result many multimanagers end up in part running large levered factor portfolios.
The reason is that even if you force every PM to run at 80%+ idio, the remaining 20% factor variance in each pod’s book is often long similar factors (momentum, beta, growth, & the latest winning industry bet).
The issue is that while idio diversifies across the number of bets, factor bets compound, so while idiovol is mathematically collapsing in proportion to (the sqrt of) breadth in % terms, factor vols are staying right where they started — so even if you have every PM in the 80s idio, the aggregate firm book might be 30-50 idio before central hedging.
Firms can and do put on factor hedges, but the problem is netting given the magnitude you need for the hedging to be effective: who takes the P&L of any losses in the factor hedges? Some PMs don’t like being required to be at an idio constraint in the first place, and then forcing factor hedges into a PM’s book on top of that can create friction. There can be complex hedge P&L allocation rules and much more, which are ultimately more political and talent questions than they are objective risk management decisions.
And to add a layer, one of the verticals many firms now compete on for talent has become how tight/loose risk limits are. PMs want the best risk tooling to avoid missing something, but often want the most flexibility to manage risk in the way they want to at each point in time. But the math discussed above only gets harder at a firm level if PMs can individually be in the 60-70 idio range or below.
So while people think of the growth of multimanagers as the growth of truly factor-neutral gross, in reality it is also the creation of large, levered factor portfolios that often are doing their best to translate individually tight PM books and in a competitive talent market manage aggregate firm factor and netting risk to a reasonable place on the utility curve.
This isn’t to say getting a multimanager book to truly low factor vol can’t be accomplished, but it is much more a function of people & process management, political capital, talent dynamics, and day to day execution.
All of the other dynamics are super important as well - modeling crowding, thematics, imperfect factors and constantly changing correlation structures & market environments: ultimately managing risk is managing any source of correlation/concentration - but it’s worth highlighting that even the basic management of core factor exposures is harder at scale to accomplish than it might seem.
And then the same mathematical effect that happens from pods vs their multi-manager parent is effectively happening across the market, as the many multi-managers (with growing AUM) feed into the broad market -- individually manageable risk exposures can mean the aggregate exposure is more levered to factors than the individual components appear.
All of which is also against the backdrop of what has recently been steadily rising factor volatility marketwide (for many reasons), which makes all of these dynamics more impactful to every kind of portfolio (tightly risk managed or not) than it has ever been.
Read an interesting piece from Fundamental Research Labs on whether AI agents can forecast earnings better than the Street. They ran it live through Q3 on 212 companies, and the agent came in closer than consensus on 158 of them.
My first reaction was that this is mostly the beat bias. Consensus nearly always ends up a bit low, and the authors say as much themselves. Bumping every estimate up by about 5% would have done roughly as well on the headline number.
The more interesting part is where the agent strayed a long way from consensus. It was usually closer, and the reasons were fairly unglamorous. Boeing had already published its deliveries. Progressive puts out its combined ratio every month. Some of it was read-across from peers. None of it was hidden, it just hadn't been joined up.
Most of what moves a number is already out there somewhere, scattered across filings, monthly releases, a competitor's call, a supplier's commentary. An analyst covering a dozen stocks can only hold so much of that in their head. An agent doesn't have that limit, and it can connect something in one company's data to another company's earnings.
So maybe the market is slowly turning into something like one big interconnected brain, where each piece of public information gets linked to everything it touches. If that's where we're going, having the information stops being the advantage, because everyone's agents will be reading the same map. What matters is how well you map it. Knowing which connections actually matter, and adding the things that never make it into a filing: what management said in the room, what customers are really doing, where the business will be in three years.
It also makes me wonder what a beat means if the number gets harder to sandbag. If consensus starts reflecting everything that's public, maybe the market cares less about the headline beat and more about what has actually changed.
The question I find hardest is how people build that judgement. Most of us learnt it by spending years doing exactly the model work that's being automated. I'm not sure what replaces that apprenticeship.
There's plenty in the paper to be cautious about, and the strongest test was a backtest rather than live. But I suspect this is where things are heading.
Worth a read
Can AI forecast earnings better than Wall Street pros?
In this new blog post, we show that AI agents can forecast earnings per share (EPS) better than the Wall Street consensus by reasoning about business fundamentals
EPS is one of the most important metrics about public companies, and the Wall Street consensus comes from expert sell-side analysts
But: the Street consensus systematically underestimates real EPS, so a simple heuristic like increasing the Street number by 5% would do well too
Our key finding is that AI agents outperform the Street consensus by *understanding* the business fundamentals, and making adjustments to the financial models that are company-specific
So not just a cheap heuristic
I think this is some of the first serious evidence that AI can really understand company finance well enough to make decent forecasts
Most of the work done by the fantastic @mishhman
https://t.co/52GfFAnrrJ
Good thread doing the rounds on pod risk. A few thoughts.
A risk model can only neutralise what it can name. Everything else (the theme, the crowd, the fact that a stock is simply useful to own in a pod book) sits in the residual and gets called alpha. For years that was mostly true stock-picking. As multistrat capital has grown and the talent pool has converged, more of that residual is shared exposure that nobody's model treats as a factor.
The risk management itself is what turns that into a drawdown. Tight stops make each book safe on its own. But when hundreds of books with similar limits and similar positions hit those stops in the same week, the stop-loss is what spreads the losses. Crowding isn't invisible either: everyone has the PB overlap reports. The problem is that everyone has the same reports, so the exit is as crowded as the entry.
You see it most clearly in European small and mid caps. Liquidity is thin, so around results the price is often set by positioning rather than by the numbers. A modest miss on a crowded long does damage the fundamentals don't justify, and the same happens in reverse on a crowded short. That isn't a broken market. It's a factor nobody is pricing.
So who breaks? Not the top platforms, with their multi-year lockups, the best people and first call on capital. It's the second tier: shorter-dated capital, adverse selection in hiring, and drawdowns that turn into redemptions. Which is roughly what October looked like.
In honor of some “pods blowing up” and me being traveling I will outline some concepts about pod risk management about which I do know a thing or two, as my name might suggest.
It is a common perception that pods are factor beta neutral and thus largely hedged. That is not quite true. A truer statement is that they are factor beta neutral to the extent they can measure the exposures.
Most equity risk models are derivatives of the original axioma and barra factor models. There are now many things that go into this but at their core they are a 12 (IIRC) variable linear regression. And mathematically, the unexplained remainder, the error term, is assumed to be the alpha (Upon which the team gets paid). You well recognize most of these factors: size, momentum (short and long), quality, dividend, domicile, sector, etc.
Now even the dull among you may note that there are in fact many other things that go into a stock. That’s true and that’s one reason why many people at the pods are very rich. There is though a very active and live debate to the highest level of these firms as what you “want” in the other bucket. On the one extreme, scheduling a proprietary drone flyover on the Aurora AV truck up fitting facility to measure parking lot activity vs expected timeline….that feels like pretty good alpha. On the other extreme, going long the Canadian listing rather than the U.S. listing because the Canadian listing diversifies the domicile score so you get a higher portfolio level idio score…..that doesn’t feel like great alpha. But the range is wide: paying GS a billion dollars so your team is the first meeting at the conference? That’s kind of the pod scale advantage. Albeit less so if every other pod is in the room. Going balls long large cap domestic U.S. GLP-1 manufacturers vs non GLP-1? Well that kind of is thematic alpha (depending on the work put in by analyst), but even if you’re of the opinion fuck it, let the kids rip (a reasonable view) you also know at the levered portfolio level that we aren’t measuring that risk completely. This line can really be illustrated with the concept of a “custom factor”. Maybe going long a shit load of SPACs is alpha, maybe it isn’t, but how the FUCK are you gonna build a portfolio level SPAC factor exposure loading in late 2021 when spacs didn’t functionally exist until 2021????
Anyways, interesting & active philosophical debate but there are some downstream derivatives.
Firstly, as a well known matter, 6 sigma events happen in finance all the time. There’s one every year in some corner of the market. So ex ante we know our models aren’t “great”.
Second, everyone knows the agent is an unobserved blind spot. It’s impossible to actually “know” why the analyst and PM are doing anything. You like to think they’re doing it on the back of deep fundamental quality work, but the median analyst and PM isn’t good at their job. So that assumption is known to be unreliable. The capital allocation solution to this is momentum chasing at the portfolio level: you allocate more to winning pods and you cut the losers fast. This is a brilliant approach because it means the pod business model is capital light- they identify and scale the good teams without actually having to invest in knowing which pods have “good” process. It’s worth really appreciating that point because it’s one of the true genius aspects of the model, and at its core it’s why the GPs are so fucking rich. (Deep finance readers will note that some of the original papers on factors saw that one of the earliest possible explanations for the decade-long trend nature for factor performance is implicit fund flow pressure from the momentum chasing nature of capital at the LP level)
(Continued in reply)
I think you’re identifying something important here, but I’d make a distinction between the convergence of information and the convergence of institutional constraints.
The former doesn’t necessarily produce identical investment decisions. Two investors can analyse the same information and reach very different conclusions about intrinsic value.
The latter is potentially much more dangerous.
If thousands of managers have similar leverage, drawdown limits, investment horizons and risk-management systems, then even independently formed investment views can translate into highly correlated trading behaviour.
And there’s an interesting paradox here: what constitutes rational risk management at the individual portfolio level can create systemic instability when everyone responds to the same constraints simultaneously.
But I’d challenge the conclusion that fundamental research becomes irrelevant.
If a company loses 30% of its market value because the marginal shareholder is a forced seller, without a corresponding deterioration in its future cash flows, that doesn’t invalidate fundamental research. It potentially creates a much larger fundamental mispricing.
The distinction, I think, is between being right about intrinsic value and having the capital structure necessary to monetise that insight.
And that’s why I’d argue duration alone isn’t an edge. What matters is independence: independence of thought, independence of positioning, and perhaps most importantly, independence from the constraints forcing everyone else to transact.
A five-year investment thesis supported by capital that cannot tolerate a three-month drawdown isn’t really a five-year strategy.
I also wonder whether the proliferation of AI-powered research makes this problem more interesting. If information becomes increasingly commoditised while institutional constraints remain homogeneous, perhaps the real opportunity isn’t discovering what everyone else has missed, but understanding why market participants are being compelled to act irrespective of what they actually believe.
In that world, fundamental research doesn’t become obsolete. The ability to distinguish genuine changes in economic value from mechanically induced changes in market prices potentially becomes even more valuable.
The scarce resource might not be information or even analytical sophistication, but the freedom to act independently of everyone else’s constraints.
A working theory I have is that crowding and contagion in public markets, particularly with MM funds, is basically unavoidable, right?
You have a cohort of senior analysts / PMs who came through the same training programs, leverage the same alt data, have similar tight risk constraints, and are trading similar ~quarterly time horizons. Oh, and now folks are likely using the same LLMs as part of their research. If you get fired, another pod picks you up, you carry your process there, rinse, repeat.
Same process, parameters, participants, and risk constraints across many levered shops. Correlation seems like it has to approach 1.
And if you’re effectively playing quarters, you’re forced into momentum trades to make money, because it fits your time horizon.
With tight risk constaints, if your pod blows up, you’re a forced seller, causing a cascade of other forced sellers who were likely positioned similarly, etc.
The simple answer is “duration is my edge” but if your “duration” still has you holding the same positions as the pods who are blowing out, you still suffer a 30% drawdown (see Lone Pine).
Fundamental research doesn’t matter if your position is hit by a tsunami of forced sellers when narrative (or a 2nd derivative data point) shifts. You still get smoked, LPs could pull capital, PMs lose bonuses, etc.
If anything, the value of “duration” is that you can sell or avoid overheated stuff that pods are forced to trade and hold bc they have a short time horizon and “that’s what’s working.” You can sell into euphoria / momentum and capitalize on blowouts when they happen. We’ve seen this cycle multiple times this year.
If market structures cause whiplash, even “fundamental” investors have to be aware of these high correlation moves and trade accordingly. “We can hold through this blowout and trust the long-term value of the stock” is cope.
I think David raises an excellent question.
At some point, the persistence of outperformance should meaningfully change our assessment of whether a manager possesses genuine skill.
The challenge is that almost any successful track record can be explained retrospectively through factor exposures, favourable regimes or randomness.
But that explanation needs to be falsifiable too. Otherwise, we’re effectively setting an impossible standard for demonstrating skill.
I suspect the answer isn’t a fixed number of bets or years, but how much the observed evidence should update our prior beliefs about the manager’s ability.
The independence of the bets, the economic rationale behind the strategy, the returns unexplained by factor exposures and, importantly, the performance outside the original sample all matter.
Ultimately, the question should be symmetrical: what evidence would convince us a manager has skill, and what evidence would convince us they don’t?