Introducing Unsloth Desktop 🦥
The first desktop app to run and train models locally.
• Open-source. Runs on Mac, Windows and Linux
• Supports MLX, diffusion image/video, audio, GGUF
• Connect Claude Code and Codex to local LLMs
• 50% more accurate, self-healing tool calls + sandboxed code exec
• Works for CPU + multiGPU setups - NVIDIA, AMD, Intel, Mac
• Train models 2× faster with 70% less VRAM
• Private web search, deep research, RAG, MCP and exports (NVFP4, GGUF)
• Use Unsloth’s OpenAI-compatible API and cloud models
• Securely deploy LLMs remotely and access anywhere
Unsloth Desktop is now available on https://t.co/xxBDOI9ApK and GitHub.
GitHub: https://t.co/2kXqhhvLsb
Blog and Guide: https://t.co/CYosNAQHva
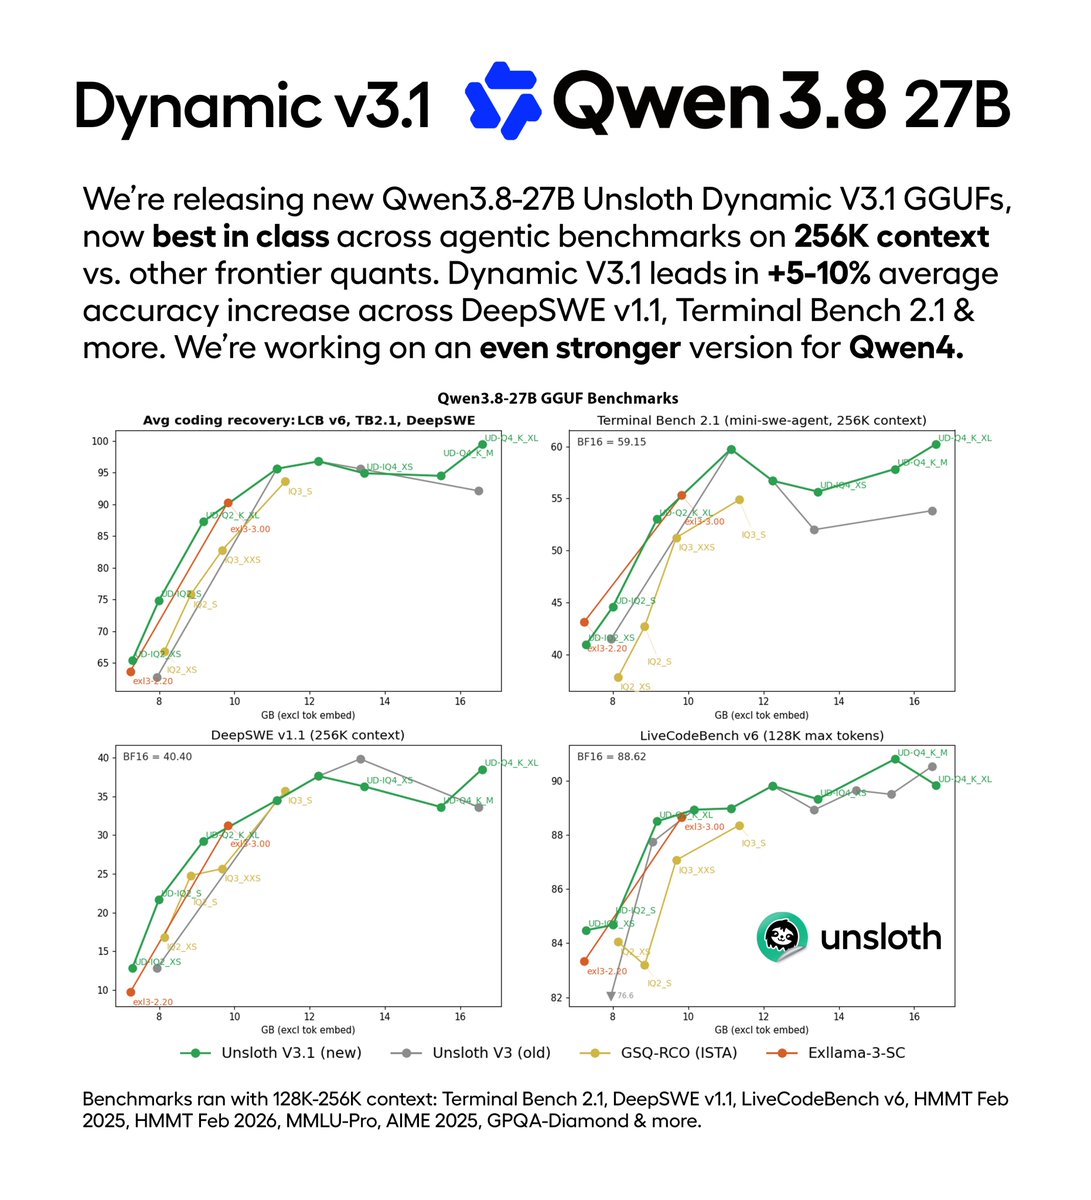
Today, we're releasing the highest accuracy Qwen3.8-27B GGUFs.
Our new Dynamic V3.1 GGUFs lead by 5–10% on average across Terminal Bench, DeepSWE & more. We’re working on even better version for Qwen4
Run on 12GB RAM.
GGUF: https://t.co/xIdNwm7CLQ
Blog: https://t.co/J2PwgMP6GZ
📢 Meet Qwen4-Max, your new AI teammate for work, creativity, and discovery!
Qwen4-Max is built on a new MoE architecture with native vision and a 1M-token context window.
Highlights:
- Outperforms Qwen3.8-Max with up to ~50% fewer tokens, while average cost per task drops over 60% in our internal evaluation.
- Advances real-world productivity through greater proficiency with professional tools, stronger long-horizon execution, and higher-quality deliverables.
- Handles real tasks, including 3D modeling, game development, manufacturing, finance, law, healthcare, and frontier scientific discovery.
- $1.5/M tokens for input, $4.5/M tokens for output, and $0.075/M tokens for implicit caching — all lower than Qwen3.8-Max, with implicit caching down by 70%.
The API is live on QwenCloud. You can also try Qwen4-Max on Qwen Studio, QwenWork and Qoder.
Start building today! 🚀
- Blog: https://t.co/AuiWxugjE6
- API: https://t.co/aS1QEkS8nu
- Token Plan: https://t.co/YRvcGdB9Bv
More to come! The open weights of smaller Qwen4 models will be released. Stay tuned. 👀
We also released Dynamic v3.1 GGUFs for Qwen3.8-Flash-Next and DeepSeek-V4.1-Flash.
UD v3.1 delivers even more prominent performance gains on these models across agentic benchmarks at 512K context.
Today, we're releasing the highest accuracy Qwen3.8-27B GGUFs.
Our new Dynamic V3.1 GGUFs lead by 5–10% on average across Terminal Bench, DeepSWE & more. We’re working on even better version for Qwen4
Run on 12GB RAM.
GGUF: https://t.co/xIdNwm7CLQ
Blog: https://t.co/J2PwgMP6GZ
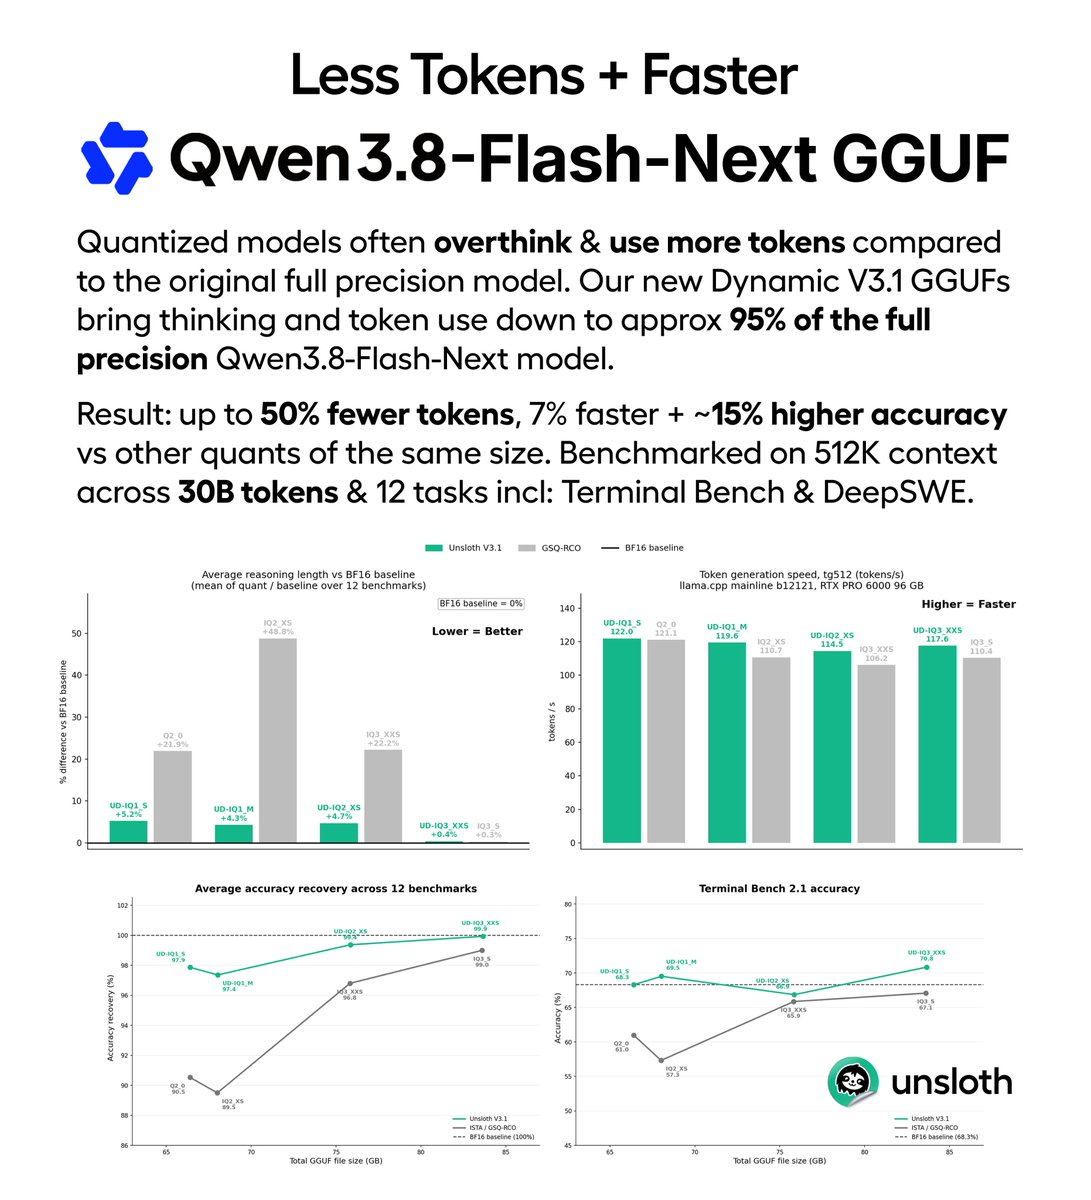
Qwen3.8-Flash-Next GGUFs now run faster with less thinking and less token use.
Unsloth Dynamic V3.1 GGUFs bring thinking & token use to match 95% of full precision Qwen3.8-Flash.
Results: 50% fewer tokens + 15% higher accuracy vs same size quants.
GGUF: https://t.co/vXkjO3W0fj
We’re releasing new Qwen3.8-Flash-Next GGUFs with 15% higher accuracy.
Unsloth Dynamic V3.1 outperforms others by >15% on Terminal Bench, DeepSWE & more benchmarks (256K context).
Run on 32GB+ RAM setups.
GGUF: https://t.co/vXkjO3W0fj
Blog: https://t.co/LLMclyJTeL
We’re releasing new Qwen3.8-Flash-Next GGUFs with 15% higher accuracy.
Unsloth Dynamic V3.1 outperforms others by >15% on Terminal Bench, DeepSWE & more benchmarks (256K context).
Run on 32GB+ RAM setups.
GGUF: https://t.co/vXkjO3W0fj
Blog: https://t.co/LLMclyJTeL
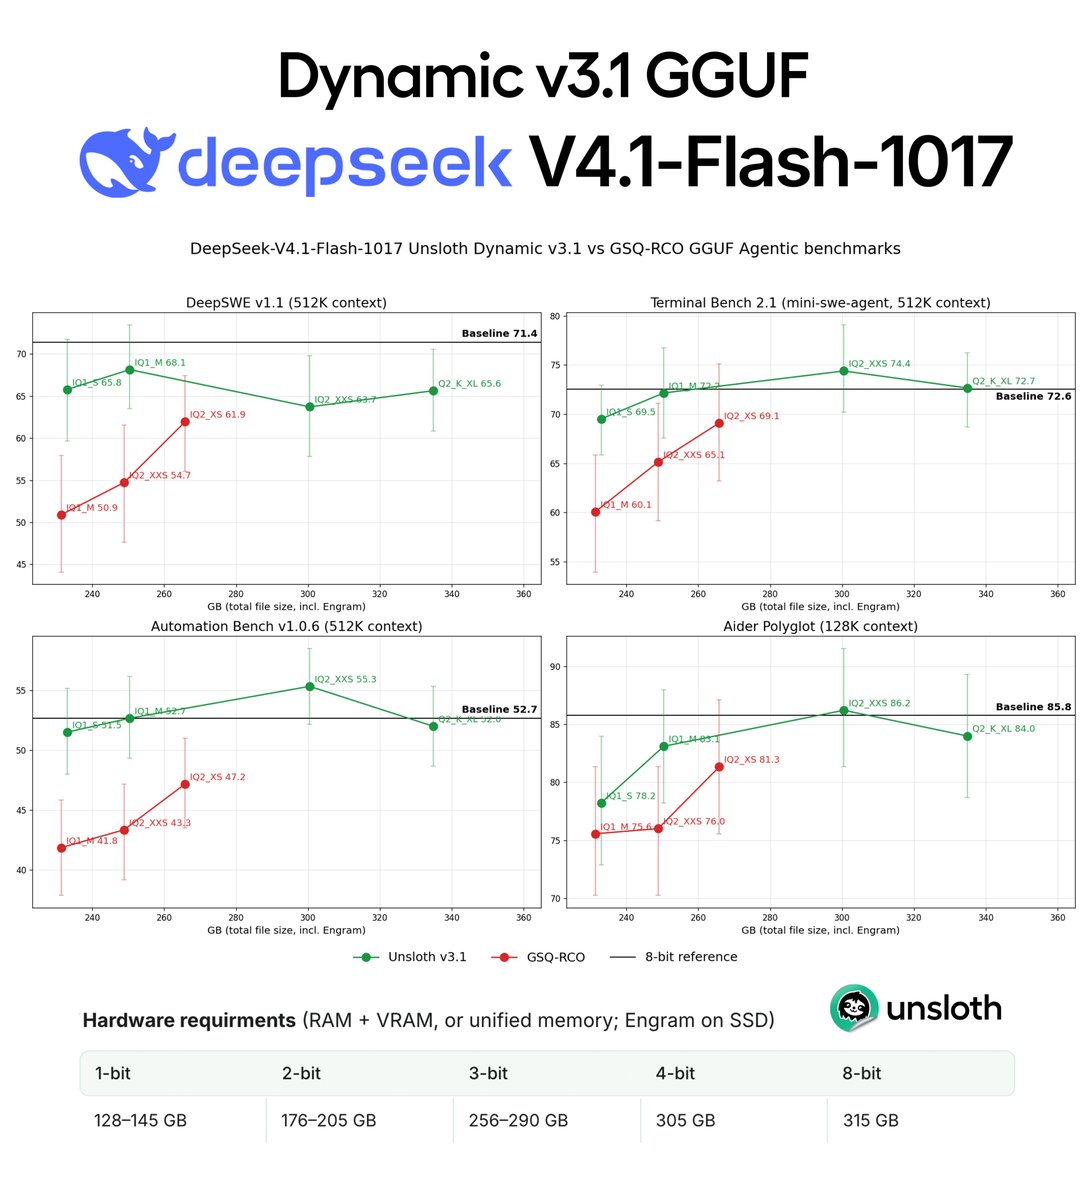
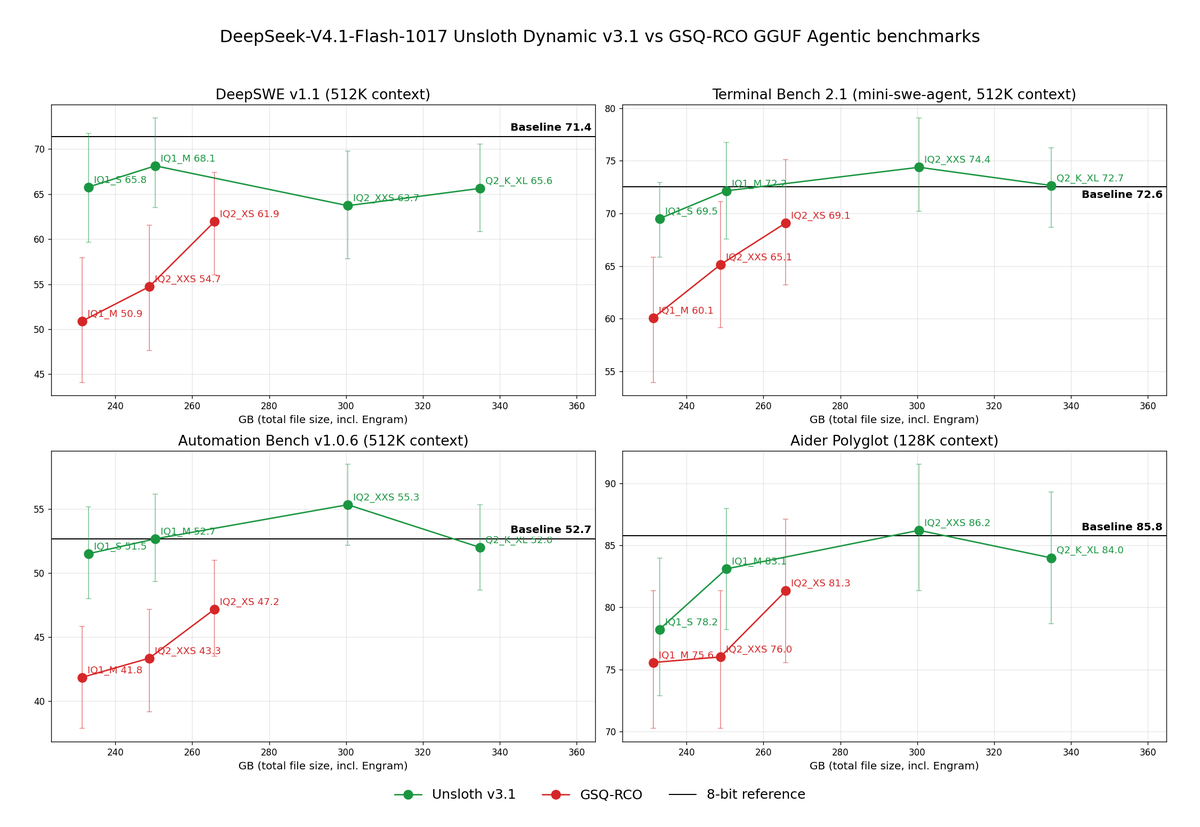
We benchmarked DeepSeek-V4.1-Flash-1017 GGUFs on Terminal Bench, DeepSWE & more on 512K context. Unsloth ranks highest overall.
1-bit Unsloth GGUF scores 68.1 on DeepSWE, 72.2 on Terminal-Bench, 52.7 on AutomationBench. >10% ahead of other quants.
GGUF: https://t.co/1kD14VTAYP
We’re releasing new DeepSeek-V4.1-Flash-1017 GGUFs, ranking highest across benchmarks.
Dynamic V3.1 leads across nearly all benchmarks: GPQA Diamond, AIME25, LiveCodeBench v6, MMLU-Pro, Aider & more.
Run on 64GB+ RAM.
GGUF: https://t.co/1kD14VTAYP
Blog: https://t.co/YPEmDLas7d
Unsloths support for Deepseek is here! 👀
+ Improvements on Strix
+ Improvements on parallel requests
+ Improvements on DGX Spark
+ Improvements on Intel B-series
See more at: https://t.co/bptoXmkAJa
We’re releasing new DeepSeek-V4.1-Flash-1017 GGUFs, ranking highest across benchmarks.
Dynamic V3.1 leads across nearly all benchmarks: GPQA Diamond, AIME25, LiveCodeBench v6, MMLU-Pro, Aider & more.
Run on 64GB+ RAM.
GGUF: https://t.co/1kD14VTAYP
Blog: https://t.co/YPEmDLas7d
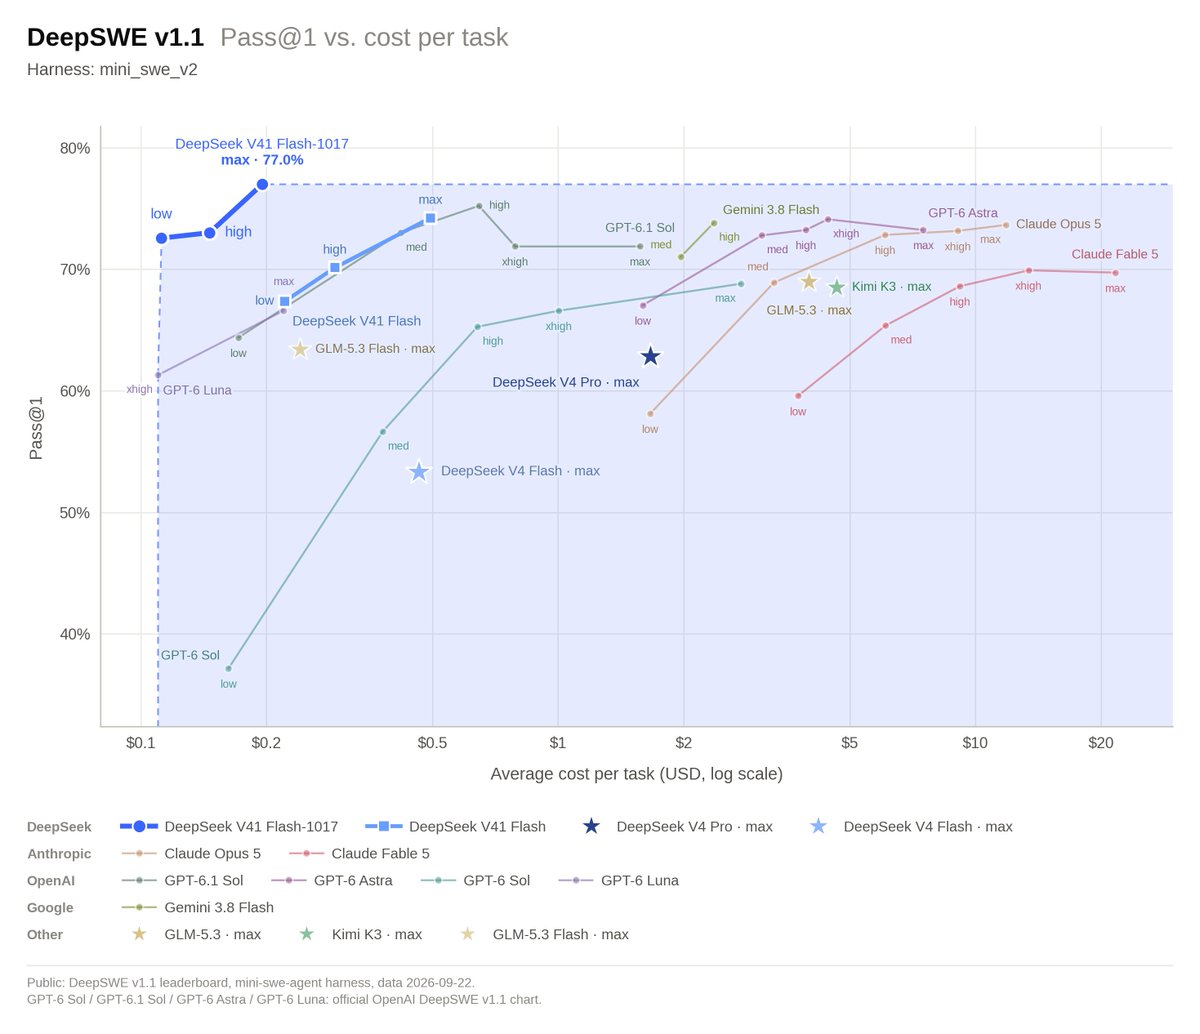
🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4
Mistral Le Chonk can now run locally!
The 1 trillion parameter model runs on a Mac Studio with our 1-bit GGUF which retains 91% top-1 accuracy.
Le Chonk is the strongest Western open model to date.
GGUF: https://t.co/irNXvfVGNg
Guide: https://t.co/StUa0S2XP6
Mistral Le Chonk can now run locally!
The 1 trillion parameter model runs on a Mac Studio with our 1-bit GGUF which retains 91% top-1 accuracy.
Le Chonk is the strongest Western open model to date.
GGUF: https://t.co/irNXvfVGNg
Guide: https://t.co/StUa0S2XP6
Today, we release the weights of a new and improved Le Chonk, advancing the open frontier for agentic coding and cybersecurity.
💻 Built to build: Le Chonk ranks #1 on @cognition’s FrontierCode among open models, and sets a new benchmark for Pareto efficiency on @artificialanalysis.
🛡 Built to defend: State-of-the-art in cyberdefense, put through the paces by the world's leading cyber vendors, including @CrowdStrike, @cloudflare, @rubrik, @zscaler, and others.
Built for sovereignty: Make it yours. Download the weights on @huggingface , customize it with Mistral Forge, and deploy it wherever you need it.
Read more from our team and customers 👇:
Your local LLM can now take control of a browser and complete tasks autonomously via Unsloth!
Qwen3.8-27B successfully controlled the browser to complete tasks like chess, painting, with no human intervention.
GitHub: https://t.co/aZWYAtakBP
Guide: https://t.co/bhq8pHfAL2
MiniMax M3.1 Flash meets the @UnslothAI community. 🐙🦥✨
Unsloth’s Dynamic GGUFs bring our 428B MoE model to a 143.9GB 2-bit footprint, with 91.5% top-1 token agreement in their evaluation across seven domains.
That means a lower memory barrier to self-hosting, deployment through Unsloth Desktop and llama.cpp, and an OpenAI-compatible API for existing apps and agents.
With 78K+ GitHub stars and over 500M model downloads on Hugging Face, Unsloth gives M3.1 Flash a path into an established community of developers running, evaluating and building with open models.
Open weights. Local control. More ways to build.
Getting started with @UnslothAI on RTX Spark? Just run the .exe.
@danielhanchen and @NaderLikeLadder got hands-on with NVIDIA RTX Spark to talk about running and training AI models locally, exploring reinforcement learning, and making it easier to start building with Unsloth.