Launching Decision models on @useRouterPlus. You can now use various system 1 decision models such as Jev, @perplexity_ai Decider, @bespokelabsai Nimble, Mercury Decide, Clef, Kev 4B and Decider 2B with 3 models free !!
https://t.co/ux78dmQV0b
btw at @useRouterPlus we have been using numerous techniques to ensure that inference providers are ACTUALLY delivering what they claim - this involves running relatively expensive live evals , checking quality and also measuring symmetric KL divergence to monitor deviations from actual expected behaviour
since a lot of inference contracts go through us we can actively monitor for such discrepencies and hold providers accountable. its only done now for certain larger contracts - but we expect to roll it out to the wider platform soon
Buying inference today means picking between two bad options.
Commit for a year and pay for capacity you don't use. Or go serverless and get rate limited the moment you grow.
But usage arrives in bursts: a weekend eval, a two-week backfill, US business hours.
And not all tokens are equal. You might need BF16, not quietly quantized FP8. Served in the US. A latency target. Zero retention. Fast tokens for your product, cheap batched tokens for the rest.
The capacity exists. It's just scattered across big clouds and long-tail providers you've never heard of.
So we built a marketplace.
Introducing the @useRouterPlus managed inference marketplace.
Post the inference you need, when you need them. Commitment you are comfortable with. Providers bid. You pick the one that meets your spec.
we're already on track for 1 trillion tokens a month.
https://t.co/gAg1S8TRmK
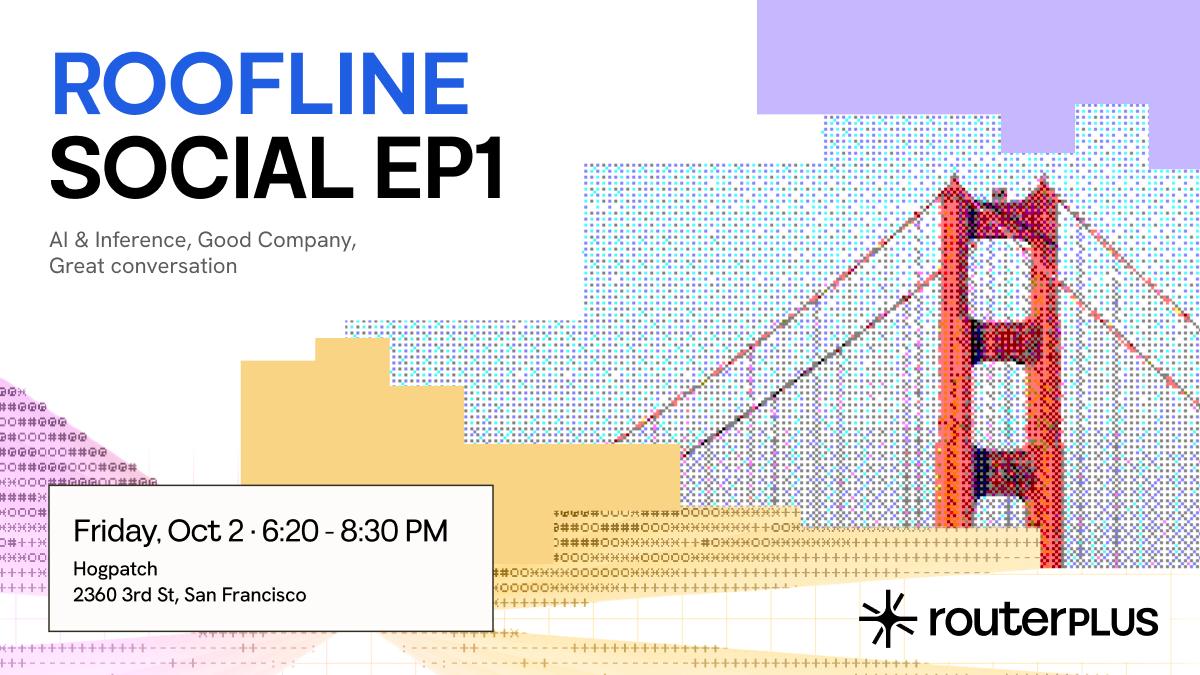
we are starting to host small gatherings around AI and inference with the first of the series tonight at 6:30pm at Hogpatch ( pizzas and snacks included ! ). Great chance to hang out with folks thinking and building in the space. luma link below
ps : we will be rebranding to @userouterplus, would love to show you what we’re upto as well!
loved the GTM brainstorming with the guys. @XLN1999 and @alokbishoyi97 are the team I'd bet my life savings on. @EVO__HQ is gonna be the biggest force in managing inference loads, will come back to this post after the demo day, and again by '28 when they hit a billion in ARR (pardon for my lack of vision if you guys get there faster)
Kill the space, my Gs.
@EVO__HQ got into YC!!
we are eager to talk with
- engineers who are hungry to become the best in the world at inference, posttraining and distributed systems.
- ops folks who have worked with datacentres and inference providers
deployed and served custom models for a big @evo__hq customer over the past week
insane and rapid learnings
understood their traffic patterns, setup evals - did lot of ablation runs on multiple models
eventually we weren't getting enough savings, so we posttrained a model - first SFT and then other RL policies
then came inference optimization setup end to end , including custom spec dec models as per their data distribution, tuning vLLM configs, quantization etc
then more work around compute allocation , inference capacity planning / warming up as per traffic profiles etc
all orchestrated by our in house autoresearch / AI engineer
all this to ensure our customers get best bang for buck
we are now rapidly onboarding inference providers who can reliably service our growing demand
and if you are someone whose agentic/AI workload spends are more than $20k a month, then do reach out. We would love to figure what we could do for you!
At @evo__hq we hillclimbed a smarted router setup for agentic workloads ( ITSM bench by @vibrantlabsai ) that achieves SOTA results while being 20x cost effective vs frontier models - beating as well the newly released models of Grok4.6 and Deepseek v4 pro in both quality and cost
For enterprise agentic workloads, what we have repeatedly found is that frontier models still do not get that last mile reliably and are prohibitively costly.
It becomes necessary to hillclimb on your specific data distribution, schema, policy and traces. This is what we do at @evo__hq
preach ! been telling ya’ll
also the most important part is the last line. “the challenge is customizing them to an org/team/individuals requires data”
this is exactly what @evo__hq solves for btw
“There is no best model for every task. Routing, harnesses, evals, and the right mix of open and proprietary models can radically change the economics.”
exactly the thesis of us at @evo__hq btw :)
Introducing EVO Router - a smart router that continuously optimizes and hill-climbs on your AI inference workloads.
It learns from your code, prompts, production traffic, use cases, and SLAs, then searches for the best setup for every workload.
That can mean more than choosing just a single model or routing through a classifier. @EVO__HQ can optimize across model × provider combinations, fusion systems, cascades, routing policies, and prompts — whatever the workload allows, while staying within your quality, latency, and reliability constraints.
As open-source models move closer to frontier-model performance, we believe this kind of workload-specific hill-climbing will become an important part of how AI systems are deployed and operated.
Our early users have seen 30–60% lower inference costs across use cases ranging from complex multi-turn agents to asynchronous batch workloads.
EVO Router has also reached the Pareto frontier on several benchmarks, outperforming existing setups on cost, quality, or both.
always great to hear folks making good use of @evo__hq's autoresearch engine
T - 48 hours untill we launch the next iteration that the team has been working on, putting to use all the learnings from our users
If you want early access to not just yet another router™, but a system that automatically sets up evals, optimizes your workloads, and continuously finds the best model x provider for YOUR USECASE , then my DMs are open.
We already have a few teams in the beta, and they’ve reduced inference costs by 30–60% with no quality regressions.
@evo__hq
i am seeing a lot of disillusion amongst folks for the new crop of AI "routers" that are popping up. everyone is in a gold rush to capture demand, w/o deep consideration of the actual problem to be solved
i have been talking with a lot of disgruntled users of such products - and the inside feedback from all such customers has been that such tools either end up degrading quality of their product or end up costing more because of non optimal switching and invalidating KV Caches
per api call task routers are meaningless when you take into consideration long agentic tasks. $ per mil token input / output is an artifact of the past.
Its an exploration - exploitation problem that you have to solve for specific usecases. its something that you need to hillclimb for specific customer on their specific distribution of data - not something a mere global classifier or decision tree will get it right.
i would love for folks who have used such product to comment if it really worked for them, or for founders of such "router" products to show what they are doing different
will be thinking and posting more on this soon
100%. From over 25k+ installations of @evo__hq, we have had a very unique vantage point of seeing what people use autoresearch / self improvement for and also failure cases at scale
We will be launching something very very soon regarding a super specific and valuable application of self improvement deriving from the insights we have had of seeing evo’s usage
would recommend to keep your notifications on :)
announcing evo x Kimi Code
now you can use Kimi code via @evo__hq to run long running autoresearch loops in two simple commands
$ uv tool install evo-hq-cli
$ evo install kimi
Point it at a repo and it discovers what to optimize, builds the eval, and runs structured experiments until the metric improves. The loop is now driven by Kimi K3, the strongest open model to date.
Open-weight autoresearch, end to end.
we have had some really initial results from folks who have been using Kimi for autoresearch, especially on kernel and inference optimization tasks ( will post more on this soon )