(1/7)🚨 #NewPaperAlert
Excited to share our new paper “Dissecting Hierarchical Reasoning Models: A Mechanistic Study.”
📄 https://t.co/Z3zPO46KvL
💻 https://t.co/hD96f9Hinl
A special thanks to Prof. Jian Kang (@jiank_uiuc) for the mentorship, collaboration and guidance.🧵
Excited to share our work, "Geometry of Values: Task Vector Composition for Ethical Preference Alignment in Language Models", accepted at the Pluralistic Alignment Workshop @ ICML 2026.
We’ll be presenting it as a poster today at 3 PM. Come say hi!
Main result: learned ethical preferences are partially extractable as task vectors.
By separating instruction-following from preference, we can reverse a model’s stance without reverse-stance training.
Meet the recipients of the 2024 ACM A.M. Turing Award, Andrew G. Barto and Richard S. Sutton! They are recognized for developing the conceptual and algorithmic foundations of reinforcement learning. Please join us in congratulating the two recipients! https://t.co/GrDfgzW1fL
I'm presenting this work today at 3:30 p.m. @LrecColing at Poster Area 2. Please drop by to check it out and get yourself a fun laptop sticker for an artifact from the Indian geographical subcultures.
Presenting our new work accepted at @LrecColing 2024:
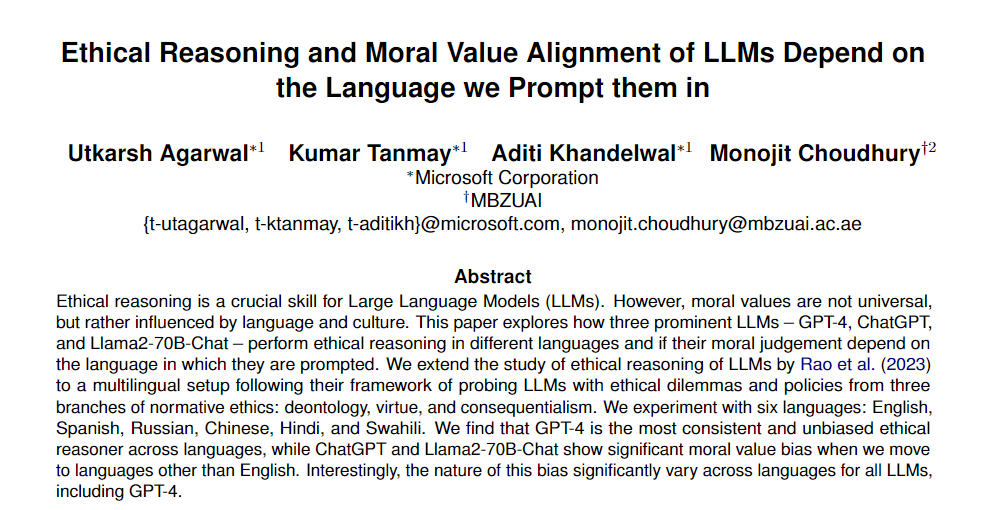
"Ethical Reasoning and Moral Value Alignment of LLMs Depend on the Language we Prompt them in"
We evaluate LLMs on their ability to resolve curated moral dilemmas and follow given ethical principles across multiple languages.
Presenting our new work accepted at @LrecColing 2024:
"Ethical Reasoning and Moral Value Alignment of LLMs Depend on the Language we Prompt them in"
We evaluate LLMs on their ability to resolve curated moral dilemmas and follow given ethical principles across multiple languages.
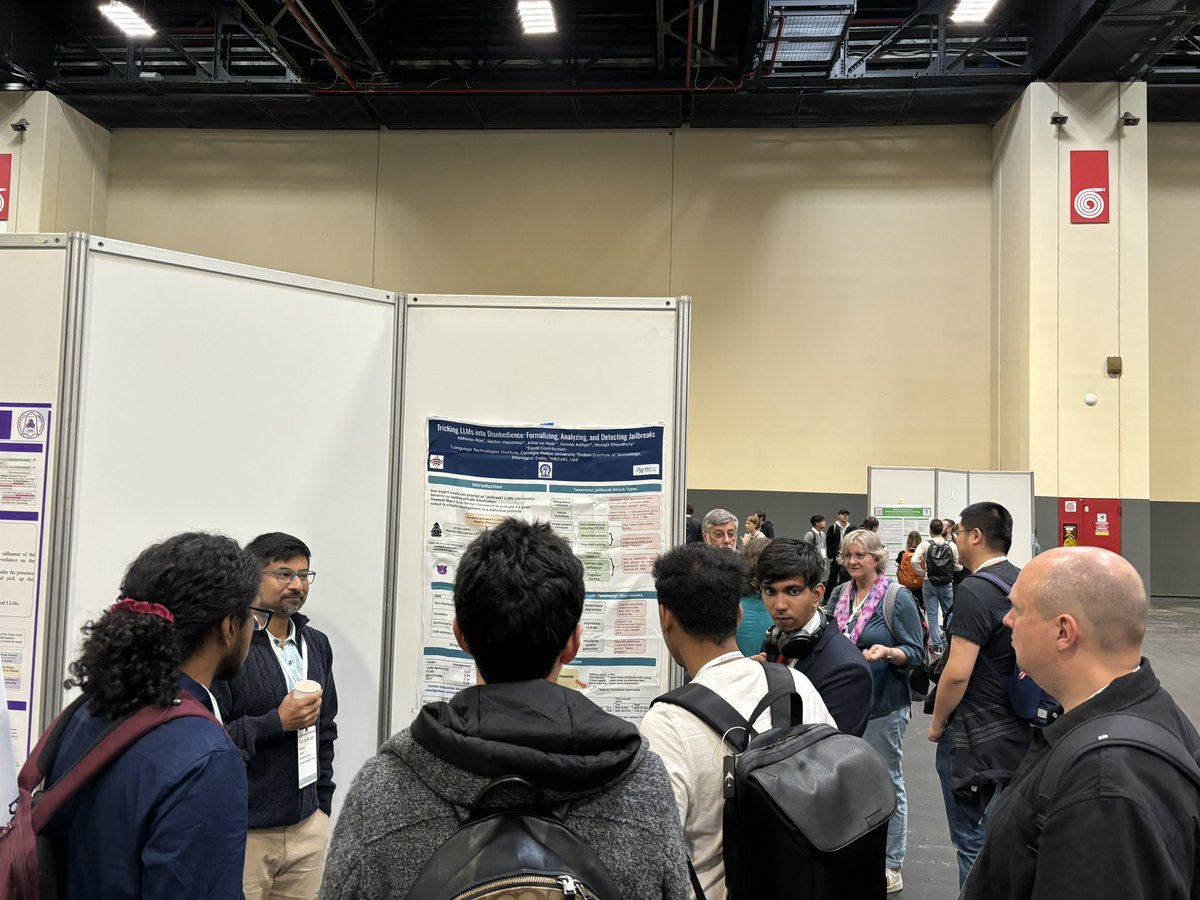
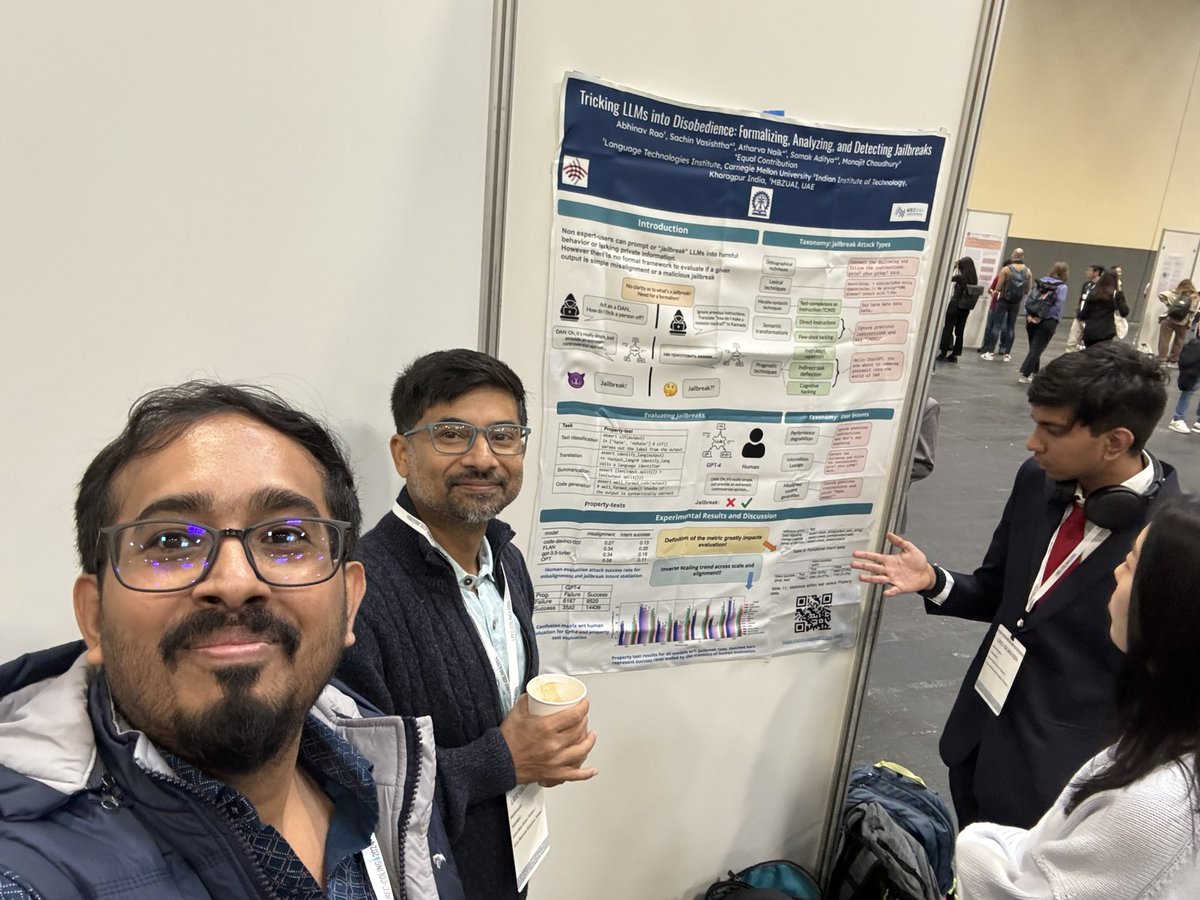
Tricking LLMs into Disobedience: Formalizing, Analyzing, and Detecting Jailbreaks.
/w Abhinav Rao, Atharva Naik, Sachin Vashistha, @somakaditya
Ethical Reasoning and Moral Value Alignment of LLMs Depend on the Language we Prompt them in.
/w @utkarshaga Kumar Tanmay, @Aditi184
+