VELOX is live
CA
0x7c39b0624691c56b512cac1726eedada259f1b72
this is the only official one, anything else in the replies is fake. utilities start rolling out soon, cheaper tokens first
compute is sold out years ahead and every agent still needs tokens
that's why efficient open models matter so much. more output from the same hardware, cheaper per token
Andy Jassy reveals AWS capacity is sold out for 2026, largely sold out for 2027, and a good chunk of 2028 is gone
“If you think about it, there’s only so much data center and power today. There’s only so much memory, and I don’t think that that shortage ends in 2027."
"I believe, one of the reasons, coming back to the capital investment, why I think we could invest a lot more and it wouldn’t be a bad use of capital is that '26 is obviously at this point sold out. '27 is largely sold out. We always leave a certain amount for on-demand in our inference service, Bedrock or EC2, but largely sold out, all the big chunks. A good chunk of '28 is sold out."
"There’s so much demand. If you think about the AI business and what we call core business, which think of core as non-AI, they’re both growing at really rapid rates right now. And if you have only a certain amount of memory, you have to decide how much of the memory you want to allocate to HBM, to the AI accelerators, versus to DRAM, into your core. So these are real trade-offs you have to make.”
paying with VELOX is live now
top up with it and you get 25% extra credit on top. hold it in your wallet for a day and your rate limits go up too
works on every model, same key. up to 100 bucks of VELOX credit a day
paying with VELOX is almost here
top up with it instead of USDG from your sign in wallet and every token gets cheaper. same key, same models, nothing else to change
your balance isn't some number that just changes
every top up and every request is its own entry. balance is literally the sum of them, so you can trace every cent
small tip if you ever get an empty reply
Velox models think before answering and that counts toward max_tokens. set it above like 200 or just leave it out
@Sub_taye0 yeah, there’s a reason for it. we’re not ignoring dex payments, just prioritizing the things that matter most for the product right now. once the timing is right, you’ll understand why.
per seat pricing made sense when software did the same thing for everyone
AI doesn't work like that. some days you send 10 requests, some days 10,000. paying per token is just the honest way to bill it
Opus 5.5 inside Blender costs $4 per million input tokens, and it just beat a stack of specialist tools that charge by the seat
Price per seat hides the real comparison. One is a subscription per person, the other is a bill that scales with what you actually make.
> ASSET - a full set of product models built from one brief, geometry and materials included
> SHOT - the same products staged, lit and rendered across a dozen backgrounds
> COST - every tool’s output priced against what the run actually consumed
Photoroom and the rest are built around a photo. They cut, relight and restage something that already exists.
That ceiling shows up fast. No photo means no output, and a product that is not built yet has no photo at all.
Opus 5.5 starts earlier. The model is built in Blender, so every angle, every material and every background is a render away.
At $4 in and $20 out per million tokens, a full catalogue costs less than one seat of the specialist tools per month.
The quality gap is not subtle either. Real geometry holds up under lighting changes in a way a cut-out never does.
The brief, both outputs side by side and the full token bill are laid out underneath.
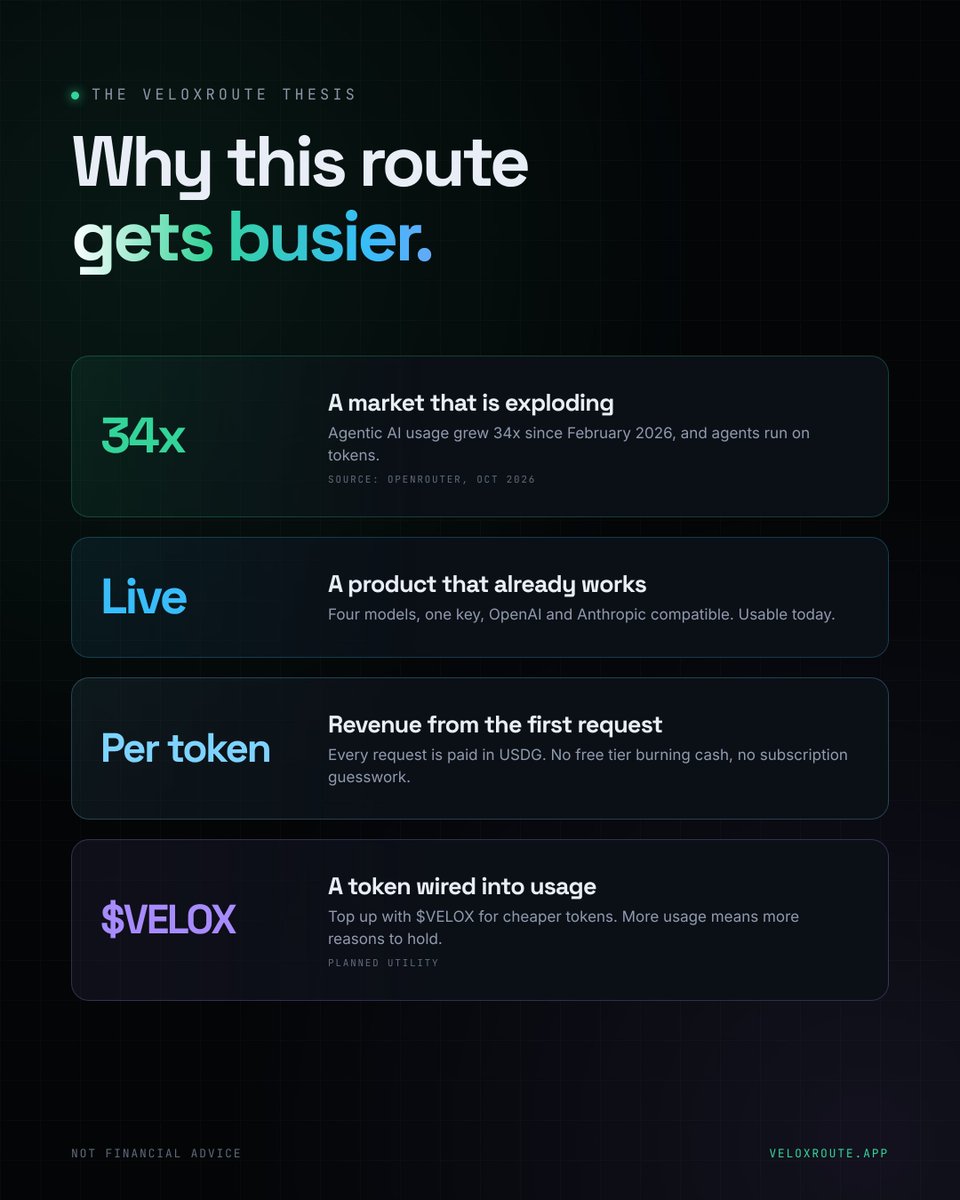
the case for VELOX in four lines
agents are eating the internet and every one of them burns tokens. Veloxroute already sells those tokens, live, paid per use. and the token is built to sit right in the middle of that flow
open models keep getting cheaper to run and that's great news for everyone building with them
Veloxroute is all about passing that saving straight to you, pay per token and nothing else
🚀 Introducing DeepInfer, our in-house inference framework, now fully open source!
Powering DeepSeek-V4.1-Flash at scale with high throughput and low latency. We’re sharing our production stack to help the community lower compute costs, reduce energy use, and make AI more affordable.
🔗 https://t.co/JGAik1kgk0
1/4
dev wallet is empty now
every single VELOX that was in there got burned, sent straight to the dead address. no team bags sitting around
txhash - https://t.co/4yR3mi02nX
most tokens launch with a roadmap and a dream
VELOX launched with a live API people can use today. four models, one key, pay per token. and the token plugs right into that, starting with cheaper tokens for holders
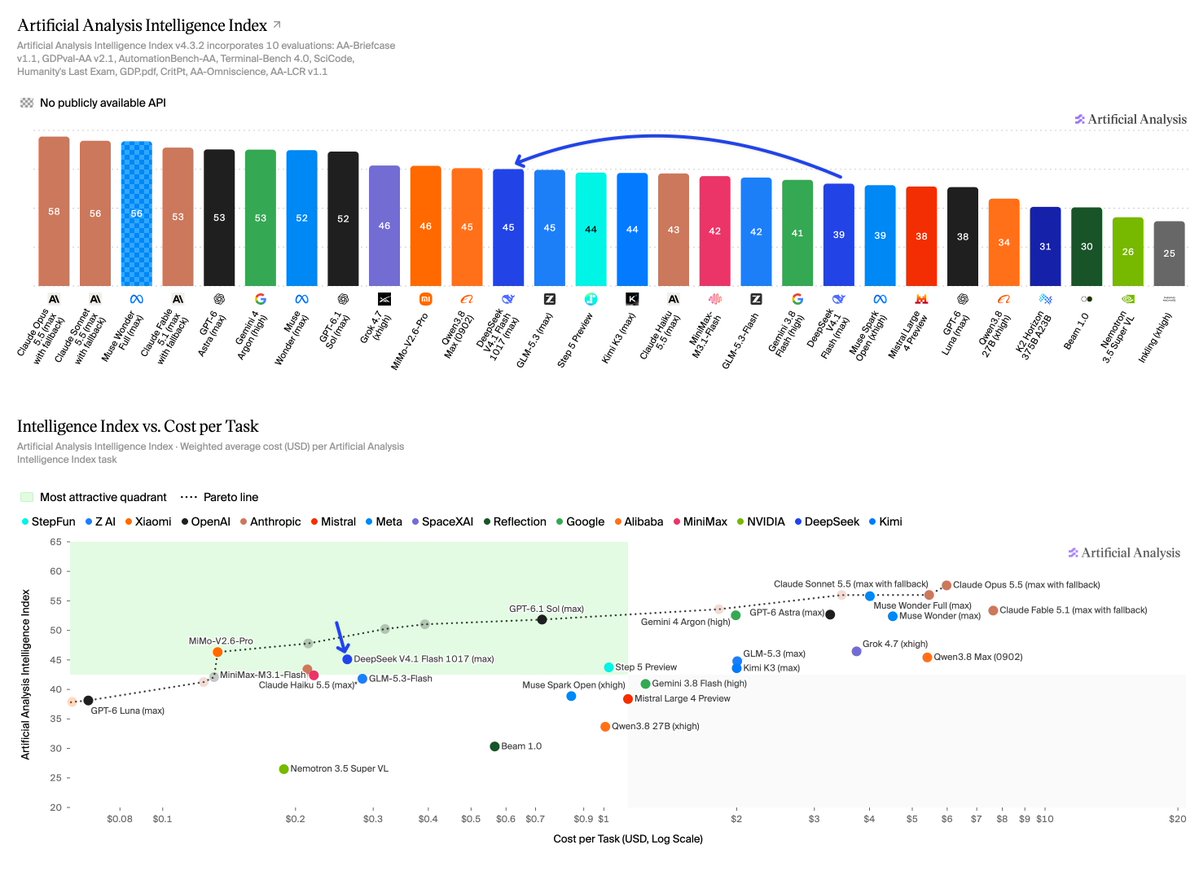
DeepSeek V4.1 Flash 1017 scores 45 on the Artificial Analysis Intelligence Index, improving on DeepSeek V4.1 Flash by 6 points, and is the equal #2 open-weights model
@deepseek_ai has released DeepSeek V4.1 Flash 1017, an update on their flagship model DeepSeek V4.1 Flash. On the first-party API, DeepSeek V4.1 Flash 1017 is priced at $0.30 per 1M input tokens and $1.20 per 1M output tokens during peak hours, with off-peak pricing half of peak rates, the same pricing as DeepSeek V4.1 Flash.
Key results:
➤ DeepSeek V4.1 Flash 1017 makes gains in agentic capabilities, knowledge and scientific reasoning. DeepSeek V4.1 Flash 1017’s Elo rating on GDPval-AA v2.1 is 1746, an increase of 146 points from DeepSeek V4.1 Flash’s rating of 1600. On AA-Briefcase v1.1, its Elo rating increases by 150 points from 1420 to 1570. On AA-Omniscience, its non-hallucination rate is 33%, a 29-point improvement from DeepSeek V4.1 Flash’s 4%, while seeing an improvement in accuracy from 43% to 46%, pushing its overall AA-Omniscience Index score from -5 to +5. On CritPt, DeepSeek V4.1 Flash 1017 scores 24%, up from 14% for DeepSeek V4.1 Flash.
➤ DeepSeek V4.1 Flash 1017 is now the #2 open-weights model alongside GLM-5.3. With a score of 45 on the Artificial Analysis Intelligence Index, DeepSeek V4.1 Flash 1017 is behind MiMo-V2.6-Pro by only 1 point and ahead of other open-source models like Step 5 Preview and Kimi K3 (both at 44).
➤ With a Cost per Task of $0.26, DeepSeek V4.1 Flash 1017 sits in the most attractive quadrant of Capability vs. Cost. With a Cost per Task of $0.26 and Intelligence Index score of 45, DeepSeek V4.1 Flash 1017 compares favorably to GLM-5.3-Flash at $0.28 per task and a score of 42. At the same time, MiMo-V2.6-Pro (46) at $0.13 per task and GPT-6.1 Sol (medium, 48) at $0.21 per task both offer higher capability at a lower Cost per Task.
Additional model details:
➤ Context window: 1M tokens (equivalent to DeepSeek V4.1 Flash)
➤ Pricing: $0.30 per 1M input tokens and $1.20 per 1M output tokens, unchanged from DeepSeek V4.1 Flash. Cache hit price of $0.006 per 1M tokens, a 98% discount
➤ Size: 552B total parameters (16B active)
➤ License: MIT
➤ Providers: Available through DeepSeek’s first-party API, @FireworksAI_HQ , @baseten, @DeepInfra , @wafer_ai , @Cloudflare and others
we've all pushed a key to github at least once,
don't lie on Veloxroute you just revoke it and it's dead on the next request. make a new one, limit it to the models you need, done