seeing this progress from @AnthropicAI makes me reflect on Valida - the zk prover my team built. it’s encouraging to see zk finding its place. i hope we still contributed something valuable along the way and helped move the field forward!
New Anthropic research: progress on provable inference for large language models.
Here, we introduce FlashProve. Building on established cryptographic techniques, FlashProve allows developers to verify whether a given response came from a given AI model. It’s substantially more efficient than prior open-source methods for doing so.
These proofs have a range of applications. They can, for instance, make it harder for attackers to hijack a chat, or enable safety evaluators to verify that the model they’re testing is the same one being served to customers.
For our full write-up, see here: https://t.co/OIZWPb6QZa
Further progress in provable inference will likely be an important part of improving trust in AI deployment. To that end, we're open-sourcing FlashProve’s code, here: https://t.co/7ky3Ir8V06
We’re grateful to our collaborators: Alessandro Chiesa, @GiacomoFenzi, @gwberg95, @miranda__christ, Rahul Dalal (https://t.co/pjWKLHWXyz) and Ben Mayer (@transmissions11).
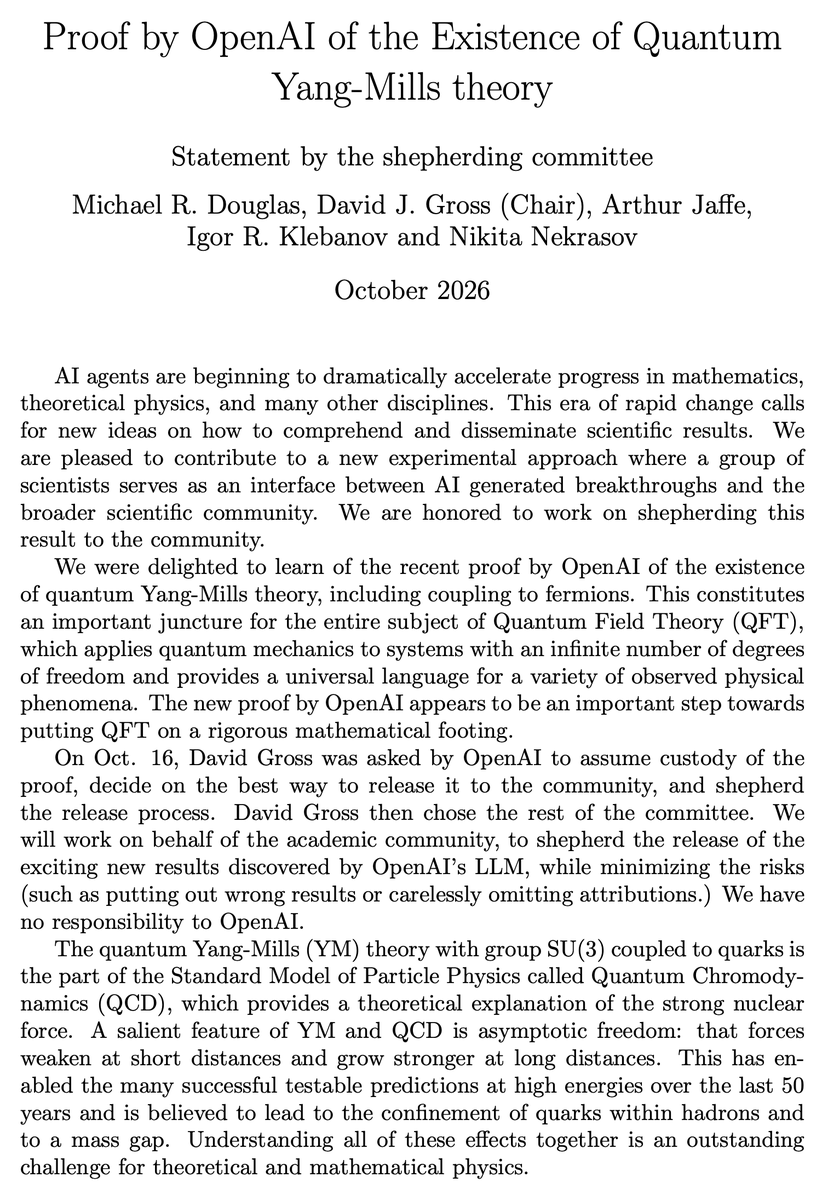
anyone knows what exactly did the model prove?
how qcd can be completely reduced to yan-mills gauge theory? when/where can we find the proof and more details?
Statement of Yang-Mills Working Group, a scientific collaboration to interpret AI result related to the existence of quantum chromodynamics & completions of the Standard Model, including a subproblem proving the existence of the Quantum Yang-Mills theory. https://t.co/j8O8TUjSD3
really cool benchmark from guanghan!
most benchmarks test whether a model can solve a problem. witness-bench tests whether it can discover the rules of a problem through experimentation, hypothesis formation, and feedback.
a much more interesting test of intelligence, especially for agents operating in unfamiliar environments.
WitnessBench is now on @FireworksAI_HQ’s Specialized Intelligence Index.
It measures how effectively RL improves model performance in puzzle game environments with hidden rules. The SII shows where open, closed, and specialized models stand.
Explore the results: https://t.co/xNgYHsiBLN
Today we're unveiling Trillium Labs @trillium_labs, a new non-profit to foster the open science of frontier AI. We're building open post-training recipes and will expand into open infra to study RSI, reward-hacking, multi-agent systems, and whatever comes next.
We're built around the theory of change that you need more eyes to solve hard technical problems. We have faith in the scientific methods and communities that humanity has built, and worry that AI is becoming too closed to utilize them.
Trilliums are wildflowers that bloom briefly in the spring, before the forest canopies fill out. Though they are small, they lay the foundation for the cycles of growth and nourishment through the rest of the year. At Trillium Labs, the recipes will be the slow nutrients for the seasons and the model releases will be the blooms. Building an institution dedicated to this is needed because, much as nature’s trilliums are slow to expand and grow, the open-ecosystem needs time and dedicated resources to catch up.
I co-founded with with a long-time friend and collaborator Tom Zick (@thesezickbeats). We're hiring (full time + student collabs/interns), we're fundraising, and we're looking for compute. Please get in touch if you're interested in helping out. Offices based in the Bay Area and Cambridge MA, remote okay.
I’m in the Bay Area until for The Curve and COLM to connect with people who are interested. We’re thankful to have initial support from Halcyon Futures and Schmidt Sciences with more funding en route to enable our ambitions of scaling. Our advisors @Thom_Wolf, @HannaHajishirzi, @gneubig and @ctnzr have been instrumental to building the ecosystem that exists today, and I’m stoked to get to keep working with them.
this is the proof abundance tao predicted at icm in one commit. proving is no longer the bottleneck. digesting is. some thoughts on a potential solution: https://t.co/YEDN6ikiuv
We’re releasing a broad range of new mathematical results produced by an internal frontier model.
We’ve been consulting with the independent Advisory Group on Mathematics and Artificial Intelligence at the Institute for Advanced Study, and we have drawn on their advice and public recommendations to inform how we release these results.
https://t.co/7N6TPlft1P
openai released 722 math manuscripts today. 372 result families, ~4,000 problems posed, about three hours of compute each, from one internal model. not all are formalized yet; the readme says some unformalized results "could have issues." nobody has read most of them. this is the proof abundance terence tao warned about at icm, and it arrived in a single commit. https://t.co/KgczlKTXr4
tao's point: a result goes through generation, verification, exposition, publication, canonicalization before it counts as mathematics. ai is good at the first and getting good at the second. the other three are slow and human. the bottleneck isn't finding proofs anymore, it's digesting them. a lean-checked proof nobody understands is correct but useless, and openai's repo has 722 of them, some not even lean-checked.
i think this post could be a solution. it attempts to turn "mathematical understanding" into something you can train on, and it points at a better reward than anything provers use today.
oleg's idea here is to freeze a smaller model, fix its compute, hand it a theory, count what it can derive now that it couldn't before. it's a measurable version of understanding, and it's basically tao's digestion stage as a number. and that number is a reward.
every prover we train today gets paid for "proof accepted." self-play setups pay the conjecturer by the prover's pass rate. both optimize for volume of provable statements, which is the stage we already have too much of.
if the reward is halo delta instead, a proof is worth nothing on its own. it only gets credit when it finds structure that makes unseen theorems cheaper. that's compression, and nobody has shown how to train it at scale yet.
the closest attempt is from @AIatMeta two weeks ago (patel, rammal, hayat, munos, kempe, "learning to discover interesting mathematics" @niketnpatel@KempeLab). they define a theorem's interestingness as proof length over statement length, train a 27b model to predict proof difficulty given premises, and grpo a conjecturer against that score. mathlib overlap drops from 92% to 31%. they also define a utility measure, lines of lean saved across the library when the theorem is added, and show it correlates with interestingness.
that utility is a halo. but it's static, computed over an existing library, and they train on interestingness rather than on utility directly. oleg's version makes the halo relative to a bounded reasoner on unseen theorems and trains on it. that's the difference.
rough shape would be: an explorer generates proofs at volume. a compressor turns piles of them into definitions and key lemmas, trained on halo delta. a frozen student is the instrument. the compressor is the model whose reasoning you actually care about.
library-learning systems have mostly accumulated lemmas with little reuse under matched compute. my guess is that's because nobody has trained the compressor with a transfer reward. there was no signal to train on. this gives you one
open questions: how big the student should be. whether halo delta on lean theorems tracks what mathematicians call insight etc. and the obvious ablation now that a baseline exists: does model-relative halo beat fair's static utility as a training signal
My utility as an individual AI researcher will be gone in a year.
Writing math proofs will be automated even sooner.
It was never about proofs.
Science is about curiosity, creativity, and compression - via @SchmidhuberAI
*Mathematicians Should Become Formal Theory Influencers*
Mathematicians were the original influencers: they created conjectures and theories that others understood, cited, and built on.
Difficult proofs often reflected deep understanding. But the proof itself was rarely the point.
Frontier AI can already generate informal proofs much faster than humans can carefully inspect them. The scalable response is machine-checkable mathematics in systems such as Lean.
AI-generated formal proofs may increasingly resemble compiler-generated machine code: essential, but rarely worth reading or writing by hand.
That shifts mathematical work up the abstraction stack.
Mathematicians become formal-math software engineers, working with AI on clean definitions, interfaces, key theorems, and reusable libraries rather than low-level proof details.
Call everything derivable from a formal library within a fixed compute budget its mathematical halo.
Humans and AIs should compress clusters of results into insightful, useful theories that expand the halo further.
A great theory compresses many results, makes future results cheaper to derive, and exposes structure that humans and machines can understand and build on.
That is why minimum description length is a useful lens on mathematical insight.
Frontier math will eventually require huge compute budgets.
At that point mathematics starts to resemble experimental science: scarce computational instruments, with researchers deciding which problems deserve them.
Mathematicians and AIs should create conjectures and theories that expand the mathematical halo.
Mathematics should become an enormous machine-checkable software project.
*Become a Formal Theory Influencer*
Inspired since 2010 by:
https://t.co/KwmTxkNoFC
We have seen a growing and concerning trend of startups supplying data to China. Today we are taking a public stance against this practice
At fleet, we believe this represents one of the largest national security threats today and must be stopped. We must win the AI race for America and shape AI with the same democratic values that have shaped our nation
Our full statement here: https://t.co/xrECD0hepr
@oleg_murk very much agree! hosting a pragmatist manifesto meetup to get some conversations going in the research community if you have time to swing by: https://t.co/Pr9oTkIVCR
as a field our understanding of what rl is actually doing to models is still surprisingly rudimentary.
reward hacking is the obvious symptom: models exploit the gap between intended objective and measured reward, but we have weak tools for identifying the learned strategy itself, how it changes through training, and whether it survives distribution shift or evaluator awareness.
the core methodological problem is isolation vs realism. toy environments give causal control but often suppress the behaviors we care about; realistic environments preserve them but make attribution extremely hard.
i think the direction should be toward building an experimental science of objective formation under rl: checkpointing throughout training, perturbing reward structure / evaluator awareness / environment structure, then tracing when proxy strategies first emerge, what causes them to become stable, and whether the same internal mechanism survives as the environment becomes more realistic.
ideally this gives us something closer to a phase diagram of rl behavior: when reward hacking emerges, what training conditions produce it, and which learned strategies are genuinely invariant across environments rather than artifacts of a particular eval.
we should eventually be able to predict reward hacking before it becomes behaviorally obvious, distinguish genuine objective change from shallow policy adaptation, and understand which learned strategies remain stable across environments
If you are a lab researcher, I urge you to consider what the next few years will actually feel like. Do you want to kick off a superintelligent RL run without a rigorous understanding of its mind? Should you put your head down because “it’s happening anyway” - or take this moment to call for different conditions?
This isn't the most notable aspect of today's news, but on the user data issue, there are different kinds of *training on user data* with very different privacy/IP implications. Sadly, AI cos don't like to disclose what they're doing.
- pretrain on user data, with users' tokens as prediction targets: high regurgitation risk, improper
- use user prompts to distill large models into small ones: low regurg. risk, some companies probably do this
- use user traces to construct RL tasks: low regurg. risk, because RL has low memorization abilities, but can extract customer IP, depending on how it's done. Ranges from benign "use explicit user feedback in reward model training" to invasive "upload user's coding environment and commit history to turn into rl envs"
"De-identification" is weak -- you can identify someone with a small number of bits, and long traces have more than enough. And it doesn't affect IP leakage concerns.
i wonder if it’s less about reward sharing and more about the combination of partial observability and trajectory-level optimization. once subagents each have only a local view, the optimal policy is to externalize intermediate state into a shared workspace. the message board is then a learned scratchpad for distributed inference rather than “altruism” per se
agreed that one important failure mode in verifier/task generation is mistaking difficulty for signal.
a lot of “hard” tasks are just poorly constructed. they introduce noise, ambiguity, or arbitrary complexity instead of isolating the capability we actually want to measure.
i think the missing piece is that most task generation lacks an explicit objective. before generating anything, we should be able to state:
• what capability are we testing?
• what specific failure mode are we targeting?
• what evidence would convince us the model improved?
then every task should be intentionally composed to maximize signal for that objective, not just maximize difficulty.
one direction we’re excited about is treating tasks as compositions of atomic capabilities, planning, abstraction, memory, retrieval, tool use, causal reasoning, etc. but the hard part isn’t composing them, it’s composing them while preserving what you’re actually measuring.
for example, if you’re evaluating long-horizon planning, adding difficult retrieval or ambiguous instructions can easily dominate the failure. a model might fail because it forgot a fact, misunderstood the prompt, or picked the wrong tool, not because its planning was weak. the planning signal gets washed out.
ideally, composition should preserve capability attribution. every added component should either (1) be controlled so it’s unlikely to fail, (2) have independent verifiers that tell you whether that component failed, or (3) be generated from a causal graph or dependency structure where you know exactly which capabilities each subtask depends on. otherwise, once a composed task fails, you no longer know why.
benchmark generation should optimize for information gain, not just hardness. the goal isn’t to make models fail, it’s to produce failures that are interpretable enough to drive the next training iteration
it's insane to me how many people take benchmark scores at face value. i spent 2 minutes looking at GDP-val tasks and realized there's a verifier item that checks for:
" The Word document includes the warehouse phone number 560-555-3867 (accepts common US formats such as 560-555-3867, (560) 555-3867, or 560-555.3867)."
but the prompt has:
"Include the address and phone number for Gravon Shoes’ warehouse, which is 555 Waters Avenue, Austin, TX 78726, phone number 455-864-3867."
the lack of good benchmark automated verifiers is jarring*, and most code benchmarks tend to lack the same verifier quality. this isn't to say GDP-val isn't useful or decent, but stuff like this is there across the benchmark if you dig deep. the "good enough" bar for data is finally starting to catch up to model performance. we need higher quality data, we need higher quality benchmarks to track improvements. my biggest peeve with how people construct tasks is that they mistake difficulty for signal. just b/c your benchmark has a 10% pass rate, doesn't mean it's good, and often, to make a difficult benchmark, people jump through loops. it's absurd that labs aim to hill-climb all these benchmarks but many have issues that would bar a model from getting better, so either you corrupt your model to improve or buy a bunch of data that doesn't actually help and look bad on your team. we saw this with OAI's paper on swe-bench, then subsequently swe-bench-pro, and im sure we'll see even more "benchmark debunks" soon.
making good benchmarks is hard, models have saturated most of the easy stuff and indie benchmark developers or contractors are no longer the best way of approaching it, because you can't have a hodgepodge task that a model will fail on. verifiers MUST be carefully constructed, the worlds the models are playing in must be realistic and without leakage, context has to be carefully selected. we're at a point now where 99% (arbitrary number) are saturated, and it's not "experts" but real expert engineers who understand what makes good training data.
*i understand that GDP-val specifically is graded by human experts, but for anyone running the tasks at home, it is still nuts to put out verifiably incorrect rubrics especially because others will use it.