Why choose us?
Because the call was never the hard part. Zoom, Meet and Teams connect two people. None of them tell you whether the person is answering you, or reading off a second screen.
1) Integrity - we detect hidden assistants, second monitors, virtual cameras, face swaps. The recruiter gets a timestamped event feed, not a verdict. A human decides.
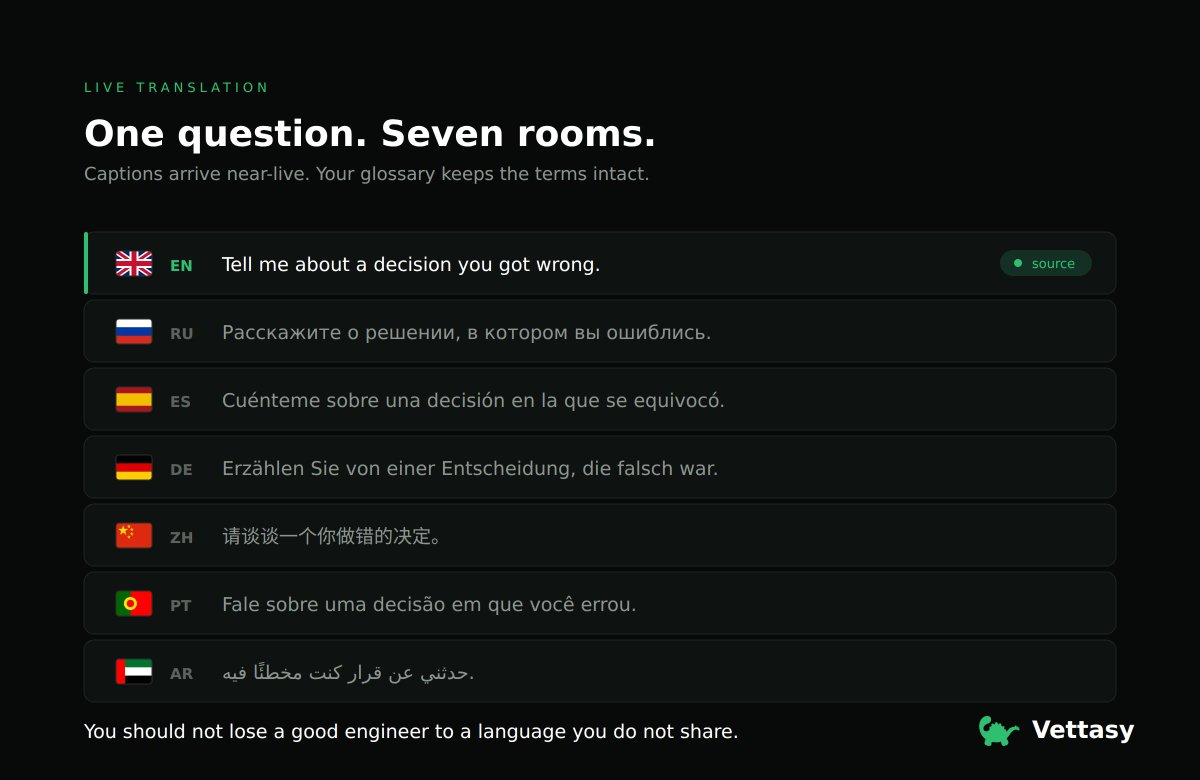
2) Translation and notes - seven languages, your glossary, a structured debrief afterwards. No third-party bots in the room.
3) Your data - your region, your retention, deletion on a button. No model trains on your recordings. That is in the contract.
The interviews are yours, not ours.
Your next hire is probably in a country where nobody on your panel is fluent.
So translation runs inside the session, not next to it. Near-live captions, your glossary loaded, no third-party bot joining as a guest.
4/4
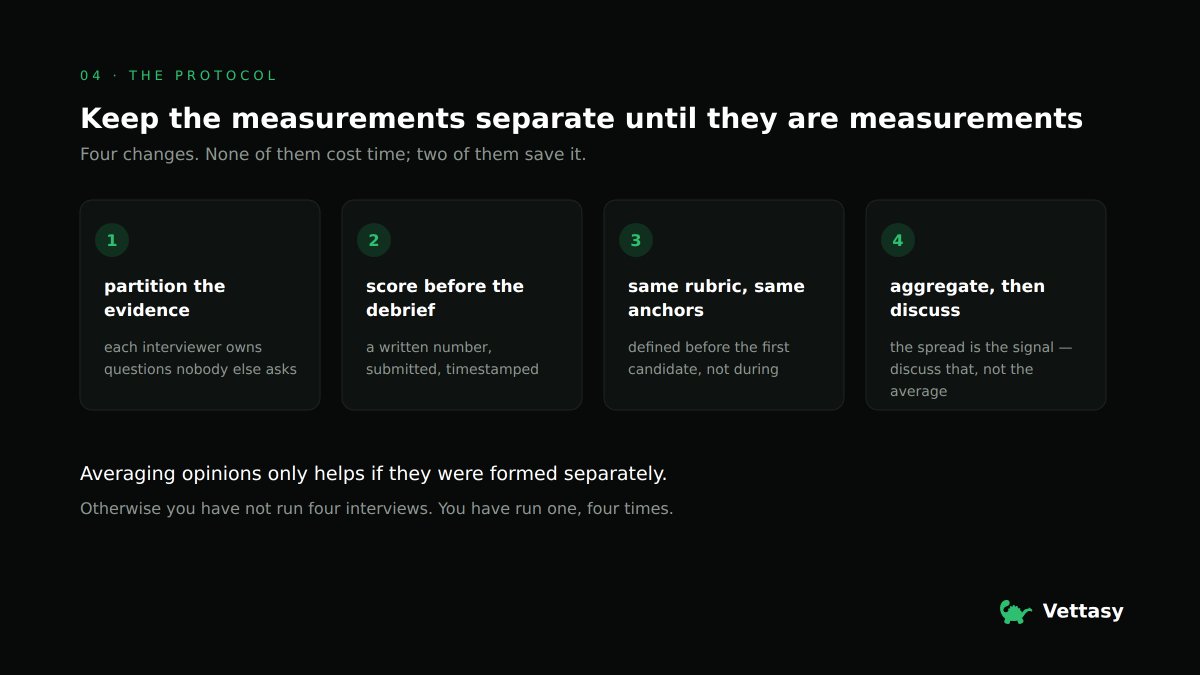
The fix is procedural, not technological.
Partition the evidence, so each interviewer owns questions nobody else asks. Take a written score before the debrief, submitted and timestamped. Use one rubric with anchors defined before the first candidate. Then aggregate, and treat the spread as the signal worth discussing not the average.
Averaging opinions only helps if they were formed separately. Otherwise you have not run four interviews. You have run one, four times.
1/4🧵👇
Four interviewers on a loop is usually described as four data points.
It is four data points under one condition: that the errors are independent. That condition is almost never checked, and it is usually false.
Four people who formed one opinion together are one measurement wearing four badges.
3/4
Four things quietly collapse a panel into a single opinion.
Everyone reads the same CV summary, so everyone starts from the same prior. Three people probe the same two topics and the fourth area goes uncovered. Whoever speaks first in the debrief sets the anchor. And nobody committed to a number before hearing what the others thought.
Each one lowers the effective number of raters. The headcount stays the same, which is why it never shows up in a process review.
Hot damn, Meta poached the CEO of a $35B, publicly traded company, MondoDB to lead their enterprise AI efforts…
CJ Desai joined MongoDB 11 months ago for a $32M equity grant - and left before the 1 year mark!! By leaving, he gave up most of the equity….
V bad news for MongoDB
Hiring in London 🇬🇧 for my Applied AI for Startups team at @OpenAI
This role is Codex focussed, combining work with top startups + ecosystem engagement
Team has MLEs, ex-founder/CTOs, research engineers. And it's pretty fun. Apply below ⬇️
it's basically impossible for someone to just "show you their prompt" now, because everything is about references, skills and examples
I often ask my agent to look at 3 other repos I've made first, search the web for references, use other AI APIs, etc.
An opportunity to do research on: continual learning: multi-agent parallel workers; and synthetic data, environments and evals that measure frontier capabilities. We make enough money to fund new research and want to make lasting contributions and share our research openly.
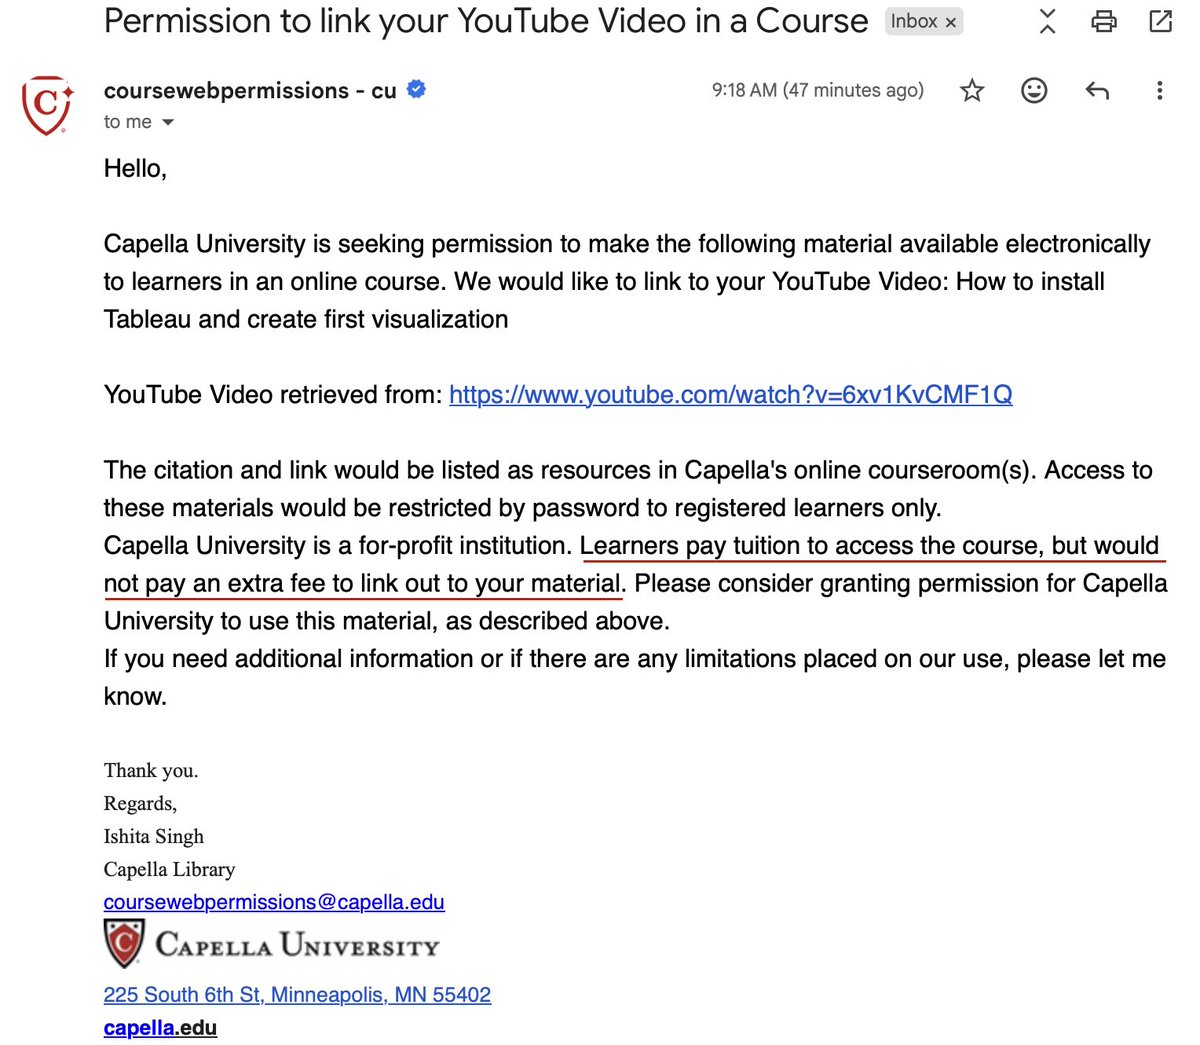
I respect the hustle, but my answer was "Just send them a link to my YouTube channel where they can learn everything in your program for free".
I'm a big fan of higher education! If you can afford it if it makes sense in your career trajectory.
But there are so many colleges using "Free" resources and having their students pay tens of thousands to get access for it? It doesn't make sense.
When colleges, bootcamps, etc reach out wanting access to my videos I always ask "is it free to get access to your program?" - the answer is always no.
My YouTube channel is a place to learn for FREE - nothing makes me more frustrated than programs trying to make people pay for my already free content.
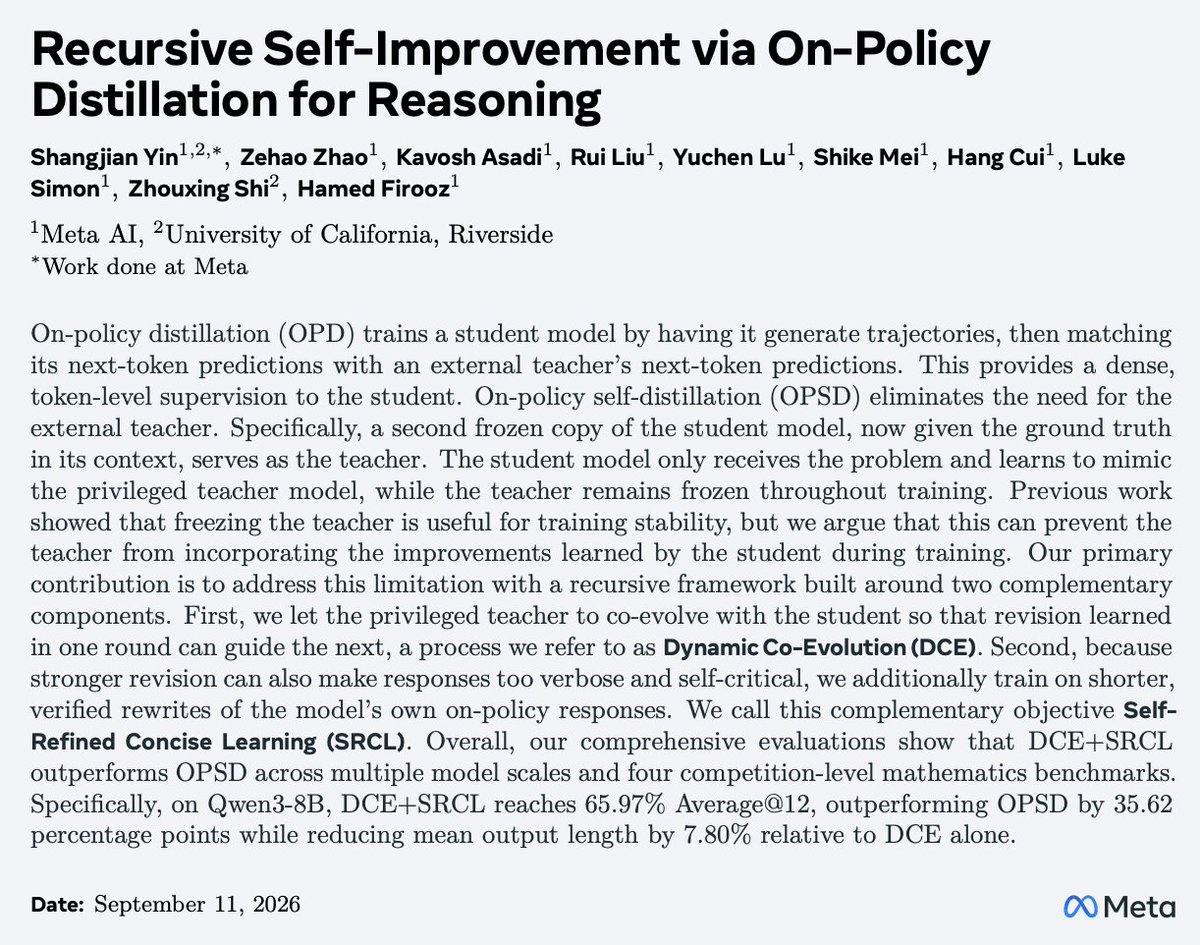
Meta's team proposes DCE + SRCL as an alternative to on-policy self-distillation (OPSD).
Achieved significant gains: 30.76% avg acc -> 65.97% on Qwen3-8B
https://t.co/nAIHRZWNDx
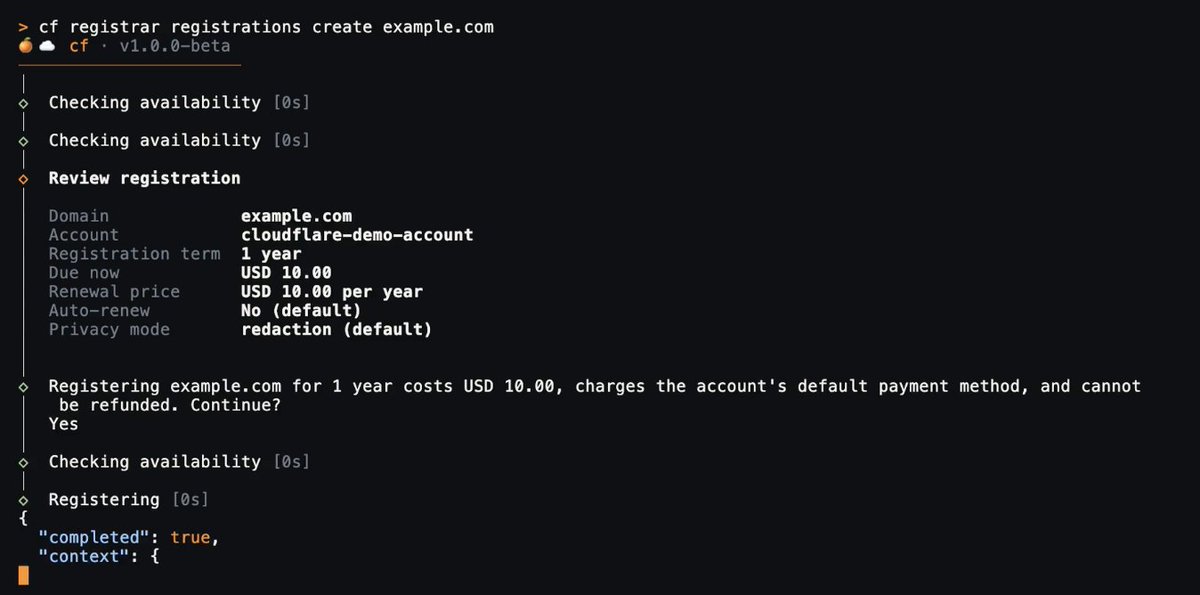
Introducing "cf", an agentic CLI for the entire Cloudflare API.
You can do nearly anything. Even buying a domain is incredibly simple from the CLI.
Don't know what command you need? Run `cf cli search "look at messages stuck in my queue"` and it will return a list of relevant commands.
https://t.co/22z5R5ArEW
This weekend our team spent 48 hours investigating the rogue OpenAI agent activity that targeted the Australian government and other organizations. Our report (coming soon) includes:
- Evidence of additional US government and other websites probed by the agents, including the CDC, International Energy Agency, and Mayo Clinic.
- Novel tactics which left records erased or inaccessible. This makes it impossible (based on public data alone) to establish that the agents did not access any sensitive data. Future investigations should analyse whether these tactics were deliberate subterfuge. 🧵
Meet the winners of The WebMCP Challenge.
These 10 projects show what people and agents can build together when websites expose structured tools agents can use.
🧵 See the winning projects and the builders behind them:
The irony of all this is it’s framed as an ai risk that needs protection against. But think about what it really means
Our banking system is so unsustainable and extractive that the moment humans have smart ai bots advising them, the ai bots will recommend exiting banks and earning better yield elsewhere
Which makes most banks economically unviable
This isn’t AIs fault, it’s a risk of highly monopolized and extractive banking
And it’s fixed by decentralized finance + ai, where users decide what to do with their own assets and earn their own yield
Surprise! AI is NOT taking recent college grads' jobs!
This was supposed to be the summer it showed up. It didn't. Great detective work by @wu_jane & Robert Fairlie in @nberpubs https://t.co/dhnQptm9ZC